# Organization Basics
Source: https://wiki.latch.bio/admin/orgs/about
Currently, we only release Latch Organization to select partners who have to
manage 5+ workspaces. To gain access to the "Organizations", please contact
our support team at `support@latch.bio`.
Latch Organizations allow administrators to **manage multiple workspaces under a single organization**. This provides a unified interface for viewing workspaces' billing overview, credit transfers between workspaces and provides organization members with owner-level access to all managed workspaces.
For help understanding the differences between Workspaces and Organizations check out our [guide here](/admin/overview).
## Accessing Organizations
You can find the list of organizations by clicking on the Avatar in the top left corner of the screen and selecting "Organizations" in the sidebar.
## Features
Latch Organizations allow you to create a group of workspaces under a single organization. The main features include:
### Workspace Overview
* Access by clicking `Workspaces` on the navbar when on the organization page.
* View all workspaces managed by the organization.
* View workspace balances and transfer balances between workspaces.
* Access workspace settings and manage resources.
* See [Adding Workspaces to an Organization](./adding-workspaces) to learn how to transfer existing workspaces or add new workspaces to the organization.
### Billing Overview
* Access by clicking `Billing` on the navbar when on the organization page.
* View aggregate billing view of all workspaces across the four Latch Products.
### Member Management
* Access by clicking `Members` on the navbar when on the organization page.
* Invite users to join the organization.
* Assign roles to users within the organization.
* Organization members have owner-level access to all managed workspaces by default.
* See [Inviting Members to an Organization](./managing-members) to learn how to invite and manage organization members.
### Customizing Organization
* Access by clicking `Settings` on the navbar when on the organization page.
* Change the name of your organization.
* Change the icon of your organization.
# Adding Workspaces to an Organization
Source: https://wiki.latch.bio/admin/orgs/adding-workspaces
Learn how to add and transfer workspaces to an organization on Latch
## Prerequisites
* You must have **Admin** permission in the organization.
* You must be an **Owner** of the workspace to transfer it to the organization.
## Transferring Existing Workspaces to the Organization
If you have existing workspaces that you would like to include in your organization, follow these steps:
1. Navigate to the workspace that you want to transfer and go to "Workspace Settings".
2. Go to General Settings
3. Click on "Transfer Ownership to Organization".
* The button will only be visible if you are an owner of the workspace and are an admin in an organization.
4. From the dropdown select the organization you want to transfer the workspace to.
5. Click "Transfer Ownership".
The workspace will now be managed under the selected organization.
## Adding New Workspaces to the Organization
To add new workspaces directly under an organization:
1. Click on your user Avatar in the top left corner of the screen
2. Then click on the Square Plus icon in the top right of the Workspace Selector Dropdown.
3. This will open the Create New Workspace modal
4. Fill out the workspace name.
5. If you are an admin in an organization, you will see an "Organization" dropdown.
6. Select an organization from the dropdown
7. Click "Create Team"
The new workspace will now be part of the selected organization and can be managed from the organization's dashboard.
# For Kit Providers: Analysis Packages
Source: https://wiki.latch.bio/admin/orgs/analysis-packages
Learn how to distribute analysis packages to customers
Many kit and solution providers aim to offer their customers a comprehensive analysis solution—from preprocessing raw data via workflows to unlocking novel biological insights through interactive downstream visualizations.
Latch simplifies this process by allowing kit providers to fully build and customize the customer experience using modular product components (workflows, plots, data, etc.) with **Analysis Packages**.
In this document, we’ll cover:
* What an Analysis Package is
* How to create redemption codes for customers
* How to share the Analysis Package and redemption code with customers
* What the customer experience looks like
* Ownership models for workspaces created from redemption codes
## Prerequisites
* Make sure that you have access to your Organization on Latch.
* If you do not have access to an Organization, please contact your workspace Admin or reach out to [support@latch.bio](mailto:support@latch.bio) (We respond to every request in less than 30 minutes.)
## Step 1: Create an Analysis Package
An Analysis Package is a curated set of Data, Workflows, Pod Templates, and Plot Notebook Templates—sourced from any of the organization’s workspaces.
To be able to create an Analysis Package, you are required to have **Admin** or **Owner** permission in your Organization.
To create an Analysis Package, first navigate to your Organization.
Click on the **Customer Packages** tab
Click **+ Package** to create a new package, then enter a name and description. You will be directed to the **Create Analysis Package** page, where you can include data, workflows, pod templates, and plot templates from *any* workspaces owned by the Organization in the package.
Once a package is created, it will show up under the **Customer Packages** page in your Organization.
## Step 2: Create redemption codes for the package
After you've created your Analysis Package, the next step is to create redemption codes for customers.
There are two types of codes that you can create: single-use codes and multi-use codes.
| Feature | Single-use Codes | Multi-use Codes |
| -------------------- | --------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------- |
| **Redemption limit** | Can only be redeemed once per code. | Can be redeemed multiple times until deactivated for the package within the Organization. |
| **Creation** | One or more codes can be manually generated for each package. | Each package has a single, unique multi-use code, which is turned off by default. |
| **Credits** | Credits can be included for single-use codes | Does not include any credits. |
| **Usage** | Ideal for offering customers starter credits to use on workflows, pods, and more. | Ideal for demos or onboarding multiple customers at once without providing starter credits. |
To create a single-use codes, navigate to your package of interest and click **Create Single Use Codes**. Here, you can also specify the number of single-use codes you want to generate.
Multi-use codes can be redeemed multiple times. Each Analysis Package includes just one multi-use code, which is turned off by default. When activated, the multi-use code can be redeemed repeatedly until you deactivate it. Unlike single-use codes, packages redeemed using multi-use codes do not include credits.
## Step 3: Distribute your Analysis Package
Single-use code packages can be distributed in two ways: via email or a link.
To share a package via email, click the email icon and enter the recipient's email address.
The customer will receive an email in their inbox, which will take them to a sign-up or log-in page. If they use Latch previously and are already logged in, a modal will pop up which asks them the workspace they want to redeem the package in.
Click on the link icon to retrieve a URL for sharing:
Here's what the experience looks like from a customer's perspective:
For a multi-use code, click the link icon to generate a shareable link that customers can use to redeem the analysis package.
## What the Customer Experience Looks Like After Receiving your Package
At Latch, we collaborate closely with each kit provider to customize and white-label the Latch platform so it fully aligns with their brand identity. This tailored approach means every element—from the color schemes and logos to the overall look and feel—matches the provider's unique brand.
As a result, when a customer purchases a kit and logs in for analysis, they step into a branded, intuitive, and visually consistent portal that feels like a natural extension of the kit provider's own offerings.
This step only applies if you sent customer single-use codes via email.
Customers receive an email with a unique redemption code link.
Customers then see a welcome page tailored to the kit provider’s brand, featuring their taglines, logos, and colors.
Next, customers can choose to either sign up or log in, depending on whether they already have a Latch account.
If this is their first time redeeming a kit and they have never previously interacted with Latch, they can click **Create a new Latch account** to sign up. If they are redeeming another kit or have previously created a Latch account, they can select **I have a Latch account** and log in.
After logging in, users will see an overview of the kit’s contents that will be unpacked into their workspace. They can choose to enable Share Usage Analytics, which gives the kit provider permission to view their activities within the workspace. These activities may include opening files, launching workflows, using a certain number of credits on a Pod or workflow, and more. By default, this option is disabled.
The first tab customers see in the workspace is **Latch Data**.
They can also navigate to the **Workflows** tab to view and launch the kit provider’s workflows.
Additionally, they can visit the **Plots** tab for interactive, downstream visualizations.
Once again, each workflow, data folder, and Pod or Plot template can be fully customized by the kit provider in the **Customers Packages** section of their Organization. This flexibility makes it easy to create a complete end-to-end analysis experience for their customers.
## How Customers Request Support for Analysis Packages
Latch makes it easy for customers to grant temporary workspace access to kit providers for debugging. Providers can enter, diagnose issues, and offer support while customers retain control over access levels and duration.
**IMPORTANT**: Because the customer is granting workspace access, the individual submitting the support request must be an **Admin** within the customer workspace.
Once a customer has redeemed a package in their workspace, they can request support by navigating to your current workspace > **Workspace Settings** > [**Packages**](https://console.latch.bio/settings/packages), and click on the **Request Support** button.
When requesting access for a kit provider organization (the organization that created the analysis packages), users will be prompted to complete the following fields:
1. **Users Within to Grant Access**
* The kit provider's organization can have users with different roles (e.g., Admin, Member, Viewer).
* Select which roles should be granted access.
* Default: Only organization admins will be granted access.
2. **Permission Level to Grant in Your Workspace**
* Choose whether to grant Admin, Member, or Viewer access to the selected users.
Default: Viewer access only.
* If users need need the kit provider to relaunch or debug workflows, consider assigning Admin or Member permissions.
3. **Duration of Access (Hours)**:
* Specify how long the kit provider's users should have access to the workspace.
After the specified duration, their access to your workspace will automatically end.
### Viewing Customer Requests for Support
As a kit provider, first go to your Organization. Navigate to the **Workspaces** tab and click on the **Support** tab. You will see list of workspaces that requested support.
Click on the arrow icon to enter the workspace.
# Comparing Workspace Ownership: Organization vs. Analysis Packages
Source: https://wiki.latch.bio/admin/orgs/managed-orgs
Learn how ownership differs in workspaces created by the Organization versus workspaces where Analysis Packages are unpacked in.
As a kit or solution provider, you may have different customer personas. Some customers prefer a fully self-serve approach, opting for complete privacy over their data. Others might seek extensive hands-on support, including direct assistance within their workspaces for data inspection, troubleshooting, or workflow management.
This guide is designed to clarify the various ownership levels you can maintain over customer workspaces. Our aim is to help you effectively navigate these options, ensuring you can steer your customers towards the most suitable experience on Latch.
## Concepts Review
### **Workspace**
* A **Workspace** is a shared environment where different team members can collaborate in.
* Every Workspace consists of five components: **Data**, **Registry**, **Workflows**, **Pods**, and **Plots**.
* Within a Workspace, each member can carry out various actions, such as adding or removing data, uploading and launching workflows, or starting an RStudio instance on a Pod.
* Permissions within a Workspace are role-based, with common roles including **Admin**, **Member**, and **Viewer**.
* As a Latch user, you can create any number of workspaces. The content of each workspace (its data, registry, workflows, pods, etc.) is completely isolated from one another.
### **Organization**
* An **Organization** is a layer above Workspaces. Workspaces can be manually added to an Organization.
* Once a Workspace is added to an Organization, all members of that Organization gain **Admin** permissions for that Workspace.
* Organizations also include **Billing**, which provides a consolidated view of credit usage across Data, Registry, Workflows, Pods, and Plots in each associated Workspace.
* Additionally, Organizations allow for **credit transfers** between Workspaces.
* They also feature a **Security** tab, enabling Organization members to set restrictions on the email domains permitted to access their Workspaces.
### **Analysis Packages**
* Organizations can create **Analysis Packages**, which bundle data, workflows, pod templates, and plot templates from any of their associated Workspaces.
* Kit providers within an Organization can generate redemption codes and share them with customers—via link or email—directly from the **Analysis Packages** tab.
## Examples of Different Levels of Ownership for Customer Workspaces
Now we understand the key concepts, let's walk through different scenarios using the diagram below:
* As a kit provider, you can create an Organization and manually add Workspaces to it. In this scenario, the Organization owns these Workspaces. Any member of the Organization automatically gains Admin access to all Organization-owned Workspaces.
* If you prefer not to grant someone in your company Admin access to every Workspace within the Organization, simply add them directly to the specific Workspace instead. This way, their permissions are limited to that Workspace.
* Your Organization can also create and send Analysis Packages to customers.
An Analysis Package, once redeemed, is unpacked into the customer's own Workspace, which the customer fully owns. Unlike Organization-owned Workspaces, the Organization does *not* have inherent ownership or Admin access to these customer-owned Workspaces.
* Customers can choose to grant the Organization visibility into activity analytics related to the Analysis Package.
This allows the Organization to see the customer's activities within their workspaces, such as if a user guide has been accessed, a workflow has been run, or how many credits have been spent. Additionally, customers may invite someone from the kit provider's Organization into their Workspace as a Viewer/ Member/ Admin to assist with troubleshooting, if needed (not shown in diagram).
## Summary
In summary, there are two common approaches:
1. For customers who are more independent, sending them Analysis Packages is recommended. Customers maintain full ownership and control of their own Workspaces while still having the option to share activity analytics or ask for troubleshooting assistance. These customers can manage their own billing by providing credit card details or setting up invoice billing directly within their Workspace.
2. For customers who need more hands-on support, the kit provider can create Workspaces on their behalf and add these Workspaces to the Organization. In this scenario, the Organization retains full ownership and Admin rights over the Workspaces. This arrangement allows the Organization to manage credits, data, workflows, and other administrative tasks directly.
# Inviting Members to an Organization
Source: https://wiki.latch.bio/admin/orgs/managing-members
Learn how to invite members to the organization and accept invitations
## Adding Users to the Organization
To add users to your organization and assign [organization roles](./roles):
1. Navigate to the **Organization Members** page
2. Click on **Invite** to open the organization invitation modal.
3. Fill out the email and the role you want to assign to the user.
4. Click **Invite** to send out an invitation email to the user.
5. \[Optional] If you want to send an invitation link directly to the user, click on **Copy Invite Link** on the Members page to copy the invitation link.
6. Share the link with the user that you wish to add to the organization.
## Accepting Organization Invitations
### If you have the invitation link
1. If you have the invitation link, paste it into your browser.
2. A modal will open with the filled-out invite code.
3. Click on **Join Organization**.
### If you have the invitation code
1. Click on the **Avatar** in the top left corner of the screen.
2. Go to the **Organizations** dropdown.
3. Click on **Join Organization**.
4. A modal will open where you can enter the invite code.
5. Click on **Join Organization**.
# What are Latch Organizations?
Source: https://wiki.latch.bio/admin/orgs/overview
Manage multiple workspaces under a single organization on Latch
Organizations act as a layer on top of [Latch Workspace](../workspaces/overview), and can own multiple workspaces.
* Within an Organization, there's a [workspace overview](/admin/orgs/about#workspace-overview) to observe credit balances of workspaces, transfer credits between workspaces, and see an aggregate [billing view](/admin/orgs/about#billing-overview) of all workspaces across the four Latch Products.
* With owner permissions, organization members can access all workspaces within the organization.
Currently, we only release Latch Organization to select partners who have to
manage 5+ workspaces. To gain access to the "Organizations", please contact
our support team at `support@latch.bio`.
Learn about the key concepts and features of Latch Organizations
Create new workspaces or transfer existing workspaces to an organization
Configure access controls and authentication methods
Add and remove members from different workspaces in your organization
Change member roles within your workspaces and organizations
Learn how to transfer credits to and from different workspaces
## To collaborate within a workspace
Manage settings within a workspace
# Organization Roles
Source: https://wiki.latch.bio/admin/orgs/roles
Learn about roles and permissions for members of an organization.
## Basic Roles and Permissions
There are 2 base roles for an organization:
### Admin
Can do anything in the organization or child workspaces:
* Can add new workspaces to the organization.
* Can add new members to the organization.
* Can view billing overview for the organization.
* Can change details of the organization such as changing name, logo, etc.
* Has [Owner](../workspaces/roles#owner) permissions for all workspaces in the organization.
### Member
Can view the organization and access child workspaces:
* Can access any workspace in the organization.
* Can have a [default role](../workspaces/roles) in all workspaces in the organization.
* I.e. you can set a member to be a **Viewer** or **Admin** in all workspaces by default.
## Changing a Member Organization Role
To change an organization member's role:
1. Go to Organization Settings > Members Tab.
2. Click on the role dropdown for the user.
3. Select the new role.
## Changing a Member Organization Workspace Role
You can set a default role for a member which they will have in every organization workspace on Latch:
1. Go to Organization Settings > Members Tab.
2. Click on the workspace role dropdown for the user.
3. Select the new role.
* In this example, the user will have [Member](../workspaces/roles#member) permissions in every workspace in the organization.
# Security Settings
Source: https://wiki.latch.bio/admin/orgs/security
Configure access controls and authentication methods
To view the Security settings for an Organization, hover over the Organizations option in the workspace avatar dropdown, select the Organization you want to view:
Then go to the Security tab on the Organization page:
## Workspace Members Settings
These settings allow you to manage and control the security features related to workspace member access within your Organization.
### Allow Reusable Invite Links in Workspaces
When enabled, workspace admins in this organization are allowed to create invite links that can be reused multiple times to join a workspace.
Learn more about inviting workspace members [here](/admin/workspaces/inviting-members).
### Limit Login Email Domains for Workspace Members
This setting restricts organization workspace access to users with email addresses from a specific domain. Entering a domain (e.g., latch.bio) ensures that only users with email addresses ending in that domain can join the workspace.
This can be used alongside the restrictions below to only permit email addresses from specified authentication providers.
### Allow Login with Google, GitHub, or Microsoft for Workspace Members
When enabled, accounts authenticated through the specified identity provider (Google, GitHub, or Microsoft) can join this organization's workspaces.
### Allow Login with Email & Password for Workspace Members
When enabled, accounts authenticated through an email and a password can join this organization's workspaces.
***
### Seeing an Org or Workspace Member's Account Authentication Method
On the members page of an organization or workspace, the authentication method used by each account is listed under the "Login" column. Accounts authenticated through a provider will display the provider's logo (e.g., Google, Microsoft) next to them.
*To find the members page of a Workspace,* click on the Workspace Settings option at the bottom of the workspace avatar dropdown, and then go to the Members tab in the Workspace Settings page.
*To find the members page of an Organization,* hover over the Organizations option in the workspace avatar dropdown, select the Organization you want to view, and then go to the Members tab on the Organization page.
# Transferring Credits to Workspaces
Source: https://wiki.latch.bio/admin/orgs/transfer-credits
You have to be a [workspace admin](/admin/workspaces/roles) to transfer
credits. To get to the orgs page, click on your workspace avatar in the
upper left hand corner and go to organizations, where you'll find the page
for your organization.
You can view and manage credits for your organization here.
In the transfer credits section, you can transfer credits into a workspace
with the icon on the left, and transfer credits out of a workspace with the
icon on the right.
# White-label Your Customer Experience
Source: https://wiki.latch.bio/admin/orgs/white-labeling
Customize the Latch platform to reflect your brand's unique look and feel.
Latch provides many ways for solution providers to deliver robust end-to-end analysis experience to their customers. For example, we previously wrote about how solution providers can [create managed workspaces under their Organization](/admin/orgs/overview) for customers for hands-on support, or send [Analysis Packages](/admin/orgs/analysis-packages) - a collection of customer data, bioinformatics pipelines, and visualization dashboards - for customers to unpack in their own workspaces.
No matter which approach a solution provider takes, Latch ensures that from the moment a customer purchases a kit, they enter a platform reflecting the provider's brand.
## Prerequisites
* Make sure you are a part of an Organization before proceeding. See how to access your Organization [here](/admin/orgs/about)
## White-labeling Options
Latch provides options for you to white-label:
**Branding**
* The signup & login page UI and domain
* Branded logos next to your Organization's published workflows
* Analysis Package redemption emails
* Workspace invitation emails
* Logos and colors of data folders originating from Analysis Packages
**Workspace Customization**
* Selective feature hiding (e.g., product tabs, Graph/Logs tabs for workflow execution) when customer workspaces are owned by the provider's Organization.
## Branding
To access your organization branding settings:
* Navigate to your Organization Settings
* Click on the **Branding** tab
Here you can customize the branding of your Organization.
### Enabling White-labeling Branding
To enable white-labeling branding for your Organization, you need to:
* Click on the **Enable White-labeling Branding** toggle in the **Branding** tab.
This will turn on the white-labeling branding features for your Organization (such as the workflow card, analysis package redemption email, and workspace invitation emails) otherwise they will use the default Latch branding.
Your Organization avatar will always appear under workspaces it owns and if you have a custom domain set up, the white-labeled login and signup page will be shown under that domain.
## Branding Options
There are several options for white-labeling your Organization on Latch. You are able to configure the white-labeling experience by providing the following brand assets:
* Organization Avatar
* Primary Logo
* Badge Logo
* Banner Background
* Brand Primary Color
For more information on the recommended image format and sizing for white-labeling, see our [guide on branding assets recommendations](/admin/orgs/white-labeling-image-recommendations).
### Login & Signup Page
Please reach out to your Latch customer success representative to have your
custom domain manually set up by our engineers. You can still upload the
branding assets to your Organization and will show up when the domain is set
up.
The login and signup page use the Organization's Primary Logo and Banner Background. To see an example of a white-labeled login and signup page, see [here](https://aboro.latch.bio/signup).
When the white-labeling branding is enabled, users who sign up from your Organization's custom domain will receive a white-labeled welcome & email verification email.
This email can be customized further with help from the Latch team.
### Workflow Card
The **Workflow Card** for published workflows owned by your Organization can be customized to show your Organization's brand. The badge will use your Brand Primary Color and your Organization's Badge Logo.
The author label will on the card use your Organization's Primary Logo and use your Organization's display name. The badge will show up on the card if it's owned by your Organization and the workflow has a version that is released.
See recommended for the badge logo [here](/admin/orgs/white-labeling-image-recommendations#organization-badge-logo).
### Analysis Package Redemption Email
The Analysis Package redemption email can be customized to show your Organization's brand. The email will use your Organization's Primary Logo and Brand Primary Color. Make sure you use a brand color that is visible on a white background (or please contact the Latch team if your color has low contrast on white so we can customize the email to have a higher contrast).
When you create an Analysis Package, you can customize the email subject, title, and body that is sent to the customer when they redeem the package. *[Learn more about creating Analysis Packages here.](/admin/orgs/analysis-packages.mdx)*
In a analysis package settings, click on the **Email** tab to customize the email that is sent to the customer for that specific package.
### Workspace & Organization Invitation Email
The workspace and organization invitation email can be customized to show your Organization's brand. The email will use your Organization's Primary Logo and Brand Primary Color.
### Analysis Package Data Folders
When a package is redeemed in the customer workspace, all data folders belonging to the package will have the Organization's brand color and brand logo on the right sidebar.
## Workspace Customization
If you are the Admin of the customer workspace, you can hide certain tabs to simplify the interface for your customers.
Please note hidden tabs remain visible to other Admins within the same
workspace. Customers must have Member-level permissions or lower to be
affected by these settings. And this only affects the display of the tabs in
the navigation, but the tabs are still accessible through the URL.
* Go to [Workspace Settings > Access](https://console.latch.bio/settings/interface).
From there, you can toggle on or off each product tab in the left navigation bar. For example, if you only want your customers to use Latch Workflows and Latch Data, turn off Latch Registry, Pods, and Plots.
Each workflow execution typically includes additional tabs like Graph & Logs or Usage Report to help developers debug and optimize resources. If you prefer a simpler experience for scientists or non-developers, you can hide these tabs as well to prevent confusion.
From workspace Admin perspective (all workflow execution tabs are shown):
From workspace Member perspective (the *Graph & Logs* and *Usage Report* tabs are not shown):
# White-labeling Recommended Image Format & Sizing
Source: https://wiki.latch.bio/admin/orgs/white-labeling-image-recommendations
Recommended image format and sizing for white-labeling.
## Recommended Image Format & Sizing
Here are the recommended image format and sizing for organization brand assets for white-labeling on Latch.
### Workspace and Organization Avatar
Each Workspace owned by an org has has an avatar with an Org sub-avatar:
The Organization Avatar can be updated under Organization Settings. Recommended size is 200px by 200px and format is JPEG or PNG.
We also recommend using a variation of your logo similar to what you would use for your website favicon so it's also legible at smaller sizes.
The Workspace Avatar can be uploaded under General Settings for a Workspace. Recommended size is 200px by 200px and format is JPEG or PNG.
### Organization Primary Logo
For you Organization Primary Logo we recommend using a PNG with transparent background and with a 160px height so it shows up crisp. To make sure it renders properly across different email clients we recommend only using PNG.
### Organization Badge Logo
For your Organization Badge Logo we recommend using a PNG with a transparent background and with a 84px height so it shows up crisp. The brand color is used for the background of the badge, so make sure to use a color that contrasts well with the logo.
### Banner Background
For you Banner Background you can use a JPEG or PNG and with the recommended dimensions of around 1600px height by 2400px width. The dimensions are not strict, but we recommend keeping the aspect ratio of the image to something that would be appropriate for a browser window and the size above 1600px.
# Workspaces & Orgs: An Overview
Source: https://wiki.latch.bio/admin/overview
Learn about roles and permissions for members of an organization.
**Latch Workspaces** are collaborative environments where teams can manage projects, share data, and utilize Latch's bioinformatics tools.
**Latch Organizations** provide a higher-level management structure for multiple workspaces.
Manage settings within a workspace
Manage multiple workspaces under a single organization on Latch
## What are Workspaces?
**In Workspaces you can...**
* Manage your team members and their [access](/admin/workspaces/roles) to the workspace as well as workspace-specific [billing](/admin/workspaces/billing), including credit balance and usage across Latch products.
* Share data with your team and organize [data](/data/overview) within the workspace.
* Run and manage [workflows](/workflows/overview) for efficient bioinformatics analyses within the workspace.
* Utilize [Latch Pods](/pods/overview) for compute and containerized tools, and access the [Registry](/registry/what-is-a-registry) for metadata labeling.
##### **Use a Workspace when:**
* You're working on a single project or with one team.
* You need to manage and allocate resources for a specific initiative.
* You require fine-grained control over access permissions for different team members within a project.
## What are Organizations?
**In Organizations you can...**
* Create and oversee [multiple workspaces](/admin/orgs/adding-workspaces) under a unified organization.
* Grant organization members with owner-level [permissions](/admin/orgs/roles) across all managed workspaces.
* View [comprehensive billing](/admin/orgs/about#billing-overview) that aggregates usage across all managed workspaces.
* [Transfer credits](/admin/orgs/transfer-credits) between workspaces to manage resources across projects.
##### **Use an Organization when:**
* You're overseeing multiple projects, customers, or teams, each requiring its own workspace.
* You need a high-level view of resource usage and billing across workspaces.
* You want to easily transfer credits between workspaces.
## Permissions
Within a [Latch Organization](/admin/orgs/about), you can be an **Admin** or a **Member**. Within a [Latch Workspace](/admin/workspaces/overview), you can be an **Admin**, **Member**, or **Viewer**.
| Workspace | Organization |
| --------------------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------- |
| [Admin](../workspaces/roles#admin): performs administrative tasks within the workspace. Configures billing, adds/ removes members, etc. | [Admin](./roles#admin): can perform tasks like adding new workspaces, inviting members, etc. |
| [Member](../workspaces/roles#member): can use the workspace resources, such as creating pods, running workflows, using Registry, etc. | [Member](./roles#member): can view members, billing, etc. You can set a member to be a **Viewer** or **Admin** in all workspaces by default. |
| [Viewer](../workspaces/roles#viewer): can only view the workspace resources but cannot perform any actions. | |
**NOTE**: All **members of an Organization** automatically have **Owner** permissions for all its child workspaces. If you want to limit someone's permissions, add them only to the specific workspaces where you want them to have access.
# Workspace Billing
Source: https://wiki.latch.bio/admin/workspaces/billing
Learn about billing for Latch workspaces and how to add your credit card information.
Latch follows a pay-as-you-go model, where you can simply add your credit card information and start using Latch.
## How to Add Your Credit Card
1. Navigate to the [**Workspace Billing**](https://console.latch.bio/settings/billing) page.
2. Select **Self-Serve** → **Continue to Stripe**. You will be directed to the Stripe billing page where you can enter your credit card information.
3. At the end of each month, you will be billed for any outstanding balance.
## Understanding your Billing page
* **Month-to-Date Usage** refers to the number of Latch credits incurred that month across all Latch products. 1 Latch credit equals 1 USD.
* **Outstanding Balance** refers to how much you will pay at the end of the month. If the payment method for the previous month fails, it will be added to the outstanding balance.
* **Latch Credits Balance** refers to prepaid credits that your team can use on the Latch platform. If your organization has purchased these credits in bulk, you will observe your outstanding balance as zero or "-" on the billing page. This indicates that instead of incurring additional costs each month, you are utilizing the credits already bought, thus drawing down from your pre-established credit balance.
## Configuring Usage Limits and Billing Alerts
You can set usage limits for your workspace to prevent unexpected charges. Additionally, you can set up email alerts to notify you when your workspace reaches a certain credit usage threshold.
1. Navigate to the [**Workspace Billing**](https://console.latch.bio/settings/billing) page and click on **Set Monthly Usage Limits**.
2. Set the credit usage limits for your workspace.
1. Set **Usage Limit** to the maximum number of credits you want to allow your workspace to use each month. After the workspace reaches this limit, users no longer will be able to start pods or launch workflows. You will also receive an email notification when the workspace reaches this limit.
2. Set **Alert Amount** to the number of credits at which you want to receive an email alert. This will help you keep track of your workspace's credit usage.
3. To receive email alerts, you need to have emails verified in your workspace. Click on **Add Verified Emails** to verify your email on the workspace settings page.
3. (Optional) Verify your email address by clicking on **Add Verified Emails**. Alternatively, you can also go to the [**Workspace Settings**](https://console.latch.bio/settings/general) page and click on **Add Email**.
4. Select the email addresses that you want to receive alerts on and click on **Save**.
Whenever your workspace reaches either the **Alert Amount** or **Usage Limit**, you will receive an email alert.
## FAQ
You will still be able to view and download data. However, you won't be able to launch a workflow or start a pod.
# Creating a Workspace
Source: https://wiki.latch.bio/admin/workspaces/creating-new-workspace
Learn how to create a new workspace on Latch
1. Click on your user avatar in the top left corner of the screen.
2. Then click on the plus icon in the top right of the Workspace Selector Dropdown.
3. Enter the name of your new team in the opened window.
* An avatar image will automatically be generated based on the workspace name provided.
* You can also upload your image. We recommend a square .jpg or .png at 200px by 200px.
* Setting a workspace as default will make it the workspace you are automatically put in every time you log in again. You can set this later in the Workspace Selector Dropdown.
4. Finally, click **Create Team**.
When your team is created you will be dropped on the members page of that new workspace where you can [invite other users to your workspace](./inviting-members).
# Inviting Members to a Workspace
Source: https://wiki.latch.bio/admin/workspaces/inviting-members
Learn how to invite users to an existing workspace
## Creating and sending workspace invites
1. Go to your Workspace Settings
1. Click on your **Avatar**.
2. Then click **Workspace Settings** at the bottom of the dropdown.
2. Go to the **Members Tab**.
3. To invite a user, click the **Invite** button at the top of the members table.
4. A window will open where you can enter the emails of the users you would like to invite to your workspace.
* You can enter multiple emails separated by commas(`test@latch.bio, test1@latch.bio`)
5. Select the [role](./roles) you would like them to have.
6. Click **Invite** to send emails to the provided emails.
7. *Alternatively*, you can get an **Invite Link** by clicking **Copy Invite Link** on the pending member row for that invited user.
## Joining workspace using workspace invites
### If you received an invitation email
1. To join the workspace, click **Join Workspace** button in the email which will open the modal to join the workspace.
2. *Alternatively*, copy the code at the bottom of the email and follow the steps for [if you have the invitation code](./inviting-members#if-you-have-a-workspace-invitation-code).
### If you have a workspace invitation code
1. Go to your account and click on the avatar.
2. Click the **Join Workspace** button at the top of the navigation bar.
3. Enter the invitation code and click **Join Workspace**.
4. The workspace will be added to your workspace list and you will be redirected to the workspace you just joined.
# Copying and Moving Data Between Workspaces
Source: https://wiki.latch.bio/admin/workspaces/move-copy-data
Click on the more options menu of the file you want to move/copy, and click
move/copy to workspace.
This will open a modal that selects the workspace you move/copy data to.
After moving/copying the file, you can navigate to the workspace it has been
moved/copied to.
# What are Latch Workspaces?
Source: https://wiki.latch.bio/admin/workspaces/overview
Latch Workspaces are where you manage your team, billing, data, workflows and other infrastructure.
You can [create multiple workspaces](./creating-new-workspace) to organize your projects and teams, or you can [join an existing workspace](./inviting-members#joining-workspace-using-workspace-invites) using workspace invites.
* Workspaces contain [Latch Data](/data/overview), [Workflows](/workflows/overview), [Pods](/pods/overview) and [Registry](/registry/what-is-a-registry).
* Each member within the workspace can perform activities within the workspace, such as adding/ removing data, launching workflow, launching Pods, etc.
* Each workspace contains its own billing and credit balance.
* Within a Latch Workspace, you can be an **Admin**, **Member**, or **Viewer**.
* Admins can add or remove more fine-grained permissions for each of its Members and Viewers.
## Setting up and administering workspaces
Learn how to create a new Workspace
Invite other users to your workspace to collaborate with
Manage roles and permissions for workspace members
Learn about billing for Latch workspaces and how to add your credit card
information.
Move or copy data between workspaces
Open pod templates in other workspaces
## To manage multiple workspaces
Manage multiple workspaces under a single organization on Latch
# Workspace Roles
Source: https://wiki.latch.bio/admin/workspaces/roles
Learn about workspace roles and permissions
## Basic Roles and Permissions
There are 4 base roles for a workspace:
### Owner
* This is the user who created the workspace.
* The only one who can delete a workspace.
* Has all permissions of **Admin**.
### Admin
* Has full access to everything in a workspace.
* Can invite new members and change member workspace permissions.
* Can change workspace settings.
* Can view and manage workspace billing.
* Can view and edit all workspace data(data, workflows, pods, etc.).
### Member
* Can execute, edit and delete resources inside of the workspace.
### Viewer
* Can only view and download data in the workspace.
* Cannot execute, edit or delete resources(ex. workflows, pods, etc.).
## Changing a Member's Role
1. Go to Workspace Settings > Members Tab.
2. Click on the role dropdown for the user.
3. Select the new role.
## Advanced Roles and Permissions
You can set fine-grained permissions for what a member of a workspace can do:
1. Go to Workspace Settings > Members Tab.
2. Click on the Advanced Permissions button next to the role dropdown for the user.
3. This will open up a window where you can toggle specific permissions on and off.
# Opening Pod Templates in Other Workspaces
Source: https://wiki.latch.bio/admin/workspaces/workspace-pod-templates
You can open any pod template in another workspace. Open the main pod
template page, and in the sidebar you can toggle open the Use Template
button to open the template in another workspace.
This will open a modal that selects the workspace you open the pod template
in.
Now you can set up the pod template in your desired workspace.
# Code
Source: https://wiki.latch.bio/agent/code
View and modify all code generated by Latch Agent.
All code produced by Latch Agent is fully transparent and accessible. Click **[Edit mode](/plots/layouts#edit-vs-app-mode)** to view, modify, or rerun any analysis step. This ensures reproducibility and gives you full control over the analysis.
## Accessing Code
To view the code behind any analysis:
1. Click Edit at the upper right corner next to the "Run All" button in the [Latch Plots interface](/plots/layouts#edit-vs-app-mode)
2. Navigate to code cells associated with each step
3. Review the code that generated the results
4. Modify as needed to customize your analysis
# Core Concepts
Source: https://wiki.latch.bio/agent/concepts
Key concepts for understanding how Latch Agent works.
Understanding these core concepts will help you get the most out of Latch Agent.
***
### [Plan](/agent/plan)
Agent creates a structured plan before executing complex tasks. Review and approve the plan, or ask for modifications before execution begins.
***
### [Modes](/agent/modes)
Choose between **Proactive** mode for autonomous execution or **Step-by-step** mode for guided, incremental analysis with approval at each stage.
***
### [Tools](/agent/tools)
The capabilities available to the agent, from running workflows and executing code to generating visualizations and querying databases.
***
### [Code](/agent/code)
View all code the agent produces by clicking **[Edit mode](/plots/layouts#edit-vs-app-mode)**. Every analysis step is transparent and can be modified or rerun.
***
### [Environment](/agent/environment)
Agent runs on Latch Plots with specific behaviors for startup, shutdown, dependencies, and resource allocation. Understand how sessions persist between restarts.
***
### [Context](/agent/context)
What the agent sees and uses to inform its responses, including your data, conversation history, and available tools. Learn how to manage context effectively.
***
### [History](/agent/history)
Access past conversations with the agent. Review previous discussions and analysis results.
***
# Context
Source: https://wiki.latch.bio/agent/context
What Latch Agent sees and uses to inform its responses.
The agent can see your conversation history, notebook contents, and analysis results to understand what you're working on and provide relevant responses.
## What the Agent Can See
### Conversation
The agent remembers your entire conversation history in the current session, including your questions, the agent's responses, and any analysis results.
### Current Notebook
The agent can see:
* All code in your notebook cells
* Execution results and outputs from running cells
* Plots and visualizations you've generated
* Interactive widgets and their current settings
* Variables and data in your notebook
This helps the agent understand what analysis you've already done and build on your work.
### Analysis Plan
If you're working through a multi-step analysis, the agent can see your plan and track progress through each step.
### Platform-Specific Knowledge
The agent has access to documentation for supported technologies (Xenium, Vizgen, Takara, Visium, AtlasXOmics, etc.) and can reference best practices and workflows specific to your platform.
### Attached Files
When you attach files via the chat, the agent can use them in the analysis.
## What the Agent Cannot See
* **Previous sessions**: Each notebook session is isolated—the agent starts fresh each time
* **Other notebooks**: The agent only sees the current notebook you're working in
* **External websites**: The agent cannot browse the internet or access external URLs
If you want the agent to continue work from a different notebook, ask the agent in your previous notebook to create a summary file, upload to Latch Data, and attach the summary file in the new notebook.
# Environment
Source: https://wiki.latch.bio/agent/environment
How Latch Agent runs on Latch Plots and manages resources.
Latch Agent operates within [Latch Plots](/plots/overview), where each notebook is backed by a dedicated virtual machine. Understanding how the notebook runtime works helps you manage agent sessions effectively.
## Notebook Runtime
Latch Agent runs within a [Latch Plots notebook runtime](/plots/layouts#notebook-runtime). Each notebook is backed by a dedicated virtual machine with a Python kernel, compute resources (CPU, GPU, RAM), and the `plots-faas` conda environment. The agent is only available when the notebook is in the "Connected" state.
## Notebook Statuses and Agent Availability
When you create or open a notebook, it transitions through these states:
* **Creating Runtime / Layout Connecting / Initializing**: The agent is not available during these startup phases. Initialization automatically executes all cells, which can take several minutes for complex notebooks.
* **Connected**: The agent is fully operational and can interact with the notebook, execute code, and manipulate cells.
* **Dormant**: The notebook has shut down. In-memory variables and session state are cleared, but files and installed packages persist on disk. The agent is unavailable until the notebook restarts and completes initialization.
By default, notebooks automatically shut down after 1 hour of inactivity.
## Session Persistence
**What persists**: Code cells, files on disk, and installed packages.
**What doesn't persist**: In-memory variables, functions, and loaded data are cleared when the notebook shuts down. On restart, autorunning re-executes all cells, which recreates these variables.
Before ending a session and shutting down the notebook, save important data to disk or upload to Latch Data. Ask the agent to help save data if needed.
## Dependencies
The agent runs in the `plots-faas` conda environment and **can automatically install custom dependencies** as needed during analysis. Installed packages persist on disk across sessions, so they're available in future sessions without reinstallation.
## Best Practices
* **Check notebook status**: If the agent seems unresponsive, verify the notebook is in the "Connected" state. It may be initializing or dormant
* **Plan for startup time**: Opening a dormant notebook requires waiting for initialization (several minutes for complex notebooks) before the agent is ready
* **Let the agent handle dependencies**: The agent automatically installs required packages; manually installing everything upfront isn't necessary
* **Save important data**: In-memory variables are cleared on shutdown, so explicitly save critical outputs to disk
* **Restart strategically**: Restart if memory issues occur, but expect temporary agent unavailability during reinitialization
# History
Source: https://wiki.latch.bio/agent/history
Access and review past conversations with Latch Agent.
All notebooks and their conversation history and analyses are tracked within the Plots tab at [console.latch.bio/plots](https://console.latch.bio/plots).
Each notebook session is isolated from one another. There is no shared memory between sessions. The agent doesn't automatically recall previous conversations when starting a new session.
# Latch MCP
Source: https://wiki.latch.bio/agent/latch-mcp
Use the Latch MCP to access the Latch platform from AI tools
## Overview
The [Model Context Protocol (MCP)](https://modelcontextprotocol.io/docs/getting-started/intro) is an open standard for connecting AI applications to external systems. You can use Latch's remote MCP server to securely connect your favorite AI development tools to the Latch platform. You can then directly access Latch resources and carry out actions on the Latch platform.
Using the Latch MCP requires you to have a Latch account. While there is no separate pricing for the MCP, you will be charged normally for any actions you perform on Latch using the MCP. For example, if you use the MCP to launch a [Latch workflow](https://wiki.latch.bio/workflows/overview), you will be charged the same as if you had launched it directly from the Latch Console or SDK.
## Setup
Authenticating to the Latch MCP only authorizes the connected AI client to access the MCP server. These credentials cannot be used for general Latch access through the Latch SDK or console.
You can install the Latch MCP as a third-party connector in Claude (web) or Claude Desktop. Follow the steps in [Claude's documentation to set up a third-party connector](https://claude.com/docs/connectors/custom/remote-mcp). When asked to provide the remote MCP URL, use `https://mcp.latch.bio/mcp`. Once you have set up the connector, you will be asked to authorize the connector to access your Latch account.
Run this command in your terminal:
```bash theme={null}
claude mcp add --transport http latchbio https://mcp.latch.bio/mcp
```
Then authenticate by running `/mcp` in Claude Code and following the OAuth flow.
First add the Latch MCP to Codex from your terminal:
```bash theme={null}
codex mcp add latchbio --url https://mcp.latch.bio/mcp
```
Then log in to the Latch MCP server:
```bash theme={null}
codex mcp login latchbio
```
Add this to your `~/.cursor/mcp.json` file:
```json theme={null}
{
"mcpServers": {
"LatchBio": {
"url": "https://mcp.latch.bio/mcp"
}
}
}
```
In Cursor, navigate to **Cursor Settings > Tools & MCP(s)**. You should see the `LatchBio` MCP server listed under `MCP Servers`. Click **connect** and proceed with the OAuth flow.
Follow the MCP setup instructions for your application using `https://mcp.latch.bio/mcp` as your remote MCP server url.
## Tools
The Latch MCP server exposes tools that allow an AI agent to interact with the Latch platform. By default, Claude will ask you for permission before launching workflow executions.
| Tool | Description |
| --------------------- | -------------------------------------------------------------------------------------------------------------------------- |
| `list_files` | Lists the immediate contents of a directory in Latch Data. File contents are not returned. |
| `get_file` | Returns access information for a file stored in Latch Data, either as a Latch Console link or as a presigned download URL. |
| `list_workspaces` | Lists the workspaces the current user can access, including the default workspace. |
| `list_workflows` | Discovers workspace workflows and public workflows that can be launched. |
| `get_workflow_schema` | Fetches launch metadata and parameter schema for a workflow. |
| `launch_workflow` | Launches a workflow with parameter values matching the workflow schema. |
| `list_executions` | Lists workflow executions in a workspace, with optional filters for name, workflow, and status. |
| `get_execution` | Fetches workflow execution status, task nodes, result files, and a Console URL. |
| `get_task_logs` | Fetches inline task logs or a presigned download URL for full task logs. |
# Modes
Source: https://wiki.latch.bio/agent/modes
Choose between Proactive and Step-by-step execution modes.
Latch Agent offers two execution modes to match your workflow preferences. Choose **Proactive** mode for autonomous execution or **Step-by-step** mode for guided, incremental analysis with approval at each stage.
## Execution Modes
### Proactive Mode
In **Proactive** mode, the agent creates a plan and executes it automatically without requiring approval. This mode is ideal for:
* **Experienced users** who trust the agent's capabilities
* **Well-defined tasks** with clear requirements
* **Time-sensitive analysis** where speed is important
* **Repetitive workflows** that follow established patterns
The agent will ask all questions it needs upfront to complete the plan, then work through it automatically from start to finish.
### Step-by-Step Mode (Default)
In **Step-by-step** mode, the agent pauses at each stage to show you results and get your approval before proceeding. This mode is ideal for:
* **Exploratory analysis** where you want to guide the process
* **Learning workflows** where you want to understand each step
* **Difficult datasets** where you want careful oversight
* **Complex analyses** where intermediate results inform next steps
You review each step's output, provide feedback, and approve before the agent continues.
## Switching Modes
You can switch between modes at any time during your session:
* **To Proactive**: Click the mode toggle to enable autonomous execution
* **To Step-by-step**: Click the mode toggle to require approval at each stage
## Best Practices
* Start with **Step-by-step** mode when exploring new analysis types
* Use **Proactive** mode for routine, well-understood workflows
* Switch to **Step-by-step** if results don't match expectations
# What is Latch Agent?
Source: https://wiki.latch.bio/agent/overview
Intelligent bioinformatics assistant for data analysis and visualization, built on Latch Plots.
Powered by Claude Opus, Latch Agent is a bioinformatics assistant built on top of [Latch Plots](/plots/overview) that helps scientists perform multiomics data analysis and visualization.
## Key Features
* **Natural Language Interface**: Describe your analysis goals in plain English—no coding required.
* **Technology-Specific Expertise**: We partner with kit, assay, and instrument providers to deliver technology-specific analysis best practices as [skills](/agent/skills) — modular packages loaded on demand for each data type.
* **Built on Latch Plots**: Seamlessly integrates with the reactive notebook environment for interactive visualizations and transparent code execution.
* **Reproducible Analysis**: View all code, plots, and methods for every analysis step to ensure scientific rigor and reproducibility.
## Supported Technologies
Latch Agent currently supports the following spatial and single-cell technologies:
Spatial transcriptomics by 10X Genomics
In situ transcriptomics by 10X Genomics
Spatial transcriptomics by Takara Bio
Spatial transcriptomics by Takara Bio
Spatial multi-omics by AtlasXomics
Multiplexed imaging by Vizgen
Interested in a technology that is not listed here? Reach out to [support@latch.bio](mailto:support@latch.bio) to request it. You can also build your own technology support using [custom skills](/agent/skills).
## See It In Action
Try Latch Agent with a demo example at [agent.bio](https://agent.bio).
## Next Steps
Learn the key concepts: plans, modes, tools, code transparency, environment, context, and history.
Understand Proactive and Step-by-step execution modes and when to use each.
Explore the capabilities available to Latch Agent, from cell manipulation to workflow execution.
Understand how Latch Agent runs on Latch Plots and manages notebook sessions.
# Plan
Source: https://wiki.latch.bio/agent/plan
How Latch Agent creates structured plans for complex tasks.
Before executing complex tasks, Latch Agent creates a structured plan that breaks down the work into manageable steps. This gives you visibility into what the agent intends to do.
## How It Works
When you request a complex analysis or task, Latch Agent automatically:
1. Analyzes your request to understand the goals and requirements
2. Creates a structured plan with sequential steps
3. Presents the plan for review (behavior depends on the execution mode)
4. Executes the plan according to your selected mode
### In Step-by-Step Mode
The agent presents the plan and waits for your approval before executing each step. You can review, modify, or approve the plan before execution begins.
### In Proactive Mode
The agent creates the plan and proceeds with execution autonomously, executing steps automatically without requiring approval at each stage.
# Skills
Source: https://wiki.latch.bio/agent/skills
Built-in technology skills and custom skills from private GitHub repositories.
Skills are prompt packages that teach the agent new capabilities — domain-specific workflows, analysis templates, institutional conventions, or technology-specific guidance. Each skill is a directory with a `SKILL.md` entrypoint that the agent loads on demand based on context.
## Developing Skills (Branch Workflow)
You can test skill changes on a branch before merging to `main` by pinning a notebook to a specific `latch-skills` branch.
Push a branch to the [`latch-skills`](https://github.com/latchbio/latch-skills) repository with your changes (new or modified skills).
In **Edit** mode, open **Runtime Settings** (via the runtime dropdown in the notebook top bar) and select your branch from the **Skills Branch** picker.
Restart the notebook runtime. On startup, the agent clones `latch-skills` at your chosen branch instead of `main`.
Send a prompt that should trigger your skill. Verify the agent loads and uses it correctly.
Once verified, merge your branch into `main`. Clear the Skills Branch setting (or leave it as default) so the notebook tracks `main` going forward.
The skills branch setting is per-notebook and persists across restarts. On every restart, the runtime fetches the latest commit on the configured branch, so you can push updates and restart without changing the setting.
## Built-in Skills
Every agent session includes Latch's public skill set from [`latch-skills`](https://github.com/latchbio/latch-skills). These are cloned automatically at startup — no registration required. By default, the `main` branch is used. See [Developing Skills](#developing-skills-branch-workflow) above to test on a different branch.
### Platform Skills
Core Latch Plots APIs and patterns:
| Skill | Description |
| ------------------- | -------------------------------------------------------------------------------------------------------------------------------- |
| `latch-plots-ui` | Widget APIs for output (plots, tables, H5 viewers), user input (selects, sliders, checkboxes), and layout (rows, columns, grids) |
| `latch-data-access` | File selection widgets, Latch Data browsing, Registry tables, and LPath utilities for `latch://` paths |
| `latch-workflows` | Launching and monitoring bioinformatics workflows — parameter construction, validation, and output retrieval |
| `latch-curation` | Curating external datasets (GEO/GSE) into Latch-compatible AnnData with Ensembl gene IDs and ontology-annotated metadata |
### Technology Skills
Provider-specific analysis workflows and best practices:
| Skill | Technology | Description |
| --------------- | ----------------------- | ---------------------------------------------------------------------------------------------------- |
| `takara-devkit` | Takara Seeker / Trekker | QC, background removal, normalization, clustering, differential expression, and cell typing |
| `xenium-devkit` | 10x Xenium | Data preparation, preprocessing, differential expression, cell type annotation, and domain detection |
| `vizgen-devkit` | Vizgen MERFISH | Cell segmentation, preprocessing, QC, spatial analysis, and secondary analysis |
| `atlasx-devkit` | AtlasXomics DBiT-seq | QC, clustering, differential analysis, and cell type annotation for spatial ATAC-seq |
## Custom Skills
Organization admins can register private GitHub repositories containing custom skills that get loaded into agent runtimes across all workspaces in the organization.
## Skill Repository Structure
A skill repository must follow this structure:
```
my-org-skills/
├── README.md # For humans browsing GitHub (not loaded by agent)
│
├── spatial-analysis/ # Each top-level directory = one skill
│ ├── SKILL.md # Required: skill entrypoint
│ ├── reference.md # Optional: supporting documentation
│ └── examples/
│ └── xenium-workflow.md # Optional: example outputs
│
├── curation/
│ ├── SKILL.md
│ ├── steps/
│ │ ├── harmonize.md
│ │ └── download.md
│ └── scripts/
│ └── validate.py # Optional: scripts the agent can execute
│
└── volcano-plot/
├── SKILL.md
└── templates/
└── template.md # Optional: templates for the agent to fill in
```
### Rules
* Each top-level directory containing a `SKILL.md` file becomes a skill
* Only one level of skill directories — no nesting skills inside skills
* `README.md` at the repo root is for GitHub — the agent does not load it
* Skill directory names must be **unique across all registered repos** in an organization. If two repos define the same skill name, syncing will fail.
## Writing a SKILL.md
Every skill needs a `SKILL.md` file with YAML frontmatter and markdown instructions:
```yaml theme={null}
---
name: spatial-analysis
description: >
Spatial transcriptomics analysis workflows. Use when the user is
working with Xenium, Visium, or MERFISH data and needs help with
spatial analysis, neighborhood detection, or co-expression.
---
When performing spatial analysis:
1. Identify the technology platform from the data
2. Load the appropriate reference panel
3. Follow the platform-specific QC workflow
4. Generate spatial plots with appropriate coloring
For detailed API usage, see [reference.md](reference.md).
```
### Required Fields
| Field | Description |
| ------------- | ------------------------------------------------------------------------------------------------------------ |
| `name` | Lowercase letters, numbers, and hyphens only (max 64 characters). Used as the skill identifier. |
| `description` | What the skill does and when to use it. The agent reads this to decide when to load the skill automatically. |
### Optional Fields
| Field | Description |
| -------------------------- | ---------------------------------------------------------------------------------- |
| `allowed-tools` | Restrict which tools the agent can use (e.g., `Read, Grep, Glob`). |
| `disable-model-invocation` | Set to `true` to prevent auto-loading. The skill can only be triggered explicitly. |
| `argument-hint` | Hint shown for expected arguments (e.g., `[dataset-name]`). |
### Supporting Files
Keep `SKILL.md` focused and under 500 lines. Move detailed reference material to separate files and link them from `SKILL.md`:
```markdown theme={null}
## Additional resources
- For complete API details, see [reference.md](reference.md)
- For usage examples, see [examples/](examples/)
```
The agent loads supporting files on demand when it follows a link from `SKILL.md`.
## Merging Multiple Repositories
When multiple repositories are registered with the same target path (the default `.claude/skills/`), their skill directories are merged side by side:
```
.claude/skills/
├── xenium-qc/ # from repo A
├── lab-conventions/ # from repo A
├── my-custom-plots/ # from repo B
└── curation/ # from repo B
```
Skill directory names must be unique across all repos. If two repos both define a `spatial-analysis/` skill, syncing will fail and the conflict will be reported in **Organization Settings → Agent Skills**.
## Registering a Repository
Generate a [GitHub PAT](https://github.com/settings/tokens) with **repo** scope so the agent runtime can clone private repositories.
Go to **Organization Settings → Agent Skills → GitHub Authentication** and enter your GitHub username and token.
Click **Add Repository** and provide:
* **Display Name**: A human-readable label (e.g., "Our Lab Skills")
* **Repository URL**: The HTTPS clone URL (e.g., `https://github.com/my-org/agent-skills.git`)
* **Branch**: The branch to track (defaults to `main`)
* **Target Path**: Where to mount in the runtime (defaults to `.claude/skills`)
When a new workspace agent session starts, the registered repositories are cloned into the runtime. The agent discovers all skills automatically.
## How Skills Are Loaded
When an agent runtime starts in a workspace belonging to your organization:
1. All registered repositories are cloned using the org's GitHub PAT
2. Skill directory names are checked for uniqueness — conflicts block the sync
3. The agent discovers `SKILL.md` files and reads their `description` fields
4. During a session, the agent automatically loads a skill when your request matches its description
Skills do not need to be invoked explicitly — the agent decides when they are relevant based on the conversation.
## Example: Technology-Specific Skill
```yaml theme={null}
---
name: xenium-qc
description: >
Xenium spatial transcriptomics QC workflow. Use when the user has
Xenium data and needs quality control, transcript filtering, or
cell segmentation validation.
---
## Xenium QC Workflow
1. Load the Xenium output bundle with `xeniumranger`
2. Check transcript counts per cell (expect >50 median)
3. Validate cell segmentation boundaries
4. Filter low-quality cells (< 20 transcripts)
5. Generate spatial QC plots
For platform-specific thresholds, see [reference.md](reference.md).
```
## Example: Institutional Conventions Skill
```yaml theme={null}
---
name: lab-conventions
description: >
Lab-specific analysis conventions and standards. Use when generating
plots, writing methods sections, or exporting results.
---
## Plot Standards
- Use colorblind-safe palettes (viridis, cividis)
- Font size: 12pt for labels, 10pt for ticks
- Always include scale bars on spatial plots
- Export as both PNG (300 DPI) and SVG
## Methods Sections
When writing methods text, cite the following versions:
- scanpy 1.10.x
- squidpy 1.4.x
- anndata 0.10.x
```
# Tools
Source: https://wiki.latch.bio/agent/tools
Internal capabilities and tools available to Latch Agent.
Latch Agent operates within [Latch Plots](/plots/overview) and has direct tools to manipulate the notebook environment. It can add, delete, and modify cells; execute code; and create interactive widgets for user interaction, and more.
## Latch Plots Manipulation
Tools used to interact with and manipulate the Latch Plots notebook interface.
Manipulate notebook cells programmatically:
* Create code cell
* Create markdown cell
* Edit cell
* Delete cell
* Delete all cells
* Run cell
* Stop cell
Cells are automatically executed after creation or editing.
Manage notebook structure and organization:
* Rename notebook
* Create tab
* Rename tab
Revert the notebook to a previously-created checkpoint state.
Useful when you are unhappy with recent prompt and notebook changes and want to revert the notebook state to the prompt before.
Generate and interact with widgets using the [Latch Plots library](/plots/widgets):
* **Set widget value**: By widget key
* **Auto-run code cells**: Configure widgets to automatically run code cells when values change
Users can interact with widgets directly, triggering real-time updates.
Interact with the H5AD viewer, a performant viewer widget in Latch Plots for single-cell and spatial data:
**Data Visualization:**
* **Change embeddings**: Switch between different embeddings (PCA, UMAP, t-SNE, etc.)
* **Color by**: Set the viewer to color cells by a specific observation or variable
* **Filter by range**: Set filters for an h5/AnnData widget to focus on specific data ranges
* **Change marker opacity**: Adjust the opacity of cell markers in the visualization
**View Controls:**
* **Autoscale**: Reset the plotted view to Plotly's autoscaled data bounds
* **Zoom**: Zoom the Plotly view in or out
**Background Images:**
* **Set background image**: Set a background image from user-attached file
* **Toggle background visibility**: Show or hide a specific background image
* **Open image aligner**: Open the image alignment modal
**Data Management:**
* **Manage observations**: Create or delete an observation column
* **Add selected cells to category**: Assign selected cells to a categorical observation
Capture images of what's displayed in the notebook to help with analysis and decision-making:
* **Capture widget image**: Take screenshots of h5/AnnData or plot widgets (Plotly, Matplotlib, Seaborn, etc.) displayed in the notebook
* **Returns metadata**: Includes base64-encoded PNG images with visualization state (color\_by settings, filters, cell counts for h5 widgets)
Use this to visually inspect plots, clustering results, or any Plotly-based visualization.
Guide user attention and interaction:
* **Spotlight UI element**: Highlight a UI element to draw attention to specific parts of the interface
Manage the agent's analysis plan:
* **Update plan**: Modify the structured plan during execution
* **Submit response**: Final responses with status, questions, and summaries
## System Access
Tools used to interact with the underlying compute environment that powers Latch Plots.
Manage the computational environment:
* **Installing dependencies**: Install Python/R packages and system dependencies on demand
Interact with the local file system:
* **Read file**: Optional offset and limit for large files (returns numbered lines)
* **Search files**: Find files matching glob patterns (e.g., 'technology\_docs/\*.md')
* **Search text**: Search for patterns using grep with line numbers (supports regex)
* **Edit file**: Replace strings using search and replace operations
Execute code and inspect variables:
* **Execute Python code**: Run code in the notebook kernel and return results, stdout, stderr, and exceptions
* **Inspect variables**: Get detailed information about global variables (type, shape, columns, dtypes) - especially useful for DataFrames and AnnData objects
Execute system and bash commands when needed for advanced operations:
## Analysis Capabilities
Latch Agent's analysis capabilities are based on partnerships with solution providers. We work with kit, assay, and instrument providers to build customized agents for each technology, ensuring best-in-class tools for each data type.
Redeem packages so the workspace gains access to technology-specific assets like data, workflows, and more.
Launch registered Latch workflows, configure parameters, retrieve results, and monitor execution progress. The available workflows are based on our solution provider partnerships.
#### Technology-Specific Workflows
| Workflow | Technology | Utility |
| ------------------------------------- | -------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------ |
| `xenium_preprocess_workflow` | 10X Xenium | Preprocesses raw Xenium output into an analysis-ready .h5ad file. Run when user provides raw Xenium data without an existing H5AD. |
| `xenium_cell_segmentation_workflow` | 10X Xenium | Re-segments cells using custom parameters or alternative segmentation methods when default Xenium segmentation is insufficient. |
| `vizgen_cell_segmentation_wf` | Vizgen MERFISH | Performs cell segmentation on raw Vizgen MERSCOPE images. Required when starting from raw imaging data without pre-computed cell boundaries. |
| `domain_detection_wf` | 10X Xenium, Vizgen MERFISH | Identifies spatial domains/niches in tissue sections using clustering of spatial neighborhoods. Useful for discovering tissue microenvironments. |
| `trekker_pipeline_wf` | Takara Trekker | Processes raw FastQ files from Takara Trekker spatial experiments into analysis-ready outputs. |
| `visium_spaceranger_to_h5ad_workflow` | 10X Visium | Converts Space Ranger output directories into .h5ad format for downstream analysis. |
| `opt_workflow` | AtlasXOmics (DBiT-seq) | Optimizes clustering parameters for spatial ATAC-seq data. |
| `compare_workflow` | AtlasXOmics (DBiT-seq) | Performs differential expression/accessibility analysis between groups or conditions. |
#### Cross-Platform Workflows
| Workflow | Technology | Utility |
| ---------------------------------- | ---------------------------- | ----------------------------------------------------------------------------------------------------- |
| `cell2location_workflow` | Cross-platform (any spatial) | Performs cell type deconvolution using a single-cell reference. Maps cell types to spatial locations. |
| `rapids_single-cell_preprocessing` | Cross-platform | GPU-accelerated preprocessing for large single-cell/spatial datasets using RAPIDS. |
Technology-specific analysis best practices are delivered through [skills](/agent/skills) — modular prompt packages that the agent loads on demand. Latch maintains a public set of skills covering platform APIs and technology workflows:
* **Platform skills**: Widget APIs, data access patterns, and workflow launching for Latch Plots (`latch-plots-ui`, `latch-data-access`, `latch-workflows`, `latch-curation`)
* **Technology skills**: Provider-specific analysis workflows, QC standards, and interpretation guidelines delivered as devkit skills (`takara-devkit`, `xenium-devkit`, `vizgen-devkit`, `atlasx-devkit`)
Organizations can also register [custom skills](/agent/skills) from private GitHub repositories to add institutional conventions, internal workflows, or additional technology support.
# Configuration Reference
Source: https://wiki.latch.bio/curate/configuration
Configuration files for cell typing and metadata harmonization
# Configuration Reference
Latch Curate uses two YAML configuration files to customize cell typing and metadata harmonization workflows. These files allow you to define custom vocabularies, ontologies, and validation rules for your datasets.
## cell\_typing\_schema.yaml
The cell typing configuration defines the vocabulary and marker genes used for automated cell type annotation.
**Location**: `~/.latch/latch-curate/cell_typing_schema.yaml`
### Configuration Fields
#### cell\_type\_column
* **Type**: `string`
* **Required**: Yes
* **Description**: Column name where cell type annotations will be stored in `AnnData.obs`
* **Default**: `"latch_cell_type_lvl_1"`
#### cluster\_column
* **Type**: `string`
* **Required**: Yes
* **Description**: Name of the clustering column in `AnnData.obs` to use for cell typing
* **Default**: `"leiden_res_0.50"`
* **Validation**: Must exist in `AnnData.obs`
#### vocabulary
* **Type**: `list[object]`
* **Required**: Yes
* **Description**: List of allowed cell types with Cell Ontology (CL) identifiers
Each vocabulary entry contains:
* **name** (`string`): Human-readable cell type name
* **ontology\_id** (`string`): Cell Ontology ID in format `"CL:XXXXXXX"`
#### marker\_genes
* **Type**: `dict[string, list[string]]`
* **Required**: Yes
* **Description**: Mapping of cell type groups to lists of marker gene symbols
* **Keys**: Cell type group names (can differ from vocabulary names)
* **Values**: Lists of gene symbols
* **Validation**: Warnings if genes are not found in `AnnData.var['gene_symbols']`
### Example Configuration
```yaml theme={null}
cell_type_column: "latch_cell_type_lvl_1"
cluster_column: "leiden_res_0.50"
vocabulary:
- name: "astrocyte"
ontology_id: "CL:0000127"
- name: "B cell"
ontology_id: "CL:0000236"
- name: "endothelial cell"
ontology_id: "CL:0000115"
- name: "T cell"
ontology_id: "CL:0000084"
marker_genes:
"T cell/NK cell":
- "CD3D"
- "CD3E"
- "CD8A"
- "CD4"
"B cell/plasma cell":
- "JCHAIN"
- "CD19"
- "MS4A1"
"astrocyte":
- "GFAP"
- "AQP4"
"endothelial cell":
- "CDH5"
- "VWF"
- "PECAM1"
```
### Validation Rules
* The `cluster_column` must exist in the AnnData object
* Cell types in the data should match vocabulary names or use format `"name/ontology_id"`
* Ontology IDs must follow Cell Ontology format (`CL:XXXXXXX`)
* Missing marker genes generate warnings but don't fail validation
### Usage in Pipeline
The cell typing schema is used by:
* `latch-curate type-cells` - Main cell typing workflow
* `latch-curate publish build` - Validation during publication
If no custom configuration exists, the system falls back to default values defined in the codebase.
## metadata\_schema.yaml
The metadata schema defines harmonized metadata variables that should be extracted and validated against controlled vocabularies or ontologies.
**Location**: `~/.latch/latch-curate/metadata_schema.yaml`
### Configuration Fields
#### variables
* **Type**: `list[object]`
* **Required**: Yes
* **Description**: List of metadata variable definitions
Each variable contains:
##### name
* **Type**: `string`
* **Required**: Yes
* **Description**: Column name to create in `AnnData.obs`
* **Convention**: Prefix with `latch_` (e.g., `"latch_disease"`, `"latch_tissue"`)
##### description
* **Type**: `string`
* **Required**: Yes
* **Description**: Natural language description of what the variable represents
* **Usage**: Used by LLM to understand what metadata to extract
##### vocab
* **Type**: `object`
* **Required**: Yes
* **Description**: Vocabulary specification defining allowed values
The `vocab` object contains:
###### vocab.type
* **Type**: `string`
* **Required**: Yes
* **Allowed Values**:
* `"uncontrolled"` - Free text, no validation
* `"ontology"` - Must match terms from a specific ontology
* `"custom"` - Must match predefined list of values
###### vocab.name
* **Type**: `string`
* **Required**: Required when `type: "ontology"`
* **Allowed Values**:
* `"mondo"` - Disease ontology
* `"uberon"` - Tissue/anatomy ontology
* `"cl"` - Cell type ontology
* `"efo"` - Experimental Factor Ontology (sequencing platforms)
###### vocab.values
* **Type**: `list[string]`
* **Required**: Required when `type: "custom"`
* **Description**: List of allowed values for custom vocabularies
### Example Configuration
```yaml theme={null}
variables:
- name: "latch_subject_id"
description: "unique patient subjects"
vocab:
type: "uncontrolled"
- name: "latch_disease"
description: "disease"
vocab:
type: "ontology"
name: "mondo"
- name: "latch_tissue"
description: "tissue or anatomical site"
vocab:
type: "ontology"
name: "uberon"
- name: "latch_sample_site"
description: "sample site"
vocab:
type: "custom"
values:
- "lesional"
- "peri-lesional"
- "normal"
- "blood"
- "in vitro"
- name: "latch_sequencing_platform"
description: "sequencing platform used"
vocab:
type: "ontology"
name: "efo"
- name: "latch_organism"
description: "organism"
vocab:
type: "custom"
values:
- "homo sapiens"
- "mus musculus"
```
### Validation Rules
* Ontology terms must be in format: `"name/ONTOLOGY_ID"` (e.g., `"systemic sclerosis/MONDO:0005100"`)
* Custom vocabulary values must exactly match one of the allowed values (case-sensitive)
* Uncontrolled fields cannot be empty
* All variables defined in the schema will be created as columns in the AnnData object
### Output Format
The harmonization process creates:
**File**: `harmonize_metadata/harmonize_metadata_metadata.yaml`
```yaml theme={null}
latch_disease:
annotations:
SAMPLE_001: "systemic sclerosis/MONDO:0005100"
SAMPLE_002: "systemic sclerosis/MONDO:0005100"
reasoning: "Based on the paper abstract..."
latch_tissue:
annotations:
SAMPLE_001: "skin/UBERON:0002097"
SAMPLE_002: "skin/UBERON:0002097"
reasoning: "Study metadata indicates..."
```
This file can be manually edited to correct errors, then re-applied using `latch-curate harmonize-metadata run --use-metadata`.
### Usage in Pipeline
The metadata schema is used by:
* `latch-curate harmonize-metadata run` - LLM-based metadata extraction
* `latch-curate publish build` - Tag extraction and validation
* `latch-curate lint` - Metadata validation
The LLM receives the variable definitions and has access to ontology search tools to find matching terms. Results are written to both the AnnData object and a YAML cache file for review and correction.
### Using with External Data
The harmonize-metadata command can work with any AnnData file using the `--adata-path` flag:
```bash theme={null}
latch-curate harmonize-metadata run --adata-path /path/to/your_data.h5ad
```
**Requirements:**
* AnnData object must have `obs['latch_sample_id']` column with sample identifiers
* The `download/` folder must exist with `study_metadata.txt` and `paper_text.txt` files
* Metadata schema must be configured at `~/.latch/latch-curate/metadata_schema.yaml`
**Example workflow for ATAC-seq:**
```bash theme={null}
# 1. Ensure your ATAC-seq AnnData has sample IDs
python3 -c "
import scanpy as sc
adata = sc.read_h5ad('atac_data.h5ad')
adata.obs['latch_sample_id'] = adata.obs['sample_name']
adata.write('atac_data.h5ad')
"
# 2. Create download folder with metadata
mkdir -p download
echo 'Study metadata here...' > download/study_metadata.txt
echo 'Paper abstract here...' > download/paper_text.txt
# 3. Run harmonization
latch-curate harmonize-metadata run --adata-path atac_data.h5ad
```
# Engineering Principles
Source: https://wiki.latch.bio/curate/engineering-principles
Core engineering and curation principles behind Latch Curate
# Engineering Principles
Latch Curate is built on carefully designed engineering principles that enable effective collaboration between language models and human curators. These principles were developed through manually curating ten million cells spanning roughly 200 datasets and covering more than 80 autoimmune indications.
## LLM Engineering Principles
### 1. End-to-End Reasoning
As the performance of frontier models continues to improve, we hypothesize that curation systems built around end-to-end reasoning will scale more effectively than architectures that rigidly partition function and order among multiple sub-agents.
Whenever possible, latch-curate embeds task context, control-flow decisions, and tool selection within a single model call rather than orchestrating an array of specialised models with fixed interaction patterns.
### 2. Precise Validation Criteria
We define precise validation criteria to capture edge cases, especially in agentic loops where test results provide the only feedback signal. Each criterion is split into:
* A natural-language description, which guides the agent
* A code assertion, which formally verifies the output and provides clear error logs
Example validation criteria:
```python theme={null}
# Natural language: "the var index consists of Ensembl IDs"
record_and_assert(validation_log,
all(map(bool, map(ensembl_pattern.match, adata.var_names))),
"var index are Ensembl IDs")
# Natural language: "var contains gene_symbols"
record_and_assert(validation_log,
'gene_symbols' in adata.var.columns,
"var contains gene_symbols")
```
### 3. Domain Knowledge as Prompts and Tools
To minimise novel reasoning per task, domain knowledge is pulled into prompts and reusable tool libraries. This focuses the model on genuine task variation, boosting accuracy while reducing runtime and cost.
Tools are developed both by:
* Hand-coding utilities during manual cleaning
* Mining logs from earlier agentic runs to find recurring operations
Task prompts evolve in the same way, becoming living documents that record edge cases and pitfalls observed across months of cleaning.
### 4. Output Integration
To integrate model outputs with conventional software, the model:
* Writes driver scripts to canonical paths
* Emits JSON data that conform to fixed schemas
Paths and schemas are validated in code; failures trigger automatic retries with validation errors appended to the prompt.
### 5. Chain-of-Thought Traces
Requesting explicit chain-of-thought traces consistently improves reasoning accuracy and provides curators with an introspectable record of the model's logic. These traces are embedded in the output JSON and surfaced in validation reports.
## Curation Principles
### 1. Understanding the Assignment
Most of the engineering effort for this system went into deeply understanding the curation task and encoding that domain knowledge into prompts, tool libraries, and tests, rather than traditional software development.
We manually curated ten million cells spanning roughly 200 datasets and covering more than 80 autoimmune indications to learn which parts of the problem were conserved and which truly varied.
For several months, we delivered data weekly to a biotech company developing autoimmune therapies, incorporating rapid feedback from domain experts to refine the process. As the curated volume grew, our prompts, tools, and tests became more robust with exposure to diverse:
* Sequencing technologies
* File formats
* Supplemental structures
* Study designs
* Downstream analytical needs
This iterative loop ensured the system met the quality bar and translational requirements of real data consumers.
### 2. Ontology-Driven Variables
Where possible, we relied on well-maintained ontologies with strong scientific backing to populate key variables:
* **MONDO** for `latch_disease`
* **CL** for `latch_cell_type_lvl_1`
* **UBERON** for `latch_tissue`
* **ETF** for `latch_sequencing_platform`
Ontology names and CURIE IDs were concatenated with slashes (e.g., "systemic sclerosis/MONDO:0005100") to avoid column duplication.
Variable scopes were set in collaboration with data consumers—detailed enough to capture study-wide nuance while remaining coarse enough to avoid ambiguities. Cell types, for example, stay at "level 1" (T cells, neutrophils, etc.), allowing users to filter atlases quickly or run specialised subtyping tools.
### 3. Validation Artifacts
Creating concise validation artifacts—reports with before-and-after plots that give curators just enough information to make decisions—proved challenging. Running large, diverse datasets through the system and iterating with domain experts revealed which plots and metrics mattered most.
### 4. Parallel Agentic Workflows
Human-in-the-loop efficiency scales when curators can juggle many agentic workflows simultaneously. A single task, such as count-matrix construction, may take 5–30 minutes before it needs human validation. Throughput peaks when enough concurrent runs keep the validation queue full.
Ongoing work aims to streamline curator triage of agentic runs and to boost throughput by dispatching containerised tasks to workflow-orchestration software.
## Technical Implementation
### Storage Standard
We adopted the Scanpy ecosystem and AnnData objects as our storage standard. Their Python-native design and widespread community support let us reuse tool libraries across agentic tasks and kept model-generated code readable.
### Version Control
Each task outputs assets - driver scripts, JSON files, agent logs, and reports - into directories that can be uploaded to version-controlled blob stores. Because the agentic workflow runs inside a versioned container with input data mounted to a sandboxed file system at well-defined locations, rerunning these workflows with modified information is straightforward.
### Reproducibility
Curated datasets are living assets, and new computational tools or updated scientific knowledge often require re-processing previously curated objects. The framework maintains complete reproducibility through:
* Versioned containers
* Fixed input/output paths
* Comprehensive logging
* Parameter files for each processing step
# Latch Curate
Source: https://wiki.latch.bio/curate/getting-started
An agentic Python framework to curate public single cell data
# Latch Curate v0.2.0
Latch Curate is an agentic Python framework designed to streamline the curation of public single cell data from GEO accession IDs into standardized, analysis-ready objects.
## Overview
The curation lifecycle consists of 7 concrete steps, each with a dedicated CLI command. Human validation is required at the end of each step through step-specific reports to ensure data quality and catch errors early in the process.
## Prerequisites
Before beginning:
* Create a fresh, dedicated directory for your curation project (ideally named after your dataset)
* Each dataset requires its own directory
* Ensure you have the GEO accession ID for your dataset
## Curation Steps
### 1. Download
Download metadata and supplementary files from GEO.
```bash theme={null}
latch-curate download run --gse-id GSE252545
```
**Required manual steps:**
* Copy and paste the paper text into `download/paper_text.txt`
* If the paper is unavailable or behind a paywall, use the abstract only
* If no abstract exists, copy the entire text from the GEO accession page
* Copy the paper URL to `download/paper_url.txt`
**Outputs:**
* GSE and SRP metadata → `download/study_metadata.txt`
* Supplementary files → `download/supp_data/`
* User-provided paper text → `download/paper_text.txt`
* User-provided paper URL → `download/paper_url.txt`
**Optional review step:**
```bash theme={null}
latch-curate download review
```
This checks if the total data size is within the model's context window limits. If this fails, remove non-essential content from `paper_text.txt` and `study_metadata.txt` (e.g., citations, dense methods sections).
### 2. Construct Counts
Build a counts matrix using an LLM with access to tools and terminal. The process continues until all tests pass.
```bash theme={null}
latch-curate construct-counts run
```
**Outputs:**
* Counts matrix → `construct_counts/counts.h5ad`
* Report → `construct_counts/counts.html`
**Standardize existing h5ad files:**
```bash theme={null}
latch-curate construct-counts run --input-h5ad /path/to/your_data.h5ad
```
Use this flag to transform an existing AnnData file to meet latch-curate standards:
* Maps gene symbols to Ensembl IDs
* Creates `obs['latch_sample_id']` from existing metadata
* Ensures `var['gene_symbols']` exists
* Prefixes author metadata with `author_`
* Validates counts are raw (non-negative integers)
**Optional chat review:**
```bash theme={null}
latch-curate construct-counts chat
```
Summarizes the steps taken and any errors encountered during construction.
### 3. Quality Control (QC)
Performs two-pass QC:
1. Conservative fixed filters (LLM-generated using paper and metadata)
2. Sample-based adaptive filters (using per-sample quantile tables)
```bash theme={null}
latch-curate qc run
```
**Important:** Inspect the report before proceeding.
**Outputs:**
* Filtered object → `qc/qc.h5ad`
* Report → `qc/qc_report.html`
* QC parameters → `qc/qc_params.yaml`
**Modify QC parameters:**
```bash theme={null}
latch-curate qc run --use-params
```
Uses parameters from `qc/qc_params.yaml` to re-run QC with custom values.
### 4. Transform
Runs standard transformation pipeline:
* Normalization
* Log transformation
* PCA
* Batch integration
* Neighborhood computation
* Embeddings generation
```bash theme={null}
latch-curate transform run
```
**Important:** Inspect the report before proceeding.
**Outputs:**
* Transformed matrix → `transform/transform.h5ad`
* Report → `transform/transform.html`
### 5. Type Cells
Computes differential gene expression between clusters and uses an LLM with controlled vocabulary to annotate cell types.
```bash theme={null}
latch-curate type-cells run
```
**Important:** Inspect the report before proceeding.
**Outputs:**
* Cell typed matrix → `type_cells/type_cells.h5ad`
* Report → `type_cells/type_cells.html`
* Annotations → `type_cells/type_cells_metadata.yaml`
**Modify cell type annotations:**
```bash theme={null}
latch-curate type-cells run --use-metadata
```
Uses annotations from `type_cells/type_cells_metadata.yaml` to re-run cell typing with corrected values.
**Run on external AnnData files:**
```bash theme={null}
latch-curate type-cells run --adata-path /path/to/your_data.h5ad
```
Use this flag to run cell typing on any AnnData object (e.g., from old projects or different assay types).
### 6. Harmonize Metadata
Uses an LLM with access to all downloaded information and ontology search tools to construct harmonized variables against controlled vocabularies.
**Harmonized variables (at sample resolution):**
* `latch_subject_id`
* `latch_condition`
* `latch_disease`
* `latch_tissue`
* `latch_sample_site`
* `latch_sequencing_platform`
* `latch_organism`
```bash theme={null}
latch-curate harmonize-metadata run
```
**Important:** Inspect the report for sample-to-variable mapping and reasoning.
**Outputs:**
* Harmonized object → `harmonize_metadata/harmonize_metadata.h5ad`
* Report → `harmonize_metadata/harmonize_metadata.html`
* Annotations → `harmonize_metadata/harmonize_metadata_metadata.yaml`
**Modify metadata annotations:**
```bash theme={null}
latch-curate harmonize-metadata run --use-metadata
```
Uses annotations from `harmonize_metadata/harmonize_metadata_metadata.yaml` to re-run harmonization with corrected values.
**Run on external AnnData files:**
```bash theme={null}
latch-curate harmonize-metadata run --adata-path /path/to/your_data.h5ad
```
Use this flag to run metadata harmonization on any AnnData object with an `obs['latch_sample_id']` column.
**Requirements**: The `download/` folder must still exist with `study_metadata.txt` and `paper_text.txt` files.
### 7. Publish
Build metadata and upload the curated dataset to the Latch Data Portal.
```bash theme={null}
# Build metadata and validate
latch-curate publish build
# Upload to data portal
latch-curate publish upload
# (Optional) Send email to paper authors
latch-curate publish email
```
**Prerequisites:**
* Configuration files at `~/.latch/latch-curate/`:
* `metadata_schema.yaml`
* `cell_typing_schema.yaml`
* Latch credentials at `~/.latch/`:
* `token` (from `latch login`)
* `workspace`
**Outputs:**
* `publish/build.yaml` - Build metadata with extracted tags
* `publish/publish.h5ad` - Final curated object
See [Publishing Datasets](/curate/publish) for detailed setup instructions and troubleshooting.
**Additional validation (optional):**
1. **Run linting tests:**
Use the [Lint Curated AnnData Workflow](https://console.latch.bio/workflows/109042) to validate object structure.
2. **Convert to Seurat:**
Use the [AnnData To Seurat Conversion Workflow](https://console.latch.bio/workflows/109453) if Seurat format is required.
## Best Practices
* Always review reports before proceeding to the next step
* Keep the original downloaded data intact
* Document any manual corrections made during the process
* Use the `--use-params` flag (for QC) and `--use-metadata` flags (for type-cells and harmonize-metadata) to iterate on automated decisions
* Maintain separate directories for each dataset curation
## Troubleshooting
* If the download review fails, reduce the size of text files by removing citations and detailed methods
* For construct-counts issues, use the `chat` command to understand what went wrong
* When QC seems too stringent or lenient, modify the parameters YAML and re-run with `--use-params`
* For incorrect cell type annotations, edit the metadata YAML and re-run with `--use-metadata`
* For incorrect metadata harmonization, edit the annotations YAML and re-run with `--use-metadata`
# Curate Overview
Source: https://wiki.latch.bio/curate/overview
Tools and workflows for curating biological data on Latch
# Latch Curate
Progress in engineering biology increasingly depends on data-hungry statistical models to reason about emergent properties that outstrip unaided human cognition. While purpose-built industrial data-generation efforts such as perturbation atlases offer a path forward, they do not yet sample sufficiently broad observational space, especially for rare indications. Aggregated public scRNA-seq datasets form the world's largest and most diverse repository of diseases, tissues, and patients, yet remain underutilized because manual structuring and annotation are costly.
* [Get Started with Latch Curate →](/curate/getting-started)
* [Read our white paper →](https://latch.bio/latch-curate)
## What is Latch Curate?
Latch Curate is a human-in-the-loop agentic framework that guides an expert scientist through an ordered, step-by-step curation lifecycle and helps them perform tasks like count matrix construction, cell typing and metadata harmonization with greater efficiency and accuracy.
## What is Data Curation?
In single-cell bioinformatics, curation describes the structuring of raw research data into well-defined count objects with controlled annotations fit for industrial use. This enables the re-use of existing experimental data with far less time and resources than de-novo generation.
The process involves:
* **Quality Control**: Filtering out low-quality data and artifacts
* **Standardization**: Converting data into consistent formats and structures
* **Annotation**: Adding biological context and cell type information
* **Harmonization**: Aligning metadata to controlled vocabularies and ontologies
* **Validation**: Ensuring data meets quality standards and specifications
## Available Tools
### Latch Curate CLI
An agentic Python framework that automates the curation of public single-cell data from GEO repositories. The framework uses large language models combined with bioinformatics tools to:
* Download and process GEO datasets
* Construct count matrices
* Perform quality control
* Transform and normalize data
* Annotate cell types
* Harmonize metadata against controlled vocabularies
## Why Public Data Curation Matters
Public-data curation fills an unmet need in single-cell data aggregation. While emerging purpose-built projects are beginning to alleviate limitations of public resources - technology heterogeneity, batch effects, quality variation and sparse perturbational sampling - they still cover only a fraction of the biological landscape and will require time to reach full breadth. Nonetheless, aggregated public datasets remain the largest and most diverse reservoir of diseases, tissues and patients. For indications with small patient populations or for complex diseases demanding fine-grained stratification, statistical models must draw on these niche biological states to achieve translational utility.
Despite the value of curated public datasets, these resources remain under-utilized because of the expensive human labour required for curation. Curators must blend PhD-level biological reasoning, single-cell analysis expertise, and data-engineering skills. They devote substantial effort to writing custom code that manipulates unstructured supplementary files, and comb through study metadata and primary papers for precise annotations.
## The Latch Curate Approach
### Human-in-the-Loop Efficiency
Human-in-the-loop efficiency scales when curators can juggle many agentic workflows simultaneously. A single task, such as count-matrix construction, may take 5–30 minutes before it needs human validation. Throughput peaks when enough concurrent runs keep the validation queue full.
### Automation with Human Oversight
* Automates repetitive curation tasks while maintaining human validation checkpoints
* Generates detailed reports at each step for quality assurance
* Allows iterative refinement of automated decisions
* Presents artifacts with plots and chain-of-thought reasoning for curator review
### Standardization
* Ensures consistent processing across datasets
* Harmonizes metadata to standard ontologies (MONDO, CL, UBERON, ETF)
* Produces interoperable data formats (AnnData, Seurat)
* Adopts the Scanpy ecosystem and AnnData objects as storage standard
### Reproducibility
* Documents all processing steps
* Maintains parameter files for reproducible analysis
* Tracks provenance throughout the curation pipeline
* Outputs assets (driver scripts, JSON files, agent logs, reports) into version-controlled directories
### Integration
* Seamlessly integrates with Latch Data for storage
* Works with existing Latch workflows for downstream analysis
* Supports standard single-cell analysis formats
* Deployed on the LatchBio platform and used by internal biotech teams and third-party solution providers
## Use Cases
* **Public Data Integration**: Curate GEO datasets for meta-analysis
* **Data Harmonization**: Standardize internal datasets to common formats
* **Atlas Building**: Prepare datasets for integration into cell atlases
* **Quality Assurance**: Validate and clean experimental data before analysis
## Getting Help
* Review the [Getting Started Guide](/curate/getting-started) for detailed instructions
* Check individual step documentation for specific parameters and options
* Contact support for assistance with complex curation projects
# Publishing Datasets
Source: https://wiki.latch.bio/curate/publish
Upload curated datasets to the Latch Data Portal
# Publishing Datasets
After completing the curation pipeline, the publish commands help you build metadata, upload datasets to Latch Data, and notify paper authors.
## Prerequisites
Before publishing, ensure you have:
1. **Completed the curation pipeline** through `harmonize-metadata`
2. **Configuration files** in `~/.latch/latch-curate/`:
* `metadata_schema.yaml` - Metadata harmonization schema
* `cell_typing_schema.yaml` - Cell typing vocabulary
3. **Latch credentials** in `~/.latch/`:
* `token` - Your Latch SDK token
* `workspace` - Workspace ID (JSON or plaintext)
### Setting Up Credentials
```bash theme={null}
mkdir -p ~/.latch
# Token is automatically created when you run `latch login`
# Or manually create it:
echo "your-sdk-token" > ~/.latch/token
# Workspace ID (get from Latch Console settings)
echo "your-workspace-id" > ~/.latch/workspace
```
### Setting Up Configuration Files
```bash theme={null}
mkdir -p ~/.latch/latch-curate
# Copy the cell typing schema from the repo
cp cell_typing_schema.yaml ~/.latch/latch-curate/
# Create metadata schema (see Configuration Reference for format)
cat > ~/.latch/latch-curate/metadata_schema.yaml << 'EOF'
variables:
- name: "disease"
description: "disease or condition studied"
vocab:
type: "ontology"
name: "mondo"
- name: "tissue"
description: "tissue or anatomical site"
vocab:
type: "ontology"
name: "uberon"
- name: "assay"
description: "sequencing assay used"
vocab:
type: "ontology"
name: "efo"
- name: "sample_site"
description: "sample collection site"
vocab:
type: "custom"
values: ["tumor", "normal", "metastasis", "blood"]
EOF
```
## Publish Workflow
### Step 1: Build
Generate metadata and validate the curated dataset.
```bash theme={null}
latch-curate publish build
```
This command:
* Extracts paper title and abstract via API
* Retrieves corresponding author contact information
* Validates harmonized metadata against your schema
* Validates cell typing against configured vocabulary
* Extracts ontology tags (disease, tissue, assay, cell types)
* Generates `publish/build.yaml` with all metadata
**Required files:**
* `download/paper_text.txt` - Paper text or abstract
* `download/paper_url.txt` - URL to the paper
* `download/external_id.txt` - GEO accession ID
* `harmonize_metadata/harmonize_metadata.h5ad` - Curated AnnData
**Outputs:**
* `publish/build.yaml` - Build metadata file
* `publish/publish.h5ad` - Final curated object
**Example output:**
```
Build complete! Please verify the following information:
============================================================
Paper Title: Single-cell analysis of human tissues
Paper Abstract: We performed single-cell RNA sequencing...
Cell Count: 45,231
Authors: Smith J, Jones A
Email Contacts: smith@university.edu
Metadata Validation Status: passed
Metadata Tags Extracted: 4
Cell Typing Validation Status: passed
Cell Typing Tags Extracted: 8
All Tags:
- disease: Alzheimer's disease
- tissue: brain
- assay: 10x 3' v3
- cell_type: neuron
- cell_type: astrocyte
... and 6 more
============================================================
```
### Step 2: Upload
Upload the dataset to Latch Data and register it in the data portal.
```bash theme={null}
latch-curate publish upload
```
You will be prompted for:
* **Destination path**: Where to store the dataset in Latch Data (e.g., `latch:///datasets/`)
* **Curator organization ID**: Your organization's ID in the system
* **Dataset version**: Version string (e.g., `v1.0.0`)
* **Curator dataset ID**: Unique identifier for this dataset (defaults to GEO ID)
**Or provide options directly:**
```bash theme={null}
latch-curate publish upload \
--latch-dest "latch:///curated-datasets/" \
--curator-id 123 \
--version "v1.0.0" \
--curator-dataset-id "GSE252545"
```
**What happens:**
1. Uploads `publish/` directory to Latch Data
2. Retrieves the ldata node ID for the uploaded files
3. Registers the dataset with the data portal API
4. Returns family ID and dataset ID on success
**Example output:**
```
Dataset Upload
Paper Title: Single-cell analysis of human tissues
Cell Count: 45,231
Validation Status: passed
Tags: 12 extracted
Uploading dataset...
Curator ID: 123
Version: v1.0.0
Dataset ID: GSE252545
Retrieved node ID 456789 for latch:///curated-datasets/GSE252545
Uploading dataset to active workspace 456789
Upload complete!
Family ID: 100
Dataset ID: 200
```
### Step 3: Email (Optional)
Send notification emails to paper authors about the curated dataset.
```bash theme={null}
latch-curate publish email
```
**Prerequisites:**
* Email configuration at `~/.latch/latch-curate/email-info.json`:
```json theme={null}
{
"smtp_host": "smtp.example.com",
"smtp_port": 587,
"smtp_user": "your-email@example.com",
"smtp_password": "your-password",
"sender_addr": "curation@latch.bio",
"starttls": true,
"timeout": 30
}
```
## Troubleshooting
### Missing configuration files
```
AssertionError (metadata_schema_path or cell_typing_config_path)
```
Ensure configuration files exist at `~/.latch/latch-curate/`. See [Configuration Reference](/curate/configuration) for schema formats.
### Missing pipeline files
```
AssertionError (paper_url_file, paper_text_file, etc.)
```
Run the full curation pipeline first, or create the required files manually:
```bash theme={null}
mkdir -p download harmonize_metadata
echo "https://example.com/paper" > download/paper_url.txt
echo "Paper text here..." > download/paper_text.txt
echo "GSE12345" > download/external_id.txt
```
### Cell typing validation failed
```
Cell typing validation failed: ["Cell type 'unknown' not in configured vocabulary"]
```
Add the missing cell type to `~/.latch/latch-curate/cell_typing_schema.yaml`:
```yaml theme={null}
vocabulary:
- name: "unknown"
ontology_id: ""
# ... other entries
```
### Token not found
```
ValueError: SDK token does not exist
```
Run `latch login` or manually create the token file:
```bash theme={null}
echo "your-token" > ~/.latch/token
```
### Workspace not configured
```
AssertionError (workspace_data_path)
```
Create the workspace file:
```bash theme={null}
echo "your-workspace-id" > ~/.latch/workspace
```
## build.yaml Reference
The build file contains all metadata for the dataset:
```yaml theme={null}
info:
description: "Paper abstract text..."
paper_title: "Single-cell analysis..."
cell_count: 45231
paper_url: "https://doi.org/..."
data_url: "https://www.ncbi.nlm.nih.gov/geo/query/acc.cgi?acc=GSE252545"
data_external_id: "GSE252545"
corresponding_author_names:
- "John Smith"
- "Jane Doe"
corresponding_author_emails:
- "smith@university.edu"
- "doe@institute.org"
validation:
metadata_validation_status: "passed"
metadata_schema_used: "/root/.latch/latch-curate/metadata_schema.yaml"
metadata_tags_extracted: 4
cell_typing_validation_status: "passed"
cell_typing_config_used: "/root/.latch/latch-curate/cell_typing_schema.yaml"
cell_typing_tags_extracted: 8
tags:
- metadata_type: "disease"
value: "Alzheimer's disease"
ontology_id: "MONDO:0004975"
- metadata_type: "tissue"
value: "brain"
ontology_id: "UBERON:0000955"
- metadata_type: "cell_type"
value: "neuron"
ontology_id: "CL:0000540"
curator:
curator_id: 123
version: "v1.0.0"
curator_dataset_id: "GSE252545"
upload_timestamp: "2024-01-15T10:30:00"
ldata_node_id: 456789
```
# Supporting Tools
Source: https://wiki.latch.bio/curate/supporting-tools
Additional tools for managing curated single-cell data
# Supporting Tools
Beyond the core curation workflow, Latch Curate provides supporting tools that help curators manage object consistency, interoperability, version control, project management, search, and data delivery.
## Linting and Conversion
### Linting Workflow
To ensure a consistent object structure, we developed a linting workflow that quickly verifies every task. This tool:
* Ensures count-construction validation criteria pass
* Verifies all controlled variables use a restricted term set
* Catches stray errors early in large ingestion projects
* Saves teams considerable time on quality assurance
Access the linting workflow: [Lint Curated AnnData Workflow](https://console.latch.bio/workflows/109042)
### Format Conversion
Many computational biologists prefer Seurat to Scanpy. Because reliable conversion libraries were lacking, we implemented a library that converts AnnData objects to Seurat in pure R by reading the relevant slots from `.h5ad` files directly on disk, avoiding approaches that embed Python interpreters inside R sessions.
Access the conversion workflow: [AnnData To Seurat Conversion Workflow](https://console.latch.bio/workflows/109453)
## Version Control and Reproducibility
Curated datasets are living assets, and new computational tools or updated scientific knowledge often require re-processing previously curated objects.
### Asset Management
Each task outputs assets into directories that can be uploaded to version-controlled blob stores:
* Driver scripts
* JSON configuration files
* Agent logs
* Validation reports
### Workflow Reproducibility
Because the agentic workflow runs inside a versioned container with input data mounted to a sandboxed file system at well-defined locations, rerunning these workflows with modified information is straightforward.
Key features:
* Versioned containers ensure consistent execution environment
* Fixed input/output paths enable reliable re-runs
* Comprehensive logging tracks all processing decisions
* Parameter files allow exact reproduction of previous runs
## Data Portal for Project Management
As curated data accumulate, project management becomes critical. We built a data portal that:
### Storage and Indexing
* Stores curated H5AD files
* Indexes the metadata generated during curation
* Enables search and filtering by metadata fields
### Project Organization
* Supports internal project organization
* Manages dataset collections by indication or study type
* Tracks curation progress across teams
### Data Distribution
* Delivers curated data to external teams or partners
* Provides secure access controls
* Maintains audit trails for data usage
## Integration with Latch Platform
### Latch Data Integration
* Direct upload of curated objects to Latch Data
* Automatic organization of outputs by project
* Version tracking for all curated datasets
### Workflow Integration
* Seamless connection to downstream analysis workflows
* Automatic triggering of follow-up analyses
* Support for batch processing of multiple datasets
### Collaboration Features
* Share curated datasets within workspaces
* Collaborative review of curation reports
* Team-based quality control processes
# BaseSpace Downloader
Source: https://wiki.latch.bio/data/basespace-downloader
This tutorial explains how to get an API key from BaseSpace that you can use to automatically import your sequencing runs into Latch.
## Step by Step
[Register here.](https://developer.basespace.illumina.com/apps)
[Create an application here.](https://developer.basespace.illumina.com/apps/new)
1. Application Name: `LatchBio <> [Your Organization] | API Key`
2. Organization Name: `LatchBio`
3. App Type: `Native`
4. Description: `For transfer of FASTQ files from BaseSpace`
[Visit the Latch Platform here.](https://console.latch.ai/)
1. You’re able to either import the raw Run files or a Project into Latch.
2. It will show up in a folder named “BASESPACE\_IMPORTS”.
# Basic Uploading and Downloading
Source: https://wiki.latch.bio/data/basic-uploading-and-downloading
## Uploading to Latch
You can click the upload button to select files or folders for upload.
Or drag and drop files or folders from your computer onto Latch.
Zipped files and directories can be uploaded to Latch and then unzipped on the platform. To unzip a file simply click hover over it, click the ellipsis menu, and press unzip.
## Downloading from Latch
If your folder is above \~4 GB we recommend using the [LatchCLI](/workflows/sdk/cli/commands#latch-cp-\-\) for a streamlined downloading experience.
To download a file or a folder simply click the ellipsis menu and click download. Folders will be zipped first before being downloaded to your computer.
# Command Line Interface Data Upload/Download
Source: https://wiki.latch.bio/data/data-command-line
For more advanced users, a quick way to interact with Latch Data files is through the command line.
### Setup
```bash theme={null}
python3 -m pip install latch
```
The Latch CLI requires Python >=3.8 and \< 3.11.
If you're on a computer where you're logged into console.latch.bio, simply enter `latch login` which will authenticate you through the browser that you're logged into.
If you are SSH-ing into a computer where you only have command line access, you
can authenticate by typing `latch login` and pasting in your Latch developer key.
### To do this:
1. First, type `latch login`. You should see the following message in the terminal:
```bash theme={null}
[ec2-user@ip-172-31-85-121 ~]$ latch login
Go to `https://console.latch.bio/settings/developer`, generate a Personal API Token (or Workspace API Token if you only need to access a single workspace from this machine), and paste it here:
```
1. Navigate to the workspace that you want to work with on [console.latch.bio](https://console.latch.bio). You can do this by clicking on your profile picture on the top left corner, and select your workspace of interest.
2. Then go down to account settings on the bottom of the avatar menu.
3. Then go to **[Developer > Access Tokens](https://console.latch.bio/settings/developer)**, generate a Workspace API Token, and copy the value shown (it is only displayed once).
4. Then on your local computer's terminal, paste in the API token you just copied.
```bash theme={null}
latch workspace
```
Verify that the authentication works and that you are in the desired workspace by typing:
```bash theme={null}
latch ls
```
Check that the content displayed in the terminal matches your files and folders on [https://console.latch.bio](https://console.latch.bio)
### Copying Data
```bash theme={null}
latch cp file.txt latch:///welcome/
```
This uploads `file.txt` and puts it into `welcome/` on Latch.
```bash theme={null}
latch cp latch:///welcome local_folder/
```
This downloads the contents of `/welcome` on Latch and puts them into `local_folder` on your local computer.
```bash theme={null}
latch cp latch:///dir1/ latch:///dir2/
```
This copies the contents of `/dir1` on Latch and puts them into `/dir2` on Latch.
```bash theme={null}
latch cp latch://123.account/dir1/ latch://456.account/dir2/
```
This copies the contents of `/dir1` in workspace 123 and puts them into `/dir2` in workspace 456.
You can find the remote path of the file you want to copy in the sidebar of the Latch Console
### Moving Data
You can also move data between two Latch directories.
For example, the following command will create `file.txt` in `dir2` and remove it from `dir1` in your current workspace.
```bash theme={null}
latch mv latch:///dir1/file.txt latch:///dir2/
```
### Syncing Data
The Latch CLI provides a simple way to sync data from a local directory to a Latch Data directory.
For example, the following command will update the contents of `dir1` in Latch Data with the contents of `local_folder` on your local computer.
```bash theme={null}
latch sync local_folder latch:///dir1
```
If you add files to `local_folder` and rerun the above command, the changes will be reflected in `dir1` in Latch Data. The `sync` command will only upload files when:
1. The file does not exist in the remote directory.
2. The last modified time of the file in the remote directory is older than the last modified time of the file in the local directory.
Note that, by default, the `sync` command will not remove files from the remote directory if they are removed from `local_folder` on your local computer. To allow files to be deleted from the remote directory, use the `--delete` flag:
```bash theme={null}
latch sync --delete local_folder latch:///dir1
```
### Other Commands
* List files in `dir1`:
```bash theme={null}
latch ls latch:///dir1
```
* Create directory `dir3`, creating parent directories `dir1` and `dir2` if they do not exist:
```bash theme={null}
latch mkdirp latch:///dir1/dir2/dir3/
```
* Recursively remove `dir2` in Latch Data:
```bash theme={null}
latch rmr latch:///dir1/dir2
```
### Behavior
All of the above commands follow the same behavior as their corresponding UNIX command.
* Using wildcards (\*):
```bash theme={null}
latch cp local_directory/* latch:///latch_folder
```
This copies all content within `local_directory` to `latch_folder`:
```
>>> latch ls latch:///latch_folder
Size Date Modified Name
12 29 Feb 00:43 A.txt
12 29 Feb 00:43 B.txt
```
* Using trailing slashes:
```bash theme={null}
latch cp local_directory/ latch:///latch_folder
```
This copies the directory itself and uploads it to `latch_folder`:
```
>>> latch ls latch:///latch_folder
Size Date Modified Name
- - local_directory/
```
* Omitting the trailing slash:
```bash theme={null}
latch cp local_directory latch:///latch_folder
```
This has the same behavior as `latch cp local_directory/ latch:///latch_folder`.
### DEPRECATED
The following commands have been deprecated and will not be available for Latch SDK version >= 2.39.2.
To check which version of latch you are using, run `latch --version`.
1. `latch rm` - Use `latch rmr` instead
2. `latch mkdir` - Use `latch mkdirp` instead
3. `latch touch` - No longer supported
4. `latch open` - No longer supported
# Mounting GCP Buckets
Source: https://wiki.latch.bio/data/mount-gcp-bucket
Latch allows you to mount your own GCP Buckets and use them the same as you would any data on Latch.
This will permit Latch to access the list of the projects that you have access to for 1 hour.
Latch requires the following permissions in your project:
* `storage.buckets.list` permission on the project level.
* `Storage Admin` on the bucket level.
Visit the [Create Custom Role page here.](https://console.cloud.google.com/iam-admin/roles/create)
1. Give the role name `Bucket Lister`.
2. Click on **Add Permissions** and enter `storage.buckets.list`. This will permit Latch to list buckets in your project which is required when mounting your bucket. After you have mounted the bucket, you can remove this permission.
3. Click on **Create**.
Visit the [IAM & Admin page here.](https://console.cloud.google.com/iam-admin/iam)
Visit the [Storage Browser page here.](https://console.cloud.google.com/storage/browser)
1. Click on the bucket that you want to mount.
2. Click on **Permissions** and `Grant Access`.
3. Enter the email address `latch-data@latchbio.iam.gserviceaccount.com` and select the role `Storage Admin`.
4. Click on **Save**.
On mount, Latch will set up notifications for the bucket to monitor file updates in the bucket and update the CORS policy to allow Latch to access the bucket data from the browser.
1. Go to the [Storage Browser](https://console.cloud.google.com/storage/browser) page in your project.
2. Click on the bucket that you want to mount.
3. Click on **Protection** and enable versioning.
The modal will close and the bucket you added will appear in the data list.
### Removing a Mounted Bucket
Simply hover over the bucket in the data viewer, click the ellipsis and select **Remove**.
## Troubleshooting
### My bucket isn't showing up in the list in the Mount GCP Bucket modal.
This might be because your bucket isn't versioned. Latch only supports versioned buckets for mounting. To check to see if your bucket is versioned or not, open the bucket in GCP, go to the **Protection** tab and check that the Object Versioning is enabled.
# Mounting S3 Buckets
Source: https://wiki.latch.bio/data/mount-s3-bucket
Latch allows you to mount your own AWS S3 Buckets and use them the same as you would any data on Latch. All you need is to connect your AWS account with Latch to mount buckets from that account.
## Prerequisites
Before you start, ensure you have an IAM role in your AWS that permits you to [create CloudFormation Templates](https://aws.amazon.com/cloudformation/resources/templates/).
Latch utilizes CloudFormation Templates to establish an IAM role that enables the configuration and discovery of your S3 buckets.
## Instructions
**Important:** Latch only supports mounting *versioned* buckets. To check if your bucket is versioned, open the bucket in S3, go to the **Properties** tab, and check **Bucket Versioning**.
### Connecting an AWS Account
This template creates an IAM role with:
* Permission to list all of your buckets,
* Permission to view or update CORS, versioning, policy, and notification settings only on select buckets you specify,
* Permission to create, tag, delete, and permission a `latch-mount-fw-*` Lambda in your account (this Lambda is limited to writing its own CloudWatch logs and forwarding incoming S3 events to SNS, SQS, or Lambda targets), and
* Permission to execute lambdas and to publish events to LatchBio's SQS queue (for configuration and bucket notifications, respectively).
The stack also creates a separate "roleReporter" Lambda with no permissions in your account that posts the new role's ARN back to LatchBio. No permission in the template allows LatchBio to read or configure your account outside of the permitted buckets.
When you open the CloudFormation template, you'll see an acknowledgment stating "The following resource(s) require capabilities: \[AWS::IAM::Role]. I acknowledge that AWS CloudFormation might create IAM resources with custom names." This pertains to you as the customer executing the CloudFormation stack. The role created by the stack has no IAM permissions, but since it needs to be created and it is an IAM role, AWS ensures that you are aware of this action. However, the role itself in the template has the permissions discussed above and no more, which can be verified by inspecting the template in the AWS UI.
You can also use wildcards (\*) to specify multiple buckets.
The 'Mount S3 Bucket' modal should show your AWS account and all of the buckets you gave LatchBio access to. You might have to click the refresh button on the modal a few times before your buckets show up.
The modal will close and the bucket you added will appear in the data list.
You can add more buckets by clicking the Add Buckets button - this will allow you to update the Cloudformation stack and give LatchBio access to other buckets in your account.
### Removing a Bucket
Removing a bucket requires edits both on the LatchBio side and in your AWS account.
Remove the bucket from the `buckets` list and update the Cloudformation
stack.
If this is the only entry in the `Statements` array, you can just delete
the bucket policy outright.
If you previously had an event notification for this bucket set up, you'll
have to: 1. Restore that notification, and 2. Go to the Lambda homepage and
delete the Lambda called `latch-mount-fw-[BUCKET_NAME]`.
Your bucket has now been removed.
## Troubleshooting
### My bucket isn't showing up in the list in the Mount S3 Bucket modal.
This might be because your bucket isn't versioned. Latch only supports versioned buckets for mounting. To check if your bucket is versioned, open the bucket in S3, go to the **Properties** tab, and check **Bucket Versioning**. If your bucket is versioned and is still not showing up, please reach out to [support@latch.bio](mailto:support@latch.bio) for assistance.
# What is Latch Data?
Source: https://wiki.latch.bio/data/overview
Latch Data is a cloud based file storage system built for storing biological data.
Store and browse all of your experiment data (raw files from a sequencer to processed results). NGS file types have a built in viewer on Latch (.fastq, .fasta, .pdb, and more) and can be opened with a simple double click.
## Get Started
Basic methods for getting data on and off of the Latch Platform.
}
href="/data/mount-s3-bucket"
>
Mount your AWS S3 bucket to the Latch File Explorer.
}
href="/data/mount-gcp-bucket"
>
Mount your GCP bucket to the Latch File Explorer.
}
href="/data/basespace-downloader"
>
Connect your Illumina BaseSpace account and download directly to Latch.
Download/upload data quickly & in bulk with LatchCLI.
Share your data with other users in and outside of Latch.
# Data Sharing
Source: https://wiki.latch.bio/data/sharing
Learn how to share your data on Latch
To share a file or a folder on Latch, select the file in the data explorer, go to the right sidebar, and click the share button:
This will open up a modal allowing you to either share by email or through a link.
### Sharing by Email
Sharing by email sends an email containing a link that allows the file/folder to be opened in a workspace. Multiple recipients can be specified.
Once added to a workspace the files are accesible in the **Shared with Me** in the folder in the Data Explorer.
### Sharing by Link
After enabling the Share by Link, a link will be generated that can sent to a recipient.
Share links for folders allow the recipient to view the files in a stripped-down data explorer. The files in the folder can be downloaded or copied to a workspace.
Share link for files will open the data viewer for that file.
# CELLxGENE
Source: https://wiki.latch.bio/data/visualizations/cellxgene
CELLxGENE Explorer allows scientists to execute interactive analyses on a dataset to explore how patterns of gene expression are determined by environmental and genetic factors using an interactive speed no-code UI.
## 1: Select the H5AD file you want to visualize
First, navigate to the H5AD file that you want to visualize. If this is your first time on Latch, you will find an example H5AD file under the folder `welcome/scbrowser/scanpy-pbmc3k.h5ad`
## 2: Start a new CELLxGENE Pod session
Latch Pod is a cloud-based computer that can scale up to 96 CPUs and 2TB of RAM, making it ideal for hosting interactive visualizations such as CELLxGENE, RShiny, Dash App, Jupyter Notebook, or RStudio.
For compute-intensive visualization of large single-cell datasets with over 1 million
cells, the customizable Latch Pod is powerful, as you can increase the RAM as needed
to accommodate growing datasets.
Please note that for H5AD files greater than 10GB, it may take up to 5-10
minutes to launch the Pod.
When a Pod is launched for the first time, the following steps occur:
1. A computer instance is started with the default configuration of 8 CPUs and 32 GiB RAM.
2. The necessary file is downloaded from Latch Data into the Pod.
3. The `cellxgene launch` command is automatically executed on the downloaded file.
All these steps together can incur a few minutes of wait time, depending on the input data size.
The CellXGene pod will open automatically.
### (Optional) 3: Change the compute resources for CELLxGENE
Sometimes, it's often desirable for single-cell applications to increase the computer's RAM for compute-intensive steps, such as computing TSNE and PCA, or running differential expression analyses.
Because CELLxGENE is directly hosted on a Latch Pod that you have direct access to, changing the underlying resource profile is easy.
First, navigate to the [Latch Pods](https://console.latch.bio/apps) tab. It should be fourth tab on the left navigation sidebar. You should see the CELLxGENE pod that you just opened.
Click on **Manage Pod**.
Scroll down to the **Compute & Storage** section, modify the cores and RAM, and click **Update**.
It will take a few seconds for your Pod to scale up.
Don't worry, all the dependencies and files are fully preserved inside the Pod during the scaling process.
Once the Pod finishes scaling up, you can verify the new resource profile on the sidebar.
### (Optional) 4: Turn off the Pod to save costs
Once you finish your analysis, you can go to the Pod and click the **Stop** button to shut down the Pod.
### Frequently Asked Questions
Currently, only one h5ad file can be visualized in a single Pod at a time. To visualize a different h5ad file, you must manually stop the Pod, restart it, and then select the new h5ad file.
This restriction is in place because CELLxGENE opens a new session for each file. This approach ensures that your session remains undisturbed by other users who might want to visualize their files.
Please follow the instructions [here](/pods/ssh#set-up-ssh-access) to SSH into your Pod.
The startup script is located at `/opt/latch/custom_app`. You can use a code editor like `vim` or `nano` to modify the script.
```bash theme={null}
nano /opt/latch/custom_app
```
Please follow the instructions [here](/pods/ssh#set-up-ssh-access) to SSH into your Pod.
To see the logs, type the following command:
```bash theme={null}
journalctl -f -b --user-unit latch-custom-app
```
# FastQC
Source: https://wiki.latch.bio/data/visualizations/fastqc
FastQC aims to provide a simple way to do some quality control checks on raw sequence data coming from high throughput sequencing pipelines. It provides a modular set of analyses which you can use to give a quick impression of whether your data has any problems of which you should be aware before doing any further analysis.
## Quick Start
## Inputs
Any .fastq or .fastq.gz file.
## Outputs
You'll see an interactive .html report that looks like this.
# Using IGV on Latch
Source: https://wiki.latch.bio/data/visualizations/igv
The Integrative Genomics Viewer (IGV) is a high-performance, easy-to-use, interactive tool for the visual exploration of genomic data. BAM, Fasta, etc. files can be opened in an IGV Browser natively within the Latch Platform.
## Opening Files in IGV
### From Latch Data
Nucleotide aequence (Fasta) and alignment files (BAM) files can be opened in the IGV browser from Latch Data. Simply double click a file to open it.
### BAM Aligment Files
Alignment files (BAM) hosted on our platform are linked with an automatically generated index file (BAI), which is utilized for when opened in the Integrative Genomics Viewer (IGV). In order to view alignment files within IGV, the reference genome to which the data has been aligned must be specified. Users have the option to choose from a selection of commonly employed genomes available on IGV (a list of these options can be found [here](/data/visualizations/igv-reference-genomes)), or alternatively, you can select your own reference genomes stored within Latch Data.
The IGV browser within Latch presently supports reference genome files in the .fasta, .fa, and .fna file formats.
To update the reference genome within the viewer, navigate to the top toolbar and click on the editing icon represented by a pen, which is located adjacent to the current genome name display.
## Adding additional tracks
Multiple BAM files can be opened in the viewer. To add a track scroll to the bottom of the last track displayed and click the `+ Add Track` button.
This will allow you to select other BAM files within your workspace. Files must be aligned to the same genome for them to show up in the viewer.
# IGV Hosted Reference Genomes
Source: https://wiki.latch.bio/data/visualizations/igv-reference-genomes
The IGV browser comes with many hosted options for common Reference Genomes to view Alignment Files to.
Here is a list of the options provided:
| Id | Reference Name | Fasta URL | Index URL | Supplementary Tracks |
| ---------------- | ------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------- |
| chm13v2.0 | Human (T2T CHM13-v2.0) | [chm13v2.0.fa](https://s3.amazonaws.com/igv.org.genomes/chm13v2.0/chm13v2.0.fa) | [chm13v2.0.fa.fai](https://s3.amazonaws.com/igv.org.genomes/chm13v2.0/chm13v2.0.fa.fai) | CAT/Liftoff Genes, Augustus, Genes |
| chm13v1.1 | Human (T2T CHM13-v1.1) | [GCA\_009914755.3\_CHM13\_T2T\_v1.1\_genomic.fna](https://s3.amazonaws.com/igv.org.genomes/t2t-chm13-v1.1/GCA_009914755.3_CHM13_T2T_v1.1_genomic.fna) | [GCA\_009914755.3\_CHM13\_T2T\_v1.1\_genomic.fna.fai](https://s3.amazonaws.com/igv.org.genomes/t2t-chm13-v1.1/GCA_009914755.3_CHM13_T2T_v1.1_genomic.fna.fai) | Annotations, Genes |
| hg38 | Human (GRCh38/hg38) | [hg38.fa](https://igv-genepattern-org.s3.amazonaws.com/genomes/seq/hg38/hg38.fa) | [hg38.fa.fai](https://igv-genepattern-org.s3.amazonaws.com/genomes/seq/hg38/hg38.fa.fai) | Refseq Genes |
| hg38\_1kg | Human (hg38 1kg/GATK) | [GRCh38\_full\_analysis\_set\_plus\_decoy\_hla.fa](https://1000genomes.s3.amazonaws.com/technical/reference/GRCh38_reference_genome/GRCh38_full_analysis_set_plus_decoy_hla.fa) | [GRCh38\_full\_analysis\_set\_plus\_decoy\_hla.fa.fai](https://1000genomes.s3.amazonaws.com/technical/reference/GRCh38_reference_genome/GRCh38_full_analysis_set_plus_decoy_hla.fa.fai) | Refseq Genes |
| hg19 | Human (GRCh37/hg19) | [hg19.fasta](https://igv-genepattern-org.s3.amazonaws.com/genomes/seq/hg19/hg19.fasta) | [hg19.fasta.fai](https://igv-genepattern-org.s3.amazonaws.com/genomes/seq/hg19/hg19.fasta.fai) | Refseq Genes |
| hg18 | Human (hg18) | [hg18.fasta](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/hg18/hg18.fasta) | [hg18.fasta.fai](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/hg18/hg18.fasta.fai) | Refseq Genes |
| mm39 | Mouse (GRCm39/mm39) | [mm39.fa](https://s3.amazonaws.com/igv.org.genomes/mm39/mm39.fa) | [mm39.fa.fai](https://s3.amazonaws.com/igv.org.genomes/mm39/mm39.fa.fai) | Refseq Genes |
| mm10 | Mouse (GRCm38/mm10) | [mm10.fa](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/mm10/mm10.fa) | [mm10.fa.fai](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/mm10/mm10.fa.fai) | Refseq Genes |
| mm9 | Mouse (NCBI37/mm9) | [mm9.fasta](https://s3.amazonaws.com/igv.org.genomes/mm9/mm9.fasta) | [mm9.fasta.fai](https://s3.amazonaws.com/igv.org.genomes/mm9/mm9.fasta.fai) | Refseq Genes, Genes |
| rn7 | Rat (rn7) | [rn7.fa](https://s3.amazonaws.com/igv.org.genomes/rn7/rn7.fa) | [rn7.fa.fai](https://s3.amazonaws.com/igv.org.genomes/rn7/rn7.fa.fai) | Genes, Genes |
| rn6 | Rat (RGCS 6.0/rn6) | [rn6.fa](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/rn6/rn6.fa) | [rn6.fa.fai](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/rn6/rn6.fa.fai) | Refseq Genes, Genes |
| gorGor6 | Gorilla (Kamilah\_GGO\_v0/gorGor6) | [gorGor6.fa](https://s3.amazonaws.com/igv.org.genomes/gorGor6/gorGor6.fa) | [gorGor6.fa.fai](https://s3.amazonaws.com/igv.org.genomes/gorGor6/gorGor6.fa.fai) | Refseq Genes, Genes |
| gorGor4 | Gorilla (gorGor4.1/gorGor4) | [gorGor4.fa](https://s3.amazonaws.com/igv.org.genomes/gorGor4/gorGor4.fa) | [gorGor4.fa.fai](https://s3.amazonaws.com/igv.org.genomes/gorGor4/gorGor4.fa.fai) | Refseq Genes |
| panTro6 | Chimp (panTro6) (panTro6) | [panTro6.fa](https://s3.amazonaws.com/igv.org.genomes/panTro6/panTro6.fa) | [panTro6.fa.fai](https://s3.amazonaws.com/igv.org.genomes/panTro6/panTro6.fa.fai) | Refseq Genes, Genes |
| panTro5 | Chimp (panTro5) (panTro5) | [panTro5.fa](https://s3.amazonaws.com/igv.org.genomes/panTro5/panTro5.fa) | [panTro5.fa.fai](https://s3.amazonaws.com/igv.org.genomes/panTro5/panTro5.fa.fai) | Refseq Genes, Genes |
| panTro4 | Chimp (SAC 2.1.4/panTro4) | [panTro4.fa](https://s3.amazonaws.com/igv.org.genomes/panTro4/panTro4.fa) | [panTro4.fa.fai](https://s3.amazonaws.com/igv.org.genomes/panTro4/panTro4.fa.fai) | Refseq Genes, Genes |
| macFas5 | Macaca fascicularis (macFas5) | [macFas5.fa](https://s3.amazonaws.com/igv.org.genomes/macFas5/macFas5.fa) | [macFas5.fa.fai](https://s3.amazonaws.com/igv.org.genomes/macFas5/macFas5.fa.fai) | Genes, Genes |
| GCA\_011100615.1 | Macaca fascicularis 6.0 (GCA\_011100615.1) | [Macaca\_fascicularis.Macaca\_fascicularis\_6.0.dna.toplevel.fa.gz](https://s3.amazonaws.com/igv.org.genomes/GCA_011100615.1/Macaca_fascicularis.Macaca_fascicularis_6.0.dna.toplevel.fa.gz) | [Macaca\_fascicularis.Macaca\_fascicularis\_6.0.dna.toplevel.fa.gz.fai](https://s3.amazonaws.com/igv.org.genomes/GCA_011100615.1/Macaca_fascicularis.Macaca_fascicularis_6.0.dna.toplevel.fa.gz.fai) | Annotations, Genes |
| panPan2 | Bonobo (MPI-EVA panpan1.1/panPan2) | [panPan2.fa](https://s3.amazonaws.com/igv.org.genomes/panPan2/panPan2.fa) | [panPan2.fa.fai](https://s3.amazonaws.com/igv.org.genomes/panPan2/panPan2.fa.fai) | Refseq Genes, Genes |
| canFam3 | Dog (Broad CanFam3.1/canFam3) | [canFam3.fa](https://s3.amazonaws.com/igv.org.genomes/canFam3/canFam3.fa) | [canFam3.fa.fai](https://s3.amazonaws.com/igv.org.genomes/canFam3/canFam3.fa.fai) | Refseq Genes, Genes |
| canFam4 | Dog (UU\_Cfam\_GSD\_1.0/canFam4) | [canFam4.fa](https://s3.amazonaws.com/igv.org.genomes/canFam4/canFam4.fa) | [canFam4.fa.fai](https://s3.amazonaws.com/igv.org.genomes/canFam4/canFam4.fa.fai) | Genes |
| canFam5 | Dog (canFam5) | [canFam5.fa](https://s3.amazonaws.com/igv.org.genomes/canFam5/canFam5.fa) | [canFam5.fa.fai](https://s3.amazonaws.com/igv.org.genomes/canFam5/canFam5.fa.fai) | Genes, Genes |
| bosTau9 | Cow (ARS-UCD1.2/bosTau9) | [bosTau9.fa](https://s3.amazonaws.com/igv.org.genomes/bosTau9/bosTau9.fa) | [bosTau9.fa.fai](https://s3.amazonaws.com/igv.org.genomes/bosTau9/bosTau9.fa.fai) | Refseq Genes, Genes |
| bosTau8 | Cow (UMD\_3.1.1/bosTau8) | [bosTau8.fa](https://s3.amazonaws.com/igv.org.genomes/bosTau8/bosTau8.fa) | [bosTau8.fa.fai](https://s3.amazonaws.com/igv.org.genomes/bosTau8/bosTau8.fa.fai) | Refseq Genes, Genes |
| susScr11 | Pig (SGSC Sscrofa11.1/susScr11) | [susScr11.fa](https://s3.amazonaws.com/igv.org.genomes/susScr11/susScr11.fa) | [susScr11.fa.fai](https://s3.amazonaws.com/igv.org.genomes/susScr11/susScr11.fa.fai) | Refseq Genes, Genes |
| galGal6 | Chicken (galGal6) | [galGal6.fa](https://s3.amazonaws.com/igv.org.genomes/galGal6/galGal6.fa) | [galGal6.fa.fai](https://s3.amazonaws.com/igv.org.genomes/galGal6/galGal6.fa.fai) | NCBI Refseq Genes |
| GCF\_016699485.2 | Gallus gallus (GCF\_016699485.2) | [GCF\_016699485.2.fa](https://igv-genepattern-org.s3.amazonaws.com/genomes/GCF_016699485.2/GCF_016699485.2.fa) | [GCF\_016699485.2.fa.fai](https://igv-genepattern-org.s3.amazonaws.com/genomes/GCF_016699485.2/GCF_016699485.2.fa.fai) | Genes, RefSeq Transcripts |
| danRer11 | Zebrafish (GRCZ11/danRer11) | [danRer11.fa](https://s3.amazonaws.com/igv.org.genomes/danRer11/danRer11.fa) | [danRer11.fa.fai](https://s3.amazonaws.com/igv.org.genomes/danRer11/danRer11.fa.fai) | Refseq Genes, Genes |
| danRer10 | Zebrafish (GRCZ10/danRer10) | [danRer10.fa](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/danRer10/danRer10.fa) | [danRer10.fa.fai](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/danRer10/danRer10.fa.fai) | Refseq Genes, Genes |
| ce11 | C. elegans (ce11) | [ce11.fa](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/ce11/ce11.fa) | [ce11.fa.fai](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/ce11/ce11.fa.fai) | Refseq Genes |
| dm6 | D. melanogaster (dm6) | [dm6.fa](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/dm6/dm6.fa) | [dm6.fa.fai](https://s3.amazonaws.com/igv.broadinstitute.org/genomes/seq/dm6/dm6.fa.fai) | Refseq Genes |
| dm3 | D. melanogaster (dm3) | [dm3.fa](https://s3.amazonaws.com/igv.org.genomes/dm3/dm3.fa) | [dm3.fa.fai](https://s3.amazonaws.com/igv.org.genomes/dm3/dm3.fa.fai) | UCSC Refseq Genes |
| dmel\_r5.9 | D. melanogaster (dmel\_r5.9) | [dmel-all-chromosome-r5.9.fasta](https://s3.amazonaws.com/igv.org.genomes/dmel_r5.9/dmel-all-chromosome-r5.9.fasta) | [dmel-all-chromosome-r5.9.fasta.fai](https://s3.amazonaws.com/igv.org.genomes/dmel_r5.9/dmel-all-chromosome-r5.9.fasta.fai) | Transcripts |
| sacCer3 | S. cerevisiae (sacCer3) | [sacCer3.fa](https://s3.amazonaws.com/igv.org.genomes/sacCer3/sacCer3.fa) | [sacCer3.fa.fai](https://s3.amazonaws.com/igv.org.genomes/sacCer3/sacCer3.fa.fai) | Refseq Genes |
| ASM294v2 | S. pombe (ASM294v2) | [Schizosaccharomyces\_pombe\_all\_chromosomes.fa](https://s3.amazonaws.com/igv.org.genomes/ASM294v2/Schizosaccharomyces_pombe_all_chromosomes.fa) | [Schizosaccharomyces\_pombe\_all\_chromosomes.fa.fai](https://s3.amazonaws.com/igv.org.genomes/ASM294v2/Schizosaccharomyces_pombe_all_chromosomes.fa.fai) | Pombase forward strand, Pombase reverse strand |
| ASM985889v3 | Sars-CoV-2 (ASM985889v3) | [GCF\_009858895.2\_ASM985889v3\_genomic.fna](https://s3.amazonaws.com/igv.org.genomes/ASM985889v3/GCF_009858895.2_ASM985889v3_genomic.fna) | [GCF\_009858895.2\_ASM985889v3\_genomic.fna.fai](https://s3.amazonaws.com/igv.org.genomes/ASM985889v3/GCF_009858895.2_ASM985889v3_genomic.fna.fai) | Annotations |
| tair10 | A. thaliana (TAIR 10) | [TAIR10\_chr\_all.fas](https://s3.amazonaws.com/igv.org.genomes/tair10/TAIR10_chr_all.fas) | [TAIR10\_chr\_all.fas.fai](https://s3.amazonaws.com/igv.org.genomes/tair10/TAIR10_chr_all.fas.fai) | Genes |
| GCA\_003086295.2 | Peanut (GCA\_003086295.2) | [GCF\_003086295.2\_arahy.Tifrunner.gnm1.KYV3\_genomic.fna](https://s3.amazonaws.com/igv.org.genomes/GCA_003086295.2/GCF_003086295.2_arahy.Tifrunner.gnm1.KYV3_genomic.fna) | [GCF\_003086295.2\_arahy.Tifrunner.gnm1.KYV3\_genomic.fna.fai](https://s3.amazonaws.com/igv.org.genomes/GCA_003086295.2/GCF_003086295.2_arahy.Tifrunner.gnm1.KYV3_genomic.fna.fai) | Annotations |
| GCF\_001433935.1 | O. sativa IRGSP-1.0 (GCF\_001433935.1) | [GCF\_001433935.1\_IRGSP-1.0\_genomic.fna.gz](https://s3.amazonaws.com/igv.org.genomes/GCF_001433935.1/GCF_001433935.1_IRGSP-1.0_genomic.fna.gz) | [GCF\_001433935.1\_IRGSP-1.0\_genomic.fna.gz.fai](https://s3.amazonaws.com/igv.org.genomes/GCF_001433935.1/GCF_001433935.1_IRGSP-1.0_genomic.fna.gz.fai) | MSU V7 genes |
| NC\_016856.1 | Salmonella enterica subsp. enterica serovar Typhimurium str. 14028S | [NC\_016856.1.fna](https://igv-genepattern-org.s3.amazonaws.com/genomes/NC_016856.1/NC_016856.1.fna) | [NC\_016856.1.fna.fai](https://igv-genepattern-org.s3.amazonaws.com/genomes/NC_016856.1/NC_016856.1.fna.fai) | NC\_016856.1.gff.gz |
| GCA\_000182895.1 | Coprinopsis cinerea okayama7#130 (GCA\_000182895.1) | [GCA\_000182895.1.fa](https://igv-genepattern-org.s3.amazonaws.com/genomes/GCA_000182895.1/GCA_000182895.1.fa) | [GCA\_000182895.1.fa.fai](https://igv-genepattern-org.s3.amazonaws.com/genomes/GCA_000182895.1/GCA_000182895.1.fa.fai) | Gene models |
More info about these options can be found [here](https://github.com/igvteam/igv.js/wiki/Reference-Genome).
To update the reference genome within the viewer, navigate to the top toolbar and click on the editing icon represented by a pen, which is located adjacent to the current genome name display.
# Setting Viewer Defaults for IGV on Latch
Source: https://wiki.latch.bio/data/visualizations/igv-setting-defaults
Learn how to set default viewer settings when opening files in IGV on Latch
## Setting Defaults
To update the defaults for the viewer go to the top toolbar and click the `Defaults` button:
The initial default properties on Latch are set to the default values of the IGV browser, to learn more about these go to the [IGV Wiki](https://github.com/igvteam/igv.js/wiki).
You are able to set general viewer defaults and display defaults for alignment tracks (BAM files). To set a new default update the value and click the save button at the bottom of the modal.
Clicking `Save` will save the defaults for when you open a file again in the browser and `Save & Apply` will reset your current session and reload it with the new defaults.
## Default Options Overview
## General Defaults
**Default reference genome:** Setting a default reference genome will automatically open all new alignment files on Latch with the specified reference. However, any manually selected reference genome for a particular file will override this default and be saved and used when the file is opened again.
## Alignment Track Defaults
These defaults correspond to the options availible after clicking the cog icon on the right side of an aligment track. These defaults will set the track view properties when a new session is started and can be overriden by changing the values in the track dropdown menu.
# Plot Artifacts
Source: https://wiki.latch.bio/plots/developer/artifacts
Use Artifacts API to create a new Plot notebook downstream of a workflow
With the Plots Artifacts API, your Latch workflow can generate a new notebook from a standard [Plot Template](/plots/developer/getting-started#:~:text=to%20create%20a-,Plot%20Template.,-Templates%20package%20everything) in your workspace and automatically populate the notebook's input widgets from parameters outputted from the workflow.
## Behavior
* Using the API in workflow code creates a Plot Artifact in Latch Data. We provide a detailed usage example below.
* Double-clicking the Artifact opens a new Plot Notebook based on the template defined in the workflow code.
* Each Plot Notebook runs on a dedicated machine:
* The machine is started the first time the Artifact is opened.
* Subsequent openings of the Artifact reuse the same machine to avoid extra costs.
## Usage
### Step 1: Define the `PlotsArtifact` dataclass:
```python Example theme={null}
from latch.types.plots import PlotsArtifactBindings, PlotsArtifactTemplate, PlotsArtifact, Widget
artifact = PlotsArtifact(
bindings=PlotsArtifactBindings(
plot_templates=[
PlotsArtifactTemplate(
template_id="1234", ## The Plot template ID
widgets=[
Widget(
transform_id="1234", ## The Python transform ID
key="1", ## The `key` of the widget that we want to populate
value="Value" ## Value to populate that widget with
)
],
)
]
)
)
```
To fill out the `PlotsArtifactTemplate` dataclass, we need to define four things:
1. The plot template ID
2. The ID of the Python transform cell that contains the widget
3. The unique ID of the widget (as one Python transform cell may contain many widgets)
4. The value we want to populate the widget with
### How to find:
* Navigate to [https://console.latch.bio/plots](https://console.latch.bio/plots)
* Click on the **+ Layout** icon.
* Click on the screwdriver icon to access the Template's settings.
* See the Plot Template's ID circled in the screenshot below. The template ID is the number to the right.
* Create a new notebook from the template
* Make sure you turn on **Dev Mode** for the notebook.
* Navigate to the cell of interest.
* Copy the ID underneath the cell.
When creating the Plot notebook's template, provide the widget with key like so:
```python Inside a code cell of a Plot Template theme={null}
from lplots.widgets.select import w_select
input_1 = w_select(
label="First input",
options=["A", "B", "C"],
key="input_1"
)
input_2 = w_select(
label="Second input",
options=["X", "Y", "Z"],
key="input_2"
)
```
**Pro-tip**: Not all the widgets in your original template have explicitly defined keys. If not, the key value is the order of the widget in that cell.
**Example**: Let's say a Python transform cell has three widgets:
* widget 1: (no key) => Key value is "0"
* widget 2: (key = "k") => Key value is "k"
* widget 3: (no key) => Key value is "1"
### Step 2: Upload the dataclass to Latch Data
Next, dump the dataclass into a JSON file and upload it to Latch Data.
```python expandable theme={null}
from latch.types.plots import PlotsArtifactBindings, PlotsArtifactTemplate, PlotsArtifact, Widget
@small_task
def my_task(output_dir: LatchDir) -> LatchFile:
artifact = PlotsArtifact(
bindings=PlotsArtifactBindings(
plot_templates=[
PlotsArtifactTemplate(
template_id="46", ## The Plot template ID
widgets=[
Widget(
transform_id="1234", ## The Python transform ID
key="input_1", ## The `key` of the widget that we want to populate
value="petal.width" ## Value to populate that widget with
)
],
)
]
)
)
# Convert the dataclass to a dictionary
artifact_dict = artifact.asdict()
# Write it to a JSON file
with open("artifact.json", "w") as f:
json.dump(artifact_dict, f, indent=2)
# You need to return a file artifact for the workflow
return LatchFile(output_path, f"{output_dir.remote_path}/artifact.json")
```
# Installing Custom Dependencies
Source: https://wiki.latch.bio/plots/developer/dependencies
How to install custom dependencies for your Plot runtime
Each Plot notebook runs on its own dedicated compute instance and uses dependencies from the `plots-faas` conda environment.
With SSH access, you can directly connect to the underlying environment to inspect current dependencies or install new ones as needed.
# Connect to Plot notebooks via SSH
Visit [our documentation here](/plots/developer/ssh) to set up SSH access and connect to your Plot notebook.
# Install new packages
After connecting to Plot via SSH, activate the `plots-faas` conda environment by running:
```bash theme={null}
mamba activate plots-faas
```
Inspect the existing dependencies by typing:
```bash theme={null}
mamba list
```
Install new packages using mamba install like so:
```bash theme={null}
mamba install scanpy
```
**Pro-tip**:
With terminal access to the underlying Plot's compute instance, you're not limited to just conda packages—you can also install Linux packages and other software.
# Develop your First Plot Notebook
Source: https://wiki.latch.bio/plots/developer/getting-started
Latch Plots are similar to Jupyter Notebooks, built around Python cells that you can chain together to analyze, visualize, and interact with your data.
Unlike standard notebooks, Latch Plots allow you to:
* Define interactive input widgets using pure Python
* Enable reactive execution, where input changes automtically trigger dependent cells
* Instantly convert notebooks into shareable, interactive Apps
In the walkthrough below, you'll learn how to build an interactive App using Latch Plots in under 10 minutes.
* Navigate to the Latch Plots tab at [https://console.latch.bio/plots](https://console.latch.bio/plots).
* Click **Start from a blank layout**.
* Click “+ Analysis” to add your first Python cell.
* The cell will be pre-populated with code that defines an input widget for loading a CSV file from either Latch Data or Latch Registry.
* To proceed:
* Select the Latch Data option to open the file browser.
* Navigate to: welcome > gsea\_pathway > CoCl2 vs Control (Condition).csv
* Click the file to load it into your Plot.
Code explanation:
The `.value` attribute in `datasource.value` does two things:
* Returns the selected value from the widget (in this case, a Pandas DataFrame from the selected file or table).
* Subscribes the current cell to the widget, so that if the user changes their selection, the cell will automatically re-run with the new value.
This is part of what makes Latch Plots reactive: your code updates in real time as users interact with the interface.
Let's create a volcano plot to visualize differential gene expression.\
You'll also add two text input widgets so users can adjust the significance thresholds (e.g., log₂ fold change and p-value cutoff) interactively to highlight differentially expressed genes.
You can put any content in here, including other components, like code:
```python theme={null}
import plotly.express as px
import numpy as np
from lplots.widgets.text import w_text_input
from lplots.widgets.plot import w_plot
from lplots.widgets.row import w_row
# Create input widgets for thresholds
padj_threshold = w_text_input(
label="Adjusted p-value threshold (-log10)",
default="1.3" # -log10(0.05)
)
lfc_threshold = w_text_input(
label="Log2 Fold Change threshold",
default="1"
)
# Create the volcano plot
def create_volcano_plot(df, padj_thresh, lfc_thresh):
# Convert threshold strings to floats
padj_thresh = float(padj_thresh)
lfc_thresh = float(lfc_thresh)
# Add a column to color points based on significance and fold change
df = df.copy()
df['-log10(padj)'] = -np.log10(df['padj'])
conditions = [
(df['-log10(padj)'] > padj_thresh) & (df['log2FoldChange'].abs() > lfc_thresh),
(df['-log10(padj)'] > padj_thresh) & (df['log2FoldChange'].abs() <= lfc_thresh),
(df['-log10(padj)'] <= padj_thresh) & (df['log2FoldChange'].abs() > lfc_thresh)
]
values = [
'Significant & High Fold Change',
'Significant Only',
'High Fold Change Only'
]
df['Significance'] = np.select(conditions, values, default='Not Significant')
# Create the volcano plot
fig = px.scatter(
df,
x='log2FoldChange',
y='-log10(padj)',
color='Significance',
color_discrete_map={
'Significant & High Fold Change': 'red',
'Significant Only': 'blue',
'High Fold Change Only': 'green',
'Not Significant': 'grey'
},
opacity=0.6,
template="simple_white"
)
# Add threshold lines
fig.add_hline(y=padj_thresh, line_dash="dash", line_color="grey")
fig.add_vline(x=lfc_thresh, line_dash="dash", line_color="grey")
fig.add_vline(x=-lfc_thresh, line_dash="dash", line_color="grey")
# Update layout
fig.update_layout(
title="Volcano Plot of Differential Expression",
xaxis_title="Log2 Fold Change",
yaxis_title="-log10(Adjusted p-value)",
legend_title="Significance"
)
return fig
# Create plot
fig_volcano = create_volcano_plot(df, padj_threshold.value, lfc_threshold.value)
# Display widgets in a row and plot
w_column(items=[
w_row(items=[padj_threshold, lfc_threshold]),
w_plot(source=fig_volcano)
])
```
Click Run to execute the cell. Then, try adjusting the input values. Your volcano plot will automatically update in response.
On the left-hand side of the notebook, next to the "Run All" button, click the "Switch to App Mode" icon.
In App Mode, the following elements from Edit Mode are hidden:
* Python code cells
* Cell borders
* Run buttons
* Developer-specific sidebar features (e.g., versioning)
This gives end users a clean, intuitive, and fully interactive App experience.
Now that you've set up the interface and logic for your App, it's time to create a **Plot Template.**
Templates package everything—your code, widgets, visualizations, and environment—into a reusable blueprint. This makes it easy for scientists to launch their own dedicated Plot Notebooks preloaded with your App, and start analyzing data instantly.
To create a Template:
* On the right handside of your Plot notebook, click "Save Version". Provide your version with a descriptive name.
* Click the three dots next to the newly created version. Select "Create new template from version".
* Provide a name and description for your template.
That's it! You have successfully created your first App and saved it as a reproducible template for the entire team.
# Plots Reactivity
Source: https://wiki.latch.bio/plots/developer/reactivity
Learn how reactivity works in Plot notebooks
Inside a Plots notebook, cells will automatically rerun in response to a change in widget values. This feature is powered by a generic reactivity system that can be used to encode aribtrary data dependencies between parts of a notebook's code.
## Introduction
The reactive system is based on two primitive objects:
* *signals,* which store a reactive value,
* and *computation nodes,* which store a reactive function.
Computation nodes that read a signal value will be automatically *subscribed* to the signal. Later, when a signal value changes, all its subscribers get re-executed.
This is how the familiar example of widget reactivity works:
1. Widgets are created alongside a signal for their value.
2. Cells are implicitly wrapped up in computation nodes.
3. When a cell runs, it may access a widget value through the signal. If it does, the signal records that the cell's computation node needs to rerun when the value changes.
4. User input causes the UI to send an update to the kernel, which updates the widget value signal, which reruns all of its subscribers.
## Custom Signals
Signals can be created at any time, independent of any widgets.
```py3 theme={null}
from lplots.reactive import Signal
value = Signal(10)
```
To read the signal's value, call it with no arguments. This will subscribe the current computation node to the signal:
```py3 theme={null}
x = value()
# now subscribed to changes in `value`
print(f"value = {x}")
```
To update the signal's value, call it with the new value as an argument:
```py3 theme={null}
value(10)
# the previous cell will automatically rerun
```
The signal stores a reference to the value and will not react to changes within the stored object. It is best practice to treat signal values as immutable:
```py3 theme={null}
obj = Signal({})
# Bad practice:
# mutating a signal value
#
obj()["hello"] = "world"
# *does not* cause an update
# Best practice:
# treating the signal value as immutable and copying it
#
obj({**obj(), "hello": "world"})
```
**Avoid infinite update loops** by making sure a cell never unconditionally updates a signal that it is subscribed to:
```py3 theme={null}
x = value()
# now subscribed to changes in `value`
value(x + 10)
# !!! Infinite update loop
# cell 4 will
# 1. subscribe to changes in `value`,
# 2. cause a change in `value`,
# 3. rerun because `value` changed,
# 4. cause a change in `value`,
# 5. rerun because `value` changed,
# ...
if x < 50:
value(x + 10)
# OK: the update loop will stop whenever `value` reaches 50
```
`.sample()` allows reading a signal value *without subscribing* to its changes:
```py3 theme={null}
x = value.sample()
# this cell will *not* rerun automatically
print(f"value = {x}")
```
## Reactive Transactions
Signal updates are delayed until the current cell finishes running all the way through:
```py3 theme={null}
## =-= =-=
value = Signal(10)
value_str = Signal("10")
x = value.sample()
assert x == 10
value(20)
value_str("20")
x = value.sample()
assert x == 10
# the value did not change yet!
value(30)
value_str("30")
# this update will override the previous one
## =-= =-=
## =-= =-=
assert str(value.sample()) == value_str.sample()
## =-= =-=
## After the cell 1 finishes:
assert value.sample() == 30
assert value_str.sample() == "30"
```
This somewhat unintuitive behavior is a best practice established in reactive systems design as it helps keep the overal state of the system consistent at all times.
In the previous example `value` and `value_str` are obviously related. The delayed updates ensure that the relationship is preserved at all times—cell 2 *will never trigger an `AssertionError`.*
Contrast this with a hypothetical system that applies updates immediately.
```py3 theme={null}
...
value(30)
# Causes cell 2 to rerun immediately:
#
# assert str(value.sample()) == value_str.sample()
# !!! AssertionError:
# !!! value.sample() == 30
# !!! value_str.sample() == "20"
value_str("30")
...
```
A reactive transaction can actually include more than one cell. If a signal update causes multiple cells to rerun, *all of these cells* will belong to a transaction:
```py3 theme={null}
# value = Signal(1)
# cell_a:
a(value() + 10)
# cell_b:
b(value() * 2)
# cell_print:
print(f"cell_print {a()}, {b()}")
# Run all the above cells.
# Add and run a new cell:
# cell_main:
value(20)
# Update order:
# Transaction 1:
# 1. cell_main
#
# Apply signal updates:
# value = 20
# reruns cell_a, cell_b
#
# Transaction 2:
# 1. cell_a
# 2. cell_b
#
# Apply signal updates:
# a = 30
# reruns cell_print
# b = 40
# reruns cell_print
#
# Transaction 3:
# 1. cell_print
# Program output:
# cell_print 11 2
# cell_print 30 40
```
Note that we do not see any of the intermediate states e.g. `cell_print 30 2`, `cell_print 11 40`; which could be printed in an immediate-update system.
## Reactivivity with Conditionals
Each time a cell reruns, it starts from a fresh state and will forget all its previous subscriptions. This means that a cell is *only subscribed to the signals it access during its last run.*
Cells with conditionals can change their subscriptions on each run:
```py3 theme={null}
# value = Signal(10)
# value_str = Signal("10")
if value() > 30:
# will not run as 10 < 30
x = value_str()
print(f"value_str = {x}")
# this cell subscribes to `value` but *not* `value_str`
```
If the value of `value` changes to `50`, the cell will execute the conditional and thus access and subscirbe to `value_str`.
If necessary, the cell can always uncoditionally subscribe to a signal by just accessing its value and not using it:
```py3 theme={null}
value_str() # subscribe to `value_str`
if value() > 30:
...
```
## Redefining Signals
In Python, setting a variable will dispose of the old value entirely:
```py3 theme={null}
x = {"subscribers": []}
x["subscribers"].append("cell 1")
x = {"subscribers": []}
assert len(x["subscribers"]) == 0
```
This is annoying with signals, as the cell defining the signal can rerun and then the signal would be recreated with no subscribers. There is a special rule in Plots notebooks that *global variables holding a signal* will not be disposed of when overriding them. Instead, the signal value will be updated:
```py3 theme={null}
# value = Signal(10)
# subscribers: cell 1
value = Signal(20)
# equivalent to `value(20)`
# will keep the old subscribers
# value = Signal(20)
# subscribers: cell 1
```
To replicate the default behavior and throw out the old signal, use `del`:
```py3 theme={null}
# value = Signal(10)
# subscribers: cell 1
del value
# old signal is gone, including its subscriber list
value = Signal(20)
# no subscribers
```
When using local variables, no special rule applies. To avoid overriding a signal in a local variable, check `locals()`:
```py3 theme={null}
if "value" not in locals():
value = Signal(10)
```
# Cheatsheet
1. `x = Signal(initial)` defines a new signal with value set to `initial`
2. `x()` reads the value of the signal and subscribes
3. `x(10)` sets the value of the signal
4. `x.sample()` reads the value of the signal *without subscribing.* Useful to avoid infinite update loops
5. Signal updates are delayed until the current transactions ends
6. Each time, all updated cells execute in one transaction
7. Cells only subscribe to signals they accessed during the last run
8. Signal values should be treated as immutable
9. Re-assigning a signal to a global variable will override the value but not clear subscribers
# SSH into the Plot Runtime
Source: https://wiki.latch.bio/plots/developer/ssh
How to connect to Plots runtime using SSH
Each Plot notebook is backed by a dedicated compute instance and offers SSH access for direct connection to the underlying environment.
Plots use public SSH keys to authorize which machine is allowed to connect to Plots.
```bash theme={null}
$ cat ~/.ssh/id_rsa.pub
```
If you receive an error message saying that **id\_rsa.pub** doesn’t exist, it means that your computer doesn’t have a public SSH key.
Generate one using ssh-keygen: `$ ssh-keygen`
Copy the key with: `$ pbcopy < ~/.ssh/id_rsa.pub`
Find [the Developer Settings page here.](https://console.latch.bio/settings/developer)
Make sure that there is no extra line or space at the end of the SSH key.
Latch only authorizes access to users whose public SSH keys are added here. If
you have multiple developers on the team who want to access the same Pod, it
is recommended that you add their keys here. Latch supports up to 50 keys for
each workspace.
Navigate to your Plot notebook. Click on the **Dev Toggle** to turn on developer settings. Then, click on the **SSH** icon to copy the SSH command to your clipboard.
You can only SSH into a Pod if it is running.
### Troubleshooting
Below are a few common errors when trying to connect to Pods via SSH access.
```bash theme={null}
kex_exchange_identification: Connection closed by remote host
```
* This means that an error cannot be established between your local computer and Pods.
* Try stopping and starting your Pod to refresh the connection.
You cannot SSH into a Pod when the status of Pod is **Dormant** or **Starting**. You can only establish a connection to the Pod when it is running.
* The error means that the SSH key Pod is authenticating is different from the SSH key on the computer you are trying to connect from. Hence, Pod rejects your connection.
* Double check at the SSH key you have on [Account Settings > Developer](https://console.latch.bio/settings/developer) is the same as the SSH key of the machine you’re trying to connect from.
* If the SSH keys are the same, but you are still unable to connect to Pod via SSH, this may mean that you added your SSH keys to the Developer Settings after the Pod was created. Manually restart your Pod to load in the SSH keys.
# LLM Integration for Plots
Source: https://wiki.latch.bio/plots/integrations/llm
Use LLM to assemble fully interactive analyses and applications in Latch Plots
## Capabilities
Latch Plots has a built-in LLM capable of performing various tasks, from basic statistical analyses and visualizations in Python to building fully interactive applications.
To achieve this, we prompt engineered Claude 3 to:
* Create **Python cells** with interactive input widgets
* Install any library and write any code for analyses
* Use **Text** cells for displaying text-based responses to questions
* Choose the correct cell based on the user-inputted prompt
* Navigate to correct line numbers of target cell to fix errors
* And more
All files and folders uploaded to Latch are stored in Latch Data, a remote data/ object store on Latch. The LLM knows how to read and write data from and to LData using Python's [LPath APIs](https://wiki.latch.bio/workflows/sdk/python/working-with-files).
The LLM the has context of all current and previous cells in the notebook, including existing global variables, previously written code, and past prompts.
Every LLM prompt box includes an **Attach** button, allowing you to select one or more dataframes from your current notebook or files and folders stored on Latch Data. You can also attach instructional documents, such as analysis tutorials (e.g., scanpy), to provide context and guide the LLM’s analysis.
All results and code generated by the LLM are stored in that Plot notebook, ensuring traceability and reproducibiltiy for future analyses
## Examples
We walk through a few common examples of effective prompts to demonstrate how the LLM can be used in realistic biological flows.
### Example 1: Generate Prism-like Dose-Response Curves
Below is a typical XY table from GraphPad Prism that records the responses between two groups (No Inhibitor vs. Inhibitor) against various agonist concentrations. Our end goal is to create a graph set of two dose-response curves.
First, to make it easier to work with, we transformed the GraphPad Prism XY table format to a long table format with columns such as sample names, replicates, condition (Inhibitor vs. no inhibitor), agonist concentration, and dose-response values.
To upload this file to Plots, click **Attach → Files → Drag and drop** the file to the Latch data browser. Then click **Select.**
Because the agonist concentrations span many orders of magnitude, we want to log-transform these concentration values before performing nonlinear regression.
**Prompt:** Log transform the Agonist Concentration column. Store the results in a new column called Log\_Agonist\_Concentration.
**Result:** The LLM will write Python code using LPath APIs to download the remote file from Latch Data and pandas to read the local file into a data frame for analysis. Every data frame on Latch Plots comes with a default table viewer, so you can inspect what the results look like.
**Prompt**: Create a plot with two dose-response curves, one for inhibitor and one for no inhibitor. Log agonist concentration is on the X axis, and Value is on the Y axis. Use the Variable slope (four parameters) model for logistic regression.
**Result:** The LLM will write code using curve\_fit from the scipy.optimize library to create the dose-response curves.
You can further prompt the LLM to update the aesthetics of the graph to mimic the GraphPad Prism style.

**Prompt:** The x-axis, labeled '\[Agonist], M', should be on a logarithmic scale ranging from 10^-10 to 10^-3, and the y-axis, labeled 'Response', should range from -100 to 500. Plot two datasets: 'No inhibitor' (blue circles) and 'Inhibitor' (green squares). Add smooth fitted curves to both datasets, with blue and green colors matching the markers. Include a legend in the top left corner with corresponding symbols. Use solid lines for the fitted curves, simple fonts, and minimal gridlines for a clean presentation.
### Example 2: Perform statistics between groups
When comparing groups, adding statistical annotations to plots can be helpful. **statsannotation** is a robust Python library that simplifies this process by calculating p-values and adding annotations for various statistical tests (using scipy.stats), including:
* Mann-Whitney
* t-test (independent and paired)
* Welch's t-test
* Levene test
* Wilcoxon test
* Kruskal-Wallis test
* Brunner-Munzel test
Instead of writing custom functions and manually adjusting aesthetics, it’s recommended you install **statsannotation** and prompt the LLM to use it directly.
**Prompt:** Install the statsannotation library.
Next, we want to provide the LLM with the context on how to use the library. To do so, we can download the [README.md](https://github.com/trevismd/statannotations/blob/master/README.md) from the library’s GitHub and attach it as a file to the LLM. Confirm that the document’s context is added by asking the LLM to provide a summary of the library.
**Prompt:** Use the statsannotations library to create box plots of IC50 (µM) across different Cell Lines.
For the first pass, the plot generated can be cluttered.
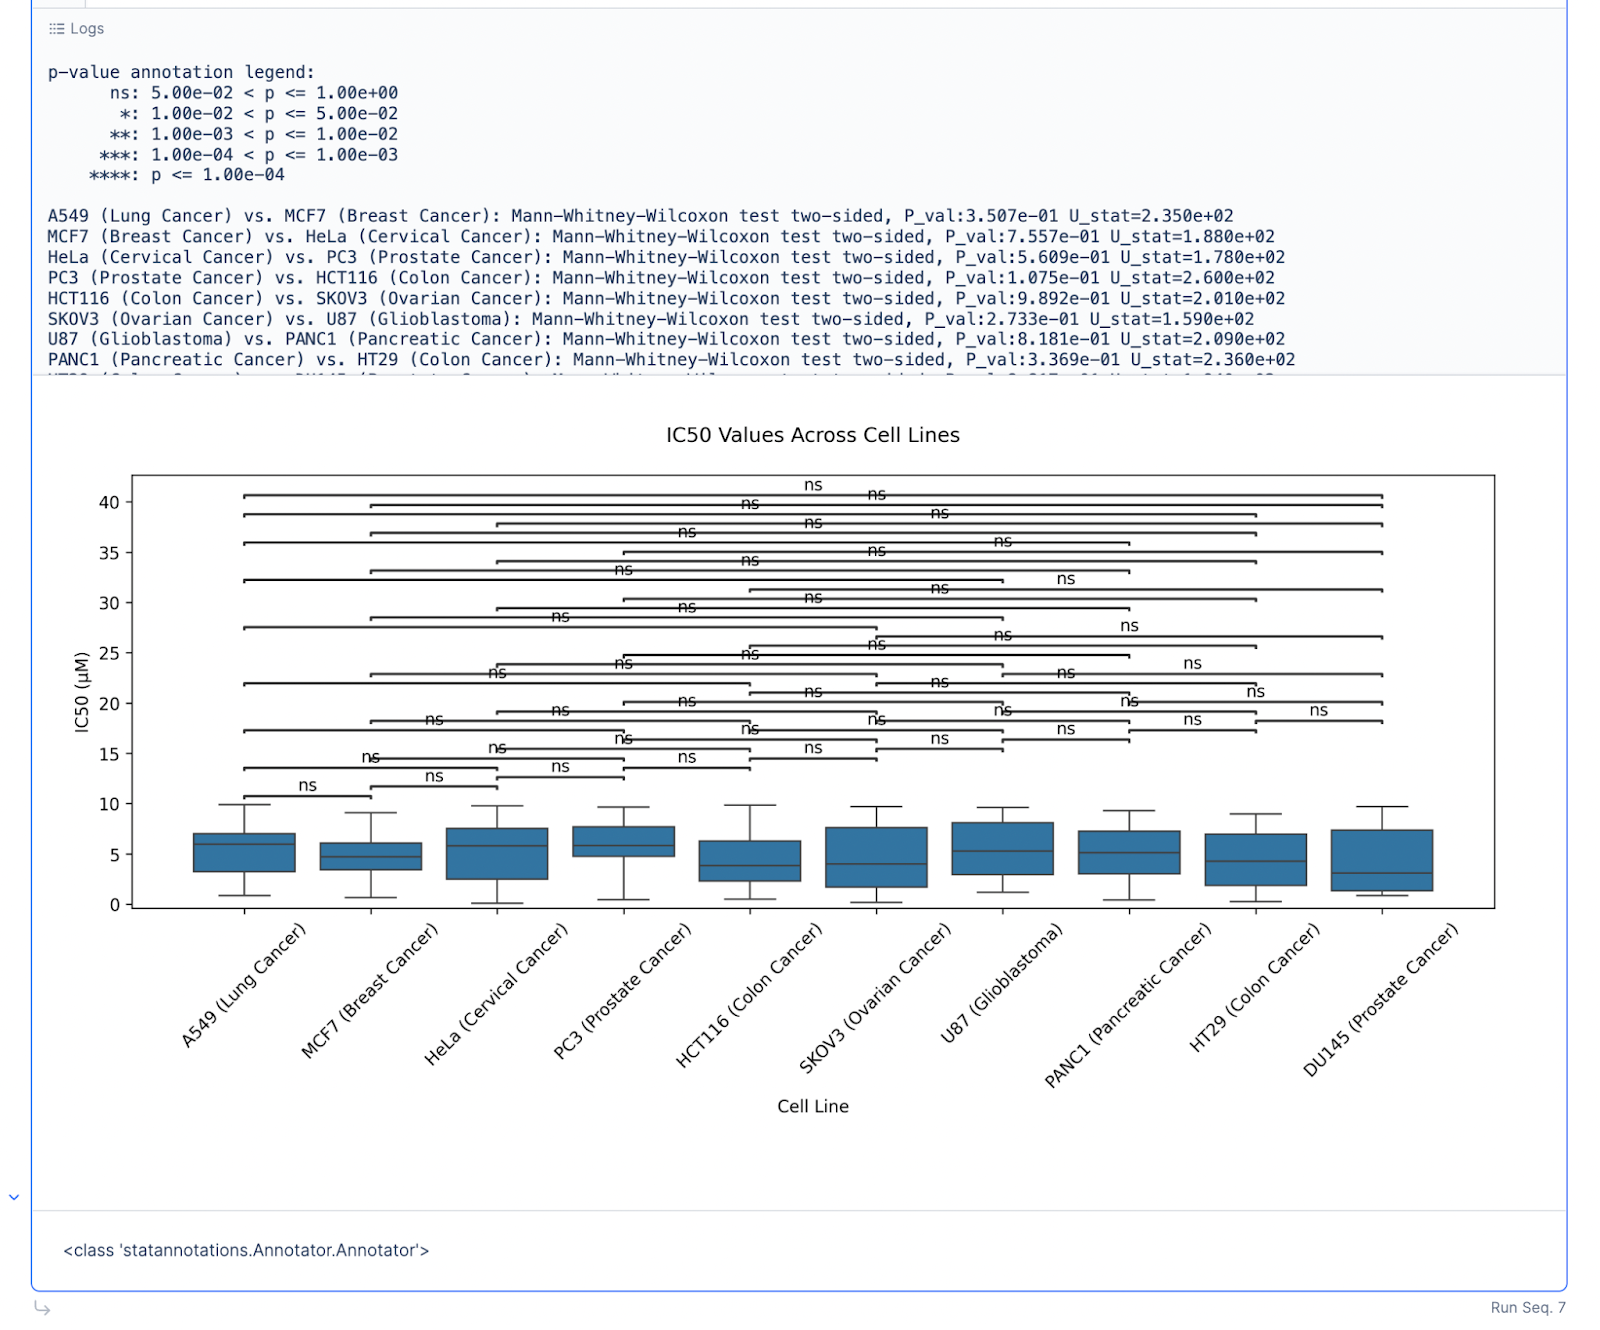
**Prompt:** Hide the non-significant annotations.
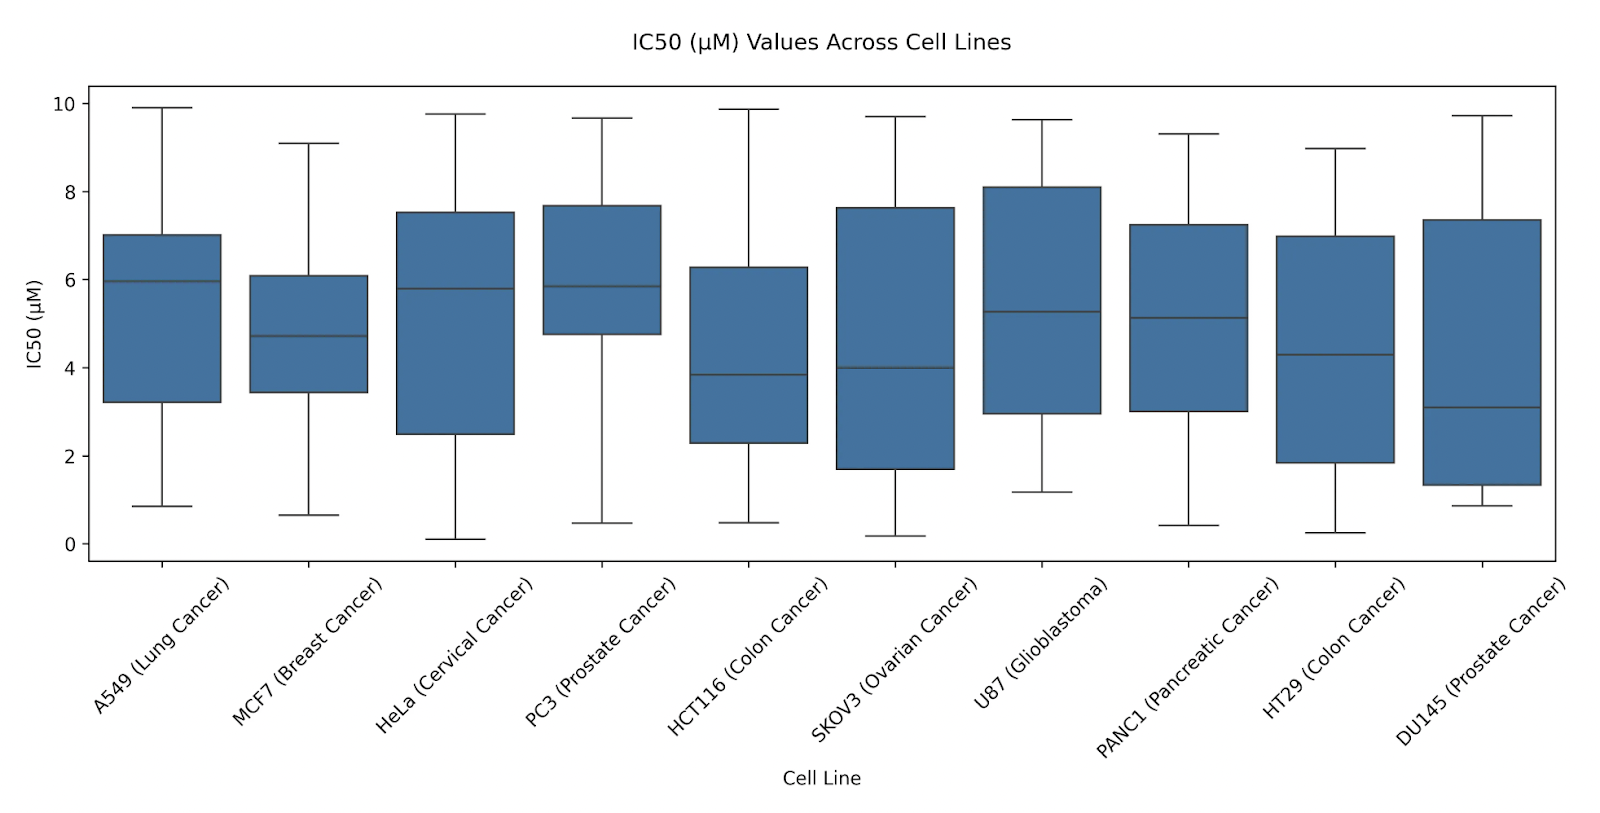
You can also explicitly specify pairs to compare between.
**Prompt:** Only show the statistical annotation between "HCT116 (Colon Cancer)" and "U87 (Glioblastoma)".
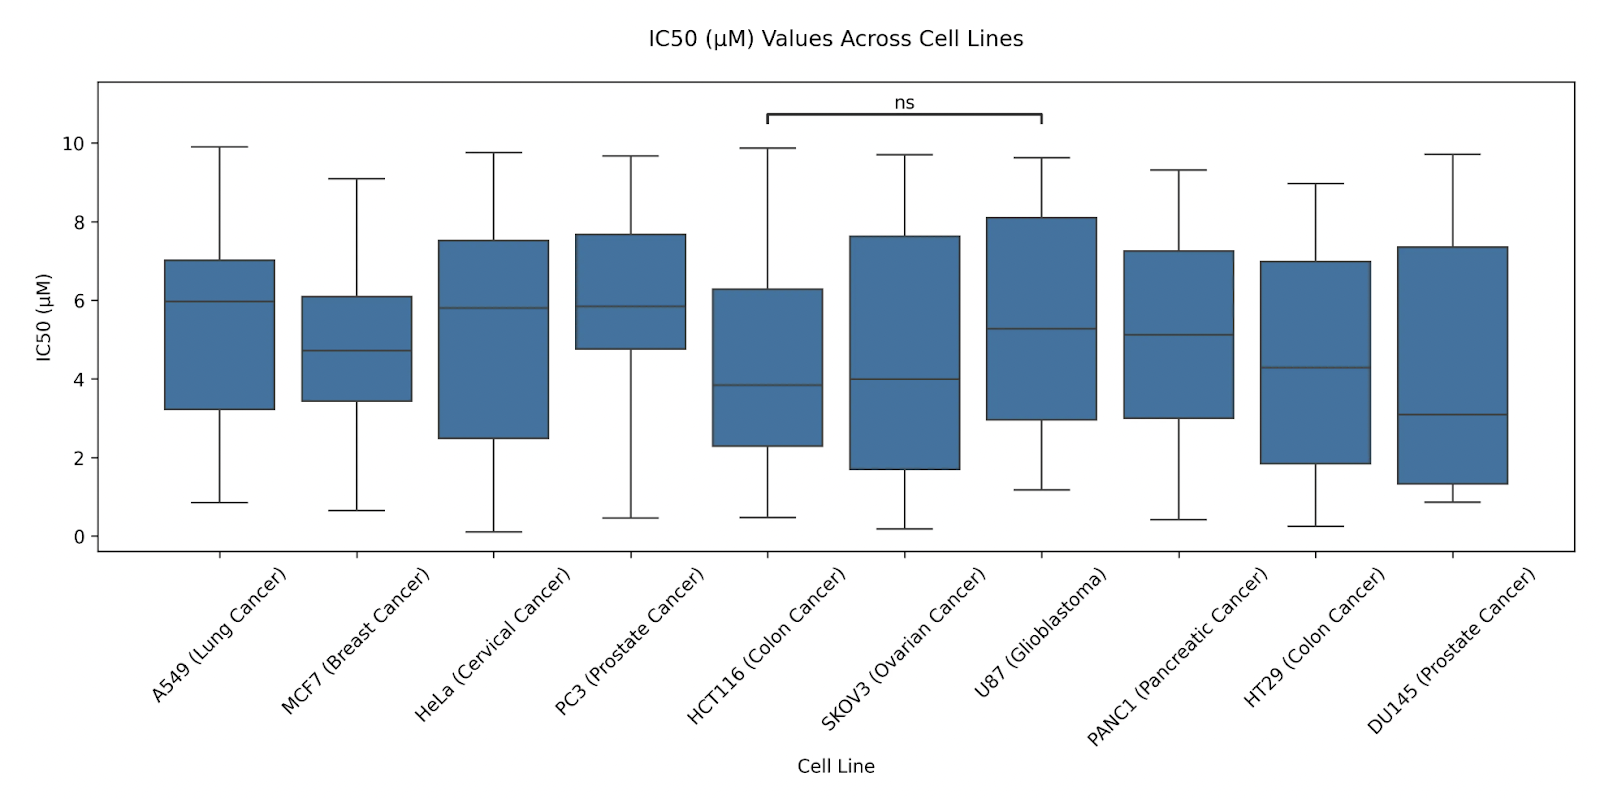
### Example 3: Perform Data Integration & Single-cell Analyses
Next, we walk through a more advanced examples of common steps in single-cell analysis, using the paper [Repeated peripheral infusions of anti-EGFRvIII CAR T cells in combination with pembrolizumab show no efficacy in glioblastoma: a phase 1 trial]("https://www.nature.com/articles/s43018-023-00709-6) by Bagley *et. al*
We selected this paper because it demonstrates advanced single-cell analysis workflows, including dataset integration with metadata, batch processing across samples, cell type annotation (automatic or manual), and generating statistical plots to compare gene expression levels pre- and post-treatment.
These workflows are common in studies involving multiple treatments and patient cohorts but are more complex than standard single-cell analyses like PBMC3K.
This complexity provides an opportunity to stress test LLMs and identify prompts that perform well.
**Prompt:**
You are working with a dataset stored on Latch Data, where:
The attached dataset folder is structured into subfolders named GSMXXXX (e.g., GSM7770561), each representing a sample.
Within each sample folder:
* If .mtx files (e.g., files ending with matrix.mtx.gz, barcodes.tsv.gz, and features.tsv.gz) are present, the folder represents a valid single-cell dataset. If no .mtx files are found, disregard the folder.
* Additionally, you have a SraRunTable.csv file in the same location containing metadata for these samples. The relevant columns from the CSV are source\_name, time, tissue, and treatment.
Your task is to:
* Use LPath to access the data stored on Latch.
* Download and process only valid single-cell samples (those containing .mtx files).
* Use scanpy to read these samples and combine them into a single AnnData object.
* Integrate the metadata (source\_name, time, tissue, treatment) into the combined AnnData object.
* Save the combined AnnData object for downstream analyses.
Follow best practices in the Scanpy tutorial provided.
**Result:**
The LLM was able to use LPath API successfully to check for folders with the correct sample names, download them, and read them into an adata object using Scanpy. It was also able to inspect the SraRun.csv downloaded from Sequence Read Archive, and adding the appropriate metadata to the obs layer for each adata per sample. Finally, it merged all H5ADs into one big adata object, with sample ID being a column in the obs layer.
```python Output Code theme={null}
import os
import subprocess
import sys
from pathlib import Path
from typing import List, Dict, Optional
import pandas as pd
import numpy as np
from latch.ldata.path import LPath
# Install required packages
subprocess.check_call([sys.executable, "-m", "pip", "install", "scanpy"])
import scanpy as sc
# Check if combined data exists locally
if os.path.exists("combined_data_patients_all.h5ad"):
print("Found existing combined data file. Loading...")
combined = sc.read_h5ad("combined_data_patients_all.h5ad")
print(f"Loaded combined AnnData object: {combined.shape[0]} cells, {combined.shape[1]} genes")
else:
# Function to check if a directory contains files ending with required suffixes
def is_valid_sc_directory(dir_path: LPath) -> bool:
"""Check if directory contains files ending with required suffixes"""
files = list(dir_path.iterdir())
required_suffixes = ['matrix.mtx', 'barcodes.tsv', 'features.tsv']
return all(any(f.path.endswith(suffix) or f.path.endswith(f"{suffix}.gz") for f in files) for suffix in required_suffixes)
# Function to process a single sample
def process_sample(sample_dir: LPath, sample_id: str) -> Optional[sc.AnnData]:
"""Process a single sample directory and return AnnData object"""
try:
# Create a temporary directory for this sample
temp_dir = Path(f"/tmp/{sample_id}")
os.makedirs(temp_dir, exist_ok=True)
# Download and rename files
for file in sample_dir.iterdir():
if 'matrix.mtx' in file.path or 'barcodes.tsv' in file.path or 'features.tsv' in file.path:
# Download with original name
local_path = temp_dir / file.name()
file.download(local_path)
# Rename to standard 10x names
new_name = None
if 'matrix.mtx' in file.path:
new_name = 'matrix.mtx.gz'
elif 'barcodes.tsv' in file.path:
new_name = 'barcodes.tsv.gz'
elif 'features.tsv' in file.path:
new_name = 'features.tsv.gz'
if new_name and local_path.exists():
os.rename(local_path, temp_dir / new_name)
# Check if all required files exist
required_files = ['matrix.mtx.gz', 'barcodes.tsv.gz', 'features.tsv.gz']
if not all((temp_dir / f).exists() for f in required_files):
print(f"Missing required files in {sample_id}")
return None
# Read the sample using scanpy
adata = sc.read_10x_mtx(
temp_dir,
var_names='gene_symbols'
)
# Add sample ID to obs
adata.obs['sample'] = sample_id
return adata
except Exception as e:
print(f"Error processing {sample_id}: {str(e)}")
return None
# Read metadata
sra_table_path = LPath("latch://35741.account/PlotAI/SraRunTable.csv")
metadata_df = pd.read_csv(sra_table_path.download())
# Keep only relevant columns
metadata_subset = metadata_df[['Individual', 'Sample Name', 'source_name', 'time', 'tissue', 'treatment']]
# Process all GSM directories
gsm_dir = LPath("latch://35741.account/PlotAI/GSM")
adatas = []
for sample_dir in gsm_dir.iterdir():
sample_id = sample_dir.name()
print(f"Processing {sample_id}...")
adata = process_sample(sample_dir, sample_id)
if adata is not None:
# Add metadata
sample_metadata = metadata_subset[metadata_subset['Sample Name'] == sample_id].iloc[0]
for col in ['Individual', 'source_name', 'time', 'tissue', 'treatment']:
adata.obs[col] = sample_metadata[col]
adatas.append(adata)
# Combine all samples
if adatas:
print(f"Combining {len(adatas)} samples...")
combined = adatas[0].concatenate(adatas[1:], join='outer')
# Basic preprocessing
sc.pp.filter_cells(combined, min_genes=200)
sc.pp.filter_genes(combined, min_cells=3)
# Save the combined object
combined.write_h5ad("combined_data_patients_all.h5ad")
# Upload to Latch
output_path = LPath("latch://35741.account/PlotAI/combined_data_patients_all.h5ad")
output_path.upload_from("combined_data_patients_all.h5ad")
print(f"Combined AnnData object saved and uploaded: {combined.shape[0]} cells, {combined.shape[1]} genes")
else:
print("No valid samples found")
```
To save time when notebook re-runs in the future, we an also instruct the LLM to save the result into a new H5AD stored in local disk and uploaded to Latch Data.
**Prompt:**
Check if “combined\_data.h5ad” exists locally. If so, load object from disk and skip the rest of the steps.
**Prompt:** Create a new adata object with only brain tissue samples from patients 1, 6, and 7.
```python theme={null}
import scanpy as sc
import numpy as np
import pandas as pd
selected_patients = ["patient 1", "patient 6", "patient 7"]
# Create boolean mask for selected patients and brain tissue
patient_mask = combined.obs["Individual"].isin(selected_patients)
tissue_mask = combined.obs["tissue"] == "brain"
combined_mask = patient_mask & tissue_mask
small_combined = combined[combined_mask].copy()
print(f"Created subset with {small_combined.shape[0]} cells and {small_combined.shape[1]} genes")
print("\nSample distribution:")
print(small_combined.obs["Individual"].value_counts())
```
Next, let’s give it a list of prompts to perform the pre-processing steps for the small\_combined adata object.
Pro-tip: We **DO NOT** recommend writing a long prompt of all steps in sequence. The LLM seems to perform better when you give it one specific instruction at a time. Another common mistake is give generic and vague prompts (e.g. “Make some QC plots”).
**Prompt:** You have already created a "small\_combined" adata object. Use scanpy to calculate QC metrics.
```python Result theme={null}
import scanpy as sc
import numpy as np
import pandas as pd
from latch.ldata.path import LPath
from lplots.widgets.text import w_text_output
# Calculate QC metrics
sc.pp.calculate_qc_metrics(adata, percent_top=None, log1p=False, inplace=True)
# Calculate mitochondrial and ribosomal gene percentages
adata.var['mt'] = adata.var_names.str.startswith('MT-')
adata.var['ribo'] = adata.var_names.str.startswith(('RPS', 'RPL'))
sc.pp.calculate_qc_metrics(adata, qc_vars=['mt', 'ribo'], percent_top=None, log1p=False, inplace=True)
# Print summary statistics
summary_stats = pd.DataFrame({
'Total genes': np.median(adata.obs.n_genes_by_counts),
'Total counts': np.median(adata.obs.total_counts),
'MT %': np.median(adata.obs.pct_counts_mt),
'Ribo %': np.median(adata.obs.pct_counts_ribo)
}, index=['Median'])
w_text_output(content="### QC Metrics Summary\n" + summary_stats.to_markdown())
# Create QC violin plots with plotly
import plotly.graph_objects as go
from plotly.subplots import make_subplots
fig = make_subplots(rows=1, cols=3, subplot_titles=('Total Counts', 'Number of Genes', 'MT%'))
# Total counts violin plot
fig.add_trace(
go.Violin(y=adata.obs['total_counts'], box_visible=True, name='Total Counts',
points="outliers"), row=1, col=1)
# Number of genes violin plot
fig.add_trace(
go.Violin(y=adata.obs['n_genes_by_counts'], box_visible=True, name='Num Genes',
points="outliers"), row=1, col=2)
# MT% violin plot
fig.add_trace(
go.Violin(y=adata.obs['pct_counts_mt'], box_visible=True, name='MT%',
points="outliers"), row=1, col=3)
fig.update_layout(height=500, width=1200, showlegend=False)
fig
```
**Prompt:** Apply these additional quality filters: A series of quality filters were applied to the data to remove cell barcodes: too few total transcript counts (`<300`); possible debris with too few genes expressed (100); more than one cell with too many genes expressed (>5–10,000) and too many UMIs (>5–10,000); possible dead cell or a sign of cellular stress and apoptosis with too high proportion of mitochondrial gene expression over the total transcript counts (>10–20%)
```python Result theme={null}
# Import necessary libraries
import scanpy as sc
import numpy as np
import pandas as pd
import plotly.express as px
from lplots.widgets.text import w_text_output
# Apply QC filters
# Filter cells based on total counts
sc.pp.filter_cells(adata, min_counts=300)
# Filter cells based on number of genes
sc.pp.filter_cells(adata, min_genes=100)
# Filter cells based on max genes and UMIs
adata = adata[adata.obs.n_genes_by_counts < 10000]
adata = adata[adata.obs.total_counts < 10000]
# Filter cells based on mitochondrial content
adata = adata[adata.obs.pct_counts_mt < 20]
# Calculate and display filtering results
filter_stats = pd.DataFrame({
'Metric': [
'Cells remaining',
'Genes remaining',
'Median UMIs per cell',
'Median genes per cell',
'Median MT%'
],
'Value': [
adata.shape[0],
adata.shape[1],
np.median(adata.obs.total_counts),
np.median(adata.obs.n_genes_by_counts),
np.median(adata.obs.pct_counts_mt)
]
})
# Create visualization of filtering results
fig = px.scatter(
adata.obs,
x='total_counts',
y='n_genes_by_counts',
color='pct_counts_mt',
opacity=0.6,
labels={
'total_counts': 'Total UMIs',
'n_genes_by_counts': 'Number of Genes',
'pct_counts_mt': 'MT%'
},
title='Cell Quality Metrics After Filtering'
)
fig.update_layout(
width=800,
height=600,
template='plotly_white'
)
# Display results
w_text_output(content="### Filtering Results\n" + filter_stats.to_markdown(index=False))
fig
```
When provided with single-prompt instructions, it also performed the subsequent steps successfully, mimicking the standard steps in the [scanpy tutorial](https://scanpy.readthedocs.io/en/stable/tutorials/basics/clustering.html).
**Prompt:** Perform normalization
**Prompt:** Perform dimensionality reduction of data using PCA
**Prompt:** Compute the neighborhood graph of cells and visualize the UMAP according to the sample
**Prompt:** Create a select widget that allows users to select what to color the UMAP by.
**Prompt:** Perform Leiden clustering
Given the iterative nature of single-cell analyses, we want to provide widgets for users to refine certain parameters to generate different UMAPs.
Pro-tip: You can ask the LLM to generate input widgets to facilitate more interactive analyses.
**Prompt:** Add two widgets for users to fill in the number of PCs used and number of neighbors used
Pro-tip: You can also ask the LLM to install any library and use that library in its analysis.
**Prompt:** Implement Celltypist for automatic cell type annotation.
Here, it wrote the majority of the code, including installing CellTypist, selecting the correct reference model, and predicting the cell types. (It failed to realize that the output type of CellTypist is a dataframe, hence incorrectly passing the dataframe column to the obs layer. This requires programmer’s intervention to fix.)
We can also use the LLM to ask questions about gene markers of specific cell types.
Pro-tip: If you click on **Focus** and select **Text**, it will provide text responses to the question. If you choose **Focus** and select **Analysis**, it will write Python that queries an API to pull down hallmark marker genes from specific cell types. For the latter case, make sure you specify a well-maintained API or database that you trust to work well.
**Prompt:** What are the markers for B Cells?
**Result**:
We next asked it to make a widget, so users can select genes of interest and confirm the predicted cell type by looking at these marker genes.
**Prompt:** Make a select widget that allows users to color the UMAP by expression of genes.
**Result**:
We then chose MS4A1 as the gene of interest as it’s a canonical for the B-lymphocyte surface antigen B1. Indeed, the cluster with B cell as the predicted cell type lit up!
Similarly, users can select HLA-DRA expression, a gene encoding the alpha chain of HLA-DR, a major histocompatibility complex (MHC) class II molecule. This gene is typically expressed by antigen-presenting cells like macrophages and dendritic cells to present antigens to CD4+ T cells. As anticipated, HLA-DRA shows higher expression in the cluster predicted to contain macrophages, supporting the accuracy of our cell type annotation.
Next, we want focus on the T cell cluster and further label more granular T cell types.
**Prompt:** Create a t\_cell\_adata object that's a subset of the adata object, where majority voting is T cell
```python Result theme={null}
# Import required libraries
import scanpy as sc
import numpy as np
import pandas as pd
from lplots.widgets.text import w_text_output
# Create t cell mask based on majority voting
t_cell_mask = adata.obs['majority_voting'] == 'T cells'
# Create subset of adata with only T cells
t_cell_adata = adata[t_cell_mask].copy()
# Display summary statistics
t_cell_stats = pd.DataFrame({
'Metric': [
'Total T cells',
'Percent of all cells',
'Number of genes'
],
'Value': [
t_cell_adata.shape[0],
f"{(t_cell_adata.shape[0] / adata.shape[0] * 100):.1f}%",
t_cell_adata.shape[1]
]
})
w_text_output(
content=f"### T Cell Subset Summary\n"
f"{t_cell_stats.to_markdown(index=False)}"
)
```
As CellTypist does not perform well with T cell subtypes, we resort to manually annotating these cell types with marker genes.
**Prompt:**
Write a Python script using the Scanpy library to assign marker gene lists to the following cell types in a single-cell RNA-seq dataset:
* Tregs cells
* IFN-stimulated CD4 and CD8 T cells
* Effector/exhausted CD8 T cells
* Memory CD4 T cells
* Resident memory CD8 T cells
* NK cells
The script should:
* Take an AnnData object as input (e.g., t\_cell\_adata).
* Define marker genes for each cell type as a dictionary (you may provide generic examples).
* Use these marker genes to assign cell types to clusters in the dataset.
* Assume the clusters are precomputed and available in adata.obs\['leiden'].
* Use scanpy functions like tl.rank\_genes\_groups to refine marker assignments.
* Output a table or file summarizing the assigned cell types and their marker genes.
**Result:**
Next, we want to see gene express levels of various T cells markers.
Markers like TOX, PDCD1 (PD-1), LAG3, and CTLA4 are hallmarks of T cell exhaustion, a dysfunctional state where T cells lose their ability to effectively kill tumor cells. High expression of these markers on CAR T cells post-treatment may indicate that the CAR T cells are becoming exhausted, reducing their efficacy in targeting glioblastoma cells.
Pembrolizumab blocks **PD-1**, a key exhaustion marker, to reinvigorate exhausted T cells. Monitoring **PDCD1 (PD-1)** and other exhaustion markers post-treatment helps assess whether pembrolizumab is successfully reversing T cell exhaustion.
Let’s proceed with creating violin plots to see expression of these markers pre- and post-treatment across different patients.
**Prompt:** For the gene TOX, create a violin plot of pre- and post-treatment for patient 1
**Result**:
**Prompt: Create the same plot for each of the following genes: TOX, PDCD1, LAG3, CTLA4.**
**Result**:
**Prompt: Generate the same set of plots for all other patients in addition to Patient 1.**
**Result**:
The LLM generated violin plots comparing pre- and post-treatment expression levels of four exhausted T cell markers for all 3 patients. The p-values (`<0.05`) indicate a significant increase in the expression of these markers post-treatment. Further studies are likely needed to determine the extent to which these changes were driven by CAR T cells plus pembrolizumab.
# Postgres
Source: https://wiki.latch.bio/plots/integrations/postgres
# Postgres Integration for Plots
Connect PostgreSQL databases to Plots. Create graphical dashboards that allow scientists to manipulate, visualize and integrate data.
### 1/ Configure and Create a `PostgresConnection`
Create a dedicated plot transform cell that constructs configuration and connection objects.
```python theme={null}
from sqlalchemy import create_engine
from dataclasses import dataclass
from contextlib import contextmanager
import pandas as pd
import logging
logging.basicConfig(level=logging.INFO)
logger = logging.getLogger(__name__)
@dataclass
class PostgresConfig:
host: str
database: str
user: str
password: str
port: int = 5432
@classmethod
def build(cls) -> 'PostgresConfig':
"""Create config from environment variables"""
return cls(
host="localhost",
database="some_db",
user="postgres_user",
password="secret",
port=5432
)
@contextmanager
def postgres_connection(config: PostgresConfig):
engine = None
try:
connection_string = (
f"postgresql://{config.user}:{config.password}@"
f"{config.host}:{config.port}/{config.database}"
)
engine = create_engine(connection_string)
conn = engine.connect()
yield conn
except Exception as e:
logger.error(f"Error connecting to PostgreSQL: {str(e)}")
raise
finally:
if engine:
engine.dispose()
```
### 2/ Allow scientists to query data with graphical widgets
Once you have established a connection, you can allow scientists to query, manipulate and visualize their own tables of data from PostgreSQL using graphical query builders.
See an example below with a table of synthetic barcode counts. Scientists can retrieve counts and barcodes based on date ranges and sample IDs:
```python theme={null}
from lplots.widgets.text import w_text_input
from lplots.widgets.multiselect import w_multi_select
from datetime import datetime
start_date = w_text_input(
label="Start Date",
default="2023-01-01",
appearance={"help_text": "Enter start date in YYYY-MM-DD format"}
)
end_date = w_text_input(
label="End Date",
default="2023-01-31",
appearance={"help_text": "Enter end date in YYYY-MM-DD format"}
)
sample_ids = w_multi_select(
label="Sample IDs",
options=['SAMPLE_001_A1', 'SAMPLE_001_A2', 'SAMPLE_001_A3'],
appearance={"help_text": "Select one or more sample IDs"}
)
barcode_ids = w_multi_select(
label="Barcode IDs",
options=['BC000001', 'BC000002', 'BC000003'],
appearance={"help_text": "Select one or more barcode IDs"}
)
limit = w_text_input(
label="Query Limit",
default="1000",
appearance={"help_text": "Enter the maximum number of rows to return"}
)
# PostgreSQL uses different parameter style (%s instead of %(name)s)
base_query = """
SELECT
sample_id,
barcode_id,
count,
run_id,
experiment_date
FROM barcode_counts
WHERE experiment_date BETWEEN %s AND %s
"""
params = [start_date.value, end_date.value]
if sample_ids.value:
base_query += " AND sample_id = ANY(%s)"
params.append(sample_ids.value)
if barcode_ids.value:
base_query += " AND barcode_id = ANY(%s)"
params.append(barcode_ids.value)
base_query += """
ORDER BY experiment_date, sample_id
LIMIT %s
"""
params.append(int(limit.value))
with postgres_connection(PostgresConfig.build()) as conn:
df = pd.read_sql(base_query, conn, params=params)
df
```
# Snowflake Integration for Plots
Source: https://wiki.latch.bio/plots/integrations/snowflake
Connect Snowflake databases to Plots. Create graphical dashboards that allow scientists to manipulate, visualize and integrate data.
### 1/ Configure and Create a `SnowflakeConnection`
Create a dedicated plot transform cell that constructs configuration and
connection objects.
```python theme={null}
from snowflake.connector import connect, SnowflakeConnection
from snowflake.connector.pandas_tools import write_pandas
from dataclasses import dataclass
from contextlib import contextmanager
import logging
logging.basicConfig(level=logging.INFO)
logger = logging.getLogger(__name__)
@dataclass
class SnowflakeConfig:
account: str
user: str
password: str
warehouse: str
database: str
role: str = "ANALYST"
@classmethod
def build(cls) -> 'SnowflakeConfig':
"""Create config from environment variables"""
return cls(
account="account-id",
user="KENNYWORKMAN",
password="secret",
warehouse="COMPUTE_WH",
database="SOME_DB",
role="ACCOUNTADMIN"
)
@contextmanager
def snowflake_connection(config: SnowflakeConfig):
conn = None
try:
conn = connect(
account=config.account,
user=config.user,
password=config.password,
warehouse=config.warehouse,
database=config.database,
role=config.role
)
yield conn
except Exception as e:
logger.error(f"Error connecting to Snowflake: {str(e)}")
raise
finally:
if conn:
conn.close()
```
### 2/ Allow scientists to query data with graphical widgets
Once you have established a connection, you can allow scientists to query,
manipulate and visualize their own tables of data from Snowflake using
graphical query builders.
See an example below with a table of synthetic barcode counts. Scientists can
retrieve counts and barcodes based on
```python theme={null}
from lplots.widgets.text import w_text_input
from lplots.widgets.multiselect import w_multi_select
from datetime import datetime
start_date = w_text_input(
label="Start Date",
default="2023-01-01",
appearance={"help_text": "Enter start date in YYYY-MM-DD format"}
)
end_date = w_text_input(
label="End Date",
default="2023-01-31",
appearance={"help_text": "Enter end date in YYYY-MM-DD format"}
)
sample_ids = w_multi_select(
label="Sample IDs",
options=['SAMPLE_001_A1', 'SAMPLE_001_A2', 'SAMPLE_001_A3'],
appearance={"help_text": "Select one or more sample IDs"}
)
barcode_ids = w_multi_select(
label="Barcode IDs",
options=['BC000001', 'BC000002', 'BC000003'],
appearance={"help_text": "Select one or more barcode IDs"}
)
limit = w_text_input(
label="Query Limit",
default="1000",
appearance={"help_text": "Enter the maximum number of rows to return"}
)
base_query = """
SELECT
sample_id,
barcode_id,
count,
run_id,
experiment_date
FROM barcode_counts
WHERE experiment_date BETWEEN %(start_date)s AND %(end_date)s
"""
params = {
'start_date': start_date.value,
'end_date': end_date.value
}
if sample_ids.value:
base_query += " AND sample_id IN ('" + "','".join(sample_ids.value) + "')"
if barcode_ids.value:
base_query += " AND barcode_id IN ('" + "','".join(barcode_ids.value) + "')"
base_query += """
ORDER BY experiment_date, sample_id
LIMIT %(limit)s
"""
params['limit'] = int(limit.value)
with snowflake_connection(SnowflakeConfig.build()) as conn:
df = pd.read_sql(base_query, conn, params=params)
df
```
The above Python code translates to the UI below:
# Components of a Plot Notebook
Source: https://wiki.latch.bio/plots/layouts
An overview of all components in a Plot notebook
All supported cell types in a notebook
Key concepts around notebook compute resources, environments, and kernel sessions
All notebook statuses and what they mean
Available actions for running cells, restarting the kernel, and more
Differences between Edit and App mode
## Cell Types
There are 4 types of cells that can be added to a Plot Notebook, these are:
* **Plotting Cells**
Plot cells allow you to plot your tabular data using various configurable chart types.
* **Analysis or Python Cells**
Analysis cells allow you to analyze and process data using Python and UI widgets.
* **Table Display/Filtering Cells**
Table display/filtering cells allow you to display a selected tabular data source (can be from a transform cell, csv, Excel, or registry) and filter that data for use downstream.
* **Text Cells**
Text cells use markdown to display explanatory text or figures in a layout
To add a Cell to a layout hover between two cells, click the **+ Add** button, and select the cell type — or scroll to the bottom of a layout and select the type.
## Notebook Runtime
A notebook runtime is the compute environment that executes the code within a notebook. Technically, it consists of:
* **Kernel**: A language-specific process (e.g., Python, R) that receives, executes, and returns the output of code cells.
* **Compute Resources**: CPU, GPU, RAM, and storage allocated to support execution, data loading, and in-memory operations.
Each Plot notebook is backed by one dedicated computer with resources you can adjust.
* **Environment Context**: The software environment, including installed packages, environment variables, and file system structure available during execution.
By default, each Plot notebook uses packages defined in the `plots-faas` conda environment.
* **Session State**: Keeps track of defined variables, function definitions, loaded data, and execution history within the notebook session.
In cloud-native platforms like Latch Plots, the runtime is typically spun up in an isolated container or virtual machine. It persists for the duration of your session and is terminated when the notebook shuts down.
## Notebook Statuses
Each Plot Notebook is backed by a dedicated virtual machine. When you create or open a notebook, it transitions through several runtime states:
* **Creating Runtime**: A new virtual machine is being provisioned for the notebook.
* **Layout Connecting**: The virtual machine is starting up, and the notebook frontend establishes a WebSocket connection to the runtime.
* **Initializing**: Once connected, all notebook cells are automatically executed in order. If the notebook has multiple tabs, initialization will run all cells across all tabs.
Auto-running all cells is the default behaviour. You also have the option to disable auto-running by clicking **Edit** and turn off **Autorun enabled**.
* **Connected**: The notebook is connected and ready to be use.
* **Dormant**: The notebook is shutdown. The session state, which includes in-memory variables and functions, are cleared. However, all files and installed dependencies stored on disk are persisted and will be available the next time the notebook is launched.
By default, a notebook automatically shuts down after 1 hour of inactivity (i.e., when no user is actively viewing it).
## Notebook Actions
You can perform the following action to the virtual machine backing the notebook:
* **Restart**:
Terminates the current session and clears all in-memory variables and session state. A new WebSocket connection is established, and all notebook cells are automatically re-executed from top to bottom.
* **Shutdown**:
Terminates the current session and clears all in-memory variables and session state.
* **Reconnect**:
Reconnects to a recently shutdown session.
You can use the following controls to manage execution and widget state within the notebook:
* **Run All**:
Executes all cells across the entire notebook, including all tabs if using a tabbed layout.
* **Run All in Tab**:
Executes only the cells within the currently visible tab.
* **Cancel Autorun**:
When the notebook first connects and begins auto-running all cells, you can interrupt this process by clicking “Cancel autorun” if it's taking too long or if you want to run specific cells manually.
* **Clear All Widgets, Tables & Plots Data**:
Resets all widget states to their default values and re-runs the associated cells. If your code uses conditionals (e.g., skipping computation when widgets are None), clearing the widgets will also clear any dependent tables or plots that rely on user input.
## Edit vs. App Mode
On the left-hand side of the notebook, next to the "Run All" button, there is an icon that allows you to toggle betwee **Edit** mode and **App** mode.
| Edit Mode | App Mode |
| --------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------- |
| See and edit code | Cannot see code |
| Manually execute each cell | Cannot see individual cell border or manually run each cell |
| Access developer configurations (SSH, toggle to enable or disable notebook autorunning, ability to clear all widget states) | All develeoper configurations are hidden |
| Options to save notebook versions and create templates | Options hidden |
Overall, App Mode provides users with a simple, application-like experience. The underlying notebook interface is hidden, making it indistinguishable from a standalone web app.
# What are Latch Plots?
Source: https://wiki.latch.bio/plots/overview
Set up dashboards with interactive visualizations and data transformations for scientists to explore their data.
Latch Plots are reactive Python notebooks designed for building interactive, shareable applications tailored to scientists. Developers can use Plots to write code that powers custom user interfaces, dynamic visualizations, and domain-specific analysis tools—all within a reproducible notebook environment.
Key features include:
* **Python-based GUIs**: Create intuitive, customizable interfaces using native Python, without needing to write JavaScript or HTML.
* **Reactive execution**: Automatically re-run relevant cells when inputs change, enabling fast, interactive workflows.
* **Shareable as Apps**: Turn any notebook into a deployable App with one click, making it easy for scientists to explore data without writing code.
* **Specialized biological visualizations**: Built-in support for genome browsers, H5AD viewers, spatial image alignment, and more.
* **PlotsAI**: Use natural language to explore datasets, generate visualizations, and summarize results
## Get Started
}
href="/plots/developer/getting-started"
>
Learn how to develop your first Plot notebook and publish an App.
Create visualizations with variables & access dev mode.
Use different plot types, customize your plot, & filter your table!
Learn how to use Python to create data collection widgets.
View data and filter it for downstream use.
Write markdown descriptions
## Integrations
Biotech teams use plot dashboards to integrate the data avilable
on Latch with external databases and warehouses. Here we provide quickstart
documentation and boilerplate code to do this for popular systems:
# Error Bars
Source: https://wiki.latch.bio/plots/plotting/error-bars
Add error bars to your plot.
You are able to add error bars to bar, scatter, and line plots. To add error bars, go to the series options in the right plot config sidebar, and select the configuration from the dropdown. You can either select prebuilt functions **Standard Deviation** and **Standard Error of the Mean** that calculate the values for you or you can select a custom column in the source table.
# Faceting
Source: https://wiki.latch.bio/plots/plotting/faceting
Facet your plot based on a categorical column.
Faceting partitions the plot into a matrix of panels based on a selected categorical column. To facet first create specify a plot series, click the add facet button, and then select the column to facet by.
Faceting currently only supports a single series
# Filtering
Source: https://wiki.latch.bio/plots/plotting/filtering
Learn how to filter the values displayed in a plot.
To create filters on the data visualized in a plot click the **Show Filter Table** button below the data source select in the right sidebar. This will display a table below the plot where you can click the **Filter** button to add a filter on a column.
Any filters added will automatically update the data displayed in your plot.
# Plotting Overview
Source: https://wiki.latch.bio/plots/plotting/overview
Create interactive and customizable plots.
Plots can be created within a plotting layout. To create a plot:
You can plot from another dataframe in your layout, a CSV, TSV or Excel file in your Latch Data, or a Latch Registry Table
We support:
* Line
* Scatter
* Volcano
* Heatmap
* Bar
* Scatter Bar
* Box
* Violin
# Supported Plot Types
Source: https://wiki.latch.bio/plots/plotting/plot-types
Learn about the plot types supported in a plotting layout.
## Scatter
## Volcano
## Line
## Heatmap
## Bar
## Scatter Bar
## Violin
## Box
# Selecting Points
Source: https://wiki.latch.bio/plots/plotting/selecting-points
Learn how to make a selection of points and use that selection to filter the source table.
You're able to use the lasso or box select tool on a plot to make a selection of points in a plot. Once selected, any points in the drawn geometry will be listed in a table below.
# Appearance
Source: https://wiki.latch.bio/plots/plotting/styling
Learn what options are available for customizing the appearance of your plots.
# Coloring
You're able to customize the color palette used in a plot. You can select a premade palette, or create your own. Colors in a palette are used in a plot sequentially per series or color group.
## Specifying coloring groups
In the series settings, you're able to specify a column to color plot markers by. This usually works best when using categorical columns in the source table
In some plot types this will both color and group by the category.
# Axis
## Customizing ticks
You can customize X & Y how ticks are displayed on a plot axis. This includes the scale, main ticks, sub-ticks, and weight and size.
# Size
You are able to adjust the height and width of a plot. To adjust the height use the height slider at the bottom of the plot. To adjust width there is an option to enable a maximum width size for the plot.
# GraphPad Prism-Inspired Themes
For scientists who are familiar with GraphPad Prism, we provide an out-of-the-box Prism-inspired theme.
## How to apply the theme
On the configuration sidebar of a no-code plot, simply select **Theme** and click **GraphPad Inspired**.
## Customize your theme
If you want to further refine your plot, here are some tips to enhance the GraphPad-like appearance:
1. Adjust font weight
2. Tilt axis labels on the X or Y-axis to improve readability.
3. Modify bar spacing for individual or grouped bars.
4. Update the color palette to match your branding or study.
## For developers
If you're working directly with code, you can apply the GraphPad-Inspired Theme by passing `template="graphpad_inspired_theme"` to your Plotly figure. Here's an example:
```python theme={null}
import plotly.express as px
fig_scatter = px.scatter(df_2619, x='rqMean', y='rqSD', color='Target Name',
hover_data=['Sample Name', 'rq'],
labels={'rqMean': 'Mean Relative Quantity',
'rqSD': 'Standard Deviation of Relative Quantity'},
title='Scatter Plot of Mean Relative Quantity vs Standard Deviation')
fig_scatter.update_layout(
legend_title='Target Name',
xaxis_title='Mean Relative Quantity',
yaxis_title='Standard Deviation of Relative Quantity',
template='graphpad_inspired_theme', ### APPLY GRAPHPAD PRISM THEME
autosize=True
)
```
# Table Display/Filter
Source: https://wiki.latch.bio/plots/table-display-cell
Learn how to use a table display to view data and filter it for use downstream.
## Overview
Table Display cells allow you to view data from various sources, filter and sort that data, and use the resulting filtered/sorted table elsewhere in the layout.
If you want to use the filtered/sorted version from the table viewer you can either select it from the data source selector:
Or you can use the variable name it creates listed below the table viewer and reference that in a transform:
## Renaming
To rename a Table Viewer cell, simply double-click the title at the top of the cell and press enter when done.
# Use Cases
Source: https://wiki.latch.bio/plots/templates/overview
Latch Plots enable scientific teams to get faster and more reproducible results (e.g., standard curves, normalized fluorescence, cell gating) while freeing your bench team’s time from manual qPCR, plate readers, ELISA, and flow cytometry analyses.
Explore the various ways scientists have leveraged Plots for their use cases.
## Downstream of NGS Processing
Compare peaks that represent chromatin accessibility across various samples and treatment conditions
View MA plots, heatmaps, and volcano plots to identify transcriptionally distinct features between biological samples.
Leverage GPU-enabled visualization dashboard with NVIDIA RAPIDs for fast data pre-processing, clustering, manual and automatic cell type annotation.
Overlay single-cell gene expression and cell type annotation data over spatial maps generated from Visium HD
## Biochemical Assays
Calculate ∆∆Cqs with a button click, without spreadsheet formulas. Easily modify the aesthetics of generated Plots for publication.
Graph UV absorbance over time alongside intensity versus m/z to provide a full spectrum analysis of LC-MS data.
## Statistical Analyses
Latch Plots also provide out-of-the-box statistical methods that you typically see in GraphPad Prism.
Linear regressionIC50 dose curve fittingOutlier detectionOne-way and two-way ANOVAt-testCorrelation analysis
# The Ultimate Guide to Relative qPCR Analysis on Latch
Source: https://wiki.latch.bio/plots/templates/qpcr
The guide below walks through how you can perform qPCR analysis on Latch using Plot Templates.
Time to complete tutorial: \< 15 minutes
Latch Plots offers a **Verified qPCR template** designed to guide you through the entire process of relative qPCR analysis from start to finish. Below is an interactive demo of what it looks like:
***
**Key functionalities of the qPCR Template include:**
* Calculate ΔCq and ΔΔCq
* Calculate fold change and percent relative expression
* Remove outliers using Grubbs' Test or by removing points with standard deviations above a certain threshold
* Calculate aggregate statistics, such as mean and standard deviations (STDEV) or standard error of the mean (SEM).
Let's get started!
## Step 1: Set up a new qPCR Plot layout
First, navigate to the [Plots tab on Latch](https://console.latch.bio/plots).
Next, click the **Plot Layout** button and select the **qPCR Analyzer** template. Give your plot layout a new name, ideally matching your experiment's name. Creating a new plot layout for each experiment is highly recommended to prevent overwriting analyses and plots from previous experiments.
***
## Step 2: Specify Input Parameters
Below, we will guide you through inputting each parameter to ensure the analysis runs successfully.
You can optionally select the **Use Test Data** checkbox to see an pre-loaded example that uses test data.
### qPCR Machine Output
Here is where you can add your qPCR machine readout file. This file typically contains columns such as *Well*, *Cq*, *Target*.
There are two options for files that can be provided here: a CSV or an Excel file.
* **CSV file**: If you input a CSV file, please ensure that your file contains **Cq**, **Well**, **Target** as the column headers.
* **Excel file**: QuantStudio machines often output data in an .eds file format, which is typically converted to an Excel file by the end user. Latch Plots can also directly process these Excel files. The tool intelligently identifies the header row containing the Well, Cq, and Target columns, trims any metadata rows above this header, and saves the cleaned table for further analysis. An example Excel file that Plots can process is seen below. Similar to the CSV input option, please also ensure that your file contains three mandatory columns that contain **targets**, **well IDs**, and **Cq** values. By default, we skip the first 24 rows of metadata, which can be modified in the code.
### Well column
Select the column header from your original CSV or Excel that contains well IDs (e.g. A1, A2).
**Common mistake 1**: QuantStudio sometimes generates a CSV file with two columns: **Well Position** and **Well**. The **Well Position** column contains the actual well IDs, while the Well column contains numeric values without a letter prefix (e.g., 31, 32, etc.). Users often mistakenly select the Well column instead of the Well Position column, which results in a warning.
### (Optional) Add a Plate Map CSV
In a typical qPCR experiment, a control sample is used as a reference point for ΔΔCq calculations. This control serves as a baseline to compare the expression levels of target genes in other samples, enabling the determination of relative gene expression changes. Common examples include untreated cells, vehicle-treated cells, and wild-type strains.
**Important**: If your CSV/Excel file contains a column that specifies the **condition** for each replicate in every row, you can skip this step.
If your CSV/Excel file does not contain a condition column, you have two options:
1. Revise the CSV to include this column.
2. Use a template Excel plate map file that we provide to map out the experimental conditions. You can download the template CSV using [this link](https://latch-public.s3.us-west-2.amazonaws.com/plot-templates/qpcr/latch_qPCR_metadata.xlsx).
If you choose to proceed with option 2, check the box that says **Use template file to provide experimental metadata** and add your Excel plate map.
**Pro-tip**: Do you have additional metadata that you consider important and might need for plotting downstream (common examples include time points, dosages, biological replicate IDs, tissue types, etc.)? If so, it's advisable to include them in your Excel sheet. To organize this information effectively, you can create separate tabs within the Excel file, with each tab dedicated to a specific type of metadata. For instance, if you have two types of metadata, such as conditions and dosages, you would create two tabs for the plate maps in the Excel file: one for conditions and another for dosages.
Latch Plots automatically merges plate map Excel sheets with qPCR machine readouts using well IDs, producing a clean dataset ready for analysis.
### Cq column
Select the column header in your original CSV/ Excel that contains Cq or Ct values.
### Target column
Select the column header in your original CSV/Excel file that contains the target and housekeeping gene data. This is often labeled **Target** in QuantStudio readouts.
### Housekeeping gene(s)
Once you specify the **Target** column, the dropdown menu will update to display all gene values from that column. Then, select your housekeeping gene(s) from this list.
### Study Design
Your qPCR study design may include multiple condition variables. For instance, you might have multiple drugs (condition variable #1) and varying dosage levels per drug (condition variable #2). You may want to compare the relative expression of different dosages within a single group. Alternatively, you could have multiple tissue types with multiple drug treatments per tissue type. In this scenario, you'd want to compare the relative expression of various drug treatments against untreated samples within each tissue type.
The two parameters below, **group column** and **experimental condition column** help specify the hierarchy of these conditions to ensure the correct experimental condition is used for ΔΔCq calculations downstream.
#### Group column
The group column represents the top-level condition by which your data is subsetted. This could represent a variety of factors, such as:
* A specific drug treatment
* A type of tissue
* Any other treatment condition
By defining this column, you ensure that your data is categorized appropriately for further analysis. This is particularly useful when you have multiple conditions and need to apply a control within specific groups.
It is optional to include a Group column.
#### Experimental condition column
The experimental condition column is used to specify the control value for your experiment for calculating ΔΔCq. This is likely a null dose or another treatment that you run across targets.
For instance, if your experiment involves multiple tissues and different conditions for each tissue, you want to ensure that the control is applied within the correct tissue group.
##### Key Points to Remember:
* Group Column: The main categorization of your data (e.g., drug, tissue).
* Experimental Condition Column: Specifies the control value within the grouped data.
#### Example
Consider an experiment with multiple tissues (e.g., liver, kidney) and various treatments (e.g., drug A, drug B) for each tissue. You want to compare the effects of these treatments within each tissue. By setting up the **group column** as the **tissue type** and the **experimental condition column** as the **specific treatment**, you ensure that the control values are accurately applied within each tissue group.
If you only have one condition, the experimental condition column can be used to define your control directly, simplifying the setup. Give the **group column** the same value as you provide the **experimental condition column**.
#### Control Condition
Once you've specified the **experimental condition column**, the dropdown menu here will display all available options for conditions across all wells and samples. Choose the condition that serves as the baseline control for ΔΔCq calculation.
### (Optional) Add additional columns to include
By default, the cleaned dataset only contains a minimal number of columns (Target, Cq, Well, Condition). If you have additional metadata you'd like to plot downstream and carry throughout the analysis, you can add them here.
### (Optional) Save your results
If you want to save the processed results as a CSV, you can simply input the experiment name and select an output directory in the **Output Results** section. Make sure to check the box once you are happy with your output directory path.
**Congratulations! You've completed all necessary inputs. Your Plot Layout will now run automatically, and all plots and results will appear below.** In the next steps, we will walk through the description for each plot and how you can customize them.
***
## Step 3: Inspect Plots and Results Tables
### 3.1. Cq by Well
The Cq value indicates the cycle number at which a qPCR reaction's fluorescent signal exceeds a predefined threshold, demonstrating the presence of detectable target DNA.
Lower Cq values suggest higher concentrations of target nucleic acid, as fewer cycles are needed for detection. Conversely, higher Cq values indicate lower concentrations.
The scatter plot below displays raw Cq values for target and housekeeping genes. The plot serves as a quick check to see if the Cq values for the target and housekeeping genes are as expected.
### 3.2. 𝚫Cq calculation
#### Method
This block displays the results of 𝚫Cq calculations.
The `𝚫Cq` value for each target gene can be defined as:
$$
\Delta {Ct}_{target} = {Cq}_{{target}} - {Cq}_{{housekeeping}}
$$
The `Cq` value of the housekeeping gene is subtracted from the `Cq` value of the target genes.
* If your target and housekeeping gene for every replicate lies in the same well, we subtract the housekeeping gene's Cq from the target gene's Cq for that well.
* If your target and housekeeping gene for replicates of the same condition lies in different wells, we first take the average of the technical replicates for every biological sample. We then subtract the average Cq of the housekeeping gene's biological sample from the average Cq of the target gene's biological sample.
#### Results
* **𝚫Cq result tables for each target gene**: You will see a new table has been created for every *target* or *non-housekeeping gene*. (e.g. 𝚫Cq\_TargetGeneX, 𝚫Cq\_TargetGeneY, etc.)
* **Merged 𝚫Cq table with all target genes**: You can view a merged table with all non-housekeeping gene targets by checking out the **delta\_ct\_df** tab.
### 3.3. 𝚫𝚫Cq calculation
#### Method
Consider a qPCR experiment with multiple tissues (such as liver and kidney) and various treatments (such as Drug A and Drug B) for each tissue, where you aim to compare the effects of these treatments within each tissue.
In this scenario, the workflow initially segregates the samples into distinct groups—for example, a Liver group and a Kidney group. To calculate the ΔΔCq, you first determine the average ΔCq for the control samples in each group. Then, you subtract this average ΔCq from the ΔCq of all other samples to assess the relative expression levels.
(If your experiment is less complex, lacking multiple high-level groups as described above, the workflow treats your setup as a single large group.)
$$
\Delta\Delta {Ct} = \Delta {Ct} - {Mean Control} \Delta {Ct}
$$
#### Result Tables
* **𝚫𝚫Cq result tables for each target gene**: You will see a new table has been created for every *target* or *non-housekeeping gene*. (e.g. 𝚫𝚫Cq\_TargetGeneX, 𝚫𝚫Cq\_TargetGeneY, etc.)
The columns in this table include:
* Well (from Step 1)
* Condition (from Step 1)
* Target (from Step 1)
* Cq (from Step 1)
* All other metadata columns (specified in the *Add additional columns to include* field from Step 1)
* 𝚫Cq: The ΔCq value is the difference between the threshold cycle (Ct) values of the target gene and the reference (housekeeping) gene in the same sample.
* Relative expression: the amount of target gene expression normalized to a reference gene
$$
\text{Relative Expression} = 2^{-\Delta Ct}
$$
* Mean Control 𝚫Cq: the average ΔCq value of the control samples. It serves as the baseline for comparing other experimental samples.
$$
\text{Mean Control} \Delta Ct = \frac{\sum \Delta Ct_{\text{control samples}}}{n_{\text{control samples}}}
$$
* 𝚫𝚫Cq: the difference between the ΔCq of the experimental sample and the Mean Control ΔCq.
$$
\Delta\Delta Ct = \Delta Ct_{\text{sample}} - \text{Mean Control} \Delta Ct
$$
* Fold Change: indicates the relative change in gene expression in the experimental sample compared to the control sample. It is calculated using the ΔΔCq value.
$$
\text{Fold Change} = 2^{-\Delta\Delta Ct}
$$
* Percent Expression: represents the expression level of the target gene in the experimental sample as a percentage of its expression in the control sample.
$$
\text{Percent Expression} = \left(2^{-\Delta\Delta Ct} \times 100\%\right)
$$
* Percent Repression: indicates the decrease in gene expression in the experimental sample compared to the control sample.
$$
\text{Percent Repression} = \left(1 - 2^{-\Delta\Delta Ct}\right) \times 100\%
$$
* **Merged 𝚫𝚫Cq table with all target genes**: You can view a merged table with all non-housekeeping gene targets by checking out the **delta\_ct\_df** tab.
### 3.4. (Optional) Outlier Removal
Here, you can optionally perform outlier removals using Grubbs' or with a standard deviation cutoff.
#### Input Parameters
* **Input data**: Specify the dataset you would like to remove outliers for. The dropdown of options likely includes all the tables generated from the previous steps. As a refresher, these tables are 𝚫𝚫Cq for each target gene, 𝚫Cq for each target gene, delta\_ct\_df table which contains 𝚫Cq for *all* target genes, and delta\_ct\_ct\_df table which contains 𝚫𝚫Cq for *all* target genes.
* **Measurement (e.g. Relative Expression, 𝚫𝚫Cq)**: Specify the column from which outliers will be removed. This is the column that represents the metric of interest, such as Relative Expression or 𝚫𝚫Cq.
* **Group by (Optional)**: If you do not enter anything here, outliers will be removed across the entire column selected above. However, if you prefer to remove outliers within specific subsets of your data, enter the grouping criterion here. For example, if you group the data by **condition**, outliers will be identified and removed within replicates associated with each condition.
**Pro-tip:** You can group your data by **multiple conditions** for more precise analysis. For instance, if your input table includes columns for *compound name* and *dosage level*, you can add both to the **Group by** field. This will automatically group all rows with the same *compound name* and *dosage level*. The software will then remove outliers based on your selection in the **Measurement** field.
* **Select outlier removal method**: There are two statistical methods provided for removing outliers: Grubbs and standard deviations cutoff.
#### Result Tables
* **delta\_delta\_ct\_df\_outliers**: Contains outliers that were removed.
* **delta\_delta\_ct\_df\_outliers**: The clean dataset where outliers have been removed.
* **plot\_outliers**: The table that has been organized in a way that facilitates easy plotting of outliers downstream.
#### Plots
In the plot below, the outliers will be plotted in green, while retained data points will be shown in orange. If no outliers are identified, all points will be orange.
This plot is plotting the plot\_outliers table generated above. This table has a column called is\_outlier, which has a True/False value for each row, denoting if that row was identified as an outlier.
Congratulations, you have finished your tutorial on how to perform relative qPCR quantification! 🎉
# Markdown Cell
Source: https://wiki.latch.bio/plots/text-cell
Add descriptive text to your layout using Markdown.
You can insert text cells into your Plot notebook. Markdown syntax is supported for formatting.
### Adding Spoilers
Create a collapsible component for toggling content
```python theme={null}
from lplots.widgets.text import w_text_output
w_text_output(content=f"""
### Section Title
Spoiler Title
Spoiler body text...
""")
```
# Description Text
Source: https://wiki.latch.bio/plots/transformations/description-text
Write descriptions using markdown within a Python analysis cell.
Within your transform code, you are able to render markdown text in the same flow as widgets using the `w_text_output` function.
````python theme={null}
from lplots.widgets.text import w_text_output
w_text_output(content=f"""
### Groups
𝚫𝚫Ct will be calculated in the following groups:
{group_bullets} \n
### Controls
We start by getting the average 𝚫Ct value of the control condition in every group. You can navigate to the ```control_table``` to see all the replicates that will be used as controls.
""")
````
### Text Output Parameters
`content`: *string* markdown text to display
`appearance`: *dict* containing widget appearance attributes:
> `message_box`: *string* specifying this wraps the code in a sematic container, allowed flavors are: "success" | "primary" | "info" | "warning" | "danger" | "neutral"
# Layout
Source: https://wiki.latch.bio/plots/transformations/layout
Layout widgets allow you to control the arrangement of other widgets in your notebook interface.
Layout widgets provide flexible ways to arrange other widgets in your notebook interface. They help you create complex, responsive layouts by combining multiple widgets together.
## Supported Layout Widget Types
Below is a comprehensive list of supported layout widget types.
The Row layout widget arranges widgets horizontally in a single row.
```python theme={null}
from lplots.widgets.row import w_row
from lplots.widgets.select import w_select
import plotly.express as px
# Get the iris dataset
df = px.data.iris()
# Get numeric columns for axis selection
numeric_cols = df.select_dtypes(include=['float64', 'int64']).columns.tolist()
# Create a column of select widgets with defaults set to first two columns
x_axis = w_select(
label="X-axis",
options=numeric_cols,
default=numeric_cols[0]
)
y_axis = w_select(
label="Y-axis",
options=numeric_cols,
default=numeric_cols[1]
)
w_row(items=[x_axis, y_axis])
```
### Widget Parameters
`key`: *string* optional unique identifier for the widget
`items`: *list\[BaseWidget]* list of widgets to arrange horizontally
The Column layout widget arranges widgets vertically in a single column.
```python theme={null}
from lplots.widgets.column import w_column
from lplots.widgets.select import w_select
import plotly.express as px
# Get the iris dataset
df = px.data.iris()
# Get numeric columns for axis selection
numeric_cols = df.select_dtypes(include=['float64', 'int64']).columns.tolist()
# Create a column of select widgets with defaults set to first two columns
x_axis = w_select(
label="X-axis",
options=numeric_cols,
default=numeric_cols[0]
)
y_axis = w_select(
label="Y-axis",
options=numeric_cols,
default=numeric_cols[1]
)
w_column(items=[x_axis, y_axis])
```
### Widget Parameters
`key`: *string* optional unique identifier for the widget
`items`: *list\[BaseWidget]* list of widgets to arrange vertically
The Grid layout widget allows you to create a grid-based layout where widgets can span multiple rows and columns.
```python theme={null}
from lplots.widgets.grid import w_grid
from lplots.widgets.plot import w_plot
import plotly.express as px
# Create some plots
df = px.data.iris()
fig1 = px.scatter(df, x="sepal_width", y="sepal_length", color="species")
fig2 = px.box(df, x="species", y="petal_length", color="species")
fig3 = px.histogram(df, x="petal_width", color="species")
plot1 = w_plot(source=fig1)
plot2 = w_plot(source=fig2)
plot3 = w_plot(source=fig3)
# Create a grid with 3 columns
with w_grid(columns=3) as g:
# Add plots to the grid with different spans
g.add(item=plot1, col_span=2) # Spans 2 columns
g.add(item=plot2, col_span=1) # Spans 1 column
g.add(item=plot3, col_span=3) # Spans all columns
```
### Widget Parameters
`key`: *string* optional unique identifier for the widget
`columns`: *int* number of columns in the grid
`rows`: *int* *optional* number of rows in the grid. If not specified, rows will be created as needed.
### Grid Item Parameters
When adding items to a grid using the `add()` method:
`item`: *BaseWidget* the widget to add to the grid
`col_span`: *int* number of columns the item should span (default: 1)
`row_span`: *int* number of rows the item should span (default: 1)
## Layout Widget Nesting
Layout widgets can be nested to create complex arrangements. For example, you can place a row of widgets inside a grid cell, or create a column of rows.
```python theme={null}
from lplots.widgets.grid import w_grid
from lplots.widgets.column import w_column
from lplots.widgets.select import w_select
from lplots.widgets.plot import w_plot
import plotly.express as px
# Get the iris dataset
df = px.data.iris()
# Get numeric columns for axis selection
numeric_cols = df.select_dtypes(include=['float64', 'int64']).columns.tolist()
# Create a column of select widgets with defaults set to first two columns
x_axis = w_select(
label="X-axis",
options=numeric_cols,
default=numeric_cols[0]
)
y_axis = w_select(
label="Y-axis",
options=numeric_cols,
default=numeric_cols[1]
)
plot_color = w_select(
label="Color",
options=["blue", "red", "green"],
default="blue"
)
# Create column layout for widgets
column = w_column(items=[x_axis, y_axis, plot_color])
# Create scatter plot
fig1 = px.scatter(
df,
x=x_axis.value,
y=y_axis.value,
template="simple_white"
)
# Update marker color
fig1.update_traces(marker=dict(color=plot_color.value))
# Render the plot
plot1 = w_plot(source=fig1)
# Add the column and plot to the grid
with w_grid(columns=12) as grid:
grid.add(item=column, col_span=3)
grid.add(item=plot1, col_span=9)
```
## Layout Widget Reactivity
Layout widgets are reactive to changes in their child widgets. When a child widget is updated, the layout will automatically adjust to accommodate the changes while maintaining the specified arrangement.
# Messages
Source: https://wiki.latch.bio/plots/transformations/messages
Learn how to display real-time messages as the cell runs.
This guide explains how to display progress messages in real-time when running long computations in a notebook. When a notebook is in non-developer mode, displaying messages helps keep end users informed about ongoing processes.
## Displaying Real-Time Messages
To provide real-time feedback to users, use the `w_text_output widget` in combination with the `submit_widget_state()` function. This approach ensures that messages appear dynamically as the process runs.
### Example
```python theme={null}
from lplots.widgets.text import w_text_output
from lplots import submit_widget_state
import time
def run_long_process():
# Display initial message
w_text_output(content="Starting long-running process...", appearance={"message_box": "info"})
submit_widget_state()
# Simulate first long task
time.sleep(2)
w_text_output(content="Step 1 complete: Data preprocessing finished...", appearance={"message_box": "warning"})
submit_widget_state()
# Simulate second long task
time.sleep(2)
w_text_output(content="Step 2 complete: Model training finished...", appearance={"message_box": "warning"})
submit_widget_state()
# Simulate final task
time.sleep(2)
w_text_output(content="✅ All processing complete!", appearance={"message_box": "success"})
submit_widget_state()
# Run the example
run_long_process()
```
What it looks like:
# Viewer Widgets
Source: https://wiki.latch.bio/plots/transformations/output-widgets
Use viewer widgets to display plots, tables, and genomic data in your notebook interface.
In Edit Mode, outputs like dataframes and figures are rendered automatically. In App Mode, no outputs are shown unless explicitly defined. Output widgets allow you to specify which elements should be visible, providing fine-grained control over the app interface.
## Supported Output Widget Types
Below is a comprehensive list of supported output widget types.
The Plot output widget allows you to display matplotlib Figures, SubFigures, Axes, or Plotly figures in your notebook interface.
```python theme={null}
import matplotlib.pyplot as plt
from lplots.widgets.plot import w_plot
# Create a matplotlib figure
fig, ax = plt.subplots()
ax.plot([1, 2, 3], [1, 2, 3])
ax.set_title("My Plot")
# Display the plot in the notebook
plot = w_plot(
label="Example Plot", # optional label displayed above the plot
source=fig
)
```
### Widget Parameters
`label`: *string* optional label displayed above the plot
`source`: *Figure | SubFigure | Axes | BaseFigure* the plot object to display. Can be:
* Matplotlib Figure
* Matplotlib SubFigure
* Matplotlib Axes
* Plotly Figure (BaseFigure)
`key`: *string* optional unique identifier for the widget
### Usage Notes
* The plot widget automatically detects the plot title from the source object
* The widget creates an interactive display of your plot that users can interact with
* In the notebook outline, the plot title from the source object will be used if no label is provided
### Examples
**Matplotlib Axes Example:**
```python theme={null}
import matplotlib.pyplot as plt
from lplots.widgets.plot import w_plot
# Create plot with axes
fig, ax = plt.subplots()
ax.scatter([1,2,3], [1,2,3])
ax.set_title("Scatter Plot")
# Display just the axes
w_plot(source=ax)
```
**Plotly Figure Example:**
```python theme={null}
import plotly.express as px
from lplots.widgets.plot import w_plot
# Create a plotly figure
fig = px.scatter(x=[1,2,3], y=[1,2,3])
fig.update_layout(title="Plotly Scatter")
# Display the plotly figure
w_plot(label="Interactive Plot", source=fig)
```
The Table output widget allows you to display tabular data in an interactive table format.
```python theme={null}
import pandas as pd
from lplots.widgets.table import w_table
# Create sample dataframe
df = pd.DataFrame({
'A': [1, 2, 3],
'B': ['a', 'b', 'c']
})
# Display the table
table = w_table(
label="Sample Data",
source=df
)
```
### Widget Parameters
`label`: *string* optional label displayed above the table
`source`: *DataFrame* the pandas DataFrame to display
`key`: *string* optional unique identifier for the widget
The IGV output widget allows you to visualize and interact with your genomic data.
```python theme={null}
from lplots.widgets.igv import w_igv, IGVOptions
latch_path = f"latch://.account/Covid/covid.bam"
index_path = f"latch://.account/Covid/covid.bam.bai"
options: IGVOptions = {
"genome": "hg38",
"tracks": [
{
"name": "test",
"type": "alignment",
"url": latch_path,
"indexURL": index_path,
"minHeight": 100,
"maxHeight": 200
}
]
}
w_igv(options=options)
```
### Widget Parameters
`options`: *dict* required dictionary of options for configuring the IGV browser. See [Browser Creation](https://igv.org/doc/igvjs/#Browser-Creation/#browser-configuration-options)
for a list of available options. See [Tracks](https://igv.org/doc/igvjs/#tracks/Tracks/) for configuration options for each track.
### Usage Notes
* The IGV widget accepts both Latch paths and generic URLs.
* If a Latch path is provided without an index, the widget will automatically generate and pull an index for the file.
The Molstar output widget allows you to visualize and interact with molecular structures using the Molstar 3D viewer. It uses [MolViewSpec (MVS)](https://molstar.org/mol-view-spec/), a toolkit for standardized description of reproducible molecular visualizations. MolViewSpec uses a tree-based approach to compose complex 3D molecular scenes from simple building blocks.
### Quick Start
```python theme={null}
# import the Molstar widget
from lplots.widgets.molstar import w_molstar, MolstarOptions
# import the MolViewSpec builder
# This is a tree-based API for defining molecular visualizations
from molviewspec.builder import Root
# Configure Molstar options
options: MolstarOptions = {
"layout": {
"layout_shown_by_default": {
"logs": False,
"sequence_viewer": True,
"right_controls": True,
"left_controls": True
}
}
}
# Create a molstarviewspec builder and define the structure view
builder = Root()
# You can also use a latch:// path to load a structure from Latch Data
builder.download(url="https://www.ebi.ac.uk/pdbe/entry-files/1cbs.bcif") \
.parse(format="bcif") \
.structure(type="model") \
.component(selector="polymer") \
.representation(type="cartoon") \
.color(color="lightblue")
# Display the Molstar viewer
molstar = w_molstar(
label="Protein Structure",
options=options,
molstarviewspec_builder=builder
)
```
### Widget Parameters
`label`: *string* optional label displayed above the viewer
`options`: *MolstarOptions* required dictionary for configuring the Molstar viewer layout. Contains:
* `layout`: Layout configuration options
* `layout_shown_by_default`: Controls visibility of UI elements
* `logs`: *bool* - Show/hide logs panel by default
* `sequence_viewer`: *bool* - Show/hide sequence viewer by default
* `right_controls`: *bool* - Show/hide right control panel by default
* `left_controls`: *bool* - Show/hide left control panel by default
`molstarviewspec_builder`: *Root | None* optional MolViewSpec builder for defining the molecular structure view
`key`: *string* optional unique identifier for the widget
### Widget Value
The Molstar widget returns selection data when users interact with the structure:
```python theme={null}
# Access the current selection
selection = molstar.value
if selection['selection'] is not None:
# Access selected segments
for segment in selection['selection']['segments']:
chain_id = segment['chain_id']
sequence = segment['sequence']
# Access individual residues
for residue in segment['residues']:
print(f"Chain: {residue['chain_id']}, "
f"Residue: {residue['residue_name']}, "
f"Number: {residue['residue_number']}")
```
### Selection Data Structure
When users select residues in the viewer, the widget returns:
* `selection`: *SequenceSelection | None* - Contains:
* `segments`: List of selected sequence segments
* `full_sequence`: Complete sequence string
* `structure_label`: Optional label for the structure
* Each segment contains:
* `chain_id`: Chain identifier
* `residues`: List of selected residues with detailed information
* `sequence`: Sequence string for the segment
* `start_residue` and `end_residue`: Segment boundaries
### MolViewSpec Builder
The MolViewSpec builder provides a powerful tree-based API for defining molecular visualizations. The builder supports:
* **Download & Parse**: Load structures from URLs in various formats (PDB, mmCIF, bcif)
* **Structure**: Create structures with support for assemblies, crystal symmetry, and multi-model structures
* **Component**: Select substructures by chain, residue range, or custom selectors
* **Representation**: Define visualization modes (cartoon, ball-and-stick, surface, etc.)
* **Color**: Apply custom colors and opacity to selections
* **Label & Tooltip**: Add text labels and interactive tooltips
* **Camera & Focus**: Control camera position and orientation
* **Volumetric Data**: Render electron density maps
* **Primitives**: Draw custom shapes (ellipses, boxes, arrows, meshes)
* **Annotations**: Create data-driven components with external annotation files
For complete documentation, see the [MolViewSpec documentation](https://molstar.org/mol-view-spec-docs/).
### Usage Notes
* The Molstar widget is fully interactive, allowing users to rotate, zoom, and select parts of the structure
* Use the `molstarviewspec_builder` parameter to programmatically define the initial view and styling
* The `value` property provides reactive access to the current selection
* MolViewSpec supports both remote URLs and Latch paths for loading structure files
* The builder uses a chainable API for building complex visualizations incrementally
## Output Widget Reactivity
Output widgets are reactive to changes in their source data. When the source plot or data is updated, the widget display will automatically update to reflect the changes.
**Example:**
```python theme={null}
import matplotlib.pyplot as plt
from lplots.widgets.plot import w_plot
# Create initial plot
fig, ax = plt.subplots()
line, = ax.plot([1, 2, 3], [1, 2, 3])
ax.set_title("Dynamic Plot")
# Display the plot
plot = w_plot(label="Updating Plot", source=fig)
# Update the plot data
line.set_ydata([2, 1, 3])
fig.canvas.draw() # Plot will automatically update in the widget
```
# Overview
Source: https://wiki.latch.bio/plots/transformations/overview
The Analysis cell functions similarly to a Python cell in a Jupyter Notebook, allowing users to input, modify, and execute Python code interactively.
One key difference from the native Jupyter cell is that you can import the Latch Plots library and write single lines of Python code to define user-friendly and no-code widgets that get exposed to scientists.
# Platform Widgets
Source: https://wiki.latch.bio/plots/transformations/platform-widgets
Platform widgets enable you to integrate and interact with other parts of the Latch platform directly within your plots and analysis workflows. These widgets provide seamless access to registry data, workflows, and file systems.
Platform widgets are specialized components that allow you to pull in and interact with other parts of the Latch platform directly within your plots and analysis workflows. These widgets serve as bridges between your visualizations and the broader platform ecosystem, enabling dynamic data integration and interactive workflows.
## Platform Integration Widgets
Below is a comprehensive list of platform widgets that enable integration with different parts of the Latch platform.
The Registry Table output widget allows you to display and interact with registry tables in your notebook interface.
```python theme={null}
from lplots.widgets.registry import w_registry_table_picker, w_registry_table
registry_table_picker = w_registry_table_picker(
label="Select table"
)
if (registry_table_picker.value is not None):
table_id = registry_table_picker.value
# Display a registry table
table = w_registry_table(
label="Sample Registry Table",
table_id=table_id
)
```
You can also use the `w_registry_table_picker` widget to select a table from the registry, or supply a table id directly.
### Widget Parameters
`label`: *string* required label displayed above the table
`table_id`: *string* required identifier for the registry table to display
`readonly`: *bool* optional, defaults to False. When True, the table is read-only
`default`: *string | None* optional default table id
`appearance`: *FormInputAppearance | None* optional appearance configuration
`key`: *string* optional unique identifier for the widget
### Value
The widget value returns a `RegistryTableValue` object with the following structure:
```python theme={null}
class RegistryTableValue(TypedDict):
table: Table
selected_rows: list[Record]
```
**Attributes:**
* `table`: *Table* - The registry table object containing the data and metadata.
* `selected_rows`: *list\[Record]* - A list of selected row records from the table. Returns an empty list if no rows are selected.
The `Table` object provides access to the table's data, schema, and metadata, while `Record` objects represent individual rows with their field values and metadata. Learn more about the [Table API](/registry/sdk/table-objects) and [Record API](/registry/sdk/record-objects).
### Usage Notes
* The registry table widget provides an interactive interface to view and interact with registry data
* The widget returns a `RegistryTableValue` containing the table object
* The table object can be accessed via the `value` property
The Workflow output widget allows you to launch and execute workflows directly from your notebook interface.
```python theme={null}
from lplots.widgets.workflow import w_workflow
# Launch a workflow with parameters
workflow = w_workflow(
label="Run Analysis",
wf_name="my_analysis_workflow",
params={
"input_file": "latch://workspace/data/sample.fastq",
"output_dir": "latch://workspace/results/"
},
version="v1.0"
)
execution = w.value
if execution is not None:
res = await execution.wait()
```
### Widget Parameters
`label`: *string* required label for the workflow button
`wf_name`: *string* required name of the workflow to execute
`params`: *dict* required dictionary of parameters to pass to the workflow.
`version`: *string | None* optional version of the workflow to use, defaults to the latest version
`readonly`: *bool* optional, defaults to False. When True, the workflow button is disabled
`key`: *string* optional unique identifier for the widget
### Class `CompletedExecution`
The CompletedExecution dataclass represents the final state of an execution, whether it succeeded, failed, or was aborted.
Attributes
id (str): A unique identifier for the execution.
output (dict\[str, Any]): A dictionary containing the processed output of the execution. This will be populated if the execution succeeded.
ingress\_data (list\[LPath]): A list of LPath objects, representing data that was written to LData during the execution.
status (ExecutionStatus): The final status of the execution
### Class `Execution`
The Execution class represents an running or completed execution. It provides methods to poll the status of an execution and wait for its completion.
Attributes
id (str): A unique identifier for the execution.
python\_outputs (dict\[str, type]): A dictionary mapping output names to their expected Python types. This is used when processing the execution's output.
status (ExecutionStatus): The current status of the execution. Defaults to "UNDEFINED".
outputs\_url (Union\[str, None]): The URL where the execution's outputs can be found, if available. Defaults to None.
flytedb\_id (Union\[str, None]): The FlyteDB ID associated with the execution, if available. Defaults to None. This attribute is updated during polling.
Methods
poll(self) -> Generator\[None, Any, None]
This is a generator method that continuously polls the status of the execution.
wait(self) -> Union\[CompletedExecution, None]
Asynchronous method that waits for the execution to complete and returns the execution outputs
If the execution status is "FAILED" or "ABORTED", it retrieves the ingress\_data and returns a CompletedExecution object with an empty output dictionary.
### Usage Notes
* The workflow widget creates a button that, when clicked, launches the specified workflow
* The widget's `value()` method returns either an `Execution` object containing information about the launched workflow or `None` if no executions have been launched.
* To retrieve the outputs of the execution, call the `Execution` object's asynchronous `wait` method which returns a `CompletedExecution` object.
The LData Browser widget enables you to pull in and interact with files and directories from your Latch workspace directly within your plots. This widget creates a connection to the platform's file system, allowing users to browse and upload files.
```python theme={null}
from lplots.widgets.ldata import w_ldata_browser
# Pull in data from your workspace for analysis
browser = w_ldata_browser(
label="Browse Data Directory",
dir="latch:///data/"
)
ldata_path = browser.value
```
### Widget Parameters
`label`: *string* required label displayed above the browser
`dir`: *string | LPath* required path to the directory to browse. Can be a string or LPath object "latch://\.account/\" will only work for the corresponding workspace\_id, but "latch:///\" will work for any workspace that has that path.
`readonly`: *bool* optional, defaults to False. When True, the browser is read-only
`appearance`: *FormInputAppearance | None* optional appearance configuration
`key`: *string* optional unique identifier for the widget
### Value
The widget value returns an `LPath` object representing the selected directory that can be integrated with your analysis. Learn more about the [LPath API](/workflows/sdk/python/working-with-files).
### Usage Notes
* The Latch Data Browser widget provides an interactive interface to browse directory structures and pull in files from the platform
* The widget automatically validates that the provided path is a valid directory
## Platform Widget Reactivity
Output widgets are reactive to changes in their source data. When the source plot or data is updated, the widget display will automatically update to reflect the changes.
# Input Widgets
Source: https://wiki.latch.bio/plots/transformations/widget-types
Use single-line Python to define input widgets and retrieve their values in code
Each widget functions as a Python class and can be assigned to a variable. By calling `.value` on the variable, you can access the actual widget value. For example:
```python theme={null}
from lplots.widgets.select import w_select
options = w_select(
label="Select an item from the dropdown",
options=["alpha", "bravo", "charlie"],
)
print(options.value)
# prints `"alpha", "bravo" or "charlie"` depending on user selection
```
Widgets are rendered in the order that they are called.
## Supported Widget Types
Below is a comprehensive list of supported widget types.
File selector widgets allow users to select a file in their Latch Data and return a latch path that can be downloaded and used in a layout.
```python theme={null}
from lplots.widgets.ldata import w_ldata_picker
import pandas as pd
csv = w_ldata_picker(
label="Condition CSV",
default="latch:///welcome/deseq2/conditions.csv"
)
csv_path = csv.value
# ex. "latch:///welcome/deseq2/conditions.csv"
# Read the selected file into a Pandas DataFrame
df = pd.read_csv(csv_path.download())
```
### Widget Parameters
`label`: *string* string value (required)
`default`: *string* latch data path string used as the default widget value
`required`: *boolean* a boolean that sets the input as requiring input by user and errored when empty
`appearance`: *dict* containing widget appearance attributes:
> `"placeholder"`: *string* placeholder value displayed before a set value
>
> `"detail"`: *string* secondary label text displayed after thet label
>
> `"help_text"`: *string* informative text displayed below input
>
> `"error_text"`: *string* error text displayed below input that replaces `help_text` and sets the input state as errored
>
> `"description"`: *string* longer description text displayed in a hoverable tooltip next to the label
Registry Table Select inputs allow users to select a table from their workspaces registry. The input returns a table id that can be used to fetch table data using the Table class.
```python theme={null}
from lplots.widgets.registry import w_registry_table_picker
from latch.registry.table import Table
# Get the unique ID of the Registry table
table = w_registry_table_picker(label="Select a Registry table")
table_id = table.value
# ex. "3092"
if table_id is not None:
# Get a dataframe from the table ID
df = Table(
id=table_id
).get_dataframe()
```
### Widget Parameters
`label`: *string* label (required)
`default`: *string* id of a registry table
`required`: *boolean* that sets the input as requiring input by user and errored when empty
`appearance`: *dict* containing widget appearance attributes:
> `"placeholder"`: *string* placeholder value displayed before a set value
>
> `"detail"`: *string* secondary label text displayed after thet label
>
> `"help_text"`: *string* informative text displayed below input
>
> `"error_text"`: *string* error text displayed below input that replaces `help_text` and sets the input state as errored
>
> `"description"`: *string* longer description text displayed in a hoverable tooltip next to the label
### Table Class Parameters & Methods
Parameters
`id`: string id of registry table
Methods
`Table.get_dataframe()`: returns a pandas dataframe for the provided registry table id
The Datasource widget allows you to select a tabular datasource from various sources. The datasource can be a file, registry table, or other dataframe in the notebook.
```python theme={null}
from lplots.widgets.datasource import w_datasource_picker, DataSourceValue
from lplots.widgets.text import w_text_output
datasource_picker = w_datasource_picker(
label="Datasource Select Input",
default={
"type": "ldata",
"node_id": "95902"
}
appearance={
"placeholder": "Placeholder…",
"detail": "(File, Registry, Dataframe)",
}
)
```
When setting default values, you must specify the datasource type and then specify the appropriate key or id.
```python theme={null}
# Files in Latch Data
…
default={
"type": "ldata",
"node_id": "95902"
}
…
# Registry Tables
…
default={
"type": "registry",
"table_id": "95902"
}
…
# Dataframes in the notebook
…
default={
"type": "dataframe",
"key": "my_dataframe"
}
…
```
Text inputs allow users to specify a custom text string.
```python theme={null}
from lplots.widgets.text import w_text_input, w_text_output
name = w_text_input(
label="Your name",
default="Barnaby Jones"
)
name_value = name.value
# ex. "Barnaby Jones"
```
`label`: string label (required)
`default`: default string value for input
`required`: a boolean that sets the input as requiring input by user and errored when empty
`appearance`: a dict containing widget appearance attributes:
> `"placeholder"`: placeholder value displayed before a set value
>
> `"detail"`: secondary label text displayed after thet label
>
> `"help_text"`: informative text displayed below input
>
> `"error_text"`: error text displayed below input that replaces `help_text` and sets the input state as errored
>
> `"description"`: longer description text displayed in a hoverable tooltip next to the label
Select inputs allow users to select a single item from a list of string or number options.
```python theme={null}
from lplots.widgets.select import w_select
option = w_select(
label="Select an item from the dropdown",
options=[
"alpha",
"bravo",
"charlie"
],
)
option_value = option.value
# ex. "alpha"
```
`label`: string label (required)
`options`: list of values for the select
`default`: default option from options
`required`: a boolean that sets the input as requiring input by user and errored when empty
`appearance`: a dict containing widget appearance attributes:
> `"placeholder"`: placeholder value displayed before a set value
>
> `"detail"`: secondary label text displayed after thet label
>
> `"help_text"`: informative text displayed below input
>
> `"error_text"`: error text displayed below input that replaces `help_text` and sets the input state as errored
>
> `"description"`: longer description text displayed in a hoverable tooltip next to the label
Multiselect inputs allow users to select a list of items from a list of string or number options.
```python theme={null}
from lplots.widgets.multiselect import w_multi_select
options = w_multi_select(
label="Select an item from the dropdown",
options=[
"alpha",
"bravo",
"charlie"
],
)
options_values = options.value
# ex. ["alpha", "Bravo"]
```
`label`: string label (required)
`options`: list of values for the select
`default`: list of default options from options
`required`: a boolean that sets the input as requiring input by user and errored when empty
`appearance`: a dict containing widget appearance attributes:
> `"placeholder"`: placeholder value displayed before a set value
>
> `"detail"`: secondary label text displayed after thet label
>
> `"help_text"`: informative text displayed below input
>
> `"error_text"`: error text displayed below input that replaces `help_text` and sets the input state as errored
>
> `"description"`: longer description text displayed in a hoverable tooltip next to the label
Radio group inputs allow users to select a single item from a list of string or number options.
```python theme={null}
from lplots.widgets.radio import w_radio_group
option = w_radio_group(
label="Select an item from the dropdown",
options=[
"alpha",
"bravo",
"charlie"
],
)
option_value = option.value
# ex. "alpha"
```
Checkbox inputs allow users to select a boolean true or false value
```python theme={null}
from lplots.widgets.checkbox import w_checkbox
conditional = w_checkbox(
label="Checkbox Input",
)
conditional_value = conditional.value
# ex. true
```
With Rows you're able to stack widgets horizontally, in a row. Widgets in a Row will automatically wrap to the next line when there is insufficient space.
```python theme={null}
from lplots.widgets.row import w_row
from lplots.widgets.select import w_select
option1 = w_select(
label="Select 1",
options=[
"alpha",
"bravo",
"charlie"
],
)
option2 = w_select(
label="Select 2",
options=[
"alpha",
"bravo",
"charlie"
],
)
w_row(
items=[option1, option2]
)
```
A button widget can be used to conditionally run a cell **only** when the button is clicked.
This approach is especially useful for long computational operations when you want to prevent the cell from automatically running in response to reactive widget input changes.
```python theme={null}
from lplots.widgets.button import w_button
from lplots.widgets.text import w_text_input, w_text_output
a = w_text_input(label="a")
b = w_text_input(label="b")
button = w_button(label="Click Button to Run")
if button.value:
# Print out the result of a+b. Pay attention to the video below where the value only updates after the button is clicked.
w_text_output(content=f"Result of a+b: {int(a.value) + int(b.value)}")
```
## Widget Appearance
Each widget allows you to specify appearance and input discriptions.
```python theme={null}
select = w_multi_select(
label="Multiselect Input",
options=["Alpha", "Bravo", "Charlie"],
appearance={
"placeholder": "Placeholder…",
"detail": "(details)",
"help_text": "Help text",
"error_text": "Error text",
"description": "Hover description",
}
)
```
`appearance`: a dict containing widget appearance attributes:
> `"placeholder"`: placeholder value displayed before a set value
>
> `"detail"`: secondary label text displayed after thet label
>
> `"help_text"`: informative text displayed below input
>
> `"error_text"`: error text displayed below input that replaces `help_text` and sets the input state as errored
>
> `"description"`: longer description text displayed in a hoverable tooltip next to the label
## Widgets Reactivity
* Every widget stores a **Signal**, which is the fundamental unit of reactivity in a Plot notebook.
* Signals hold dynamic values that change over time. When a signal's value is updated, any notebook cell that references it is automatically re-executed.
* Each Signal consists of a writer and a listener:
* The writer sets the Signal's value.
* The listener subscribes to the Signal and triggers automatic cell execution when the Signal changes.
**Example**:
```python theme={null}
# Cell number 1
a = w_text_input(label="a")
print(a.value)
```
* In this example, the text input widget `a` is the writer. When the user inputs a new value, it updates the Signal associated with `a`.
* Accessing `a.value` makes the cell a listener. Whenever the input in a changes, the cell will automatically re-run. Calling `a.value` also returns the widget's current value.
* This reactivity extends to any downstream cell using `a.value`, ensuring they also re-execute when a is updated.
### Can I access a widget value without triggering a cell rerun?
To retrieve a widget's value, you typically would use `.value`. However, there are times when you don't want to trigger an automatic cell run when the widget value updates, especially if the cells using `widget.value` are computationally expensive. There are two solutions to this problem:
1. Use a Button widget (Recommended)
2. Use `.sample()`
#### 1. Use a Button Widget (Recommended)
A button widget allows you to manually trigger a cell run only when the button is clicked.
**Example**:
```python theme={null}
from lplots.widgets.text import w_text_input
from lplots.widgets.button import w_button
# Create a text input widget
text_input = w_text_input(label="Input")
# Create a button to trigger execution manually
button = w_button(label="Run")
# When the button is clicked, this cell will execute
if button.value:
print(text_input.value)
```
**How it works:**
* The cell only executes when the user clicks the Run button.
* Widget value changes do not automatically rerun the cell, offering full control over execution.
#### 2 - Use `sample()`
You can use `.sample()` to access the widget's value without triggering a cell rerun. Think of `.sample()` as capturing a snapshot of the widget's value at the precise moment you click the "Run" button in the upper right corner of a cell.
**Examples:**
The following code cell will automatically rerun whenever the widget value changes:
```python theme={null}
from lplots.widgets.text import w_text_input
text_input = w_text_input(label="Input")
print(text_input.value)
```
The following code will *only* execute when the user presses the "Run" button in the upper right corner of the UI:
```python theme={null}
from lplots.widgets.text import w_text_input
text_input = w_text_input(label="Input")
print(text_input.sample())
```
# Setting Up Auto Shutdown from Latch
Source: https://wiki.latch.bio/pods/auto-shutdown
Pods allow easy customization of auto shutdown interval when inactive.
By default, Pods automatically shut off after 1 hour of no network activity.
In the context of Latch Pods, network activity refers to the of inbound or outbound data transfer over the network interface associated with the instance. Some examples of network activity are:
1. **Data retrieval**: If your code within JupyterLab or RStudio interacts with remote data sources, such as querying databases, making API requests, or accessing files from remote locations, network activity will occur when the code sends requests over the network to fetch the required data.
2. **Package installation or updates**: If you install or update packages from remote package repositories within JupyterLab or RStudio, network activity will be required to download the packages and dependencies.
3. **Collaborative features**: Both JupyterLab and RStudio support collaborative features, allowing multiple users to work on the same project or document simultaneously. In such cases, network activity occurs as the server synchronizes changes made by different users, allowing real-time collaboration.
It's important to note that network activity in JupyterLab or RStudio depends on the specific code and operations performed within the environment. If the code and computations are self-contained or focused on local data analysis, network activity may be minimal or non-existent during the execution.
If you notebook contain code blocks that take multiple hours to locally execute, it is recommended that you increase the auto-shutdown duration to allow sufficient time for the code to finish running.
To change the Pod's auto shutoff interval, select the pod of interest, and click **Manage Pod** to navigate to the Pod's **Settings** page.
* When auto shutdown is enabled, the minimum delay before the Pod can be shut down is **15 minutes**.
* If Pod's auto shutdown is disabled, the Pod will **always** be running. This behaviour is often undesirable, except in the case where you want an always-on Pod for running an application server or long-running scripts.
To configure auto shutdown using systemd, [check out our guide](/pods/hard-shutdown)!
# Host a Custom App
Source: https://wiki.latch.bio/pods/custom-app
Latch Pods make it easy to host any custom application, such as Dash Apps, RShiny, Streamlit, and more, on Latch.
## Setting up your Custom App
In this guide, we will walk through step-by-step how you can set up your own custom application.
Ensure your app is installed and configured according to its documentation.
The startup script is located at `/opt/latch/custom_app`. Make sure the app is on **port 5000**, and listens on `::` **(not `localhost` or `0.0.0.0`)**.
* Here are a few examples of modifying the script in different languages.
* **ShinyApp**
```bash theme={null}
#!/usr/bin/env bash
/usr/local/bin/Rscript -e "shiny::runApp(appDir = '/root/', host = '::', port = 5000)"
```
Replace "/root/" with the actual path to your Shiny app directory.
* **Streamlit**
```bash theme={null}
#!/usr/bin/env bash
/opt/mamba/envs/default/bin/streamlit run /root/app.py --server.port 5000 --server.address :: --server.enableCORS false
```
Replace "/root/app.py" with the actual path to your Streamlit app file.
* **Dash App**
```bash theme={null}
#!/usr/bin/env bash
/opt/mamba/envs/default/bin/python /root/app.py
```
Where your Python script (`/root/app.py`) contains:
```python theme={null}
from dash import Dash
app = Dash(__name__, routes_pathname_prefix='/')
# Your app layout and callbacks here
if __name__ == '__main__':
app.run_server(host='::', port=5000)
```
Replace "/root/app.py" with the actual path to your Dash app file.
In the terminal, start the custom app service:
```bash theme={null}
systemctl --user start latch-custom-app
```
The command will run the script under `/opt/latch/custom_app` and start the application for the first time on the Pod.
If you're running these commands from RStudio terminal, you'll need to set these environment variables first:
```bash theme={null}
export XDG_RUNTIME_DIR='/run/user/0'
export DBUS_SESSION_BUS_ADDRESS='unix:path=${XDG_RUNTIME_DIR}/bus'
```
To make the app automatically start as the user starts the Pod the next time, enable the Latch custom app service:
```bash theme={null}
systemctl --user enable latch-custom-app
```
To verify if the Pod is running, navigate to the Pods page, and select **Manage Pod** go to Pod's settings.
This will display a third button on the Pod's card, which we can click to open the custom app running on port 5000.
If the app is set up correctly, you should see it open up in a new tab!
If you receive a **502 Gateway Error**, that means the app has failed to start. Visit our [Debugging an Application](/pods/custom-app#debugging-an-application) section for further instructions.
To see the app in action, stop and start your Pod, and click on the **'Open Custom App'** button.
## Advanced: Enabling the Application to Read from Latch Data
Latch Pods come with Latch Data FUSE (Filesystem in Userspace), which displays the entire filesystem on Latch Data on pods.
LData FUSE is a file system that allows you to access Latch Data within Pods.
LData is mounted automatically when starting a pod, and its content can be inspected under the directory /ldata.
We recommended that you add a component to your app to display the folder tree
under /ldata so that you can select the files you want.
#### To access LData FUSE:
1. Start a new Latch Pod.
2. Navigate to the /ldata directory in your Pod.
3. You will see the entire Latch Data filesystem mirrored in this directory.
## Debugging An Application
If you see a **502 Gateway Error** after clicking **'Open Custom App'**, it means the app has not been started correctly, and there is no application running on port 5000.
To see the logs of why the application may have failed, in your terminal, type:
```bash theme={null}
journalctl --user-unit latch-custom-app
```
The same command can also be used to inspect any other errors that occur while the app is running.
# Custom File Viewer
Source: https://wiki.latch.bio/pods/file-viewer
The Custom File Viewer enables scientists to click on files in Latch Data with a specific extension and view them in an application hosted on a Latch Pod without having to manually enter the pod and download the file.
## Overview
File viewers are [Custom Apps](./custom-app) built on top of [Latch Pod Templates](./templates).
These templates are configured to host a custom application that accepts a file path as a parameter
and downloads that file for the application to access.
In this example, we will be setting up cellxgene to view `.h5ad` files in Latch Data. Note that the
[cellxgene file viewer](../data/visualizations/cellxgene) is already available in Latch Data by default.
## 1. Set up your Custom Application
Follow the instructions [here](./custom-app) to setup a pod that hosts your custom application.
For cellxgene, the launch script (`/opt/latch/custom_app`) looks like this:
```bash theme={null}
#!/usr/bin/env bash
/opt/mamba/envs/default/bin/cellxgene launch pbmc3k.final.h5ad.zarr.h5ad --host :: --port 5000
exec tail --follow /dev/null
```
In the script above, we pass in a harcoded file path `pbmc3k.final.h5ad.zarr.h5ad`. However, to
launch this application from the Latch Data UI, we need to pass in the file path of the file we
want to view.
To do so, add the following command to your bash script:
```bash theme={null}
TARGET_NODE_ID=$(tr '\0' '\n' < /proc/1/environ | grep '^LDATA_NODE_ARG=' | cut -d'=' -f2 || echo '')
```
This pulls the `LDATA_NODE_ARG` environment variable from the pod's environment.
This variable is injected by the Latch backend and contains the ID of the
node that the user clicked on in Latch Data to launch the pod.
Now that we have the node ID, we can use `latch cp` to download the file to the pod and launch the application.
```bash theme={null}
#!/usr/bin/env bash
set -e
TARGET_NODE_ID=$(tr '\0' '\n' < /proc/1/environ | grep '^LDATA_NODE_ARG=' | cut -d'=' -f2 || echo '')
if [ -z "$TARGET_NODE_ID" ]; then # -- (1)
echo "No input file provided. Launching with default Seurat h5ad object."
TARGET_LOCAL_PATH="/root/pbmc3k.final.h5ad.zarr.h5ad"
else
TARGET_REMOTE_PATH="latch://$TARGET_NODE_ID.node"
TARGET_DIR="/root/.latch_cellxgene_inputs"
TARGET_LOCAL_PATH="$TARGET_DIR/$TARGET_NODE_ID.h5ad"
if [ -f "$TARGET_LOCAL_PATH" ]; then # -- (2)
echo "File exists locally. Using $TARGET_LOCAL_PATH"
else
rm -rf $TARGET_DIR # -- (3)
mkdir -p $TARGET_DIR
echo "Downloading $TARGET_REMOTE_PATH to $TARGET_LOCAL_PATH"
/opt/mamba/envs/default/bin/latch cp "$TARGET_REMOTE_PATH" "$TARGET_LOCAL_PATH.tmp" || exit 1 # -- (4)
mv "$TARGET_LOCAL_PATH.tmp" "$TARGET_LOCAL_PATH"
fi
fi
/opt/mamba/envs/default/bin/cellxgene launch "$TARGET_LOCAL_PATH" --host :: --port 5000
exec tail --follow /dev/null
```
Breaking down the script above:
1. First check if the `LDATA_NODE_ARG` environment variable is set. If not, this pod was not launched
from a Latch Data file so we start the application with a default file.
2. Since downloading large files can take a long time, we cache the file locally in the pod. If the file
already exists, we use it instead of re-downloading.
3. Delete the cache directory to avoid stale files from consuming disk space.
4. Download the file to the pod using `latch cp`. We download to a `.tmp` file and then rename it to the
target file to avoid partial downloads from corrupting the cache.
## 2. Create a Pod Template
You should now have a pod that takes in a Latch Data file as a parameter, downloads the file locally, and
launches a custom application using that file. To make this pod available in Latch Data, you need to create a
pod template from it. Follow the instructions [here](./templates) to create a pod template from the pod
created in step 1.
## 3. Configure the Custom File Viewer
To configure Latch Data to open your pod template for a specific file pattern, go to the pod template settings page
and add a regex pattern matching the files you want to open with your custom file viewer. For cellxgene, we want
to restrict the viewer to `.h5ad` files. The regex pattern for this is `^.*\.h5ad$`.
## 4. View Files
You should now be able to click on files in Latch Data containing the pattern defined in step 3 and launch
a pod which will download the file and launch your application.
# Setup Forch Domain / BYOC (Beta)
Source: https://wiki.latch.bio/pods/forch-byoc
Latch allows you to run computation without data leaving your cloud
## Prerequisites
Before you start, ensure you have an IAM role in your AWS that permits you to [create CloudFormation Templates](https://aws.amazon.com/cloudformation/resources/templates/).
Latch utilizes CloudFormation Templates to establish an IAM role that provisions AWS Resources to create a forch domain
## Instructions
### Connecting an AWS Account
Go to this{" "}
link
}
/>
When you open the CloudFormation template, you'll see an acknowledgment stating "The following resource(s) require capabilities: \[AWS::IAM::Role]. I acknowledge that AWS CloudFormation might create IAM resources with custom names." This pertains to you as the customer executing the CloudFormation stack.
The stack creates a role that has permission to provision cloud resources, AWS ensures that you are aware of this action. The permissions of this role which can be verified by inspecting the cloudformation template in the AWS UI.
Refer to \[Advanced Notes]\(#Advanced Notes) for an overview of the permission this IAM role.
* AWS Account Id
* Target AWS Region for this deployment (us-west-2, eu-central-1, etc)
## Architecture
Please refer to this blog [post](https://blog.latch.bio/p/forch-bring-your-own-compute-on-latch?open=false#%C2%A7node-mounts) for an overview of Forch's architecture
## IAM
Each forch domain requires a minimum of 4 IAM role to operate:
1. [forch-agent](#forch-agent) for provisioning cloud resources to setup the forch-domain
2. [forch-orchestrator](#forch-orchestrator) for scheduling and managing tasks in the forch-domain
3. [forch-node](#forch-node) for running the tasks in an compute instances the forch-domain
4. [forch-nat-\*](#forch-nat-*) for running NAT instance in the forch-domain (1 per vpc)
### `forch-agent`
`forch-agent` is created by the Cloudformation Stack from previous [section](#Instructions). This role is used when provisioning cloud resources to setup the forch domain. The list of cloud resources created are as follows:
1. Network resource including vpcs, subnets, internet gateways, security groups, network acls, route tables and elastic ip addresses
2. An S3 Bucket for storing logs
3. [forch-orchestrator](#forch-orchestrator), [forch-node](#forch-node) and [forch-nat-\*](#forch-nat-*) roles and their policies
4. A KMS key for encrypting and decrypting volumes created by forch
5. An ec2 instance running the NAT server on the vpc
6. Forch specific secrets
This role can be safely deleted once the setup of the forch-domain is complete.
| Rules | Purpose |
| --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| [`s3:CreateBucket`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_CreateBucket.html), [`s3:ListBucket*`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_ListObjectsV2.html), [`s3:GetBucket*`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetBucketVersioning.html), [`s3:GetAccelerateConfiguration`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetBucketAccelerateConfiguration.html), [`s3:GetLifecycleConfiguration`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetBucketLifecycleConfiguration.html), [`s3:GetReplicationConfiguration`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetBucketReplication.html), [`s3:GetEncryptionConfiguration`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetBucketEncryption.html), [`s3:PutBucketCORS`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_PutBucketCors.html), [`s3:PutBucketVersioning`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_PutBucketVersioning.html), [`s3:PutEncryptionConfiguration`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_PutBucketEncryption.html), [`s3:PutBucketRequestPayment`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_PutBucketRequestPayment.html) | Retrieve the bucket metadata and configuration, compare it against the desired state, and apply any necessary updates to the S3 bucket `arn:aws:s3:::forch-${AWS::AccountId}` |
| [`iam:CreateRole`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_CreateRole.html), [`iam:GetRole`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_GetRole.html), [`iam:DeleteRole`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_DeleteRole.html), [`iam:PutRolePolicy`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_PutRolePolicy.html), [`iam:AttachRolePolicy`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_AttachRolePolicy.html) | Retrieve configurations, compare it against the desired state, and apply any necessary updates to the IAM roles: `arn:aws:iam::*:role/forch-orchestrator`, `arn:aws:iam::*:role/forch-node`, `arn:aws:iam::*:role/forch-nat-*`, `arn:aws:iam::*:role/forch-agent` |
| [`iam:CreateServiceLinkedRole`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_CreateServiceLinkedRole.html) | Create a service-linked role for the forch-agent linked service to AWS KMS |
| [`iam:PassRole`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_PassRole.html) | Allows `forch-agent` to pass the forch-nat or forch-node role when launching NAT, SSH Forwarder and Pod Router instances |
| [`iam:CreatePolicy`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_CreatePolicy.html), [`iam:GetPolicy`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_GetPolicy.html), [`iam:DeletePolicy`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_DeletePolicy.html), [`iam:CreatePolicyVersion`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_CreatePolicyVersion.html) | Retrieve configuration, compare it against the desired state, and apply any necessary updates to the IAM roles: `arn:aws:iam::*:policy/forch-orchestrator-base`, `arn:aws:iam::*:policy/forch-node-base`, `arn:aws:iam::*:policy/forch-agent-delete-permissions` |
| [`iam:CreateInstanceProfile`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_CreateInstanceProfile.html), [`iam:DeleteInstanceProfile`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_DeleteInstanceProfile.html), [`iam:AddRoleToInstanceProfile`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_AddRoleToInstanceProfile.html) | Create and manage instance profiles: `arn:aws:iam::*:instance-profile/forch-nat-*`, `arn:aws:iam::*:instance-profile/forch-node` |
| [`ec2:CreateTags`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateTags.html) | Tag ec2 resources created by forch-agent |
| [`ec2:CreateKeyPair`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateKeyPair.html), [`ec2:DeleteKeyPair`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DeleteKeyPair.html), [`ec2:ImportKeyPair`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_ImportKeyPair.html), [`ec2:DescribeKeyPairs`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeKeyPairs.html) | Create, import and manage a specific SSH key pair for access to forch-created instances |
| [`ec2:CreateVpc`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateVpc.html), [`ec2:DescribeVpcs`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeVpcs.html), [`ec2:DescribeVpcAttribute`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeVpcAttribute.html), [`ec2:CreateInternetGateway`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateInternetGateway.html), [`ec2:AttachInternetGateway`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_AttachInternetGateway.html), [`ec2:DescribeInternetGateways`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeInternetGateways.html), [`ec2:CreateSecurityGroup`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateSecurityGroup.html), [`ec2:AuthorizeSecurityGroupIngress`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_AuthorizeSecurityGroupIngress.html)/[`Egress`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_AuthorizeSecurityGroupEgress.html), [`ec2:RevokeSecurityGroupIngress`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_RevokeSecurityGroupIngress.html)/[`Egress`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_RevokeSecurityGroupEgress.html), [`ec2:DescribeSecurityGroups`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeSecurityGroups.html), [`ec2:DescribeSecurityGroupRules`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeSecurityGroupRules.html), [`ec2:CreateSubnet`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateSubnet.html), [`ec2:DescribeSubnets`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeSubnets.html), [`ec2:ModifySubnetAttribute`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_ModifySubnetAttribute.html), [`ec2:CreateRouteTable`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateRouteTable.html), [`ec2:CreateRoute`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateRoute.html), [`ec2:DescribeRouteTables`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeRouteTables.html), [`ec2:CreateNetworkAcl`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateNetworkAcl.html), [`ec2:DeleteNetworkAclEntry`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DeleteNetworkAclEntry.html), [`ec2:CreateNetworkAclEntry`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateNetworkAclEntry.html), [`ec2:ReplaceNetworkAclAssociation`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_ReplaceNetworkAclAssociation.html) | Retrieve the configuration of the Forch VPC and its associated network resources, compare it to the desired state, and apply any necessary updates |
| [`ec2:AllocateAddress`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_AllocateAddress.html), [`ec2:AssociateAddress`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_AssociateAddress.html), [`ec2:DescribeAddresses`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeAddresses.html), [`ec2:DescribeAddressesAttribute`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeAddressesAttribute.html) | Provision Elastic IP address for NAT instance, SSH Forwarder and Pod Router instance and associate them to the appropriate instances |
| [`ec2:DescribeImages`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeImages.html) | Retrieve information about Latch-owned Forch ami image |
| [`ec2:RunInstances`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_RunInstances.html), [`ec2:DescribeInstances`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeInstances.html), [`ec2:DescribeVolumes`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeVolumes.html), [`ec2:DescribeAvailabilityZones`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeAvailabilityZones.html) | Retrieve information about the NAT, SSH Forwarder and Pod Router instance and launch them if not present. Instance must be launched with the `forch-node` instance profile, use the Latch-owned forch ami image and launched only with forch created ebs volumes |
| [`ssm:GetParameters`](https://docs.aws.amazon.com/systems-manager/latest/APIReference/API_GetParameters.html) | Allows retrieving parameters (configuration data, environment variables, etc.) from AWS Systems Manager Parameter Store. **Note:** Required by AWS for `ec2:RunInstances` |
| [`secretsmanager:CreateSecret`](https://docs.aws.amazon.com/secretsmanager/latest/apireference/API_CreateSecret.html), [`secretsmanager:PutSecretValue`](https://docs.aws.amazon.com/secretsmanager/latest/apireference/API_PutSecretValue.html), [`secretsmanager:DeleteSecret`](https://docs.aws.amazon.com/secretsmanager/latest/apireference/API_DeleteSecret.html) | Create and manage the forch-nat JWT token, and ssh forwarder private keys |
| [`kms:CreateKey`](https://docs.aws.amazon.com/kms/latest/APIReference/API_CreateKey.html), [`kms:PutKeyPolicy`](https://docs.aws.amazon.com/kms/latest/APIReference/API_PutKeyPolicy.html), [`kms:EnableKeyRotation`](https://docs.aws.amazon.com/kms/latest/APIReference/API_EnableKeyRotation.html), [`kms:CreateAlias`](https://docs.aws.amazon.com/kms/latest/APIReference/API_CreateAlias.html) | Create and manage the forch-volume key used to encrypt / decrypt forch created EBS volumes |
| [`kms:Encrypt`](https://docs.aws.amazon.com/kms/latest/APIReference/API_Encrypt.html), [`kms:Decrypt`](https://docs.aws.amazon.com/kms/latest/APIReference/API_Decrypt.html), [`kms:GenerateDataKey*`](https://docs.aws.amazon.com/kms/latest/APIReference/API_GenerateDataKey.html), [`kms:CreateGrant`](https://docs.aws.amazon.com/kms/latest/APIReference/API_CreateGrant.html) | Allows usage of KMS keys to decrypt EBS volumes and AMIs when launching instances |
```json theme={null}
{
"Statement": [
{
"Action": [
"s3:CreateBucket",
"s3:GetBucket*",
"s3:ListBucket*",
"s3:PutBucketCORS",
"s3:GetAccelerateConfiguration",
"s3:PutBucketVersioning",
"s3:GetLifecycleConfiguration",
"s3:GetReplicationConfiguration",
"s3:GetEncryptionConfiguration",
"s3:PutEncryptionConfiguration",
"s3:PutBucketRequestPayment"
],
"Effect": "Allow",
"Resource": "arn:aws:s3:::forch-${aws_account_id}"
},
{
"Action": [
"iam:CreateRole",
"iam:GetRole",
"iam:AttachRolePolicy",
"iam:DeleteRole",
"iam:ListRolePolicies",
"iam:PutRolePolicy",
"iam:ListInstanceProfilesForRole",
"iam:ListAttachedRolePolicies",
"iam:GetRolePolicy",
"iam:CreateServiceLinkedRole"
],
"Effect": "Allow",
"Resource": [
"arn:aws:iam::*:role/forch-orchestrator",
"arn:aws:iam::*:role/forch-node",
"arn:aws:iam::*:role/forch-nat-*",
"arn:aws:iam::*:role/forch-agent"
]
},
{
"Action": ["iam:CreateServiceLinkedRole"],
"Effect": "Allow",
"Resource": ["arn:aws:iam::*:role/forch-agent"],
"Condition": {
"StringEquals": {
"iam:AWSServiceName": "kms.amazonaws.com"
}
}
},
{
"Action": ["iam:PassRole"],
"Effect": "Allow",
"Resource": ["arn:aws:iam::*:role/forch-nat-*", "arn:aws:iam::*:role/forch-node"]
},
{
"Action": [
"iam:CreatePolicy",
"iam:GetPolicy",
"iam:GetPolicyVersion",
"iam:CreatePolicyVersion",
"iam:DeletePolicy",
"iam:DeletePolicyVersion",
"iam:ListPolicyVersions"
],
"Effect": "Allow",
"Resource": [
"arn:aws:iam::*:policy/forch-orchestrator-base",
"arn:aws:iam::*:policy/forch-node-base",
"arn:aws:iam::*:policy/forch-agent-delete-permissions"
]
},
{
"Action": [
"iam:CreateInstanceProfile",
"iam:GetInstanceProfile",
"iam:DeleteInstanceProfile",
"iam:AddRoleToInstanceProfile"
],
"Effect": "Allow",
"Resource": [
"arn:aws:iam::*:instance-profile/forch-nat-*",
"arn:aws:iam::*:instance-profile/forch-node"
]
},
{
"Action": "ec2:CreateTags",
"Effect": "Allow",
"Resource": "*"
},
{
"Action": ["ec2:CreateKeyPair", "ec2:DeleteKeyPair", "ec2:ImportKeyPair"],
"Resource": "arn:aws:ec2:*:*:key-pair/forch/debug-root",
"Effect": "Allow"
},
{
"Action": "ec2:DescribeKeyPairs",
"Resource": "*",
"Effect": "Allow"
},
{
"Action": ["ec2:CreateVpc", "ec2:DescribeVpcs", "ec2:DescribeVpcAttribute"],
"Resource": "*",
"Effect": "Allow"
},
{
"Action": [
"ec2:CreateInternetGateway",
"ec2:AttachInternetGateway",
"ec2:DescribeInternetGateways"
],
"Effect": "Allow",
"Resource": "*"
},
{
"Action": "ec2:CreateSecurityGroup",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:security-group/*"
},
{
"Action": "ec2:CreateSecurityGroup",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:vpc/*",
"Condition": {
"StringEquals": {
"aws:ResourceTag/Created By": "Forch"
}
}
},
{
"Action": [
"ec2:RevokeSecurityGroupEgress",
"ec2:RevokeSecurityGroupIngress",
"ec2:AuthorizeSecurityGroupIngress",
"ec2:AuthorizeSecurityGroupEgress"
],
"Effect": "Allow",
"Resource": "*"
},
{
"Action": ["ec2:DescribeSecurityGroups", "ec2:DescribeSecurityGroupRules"],
"Effect": "Allow",
"Resource": "*"
},
{
"Action": "ec2:CreateSubnet",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:subnet/*"
},
{
"Action": "ec2:CreateSubnet",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:vpc/*",
"Condition": {
"StringEquals": {
"aws:ResourceTag/Created By": "Forch"
}
}
},
{
"Action": ["ec2:DescribeSubnets", "ec2:ModifySubnetAttribute"],
"Effect": "Allow",
"Resource": "*"
},
{
"Action": "ec2:CreateRouteTable",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:route-table/*"
},
{
"Action": "ec2:CreateRouteTable",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:vpc/*",
"Condition": {
"StringEquals": {
"aws:ResourceTag/Created By": "Forch"
}
}
},
{
"Action": "ec2:CreateRoute",
"Effect": "Allow",
"Resource": "*"
},
{
"Action": "ec2:DescribeRouteTables",
"Effect": "Allow",
"Resource": "*"
},
{
"Action": "ec2:CreateNetworkAcl",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:network-acl/*"
},
{
"Action": "ec2:CreateNetworkAcl",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:vpc/*",
"Condition": {
"StringEquals": {
"aws:ResourceTag/Created By": "Forch"
}
}
},
{
"Action": "ec2:DescribeNetworkAcls",
"Effect": "Allow",
"Resource": "*"
},
{
"Action": [
"ec2:DeleteNetworkAclEntry",
"ec2:CreateNetworkAclEntry",
"ec2:ReplaceNetworkAclAssociation"
],
"Effect": "Allow",
"Resource": "*"
},
{
"Action": "ec2:AllocateAddress",
"Effect": "Allow",
"Resource": "*"
},
{
"Action": "ec2:AssociateAddress",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:elastic-ip/*",
"Condition": {
"StringEquals": {
"aws:ResourceTag/forch/allow": "true"
}
}
},
{
"Action": "ec2:AssociateAddress",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:instance/*"
},
{
"Action": ["ec2:DescribeAddresses", "ec2:DescribeAddressesAttribute"],
"Effect": "Allow",
"Resource": "*"
},
{
"Action": "ec2:DescribeImages",
"Effect": "Allow",
"Resource": "*"
},
{
"Action": "ec2:RunInstances",
"Condition": {
"ArnLike": {
"ec2:InstanceProfile": [
"arn:aws:iam::*:instance-profile/forch-node",
"arn:aws:iam::*:instance-profile/forch-nat-*"
]
}
},
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:instance/*"
},
{
"Action": "ec2:RunInstances",
"Effect": "Allow",
"Resource": [
"arn:aws:ec2:*:*:network-interface/*",
"arn:aws:ec2:*:*:security-group/*",
"arn:aws:ec2:*:*:subnet/*"
]
},
{
"Action": "ec2:RunInstances",
"Condition": {
"StringEquals": {
"ec2:Owner": "812206152185"
}
},
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:image/*"
},
{
"Action": "ec2:RunInstances",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:key-pair/forch/debug-root"
},
{
"Action": "ec2:RunInstances",
"Resource": "arn:aws:ec2:*:*:volume/*",
"Effect": "Allow"
},
{
"Action": [
"ec2:DescribeInstances",
"ec2:DescribeInstanceTypes",
"ec2:DescribeTags",
"ec2:DescribeInstanceAttribute"
],
"Effect": "Allow",
"Resource": "*"
},
{
"Action": ["ec2:DescribeVolumes"],
"Effect": "Allow",
"Resource": "*"
},
{
"Action": ["ec2:DescribeAvailabilityZones"],
"Effect": "Allow",
"Resource": "*"
},
{
"Action": "ssm:GetParameters",
"Effect": "Allow",
"Resource": "*"
},
{
"Action": [
"secretsmanager:CreateSecret",
"secretsmanager:DescribeSecret",
"secretsmanager:PutSecretValue",
"secretsmanager:DeleteSecret",
"secretsmanager:GetSecretValue",
"secretsmanager:TagResource",
"secretsmanager:GetResourcePolicy"
],
"Effect": "Allow",
"Resource": [
"arn:aws:secretsmanager:*:*:secret:forch/nat-jwt*",
"arn:aws:secretsmanager:*:*:secret:forch/ssh-forwarder/ssh_host_ecdsa_key*",
"arn:aws:secretsmanager:*:*:secret:forch/ssh-forwarder/ssh_host_rsa_key*",
"arn:aws:secretsmanager:*:*:secret:forch/ssh-forwarder/ssh_host_ed25519_key*"
]
},
{
"Action": [
"kms:CreateKey",
"kms:ReplicateKey",
"kms:DescribeKey",
"kms:TagResource",
"kms:GetKeyPolicy",
"kms:GetKeyRotationStatus",
"kms:ListResourceTags",
"kms:PutKeyPolicy",
"kms:EnableKeyRotation",
"kms:CreateAlias",
"kms:ListAliases"
],
"Effect": "Allow",
"Resource": "*"
},
{
"Effect": "Allow",
"Action": [
"kms:Encrypt",
"kms:Decrypt",
"kms:ReEncrypt*",
"kms:GenerateDataKey*",
"kms:DescribeKey",
"kms:CreateGrant"
],
"Resource": "*"
}
],
"Version": "2012-10-17"
}
```
### `forch-orchestrator`
`forch-orchestrator` is assumed at runtime to schedule and manage tasks. It has permissions to:
1. Run and Terminate ec2 instances on forch created vpc
2. Assign Private IP Addresses to ec2 instances
3. Create, Modify, Detach, Attach and Delete volumes
4. Describe, Associate and Disassociate forch created elastic ip addresses
5. Use KMS Keys to decrypt volumes
6. Get and List objects in the S3 bucket storing logs
| Rules | Purpose |
| ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| [`ec2:RunInstances`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_RunInstances.html) | Allows launching EC2 instances in the Forch VPC. Instance must be launched with the `forch-node` instance profile, use the Latch-owned forch ami image and launched only with forch created ebs volumes |
| [`iam:PassRole`](https://docs.aws.amazon.com/IAM/latest/APIReference/API_PassRole.html) | Allows the orchestrator to pass the forch-node IAM role to an EC2 instance upon creation, granting the instance its required permissions |
| [`ssm:GetParameters`](https://docs.aws.amazon.com/systems-manager/latest/APIReference/API_GetParameters.html) | Allows retrieving parameters (configuration data, environment variables, etc.) from AWS Systems Manager Parameter Store. **Note:** Required by AWS for `ec2:RunInstances` |
| [`ec2:TerminateInstances`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_TerminateInstances.html) | Allows terminating EC2 instances that are tagged `Created By: Forch` |
| [`ec2:AssignPrivateIpAddresses`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_AssignPrivateIpAddresses.html), [`ec2:AssignIpv6Addresses`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_AssignIpv6Addresses.html) | Assign private IPv4 and public IPv6 addresses to instances within the Forch VPC |
| [`ec2:DescribeNetworkInterfaces`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeNetworkInterfaces.html) | Retrieve details of network interfaces attached to forch created instance to manage IP addresses |
| [`ec2:DescribeInstances`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeInstances.html), [`ec2:DescribeInstanceStatus`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeInstanceStatus.html) | To retrieve details and poll status of instances |
| [`ec2:ModifyVolume`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_ModifyVolume.html), [`ec2:DetachVolume`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DetachVolume.html), [`ec2:CreateVolume`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateVolume.html), [`ec2:DeleteVolume`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DeleteVolume.html), [`ec2:AttachVolume`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_AttachVolume.html) | To manage EBS volumes created by forch orchestrator |
| [`ec2:DetachVolume`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DetachVolume.html), [`ec2:AttachVolume`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_AttachVolume.html) | Allows attaching/detaching volumes to/from instances using the forch-node Instance Profile AND is tagged `Created By: Forch` |
| [`ec2:DescribeVolumesModifications`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeVolumesModifications.html), [`ec2:DescribeVolumes`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeVolumes.html) | Retrieve details of EBS volumes and storage device resize operations |
| [`ec2:DisassociateAddress`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DisassociateAddress.html), [`ec2:AssociateAddress`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_AssociateAddress.html) | Attach / Detach Elastic IPs to instances in the Forch VPC |
| [`ec2:DescribeAddresses`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeAddresses.html) | Allows retrieving details of all Elastic IP addresses in the account |
| [`ec2:CreateTags`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_CreateTags.html) | Tag ec2 instances created by forch orchestrator |
| [`s3:GetObject`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetObject.html) | Retrieve logs from the log storage s3 bucket |
| [`s3:ListBucket`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_ListObjectsV2.html) | List the contents of the log storage S3 bucket |
| [`sts:AssumeRole`](https://docs.aws.amazon.com/STS/latest/APIReference/API_AssumeRole.html) | Allows the forch orchestrator to assume another IAM role in the AWS account |
| [`secretsmanager:UpdateSecret`](https://docs.aws.amazon.com/secretsmanager/latest/apireference/API_UpdateSecret.html), [`secretsmanager:CreateSecret`](https://docs.aws.amazon.com/secretsmanager/latest/apireference/API_CreateSecret.html) | Create and update secrets tagged with `forch/allow: true` |
| [`kms:ReEncrypt*`](https://docs.aws.amazon.com/kms/latest/APIReference/API_ReEncrypt.html), [`kms:GenerateDataKey*`](https://docs.aws.amazon.com/kms/latest/APIReference/API_GenerateDataKey.html), [`kms:Encrypt`](https://docs.aws.amazon.com/kms/latest/APIReference/API_Encrypt.html), [`kms:DescribeKey`](https://docs.aws.amazon.com/kms/latest/APIReference/API_DescribeKey.html), [`kms:Decrypt`](https://docs.aws.amazon.com/kms/latest/APIReference/API_Decrypt.html), [`kms:CreateGrant`](https://docs.aws.amazon.com/kms/latest/APIReference/API_CreateGrant.html) | Allows usage of KMS keys to decrypt EBS volumes and AMIs when launching instances |
```json theme={null}
{
"Statement": [
{
"Action": "ec2:RunInstances",
"Condition": {
"StringEquals": {
"ec2:InstanceProfile": "arn:aws:iam::${aws_account_id}:instance-profile/forch-node"
}
},
"Effect": "Allow",
"Resource": "arn:*:ec2:*:*:instance/*",
"Sid": "ForchRunInstance"
},
{
"Action": "ec2:RunInstances",
"Condition": {
"StringEquals": {
"ec2:Vpc": "arn:aws:ec2:${aws_region}:${aws_account_id}:vpc/${vpc_id}""ec2:Vpc": "${vpc_arn}"
}
},
"Effect": "Allow",
"Resource": [
"arn:aws:ec2:*:*:subnet/*",
"arn:aws:ec2:*:*:security-group/*",
"arn:aws:ec2:*:*:network-interface/*"
],
"Sid": "ForchRunInstanceVpcPolicy"
},
{
"Action": "ec2:RunInstances",
"Condition": {
"StringEquals": {
"ec2:Owner": "812206152185"
}
},
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:image/*",
"Sid": "ForchRunInstanceImages"
},
{
"Action": "ec2:RunInstances",
"Effect": "Allow",
"Resource": "arn:aws:ec2:${aws_region}:${aws_account_id}:key-pair/forch/debug-root",
"Sid": "ForchRunInstanceKeyPair"
},
{
"Action": "ec2:RunInstances",
"Effect": "Allow",
"Resource": "arn:aws:ec2:*:*:volume/*",
"Sid": "ForchRunInstanceVolumes"
},
{
"Action": "iam:PassRole",
"Effect": "Allow",
"Resource": "arn:aws:iam::${aws_account_id}:role/forch-node",
"Sid": "ForchNodePassRole"
},
{
"Action": "ssm:GetParameters",
"Effect": "Allow",
"Resource": "*",
"Sid": "SystemMangerParamters"
},
{
"Action": "ec2:TerminateInstances",
"Condition": {
"StringEquals": {
"ec2:ResourceTag/Created By": "Forch"
}
},
"Effect": "Allow",
"Resource": "arn:*:ec2:*:*:instance/*",
"Sid": "ForchTerminateNode"
},
{
"Action": [
"ec2:AssignPrivateIpAddresses",
"ec2:AssignIpv6Addresses"
],
"Condition": {
"StringEquals": {
"ec2:Vpc": "arn:aws:ec2:${aws_region}:${aws_account_id}:vpc/${vpc_id}"
}
},
"Effect": "Allow",
"Resource": "*",
"Sid": "ForchNodeIps"
},
{
"Action": [
"ec2:DescribeNetworkInterfaces",
"ec2:DescribeInstances",
"ec2:DescribeInstanceStatus"
],
"Effect": "Allow",
"Resource": "*",
"Sid": "ForchNodeDescribeInfo"
},
{
"Action": [
"ec2:ModifyVolume",
"ec2:DetachVolume",
"ec2:CreateVolume",
"ec2:DeleteVolume",
"ec2:AttachVolume"
],
"Condition": {
"StringEquals": {
"ec2:ResourceTag/CreatedBy": [
"nucleus/create_volume",
"nucleus/restore_snapshot",
"nucleus-workflows"
]
}
},
"Effect": "Allow",
"Resource": "arn:*:ec2:*:*:volume/*",
"Sid": "ForchNodeVolumes"
},
{
"Action": [
"ec2:DetachVolume",
"ec2:AttachVolume"
],
"Condition": {
"StringEquals": {
"ec2:InstanceProfile": "arn:aws:iam::${aws_account_id}:instance-profile/forch-node",
"ec2:ResourceTag/Created By": "Forch"
}
},
"Effect": "Allow",
"Resource": "arn:*:ec2:*:*:instance/*",
"Sid": "ForchNodeVolumesAllowedInstances"
},
{
"Action": [
"ec2:DescribeVolumesModifications",
"ec2:DescribeVolumes"
],
"Effect": "Allow",
"Resource": "*",
"Sid": "ForchNodeDescribeVolumes"
},
{
"Action": [
"ec2:DisassociateAddress",
"ec2:AssociateAddress"
],
"Effect": "Allow",
"Resource": [
"arn:aws:ec2:${aws_region}:${aws_account_id}:elastic-ip/${eipalloc_id}",
"arn:aws:ec2:${aws_region}:${aws_account_id}:elastic-ip/${eipalloc_id}"
],
"Sid": "ForchElasticIp"
},
{
"Action": [
"ec2:DisassociateAddress",
"ec2:AssociateAddress"
],
"Condition": {
"StringEquals": {
"ec2:Vpc": "arn:aws:ec2:${aws_region}:${aws_account_id}:vpc/${vpc_id}"
}
},
"Effect": "Allow",
"Resource": "arn:*:ec2:*:*:network-interface/*",
"Sid": "ForchElasticIpNetworkInterface"
},
{
"Action": [
"ec2:DisassociateAddress",
"ec2:AssociateAddress"
],
"Effect": "Allow",
"Resource": "arn:*:ec2:*:*:instance/*",
"Sid": "ForchElasticIpInstances"
},
{
"Action": "ec2:DescribeAddresses",
"Effect": "Allow",
"Resource": "*",
"Sid": "ForchDescribeElasticIp"
},
{
"Action": "ec2:CreateTags",
"Condition": {
"StringEquals": {
"ec2:InstanceProfile": "arn:aws:iam::${aws_account_id}:instance-profile/forch-node"
}
},
"Effect": "Allow",
"Resource": "arn:*:ec2:*:*:instance/*",
"Sid": "ForchTagInstances"
},
{
"Action": "ec2:CreateTags",
"Condition": {
"StringEquals": {
"ec2:ResourceTag/Created By": "Forch"
}
},
"Effect": "Allow",
"Resource": "arn:*:ec2:*:*:volume/*",
"Sid": "ForchTagVolumes"
},
{
"Action": "ec2:CreateTags",
"Condition": {
"StringEquals": {
"ec2:Vpc": "arn:aws:ec2:${aws_region}:${aws_account_id}:vpc/${vpc_id}"
}
},
"Effect": "Allow",
"Resource": "arn:*:ec2:*:*:network-interface/*",
"Sid": "ForchNetworkInterfaces"
},
{
"Action": "s3:GetObject",
"Effect": "Allow",
"Resource": [
"arn:aws:s3:::forch-${aws_account_id}/logs/*",
"arn:aws:s3:::forch-${aws_account_id}/logs"
],
"Sid": "ForchFluentdReadWrite"
},
{
"Action": "s3:ListBucket",
"Effect": "Allow",
"Resource": "arn:aws:s3:::forch-${aws_account_id}",
"Sid": "ForchFluentdList"
},
{
"Action": "sts:AssumeRole",
"Effect": "Allow",
"Resource": "*",
"Sid": "AllowAssumeRole"
},
{
"Action": [
"secretsmanager:UpdateSecret",
"secretsmanager:CreateSecret"
],
"Condition": {
"StringEquals": {
"secretsmanager:ResourceTag/forch/allow": "true"
}
},
"Effect": "Allow",
"Resource": "*"
},
{
"Action": [
"kms:ReEncrypt*",
"kms:GenerateDataKey*",
"kms:Encrypt",
"kms:DescribeKey",
"kms:Decrypt",
"kms:CreateGrant"
],
"Effect": "Allow",
"Resource": "*"
}
],
"Version": "2012-10-17"
}
```
### `forch-node`
`forch-node` role has permission to get the task secrets from secretsmanager, read and write logs to the s3 bucket and also assume the `forch-node-shared` role to get access to ecr images and secrets from Latch's aws account. This role's can only be assumed by roles within the forch domains' cloud account.
| Rules | Purpose |
| -------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------- |
| [`s3:PutObject`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_PutObject.html), [`s3:GetObject`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_GetObject.html) | Store log files to the S3 bucket. Retrieve files for log verification or log rotation |
| [`s3:ListBucket`](https://docs.aws.amazon.com/AmazonS3/latest/API/API_ListObjectsV2.html) | List the bucket contents to check for the existence of the logs folder, manage file rotation, or check the state of previously uploaded batches of logs |
| [`ec2:DescribeAddresses`](https://docs.aws.amazon.com/AWSEC2/latest/APIReference/API_DescribeAddresses.html) | Retrieve information about EC2 Elastic IP addresses attached to the instance to configure networking |
| [`sts:AssumeRole`](https://docs.aws.amazon.com/STS/latest/APIReference/API_AssumeRole.html) | Used to assume the IAM role `forch-node-shared` to get access to resources in Latch's AWS Account (ECR images, secrets) |
| [`secretsmanager:GetSecretValue`](https://docs.aws.amazon.com/secretsmanager/latest/apireference/API_GetSecretValue.html) | Retrieve secrets tagged with `forch/allow: true` |
| [`secretsmanager:BatchGetSecretValue`](https://docs.aws.amazon.com/secretsmanager/latest/apireference/API_BatchGetSecretValue.html) | Allows retrieving multiple secrets at once |
```json theme={null}
{
"Statement": [
{
"Action": [
"s3:PutObject",
"s3:GetObject"
],
"Effect": "Allow",
"Resource": [
"arn:aws:s3:::forch-${aws_account_id}/logs/*",
"arn:aws:s3:::forch-${aws_account_id}/logs"
],
"Sid": "ForchFluentdReadWrite"
},
{
"Action": "s3:ListBucket",
"Effect": "Allow",
"Resource": "arn:aws:s3:::forch-${aws_account_id}",
"Sid": "ForchFluentdList"
},
{
"Action": "ec2:DescribeAddresses",
"Effect": "Allow",
"Resource": "*",
"Sid": "ForchDescribeAddresses"
},
{
"Action": "sts:AssumeRole",
"Effect": "Allow",
"Resource": "*",
"Sid": "AllowAssumeRole"
},
{
"Action": "secretsmanager:BatchGetSecretValue",
"Effect": "Allow",
"Resource": "*",
"Sid": "BatchGetSecretValue"
},
{
"Action": "secretsmanager:GetSecretValue",
"Effect": "Allow",
"Resource": "*",
"Sid": "GetSecretValue",
"Condition": {
"StringEquals": {
"aws:ResourceTag/forch/account_id": "${aws:PrincipalAccount}",
"aws:ResourceTag/forch/allow": "true"
}
}
}
],
"Version": "2012-10-17"
}
```
### `forch-nat-*`
`forch-nat-*` role is a superset of forch-node. It has additional permissions to get the `nat-jwt-*` JWT token from secretsmanager to perform database authentication
| Rules | Purpose |
| ------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------- |
| [`secretsmanager:GetSecretValue`](https://docs.aws.amazon.com/secretsmanager/latest/apireference/API_GetSecretValue.html) | Retrieve JWT token to authenticate with Latch's database |
```json theme={null}
{
"Version": "2012-10-17",
"Statement": [
{
"Action": "secretsmanager:GetSecretValue",
"Effect": "Allow",
"Resource": "arn:aws:secretsmanager:${aws_region}:${aws_account_id}:secret:forch/nat-jwt-*",
"Sid": "JwtSecret"
}
]
}
```
# Latch Pods Basics
Source: https://wiki.latch.bio/pods/getting-started
In this tutorial, we will walk through the basics of creating your first Pod.
### 1. Add your Pod
1. First, navigate to the Pods tab on the left sidebar.
Find the [Pods tab here.](https://console.latch.bio/apps)
2. Click 'Create a Pod' to create your first Pod.
You will be prompted to the Pod settings page to specify your Pod’s name, compute, and storage resources.
### 2. Set up GPUs & Compute
1. You can choose from a maximum of 93 CPU cores and 2 TB of RAM for your Pod, or up to 8 GPUs. Pod resources can also be modified easily at a later time once the Pod has been created.
2. Click **Create Pod** to start launching your Pod.
Depending on your resource settings, Pods may take 5-10 minutes to start.
Larger pods are likely to take longer to start up.
### 3. Access RStudio and Jupyter Labs
Once a Pod is running, JupyterLab and RStudio will start automatically. Click on the Jupyter Labs or RStudio buttons to access your notebook environment.
At first, you will see the RStudio and Jupyter Labs buttons greyed out. This
means the applications are starting, may take an additionally 30 seconds to 1
minute to start.
### 4. Accessing your Latch Data inside Latch Pods
Latch Pods come with Latch Data FUSE (Filesystem in Userspace), which displays the entire filesystem for a workspace Latch Data in those workspace's pods. The Latch Data filesystem is mounted at the `/ldata`.
Latch Data FUSE only displays a mirror of the file system on Latch Data, and does not download every file and folder by default. For large folders that need to be accessed frequently, it is advisable to copy the folder from `/ldata` to a local scratch directory inside your Pod. You can use the command `latch cp` to copy frequently use files to a Pod. More on using `latch cp` [here](/pods/data-transfer).
***
That's it! You have successfully started your first Pod, which has RStudio and Jupyter Labs pre-installed, and direct access to Latch Data.
# Configuring Auto Shutdown
Source: https://wiki.latch.bio/pods/hard-shutdown
Configure Pods for scheduled shutdown using systemd.
This guide explains how to set up automatic shutdown for a Pod using `systemd`. `systemd` is a system and service manager for Linux that provides a reliable and flexible way to manage services and tasks, including scheduled shutdowns.
We advise against using this feature for Pods running long-duration or overnight scripts, as it will forcibly terminate the Pod while the script is in progress.
1. To initiate a hard shutdown, create a systemd service unit file named `/etc/systemd/system/force-shutoff.service` with the following content:
```bash theme={null}
# /etc/systemd/system/force-shutoff.service
[Unit]
Description=Forcedly shut off this pod
[Service]
Type=exec
Restart=on-failure
SyslogIdentifier=%N
ExecStart=/usr/bin/env bash -c ' \
curl https://nucleus.latch.bio/pods/stop \
-H "Content-Type: application/json" \
-H "Authorization: Latch-SDK-Token $(cat /root/.latch/token)" \
--data "{\\"pod_id\\": $(cat /root/.latch/id)}" \
'
```
2. Next, create a systemd timer unit file named `/etc/systemd/system/force-shutoff.timer` to specify the shutdown schedule:
```bash theme={null}
# /etc/systemd/system/force-shutoff.timer
[Unit]
Description=Forcedly shut off this pod at 5pm
[Timer]
OnCalendar=*-*-* 17:00:00 America/Los_Angeles
[Install]
WantedBy=timers.target
```
3. Enable and start the timer service using the following command:
```console theme={null}
systemctl enable --now force-shutoff.timer
```
4. If you need to change the shutdown time in the future, update the time in `/etc/systemd/system/force-shutoff.timer`, and then reload all systemd configurations within the Pod by running:
```console theme={null}
systemctl daemon-reload
```
5. If you want to disable the scheduled shutdown in the future, use the following command:
```console theme={null}
systemctl disable force-shutoff.timer
```
By following these steps, you can configure your Pod to perform a scheduled hard shutdown using systemd. This ensures that your Pod shuts down automatically at the specified time, helping you manage resources efficiently.
# Integration with GitHub
Source: https://wiki.latch.bio/pods/integration-with-github
Using GitHub within Pods
Adding a Github Personal Access Token to your account and creating a Pod from
a Github Repository is depricated as of 8/12/2024. Please follow the
instructions below to use Github within your pod.
To set up a development environment within a Pod from GitHub, clone the desired repository to access the project files. Open your terminal inside the Pod (the terminal can be accessed through Jupyter Labs, RStudio or SSH), and use the `git clone` command followed by the repository URL.
# Integration with VSCode
Source: https://wiki.latch.bio/pods/integration-with-vscode
Follow our tutorial to use Visual Studio Code inside your Pod and navigate the filesystem on your favorite IDE.
1. Open Terminal & go inside the `~/.ssh` directory:
To go into the directory and see if you already have a saved public key, run the following command:
```bash theme={null}
cd ~/.ssh && ls ~/.ssh/*.pub
```
This command displays the files within the SSH directory. If you have an SSH key, there will be a file ending with .pub.
2. If you have no SSH key, follow [this tutorial.](/pods/ssh)
3. To get your SSH key, enter this in your terminal:
```bash theme={null}
pbcopy < ~/.ssh/name_of_file_that_ends_with_.pub
```
Don't worry if there is no output. This automatically copies your key into your clipboard.
1. Go back to [Developer settings](https://console.latch.bio/settings/developer) to enter the key you just copied.
Please make sure that there is no empty line after you enter your SSH key.
1. Start your pod.
The Pod needs to say "Running" before you can connect to VSCode.
2. Copy the SSH command from your pod.
3. Past the SSH command into the terminal.
If your SSH was added successfully, the directory you are in will change to the pod.
1. Download the “Remote - SSH” extension in VSCode.
2. Click on the small green or blue remote icon at the bottom left of your VSCode Window.
The icon looks like a greater than sign slightly under a less than sign.
3. Select "Connect to Host".
4. Select "Add New SSH Host".
5. Copy the SSH command on the sidebar of Pods.
6. Paste the SSH command into VS Code.
7. In the bottom right corner, click connect in the Host Added pop-up.
8. Another VS Code window will open and connect to your SSH.
You can mouse over the green/blue remote icon in the bottom left corner to see the host IP and the status
of your SSH connection.
9. Once you are connected, you can start programming in the SSH.
Click on the explorer tab, then click open folder and open sdk\_tutorial.ipynb to test out
programming in the SSH!
# Accessing Latch Data in Pod using Latch Data FUSE
Source: https://wiki.latch.bio/pods/mount-data
Latch Pods provides direct access to all files stored on Latch Data.
## Overview
[Latch Pods](./pods.mdx) come with Latch Data FUSE (Filesystem in Userspace), a virtual filesystem inside of pods which allows you to directly interact with the data in your workspace and share data between pods easily.
You can create, read, write and delete files and directories in your [Latch Data](../data/overview.mdx) simply with your command line as you would with any other filesystem.
The Latch Data FUSE is available on every new pod by default, and its content can be inspected under the directory `/ldata`.
You can also create a link to `/ldata` in your home directory for easier access with the following command:
```bash theme={null}
ln -s /ldata /root
```
## Common Use Cases
### 1. Use Latch Data FUSE to view the content of S3 buckets on Latch
To access data in your organization's AWS S3 bucket inside a Pod, it is recommended that you:
1. **Mount your AWS S3 buckets on [Latch Data](https://console.latch.bio)**: To mount your S3 buckets on Latch Data, please visit our guide [here](../data/mount-s3-bucket).
2. **Mount Latch Data inside your Latch Pod**: Launch Latch Pod which will automatically mount Latch Data FUSE.
### 2. Copy Data from Pod to Latch Data
To copy data from your Pod to Latch Data, you can use the following command:
```bash theme={null}
cp -r local_folder /ldata/s3_folder
```
Uploaded data will appear inside of your Latch Data on the console.
Latch Data FUSE write speed is much slower than using `latch cp local_folder latch:///s3_folder`. If you are trying to copy large amount of data to Latch Data, see [below](#2-use-latch-cp-for-swift-file-copy-between-local-and-s3-buckets-on-latch-data)
### 3. Accessing Latch Data from JupyterLab or RStudio
Latch Data FUSE is accessible from JupyterLab and RStudio. You can access your data in Latch Data from JupyterLab or RStudio by navigating to `/ldata` in the file browser.
### 4. Accessing Latch Data using Python Script
You can also access Latch Data from Python scripts using the `os` module. For example, to list all files in a directory and to read a file in Latch Data, you can use the following code snippet:
```python theme={null}
import os
# List all files in a directory
files = os.listdir('/ldata')
print(files)
# Read a file
with open('/ldata/file.txt', 'r') as f:
print(f.read())
```
## Best Practices
### 1. Copy frequently used folders to a local directory inside Pods
Latch Data FUSE only displays a mirror of the file system on Latch Data, and does not download every file and folder by default.
Folder child metadata is downloaded when upon attempting to access the folder programmatically or by double-clicking within the RStudio/JupyterLab interface.
Initial access to a folder might incur brief delays due to metadata downloading.
After this, the folder's contents are cached, ensuring instantaneous access for subsequent reads.
When a Pod shuts down, all cache is purged. For large folders that need to be accessed frequently,
it is advisable to copy the folder from `/ldata` to a local scratch directory inside your Pod.
To efficiently copy large folders from `/ldata` to a local directory, see the next section on `latch cp`.
### 2. Use `latch cp` for swift file copy between local and S3 buckets on Latch Data
For efficient file transfers between local directories within Pods and S3 buckets mounted on Latch Data,
it is recommended to use `latch cp` command to ensure optimal copying speed.
After S3 buckets are mounted to Latch Data, `latch cp` can be used for copying
files and directories to any Latch location, including mounted S3 buckets.
For a comprehensive guide on how to copy data between Latch Data and Pods, please visit the documentation [here](../pods/data-transfer).
If you `latch cp` a local directory that has the same folder name as a folder inside your S3 bucket on Latch Data, `latch cp` will overwrite that folder in your Latch Data. If this behavior is undesirable, it is recommended that you change the name of your local directory to not overlap with an existing folder in your S3 bucket.
## Known Limitations and Workarounds
* Some operations in Latch Data FUSE are slow. For example, the following commands are known to be slow:
```bash theme={null}
touch /ldata/new.txt
cp /root/big_folder /ldata/big_folder
mv /root/big_folder /ldata/big_folder
rm -rf /ldata/big_folder
```
**Workaround**:
Use [**latch touch**](/workflows/sdk/cli/commands),
[**latch cp**](/workflows/sdk/cli/commands#latch-cp-\-\),
[**latch mv**](/workflows/sdk/cli/commands#latch-mv-\-\),
[**latch rmr**](/workflows/sdk/cli/commands#latch-rmr-remote_path),
[**latch mkdirp**](/workflows/sdk/cli/commands#latch-mkdirp-remote_directory)
instead if you want to write to Latch Data. Since FUSE is a mirror of Latch Data, all new content written directly to Latch Data will be synced and reflected in `/ldata`.
* `rsync` is not currently supported. The following command will throw an error:
```bash theme={null}
rsync -av /root/scratch /ldata/big_folder
```
**Workaround**: `latch cp` is currently the most effective alternative. However, it's important to note that `latch cp` copies entire directories between local and remote paths every time, instead of transferring only the differences.
* Latch Data FUSE doesn't always refresh when a new file or folder is uploaded to Latch Data via `latch cp` or via the interface on console.latch.bio/data.
**Workaround**: To get the most up-to-date content for `/ldata`, you can: (1) write a fake new file to `/ldata` (e.g. `touch /ldata/new.txt`), which will trigger a refresh; (2) restart your Pod, which will restart the mount for FUSE; or (3) restart the Ldata FUSE mount with:
```bash theme={null}
systemctl restart latch-ldata-fuse.service
```
## Troubleshooting
* If you don't see Latch Data mounted at `/ldata` or there's no data in that directory try re-mounting the filesystem with
```bash theme={null}
systemctl restart latch-ldata-fuse.service
```
## Planned Improvements
1. Support `latch rsync` to only copy the content differences between local directories and remote Latch directories.
2. Make reading and writing faster for Latch Data FUSE
3. Fix inconsistent refresh behavior of Latch Data FUSE
# What are Latch Pods?
Source: https://wiki.latch.bio/pods/overview
Access the scale of the cloud with the flexibility of your personal computer.
Pods are virtual computing environments that allow you to run analysis tools like Jupyter Labs and RStudio with resource requirements (GPU, CPUs, RAM) of your choice in the browser using data stored on Latch.
## Key Features
* **Scalable compute and storage:** Get up to 8 GPUs, 93 CPU cores, 1918 GiB RAM, and 16,000 GB of storage.
* **Notebook Environments:** Access familiar notebook environments, such as RStudio and JupyterLab.
}
href="/pods/getting-started"
>
The basics of creating your first Pod.
}
href="/pods/getting-started#set-up-gpus-and-compute"
>
Get access to Nvidia A10G GPUs (up to 8) instantly.
}
href="/pods/mount-data"
>
Use a single command to mount the entire filesystem on Latch Data on Pods.
Customize auto shut off interval to save costs.
Host any apps (RShiny, Dash, Streamlit) on Pods.
Take a snapshot of your pod, create a template, and reuse & share it
across your workspace.
### Integrations
Connect to Pods via SSH access.
Connect local VSCode and PyCharm to Pods via SSH extensions.
Clone private and public GitHub repositories.
# Set up SSH Access
Source: https://wiki.latch.bio/pods/ssh
You may want to set up SSH access for Pod if you want to access Pod from your local terminal or open your favorite IDE, such as Visual Studio Code, inside a Pod.
Pods use public SSH keys to authorize which machine is allowed to connect to Pods.
```bash theme={null}
$ cat ~/.ssh/id_rsa.pub
```
If you receive an error message saying that **id\_rsa.pub** doesn’t exist, it means that your computer doesn’t have a public SSH key.
Generate one using ssh-keygen: `$ ssh-keygen`
Copy the key with: `$ pbcopy < ~/.ssh/id_rsa.pub`
Find [the Developer Settings page here.](https://console.latch.bio/settings/developer)
Make sure that there is no extra line or space at the end of the SSH key.
Latch only authorizes access to users whose public SSH keys are added here. If
you have multiple developers on the team who want to access the same Pod, it
is recommended that you add their keys here. Latch supports up to 50 keys for
each Pod.
You can only SSH into a Pod if it is running.
### Troubleshooting
Below are a few common errors when trying to connect to Pods via SSH access.
```bash theme={null}
kex_exchange_identification: Connection closed by remote host
```
* This means that an error cannot be established between your local computer and Pods.
* Try stopping and starting your Pod to refresh the connection.
You cannot SSH into a Pod when the status of Pod is **Dormant** or **Starting**. You can only establish a connection to the Pod when it is running.
* The error means that the SSH key Pod is authenticating is different from the SSH key on the computer you are trying to connect from. Hence, Pod rejects your connection.
* Double check at the SSH key you have on [Account Settings > Developer](https://console.latch.bio/settings/developer) is the same as the SSH key of the machine you’re trying to connect from.
* If the SSH keys are the same, but you are still unable to connect to Pod via SSH, this may mean that you added your SSH keys to the Developer Settings after the Pod was created. Manually restart your Pod to load in the SSH keys.
# Pod Templates
Source: https://wiki.latch.bio/pods/templates
Pod Templates provide an easy way to take a snapshot of a Pod’s dependencies and files, and save it as a template that is reusable in future Pods for your organization.
## Create a Template
Find the [Applications page here.](https://console.latch.bio/apps)
Selecting **New** will generate a template from the current setup, dependencies, and data on your Pod right now whereas **Select From Backup** allows you to select a previous backup snapshot.
Find the [My Templates page here.](https://console.latch.bio/apps/templates)
## Update a Template
To update a template, follow step 1 to 4 of the section above. You will be prompted to update an existing template.
Select **Update** and assign a new version to the template to publish it.
## Using a Template in a Different workspace
Once a template has been created, it is also possible to use the templates in multiple workspaces that you are a part of.
Select the toggle next to Use Template. You will be prompted to select the workspace you want to open the template in.
# Latch SDK API Reference
Source: https://wiki.latch.bio/reference/sdk
Auto-generated API documentation from source code.
*Generated using: OpenAI/gpt-5-nano-2025-08-07*
## Table of Contents
* **Core SDK**
* [latch.**init**](#latch-init) - Main SDK initialization and imports
* **Workflow Resources**
* [latch.resources.tasks](#latch-resources-tasks) - Task decorators and execution
* [latch.resources.workflow](#latch-resources-workflow) - Workflow definition and execution
* [latch.resources.conditional](#latch-resources-conditional) - Conditional workflow logic
* [latch.resources.map\_tasks](#latch-resources-map-tasks) - Parallel task execution
* [latch.resources.reference\_workflow](#latch-resources-reference-workflow) - Workflow references
* **Data Types**
* [latch.types.**init**](#latch-types-init) - Type system overview
* [latch.types.file](#latch-types-file) - File handling (`LatchFile`, `LatchOutputFile`)
* [latch.types.directory](#latch-types-directory) - Directory handling (`LatchDir`, `LatchOutputDir`)
* [latch.types.metadata](#latch-types-metadata) - Workflow metadata and UI configuration
* [latch.types.glob](#latch-types-glob) - File pattern matching (`file_glob`)
* **Utility Functions**
* [latch.functions.messages](#latch-functions-messages) - Console messaging (`message`)
* [latch.functions.operators](#latch-functions-operators) - Data manipulation operators (deprecated)
* [latch.functions.secrets](#latch-functions-secrets) - Secret management (`get_secret`)
* **Data Management**
* [latch.ldata](#latch-ldata) - Latch Data cloud storage (`LPath`)
## latch.**init**
The Latch SDK is a command line toolchain to define and register serverless workflows with the Latch platform.
This module re-exports a collection of utilities and resources from several submodules. The following names are imported and exposed by this package:
## latch.resources.tasks
Latch tasks are decorators to turn Python functions into workflow 'nodes'.
Each task is containerized, versioned and registered with [Flyte](https://www.union.ai/docs/v1/flyte/user-guide/introduction/) when a
workflow is uploaded to Latch. Containerized tasks are then executed on
arbitrary instances as [Kubernetes Pods](https://kubernetes.io/docs/concepts/workloads/pods/), scheduled using [`flytepropeller`](https://github.com/flyteorg/flytepropeller) under the hood.
The type of instance that the task executes on (eg. number of available
resources, presence of GPU) can be controlled by invoking one of the set of
exported decorators.
```python theme={null}
from latch.resources.tasks import medium_task
@medium_task
def my_task(a: int) -> str:
...
```
### Functions
Below are the functions available in the `tasks` module.
#### `custom_memory_optimized_task(cpu: int, memory: int)`
Description: Deprecated helper returning a custom task configuration with specified CPU and RAM allocations.
**Notes:**
* This function is deprecated and will be removed in a future release.
* It raises a deprecation warning.
**Parameters:**
* `cpu` (int): Number of CPU cores to request
* `memory` (int): Memory in GiB to request
**Returns:**
* A partial Flyte task configured with the specified Pod settings
```python theme={null}
def custom_memory_optimized_task(cpu: int, memory: int):
```
**Example:**
```python theme={null}
from latch.resources.tasks import custom_memory_optimized_task
@custom_memory_optimized_task(cpu=16, memory=128)
def my_task(a: int) -> str:
...
```
#### `custom_task(cpu: Union[Callable, int], memory: Union[Callable, int], *, storage_gib: Union[Callable, int] = 500, timeout: Union[datetime.timedelta, int] = 0, **kwargs)`
Description: Returns a custom task configuration requesting the specified CPU/RAM allocations.
If `cpu`, `memory`, or `storage_gib` are callables, returns a dynamic task configuration using `DynamicTaskConfig` with a small pod config; otherwise, constructs a static `_custom_task_config` Pod.
**Parameters:**
* `cpu` (Union\[Callable, int]): CPU cores to request (integer or callable for dynamic)
* `memory` (Union\[Callable, int]): Memory in GiB to request (integer or callable)
* `storage_gib` (Union\[Callable, int], default 500): Storage in GiB (integer or callable)
* `timeout` (Union\[datetime.timedelta, int], default 0): Timeout for the task
* `**kwargs`: Additional keyword arguments
**Returns:**
* A partial Flyte task configured for either a dynamic or a static custom task
```python theme={null}
def custom_task(
cpu: Union[Callable, int],
memory: Union[Callable, int],
*,
storage_gib: Union[Callable, int] = 500,
timeout: Union[datetime.timedelta, int] = 0,
**kwargs,
):
```
**Example:**
```python theme={null}
from latch.resources.tasks import custom_task
@custom_task(cpu=8, memory=32, storage_gib=200)
def my_task(a: int) -> str:
...
```
#### `lustre_setup_task()`
Description: Returns a partial Flyte task configured for Lustre setup with a Nextflow work directory PVC.
**Parameters:**
* None
**Returns:**
* A partial Flyte task
```python theme={null}
def lustre_setup_task():
```
**Example:**
```python theme={null}
from latch.resources.tasks import lustre_setup_task
@lustre_setup_task()
def setup_workdir(pvc_name: str) -> str:
os.chmod("/nf-workdir", 0o777)
return pvc_name
```
#### `nextflow_runtime_task(cpu: int, memory: int, storage_gib: int = 50)`
Description: Returns a partial Flyte task configured for Nextflow runtime with a shared work directory volume mounted at `/nf-workdir`.
**Parameters:**
* `cpu` (int): CPU cores
* `memory` (int): Memory in GiB
* `storage_gib` (int, default 50): Storage in GiB
**Returns:**
* A partial Flyte task
```python theme={null}
def nextflow_runtime_task(cpu: int, memory: int, storage_gib: int = 50):
```
**Example:**
```python theme={null}
# Full code example: https://github.com/latchbio-nfcore/atacseq/blob/370c45694bca54a89a7cc65902b0fb54747a87b5/wf/entrypoint.py#L98
from latch.resources.tasks import nextflow_runtime_task
@nextflow_runtime_task(cpu=4, memory=16, storage_gib=64)
def nextflow_runtime(
pvc_name: str,
input: LatchFile,
outdir: LatchDir,
fasta: LatchFile,
) -> None:
...
```
#### `g6e_xlarge_task`, `g6e_2xlarge_task`, `g6e_4xlarge_task`, `g6e_8xlarge_task`, `g6e_12xlarge_task`, `g6e_16xlarge_task`, `g6e_24xlarge_task`, `g6e_48xlarge_task`
Partial Flyte tasks configured for specific L40s GPU pod configurations.
**Parameters:**
* None
**Returns:**
* A partial Flyte task for each respective instance type and resources
```python theme={null}
g6e_xlarge_task = functools.partial(
task,
task_config=_get_l40s_pod("g6e-xlarge", cpu=4, memory_gib=32, gpus=1)
)
```
**Example:**
```python theme={null}
from latch.resources.tasks import g6e_xlarge_task
@g6e_xlarge_task
def my_task(a: int) -> str:
...
```
#### `v100_x1_task`, `v100_x4_task`, `v100_x8_task`
Partial Flyte tasks configured for specific V100 GPU pod configurations.
**Parameters:**
* None
**Returns:**
* A partial Flyte task for each respective instance type and resources
```python theme={null}
v100_x1_task = functools.partial(
task,
task_config=_get_v100_pod("v100-x1", cpu=4, memory_gib=48, gpus=1)
)
```
**Example:**
```python theme={null}
from latch.resources.tasks import v100_x1_task
@v100_x1_task
def my_task(a: int) -> str:
...
```
## latch.resources.workflow
This module defines decorators and helpers to convert Python callables into Flyte `PythonFunctionWorkflow` objects. It includes internal utilities for metadata generation and docstring injection, a `workflow` decorator that supports usage with or without arguments, and a `nextflow_workflow` helper for Nextflow-style workflows.
### Functions
#### `workflow()`
Decorator to expose a Python function as a Flyte PythonFunctionWorkflow. Can be used as `@workflow` without arguments or with a `LatchMetadata` argument.
```python theme={null}
def workflow(
metadata: Union[LatchMetadata, Callable],
) -> Union[PythonFunctionWorkflow, Callable]:
```
**Parameters:**
* `metadata` (Union\[LatchMetadata, Callable]): Either a `LatchMetadata` instance or the function to decorate (when used without parentheses)
**Returns:**
* `Union[PythonFunctionWorkflow, Callable]`: A `PythonFunctionWorkflow` if used directly or a decorator if used with arguments
**Example:**
```python theme={null}
from latch.resources.workflow import workflow
@workflow
def add(a: int, b: int) -> int:
return a + b
```
```python theme={null}
from latch.resources.workflow import workflow
from latch.types.directory import LatchDir, LatchOutputDir
from latch.types.metadata import LatchAuthor, LatchMetadata, LatchParameter
metadata = LatchMetadata(
display_name="Target Workflow",
author=LatchAuthor(
name="Your Name",
),
parameters={
"input_directory": LatchParameter(
display_name="Input Directory",
batch_table_column=True, # Show this parameter in batched mode.
),
"output_directory": LatchParameter(
display_name="Output Directory",
batch_table_column=True, # Show this parameter in batched mode.
),
},
)
@workflow(metadata)
def template_workflow(
input_directory: LatchDir, output_directory: LatchOutputDir
) -> LatchOutputDir:
return task(input_directory=input_directory, output_directory=output_directory)
```
#### `nextflow_workflow()`
Decorator to expose a Python function as a Nextflow-style workflow.
```python theme={null}
def nextflow_workflow(
metadata: NextflowMetadata,
) -> Callable[[Callable], PythonFunctionWorkflow]:
```
**Parameters:**
* `metadata` (NextflowMetadata): Metadata for the Nextflow-style workflow
**Returns:**
* `Callable[[Callable], PythonFunctionWorkflow]`: A decorator compatible with `workflow`
**Example:**
```python theme={null}
from latch.resources.workflow import nextflow_workflow
from latch.types.metadata import NextflowMetadata, NextflowParameter
from latch.types.file import LatchFile
from latch.types.directory import LatchDir
from latch.types.metadata import LatchAuthor, NextflowRuntimeResources
generated_parameters = {
"input": NextflowParameter(
type=LatchFile,
display_name="Input",
description="Input file description",
),
...
}
nextflow_metadata = NextflowMetadata(
display_name="nf-core/atacseq",
author=LatchAuthor(
name="nf-core",
),
repository="https://github.com/latchbio-nfcore/atacseq",
parameters=generated_parameters,
runtime_resources=NextflowRuntimeResources(
cpus=4,
memory=8,
storage_gib=100,
),
log_dir=LatchDir("latch:///your_log_dir"),
)
@nextflow_workflow(nextflow_metadata)
def nf_nf_core_atacseq(...) -> LatchOutputDir:
...
return LatchOutputDir("latch:///your_output_dir")
```
## latch.resources.conditional
This module exposes a factory function to create a `ConditionalSection` for conditional execution in workflows. It delegates to `conditional` from `flytekit.core.condition` to create the `ConditionalSection`.
### Functions
#### `create_conditional_section()`
Creates a new conditional section in a workflow, allowing a user to conditionally execute a task based on the value of a task result.
* The conditional sections can be n-ary with as many `elif` clauses as desired.
* Outputs from conditional nodes can be consumed, and outputs from other tasks can be passed to conditional nodes.
* Boolean expressions in the condition use `&` (and) and `|` (or) operators.
* Unary expressions are not allowed. If a task returns a boolean, use built-in truth checks like `result.is_true()` or `result.is_false()`.
**Parameters:**
* `name` (str): The name of the conditional section, to be shown in Latch Console
**Returns:**
* `ConditionalSection`
```python theme={null}
def create_conditional_section(name: str) -> ConditionalSection:
...
```
**Example:**
```python expandable theme={null}
from latch.resources.tasks import small_task
from latch import create_conditional_section
@small_task
def square(n: float) -> float:
"""
**Parameters:**
- `n` (float): Name of the parameter for the task is derived from the name of the input variable, and the type is automatically mapped to Types.Integer
**Returns:**
- `float`: The label for the output is automatically assigned and the type is deduced from the annotation
"""
return n * n
@small_task
def double(n: float) -> float:
"""
**Parameters:**
- `n` (float): Name of the parameter for the task is derived from the name of the input variable and the type is mapped to `Types.Integer`
**Returns:**
- `float`: The label for the output is auto-assigned and the type is deduced from the annotation
"""
return 2 * n
@workflow
def multiplier(my_input: float) -> float:
result_1 = double(n=my_input)
result_2 = (
create_conditional_section("fractions")
.if_((result_1 < 0.0)).then(double(n=result_1))
.elif_((result_1 > 0.0)).then(square(n=result_1))
.else_().fail("Only nonzero values allowed")
)
result_3 = double(n=result_2)
return result_3
```
## latch.resources.map\_tasks
### map\_tasks
A map task lets you run a pod task or a regular task over a list of inputs within a single workflow node. This means you can run thousands of instances of the task without creating a node for every instance, providing valuable performance gains.
Some use cases of map tasks include:
* Several inputs must run through the same code logic
* Multiple data batches need to be processed in parallel
* Hyperparameter optimization
**Parameters:**
* `task_function`: The task to be mapped, to be shown in Latch Console
**Returns:**
* A conditional section
**Intended Use:**
```python theme={null}
from latch.resources.tasks import small_task, map_task
from latch.resources.workflow import workflow
@small_task
def a_mappable_task(a: int) -> str:
inc = a + 2
stringified = str(inc)
return stringified
@small_task
def coalesce(b: typing.List[str]) -> str:
coalesced = "".join(b)
return coalesced
@workflow
def my_map_workflow(a: typing.List[int]) -> str:
mapped_out = map_task(a_mappable_task)(a=a)
coalesced = coalesce(b=mapped_out)
return coalesced
```
## latch.resources.reference\_workflow
This module defines `workflow_reference` to create a Flyte Launch Plan reference using the current workspace as the project and the domain set to `'development'`. It imports `reference_launch_plan` from `flytekit.core.launch_plan` and `current_workspace` from `latch.utils`.
### Functions
#### `workflow_reference()`
Returns a Flyte Launch Plan reference for the given `name` and `version` in the current workspace under domain `'development'`.
**Parameters:**
* `name` (str): The name of the launch plan to reference
* `version` (str): The version of the launch plan to reference
**Returns:**
* The value returned by `reference_launch_plan` configured with:
* `project=current_workspace()`
* `domain="development"`
* `name=name`
* `version=version`
```python theme={null}
def workflow_reference(
name: str,
version: str,
):
return reference_launch_plan(
project=current_workspace(),
domain="development",
name=name,
version=version,
)
```
### Examples
```python theme={null}
from reference_workflow import workflow_reference
lp = workflow_reference(name="my_workflow", version="v1")
```
## latch.types.**init**
Latch types package initializer. This module re-exports several type definitions and a utility function from submodules under `latch.types`. The available exports are:
* `LatchDir`
* `LatchOutputDir`
* `LatchFile`
* `LatchOutputFile`
* `file_glob`
* `DockerMetadata`
* `Fork`
* `ForkBranch`
* `LatchAppearanceType`
* `LatchAuthor`
* `LatchMetadata`
* `LatchParameter`
* `LatchRule`
* `Params`
* `Section`
* `Spoiler`
* `Text`
### Functions
#### `file_glob()`
Constructs a list of LatchFiles from a glob pattern.
Convenient utility for passing collections of files between tasks. See [nextflow's channels](https://www.nextflow.io/docs/latest/channel.html) or [snakemake's wildcards](https://snakemake.readthedocs.io/en/stable/snakefiles/rules.html#wildcards) for similar functionality in other orchestration tools.
The remote location of each constructed LatchFile will be constructed by appending the file name returned by the pattern to the directory represented by the `remote_directory`.
```python theme={null}
def file_glob(
pattern: str,
remote_directory: str,
target_dir: Optional[Path] = None
) -> List[LatchFile]:
```
**Parameters:**
* `pattern` (str): A glob pattern to match a set of files, e.g. `'*.py'`. Will resolve paths with respect to the working directory of the caller.
* `remote_directory` (str): A valid latch URL pointing to a directory, e.g. `latch:///foo`. This *must* be a directory and not a file.
* `target_dir` (Optional\[Path]): An optional Path object to define an alternate working directory for path resolution.
**Returns:**
* `List[LatchFile]`: A list of instantiated LatchFile objects.
\***\*Example:\*\***
```python theme={null}
@small_task
def process_fastq_files():
# Get all .fastq.gz files from the current directory
# and map them to a remote directory
fastq_files = file_glob("*.fastq.gz", "latch:///fastqc_outputs")
for fastq_file in fastq_files:
# Process each file
process_file(fastq_file)
return fastq_files
```
### Classes
This module re-exports the following classes from their respective submodules. For detailed documentation, see the individual module sections:
* **`LatchDir`** - See [latch.types.directory](#latch-types-directory)
* **`LatchOutputDir`** - See [latch.types.directory](#latch-types-directory)
* **`LatchFile`** - See [latch.types.file](#latch-types-file)
* **`LatchOutputFile`** - See [latch.types.file](#latch-types-file)
* **`DockerMetadata`** - See [latch.types.metadata](#latch-types-metadata)
* **`Fork`** - See [latch.types.metadata](#latch-types-metadata)
* **`ForkBranch`** - See [latch.types.metadata](#latch-types-metadata)
* **`LatchAppearanceType`** - See [latch.types.metadata](#latch-types-metadata)
* **`LatchAuthor`** - See [latch.types.metadata](#latch-types-metadata)
* **`LatchMetadata`** - See [latch.types.metadata](#latch-types-metadata)
* **`LatchParameter`** - See [latch.types.metadata](#latch-types-metadata)
* **`LatchRule`** - See [latch.types.metadata](#latch-types-metadata)
* **`Params`** - See [latch.types.metadata](#latch-types-metadata)
* **`Section`** - See [latch.types.metadata](#latch-types-metadata)
* **`Spoiler`** - See [latch.types.metadata](#latch-types-metadata)
* **`Text`** - See [latch.types.metadata](#latch-types-metadata)
## latch.types.file
Latch types for file handling within Flyte tasks. This module defines a LatchFile class to represent a file object with both a local path and an optional remote path, a type alias for an output file, and a transformer that converts between LatchFile instances and Flyte Literals.
**Notes:**
* `LatchOutputFile` is a type alias for `LatchFile` annotated as an output in Flyte. It is defined as:
`Annotated[LatchFile, FlyteAnnotation({"output": True})]`
### Classes
Other notable methods and properties
* `size(self) -> int`
Returns the size of the remote data via `LPath(self.remote_path).size()`.
* `local_path` (property) -> `str`
Local file path for the environment executing the task.
* `remote_path` (property) -> `Optional[str]`
Remote URL referencing the object (LatchData or S3).
Code example (basic usage)
```python theme={null}
# Basic usage: create a LatchFile with a local path
lf = LatchFile("./my_file.txt")
# With a remote path
lf_remote = LatchFile("./my_file.txt", "latch:///remote_path.txt")
```
## latch.types.directory
Module for directory handling in Latch workflows and standalone Python environments. Provides `LatchDir` for working with directories that can be stored locally or remotely (on Latch Data or S3).
### Classes
#### `LatchDir`
Represents a directory with both local and remote path management.
**Constructor:**
```python theme={null}
def __init__(
self,
path: Union[str, PathLike],
remote_path: Optional[PathLike] = None,
**kwargs,
) -> None:
```
**Parameters:**
* `path` (Union\[str, PathLike]): The local path to the directory
* `remote_path` (Optional\[PathLike]): The remote path (latch:// or s3:// URL) where the directory is stored
**Properties:**
* `local_path` (str): Local directory path for the environment executing the task
* `remote_path` (Optional\[str]): Remote URL referencing the directory (LatchData or S3)
**Methods:**
* `iterdir() -> List[Union[LatchFile, LatchDir]]`: Returns a list of the directory's children (files and subdirectories)
* `size_recursive() -> int`: Returns the total size of the directory and all its contents recursively
**Usage Examples:**
```python expandable theme={null}
from latch.types.directory import LatchDir
from pathlib import Path
# Create a local directory
local_dir = LatchDir("./my_directory")
# Create a directory with remote path
remote_dir = LatchDir("./my_directory", "latch:///remote_directory")
# In a workflow task
@small_task
def process_directory(input_dir: LatchDir) -> LatchDir:
# Access local path
local_path = Path(input_dir.local_path)
# List directory contents
for item in input_dir.iterdir():
if isinstance(item, LatchFile):
print(f"Found file: {item}")
elif isinstance(item, LatchDir):
print(f"Found subdirectory: {item}")
# Get directory size
total_size = input_dir.size_recursive()
print(f"Directory size: {total_size} bytes")
# Create output directory
return LatchDir("./output", "latch:///output_directory")
# In a Jupyter notebook or standalone script
def explore_remote_directory():
# Create a LatchDir pointing to a remote directory
remote_dir = LatchDir("latch:///my_data")
# List contents of the remote directory
for item in remote_dir.iterdir():
print(f"Item: {item}")
if hasattr(item, 'remote_path'):
print(f" Remote path: {item.remote_path}")
# Get directory size
total_size = remote_dir.size_recursive()
print(f"Total directory size: {total_size} bytes")
```
#### `LatchOutputDir`
A `LatchDir` tagged as the output of some workflow.
**Definition:**
```python theme={null}
LatchOutputDir = Annotated[LatchDir, FlyteAnnotation({"output": True})]
```
**Purpose:** The Latch Console uses this metadata to avoid checking for existence of the directory at its remote path and displaying an error. This check is normally made to avoid launching workflows with `LatchDir`s that point to objects that don't exist.
**Usage:**
```python theme={null}
from latch.types.directory import LatchDir, LatchOutputDir
@small_task
def create_output() -> LatchOutputDir:
return LatchDir("./results", "latch:///my_workflow_output")
```
## latch.types.metadata
Module for defining workflow metadata, parameter configurations, and UI flow elements. It provides the building blocks for creating rich, interactive workflow interfaces in the Latch Console, including parameter validation, custom UI layouts, and integration with Snakemake/Nextflow workflows.
### Functions
#### `default_samplesheet_constructor(samples: List[DC], t: DC, delim: str = ",") -> Path`
Creates a CSV samplesheet from a list of dataclass instances.
**Parameters:**
* `samples` (List\[DC]): List of dataclass instances to convert to CSV
* `t` (DC): The dataclass type to use for column headers
* `delim` (str): CSV delimiter, defaults to ","
**Returns:**
* `Path`: Path to the created `samplesheet.csv` file
\***\*Example:\*\***
```python theme={null}
from dataclasses import dataclass
from latch.types.metadata import default_samplesheet_constructor
@dataclass
class SampleData:
sample_id: str
condition: str
replicate: int
# Create sample data
samples = [
SampleData("sample1", "control", 1),
SampleData("sample2", "treatment", 1),
SampleData("sample3", "control", 2),
]
# Generate samplesheet
csv_path = default_samplesheet_constructor(samples, t=SampleData)
print(f"Created samplesheet at: {csv_path}")
```
***
### Classes
#### `LatchRule`
Defines validation rules for parameter inputs using regular expressions.
**Attributes:**
* `regex` (str): Regular expression pattern that inputs must match
* `message` (str): Error message displayed when validation fails
\***\*Example:\*\***
```python theme={null}
from latch.types.metadata import LatchRule
# Validate email format
email_rule = LatchRule(
regex=r"^[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}$",
message="Please enter a valid email address"
)
# Validate file extension
fastq_rule = LatchRule(
regex=r"\.(fastq|fq)(\.gz)?$",
message="File must be a FASTQ file (.fastq, .fq, .fastq.gz, or .fq.gz)"
)
```
#### `LatchAppearanceEnum`
Controls how text input fields are rendered in the UI.
**Values:**
* `line`: Single-line text input
* `paragraph`: Multi-line text area
\***\*Example:\*\***
```python theme={null}
from latch.types.metadata import LatchAppearanceEnum
# Single line input for short text
short_input = LatchAppearanceEnum.line
# Multi-line input for longer text
long_input = LatchAppearanceEnum.paragraph
```
#### `MultiselectOption`
Represents a single option in a multiselect widget.
**Attributes:**
* `name` (str): Display name shown in the UI
* `value` (object): Value associated with this option
#### `Multiselect`
Creates a multiselect input widget with predefined options.
**Attributes:**
* `options` (List\[MultiselectOption]): List of available options
* `allow_custom` (bool): Whether users can enter custom values
\***\*Example:\*\***
```python theme={null}
from latch.types.metadata import Multiselect, MultiselectOption
# Create multiselect for organism selection
organism_multiselect = Multiselect(
options=[
MultiselectOption("Human", "homo_sapiens"),
MultiselectOption("Mouse", "mus_musculus"),
MultiselectOption("Drosophila", "drosophila_melanogaster"),
],
allow_custom=True # Allow users to enter custom organism names
)
```
#### `LatchAuthor`
Contains metadata about the workflow author.
**Attributes:**
* `name` (Optional\[str]): Author's name
* `email` (Optional\[str]): Author's email address
* `github` (Optional\[str]): Link to author's GitHub profile
\***\*Example:\*\***
```python theme={null}
from latch.types.metadata import LatchAuthor
author = LatchAuthor(
name="Dr. Jane Smith",
email="jane.smith@university.edu",
github="https://github.com/janesmith"
)
```
### UI Flow Elements
These classes define the layout and organization of workflow parameters in the Latch Console UI.
#### `FlowBase`
Base class for all UI flow elements. This is a frozen dataclass that serves as the foundation for organizing workflow interfaces.
#### `Section`
Creates a card with a title containing child flow elements.
**Constructor:**
```python theme={null}
Section(section: str, *flow: FlowBase)
```
**Parameters:**
* `section` (str): Title displayed on the section card
* `*flow` (FlowBase): Variable number of flow elements to display in the section
#### `Text`
Displays markdown-formatted text in the UI.
**Attributes:**
* `text` (str): Markdown content to display
#### `Title`
Displays a markdown title in the UI.
**Attributes:**
* `title` (str): Markdown title text
#### `Params`
Displays parameter input widgets for specified parameters.
**Constructor:**
```python theme={null}
Params(*args: str)
```
**Parameters:**
* `*args` (str): Names of parameters to display
#### `Spoiler`
Creates a collapsible section with a title and child flow elements.
**Constructor:**
```python theme={null}
Spoiler(spoiler: str, *flow: FlowBase)
```
**Parameters:**
* `spoiler` (str): Title of the collapsible section
* `*flow` (FlowBase): Flow elements to display when expanded
\***\*Example:\*\***
```python theme={null}
from latch.types.metadata import Section, Text, Params, Spoiler
# Create a workflow UI flow
flow = [
Text("## RNA-seq Analysis Workflow"),
Text("This workflow performs differential gene expression analysis."),
Section("Input Parameters",
Params("input_files", "reference_genome"),
Text("Select your input FASTQ files and reference genome.")
),
Section("Analysis Options",
Params("min_reads", "p_value_threshold"),
Spoiler("Advanced Options",
Params("threads", "memory_limit"),
Text("Configure advanced computational parameters.")
)
)
]
```
#### `ForkBranch`
Defines a single branch within a Fork element.
**Constructor:**
```python theme={null}
ForkBranch(display_name: str, *flow: FlowBase)
```
**Parameters:**
* `display_name` (str): Text displayed on the branch button
* `*flow` (FlowBase): Flow elements to display when this branch is active
#### `Fork`
Creates a conditional UI flow where users can select between mutually exclusive options.
**Constructor:**
```python theme={null}
Fork(fork: str, display_name: str, **flows: ForkBranch)
```
**Parameters:**
* `fork` (str): Name of the string parameter that stores the selected branch key
* `display_name` (str): Title shown above the fork selector
* `**flows` (ForkBranch): Named branches, where keys become the parameter values
\***\*Example:\*\***
```python theme={null}
from latch.types.metadata import Fork, ForkBranch, Params, Text
# Create conditional analysis options
analysis_fork = Fork(
fork="analysis_type",
display_name="Analysis Type",
differential=ForkBranch(
"Differential Expression",
Params("p_value_threshold", "fold_change_threshold"),
Text("Configure parameters for differential expression analysis.")
),
pathway=ForkBranch(
"Pathway Analysis",
Params("pathway_database", "enrichment_method"),
Text("Configure parameters for pathway enrichment analysis.")
)
)
```
### Core Metadata Classes
#### `LatchParameter`
Defines metadata and behavior for workflow parameters in the Latch Console UI.
**Key Attributes:**
* `display_name` (Optional\[str]): Human-readable name for the parameter
* `description` (Optional\[str]): Help text describing the parameter
* `hidden` (bool): Whether to hide the parameter by default
* `placeholder` (Optional\[str]): Placeholder text in input fields
* `output` (bool): Whether this parameter represents a workflow output
* `rules` (List\[LatchRule]): Validation rules for the parameter
* `appearance_type` (LatchAppearance): How to render the input (line/paragraph/multiselect)
**Samplesheet Integration:**
* `samplesheet` (Optional\[bool]): Enable samplesheet input UI
* `allowed_tables` (Optional\[List\[int]]): Registry table IDs allowed for samplesheet
\***\*Example:\*\***
```python theme={null}
from latch.types.metadata import LatchParameter, LatchRule, LatchAppearanceEnum
# Basic parameter
input_file_param = LatchParameter(
display_name="Input FASTQ Files",
description="Select your input FASTQ files for analysis",
placeholder="Choose files...",
rules=[
LatchRule(
regex=r"\.(fastq|fq)(\.gz)?$",
message="Please select FASTQ files"
)
]
)
# Samplesheet parameter
sample_param = LatchParameter(
display_name="Sample Information",
description="Upload a samplesheet with sample metadata",
samplesheet=True,
allowed_tables=[123, 456] # Specific registry table IDs
)
# Text parameter with validation
email_param = LatchParameter(
display_name="Email Address",
description="Your email for notifications",
appearance_type=LatchAppearanceEnum.line,
rules=[
LatchRule(
regex=r"^[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}$",
message="Please enter a valid email address"
)
]
)
```
#### `LatchMetadata`
The main class for defining workflow metadata and UI configuration.
**Core Attributes:**
* `display_name` (str): Human-readable workflow name
* `author` (LatchAuthor): Workflow author information
* `documentation` (Optional\[str]): Link to workflow documentation
* `repository` (Optional\[str]): Link to source code repository
* `license` (str): SPDX license identifier
* `parameters` (Dict\[str, LatchParameter]): Parameter definitions
* `flow` (List\[FlowBase]): UI layout configuration
**Additional Metadata:**
* `tags` (List\[str]): Categorization tags
* `wiki_url` (Optional\[str]): Link to wiki documentation
* `video_tutorial` (Optional\[str]): Link to tutorial video
* `about_page_path` (Optional\[Path]): Path to markdown about page
\***\*Example:\*\***
```python theme={null}
from latch.types.metadata import (
LatchMetadata, LatchAuthor, LatchParameter,
Section, Text, Params
)
# Define workflow metadata
metadata = LatchMetadata(
display_name="RNA-seq Differential Expression Analysis",
author=LatchAuthor(
name="Dr. Jane Smith",
email="jane.smith@university.edu",
github="https://github.com/janesmith"
),
documentation="https://docs.example.com/rnaseq-workflow",
repository="https://github.com/janesmith/rnaseq-workflow",
license="MIT",
tags=["RNA-seq", "differential-expression", "bioinformatics"],
# Define parameters
parameters={
"input_files": LatchParameter(
display_name="Input FASTQ Files",
description="Select your input FASTQ files"
),
"reference_genome": LatchParameter(
display_name="Reference Genome",
description="Choose a reference genome"
),
"p_value_threshold": LatchParameter(
display_name="P-value Threshold",
description="Statistical significance threshold",
placeholder="0.05"
)
},
# Define UI layout
flow=[
Text("## RNA-seq Analysis Workflow"),
Text("This workflow performs differential gene expression analysis using DESeq2."),
Section("Input Data",
Params("input_files", "reference_genome"),
Text("Select your input files and reference genome.")
),
Section("Analysis Parameters",
Params("p_value_threshold"),
Text("Configure statistical parameters for the analysis.")
)
]
)
```
### Integration Metadata Classes
#### `DockerMetadata`
Configuration for private Docker repositories.
**Attributes:**
* `username` (str): Docker registry username
* `secret_name` (str): Name of the secret containing the password
#### `SnakemakeMetadata(LatchMetadata)`
Extended metadata class for Snakemake workflows with additional Snakemake-specific configuration.
**Additional Attributes:**
* `output_dir` (Optional\[LatchDir]): Directory for Snakemake outputs
* `docker_metadata` (Optional\[DockerMetadata]): Docker registry credentials
* `cores` (int): Number of cores for Snakemake execution
* `parameters` (Dict\[str, SnakemakeParameter]): Snakemake-specific parameter metadata
#### `NextflowMetadata(LatchMetadata)`
Extended metadata class for Nextflow workflows with additional Nextflow-specific configuration.
**Additional Attributes:**
* `runtime_resources` (NextflowRuntimeResources): Computational resources
* `execution_profiles` (List\[str]): Nextflow execution profiles
* `log_dir` (Optional\[LatchDir]): Directory for Nextflow logs
* `parameters` (Dict\[str, NextflowParameter]): Nextflow-specific parameter metadata
### Helper Classes
#### `SnakemakeParameter(Generic[T], LatchParameter)`
Snakemake-specific parameter with type information and default values.
#### `NextflowParameter(Generic[T], LatchParameter)`
Nextflow-specific parameter with samplesheet integration and results path configuration.
#### `NextflowRuntimeResources`
Defines computational resources for Nextflow tasks.
**Attributes:**
* `cpus` (Optional\[int]): Number of CPUs
* `memory` (Optional\[int]): Memory in GiB
* `storage_gib` (Optional\[int]): Storage in GiB
* `storage_expiration_hours` (int): Workdir retention time
## latch.types.glob
Module for creating collections of `LatchFile` objects from glob patterns. This is useful for batch processing files and passing file collections between workflow tasks.
### Functions
#### `file_glob()`
Creates a list of `LatchFile` objects by matching files with a glob pattern and mapping them to a remote directory.
**Signature:**
```python theme={null}
def file_glob(
pattern: str,
remote_directory: str,
target_dir: Optional[Path] = None
) -> List[LatchFile]:
```
**Parameters:**
* `pattern` (str): Glob pattern to match files (e.g., `"*.fastq.gz"`, `"data/*.csv"`)
* `remote_directory` (str): Latch URL pointing to a directory (e.g., `"latch:///my_data"`)
* `target_dir` (Optional\[Path]): Alternative working directory for pattern resolution
**Returns:**
* `List[LatchFile]`: List of `LatchFile` objects with local paths matching the pattern and remote paths in the specified directory
**Examples:**
```python theme={null}
from latch.types.glob import file_glob
from pathlib import Path
# Basic usage - match all FASTQ files in current directory
fastq_files = file_glob("*.fastq.gz", "latch:///rnaseq_inputs")
# Match files in subdirectories
all_csv_files = file_glob("data/**/*.csv", "latch:///processed_data")
# Use custom working directory
custom_files = file_glob(
"*.bam",
"latch:///alignment_outputs",
target_dir=Path("/path/to/working/dir")
)
# Process multiple file types
@small_task
def process_sequencing_files():
# Get all sequencing files
fastq_files = file_glob("*.fastq.gz", "latch:///raw_data")
bam_files = file_glob("*.bam", "latch:///alignments")
# Process each file
for file in fastq_files + bam_files:
process_file(file)
return fastq_files + bam_files
```
**Notes:**
* The `remote_directory` must be a valid Latch URL pointing to a directory (not a file)
* If the remote directory URL is invalid, an empty list is returned
* Each matched file gets a remote path constructed by appending the filename to the remote directory
* This is particularly useful for workflows that need to process multiple files of the same type
## latch.functions.messages
Module for displaying messages to users during workflow execution. These messages appear prominently in the Latch Console and help communicate task status, warnings, and errors to users.
### Functions
#### `message(typ: str, data: Dict[str, Any]) -> None`
Displays a message in the Latch Console during task execution. Messages are shown on the task execution page and help users understand what's happening or if there are issues.
**Parameters:**
* `typ` (str): Message type determining display style. Options:
* `"info"`: Informational messages (blue styling)
* `"warning"`: Warning messages (yellow/orange styling)
* `"error"`: Error messages (red styling)
* `data` (Dict\[str, Any]): Message content with required keys:
* `"title"` (str): Brief message title
* `"body"` (str): Detailed message content
**Returns:**
* `None`
**Raises:**
* `RuntimeError`: If message processing fails
**Examples:**
```python expandable theme={null}
from latch.functions.messages import message
@small_task
def process_samples(input_file: LatchFile) -> str:
# Info message - task progress
message("info", {
"title": "Processing Started",
"body": f"Analyzing {input_file} with 1000 samples"
})
try:
# Process the file
result = analyze_file(input_file)
# Success message
message("info", {
"title": "Analysis Complete",
"body": f"Successfully processed {len(result)} samples"
})
return result
except ValueError as e:
# Error message with helpful guidance
message("error", {
"title": "Invalid File Format",
"body": f"Expected CSV format with columns: sample_id, condition, replicate. Error: {str(e)}"
})
raise
except FileNotFoundError:
# Warning message
message("warning", {
"title": "File Not Found",
"body": "Input file could not be located. Please check the file path and try again."
})
raise
@small_task
def validate_parameters(threshold: float) -> bool:
if threshold < 0 or threshold > 1:
message("error", {
"title": "Invalid Parameter Value",
"body": f"Threshold must be between 0 and 1, got {threshold}. Please adjust your input."
})
return False
if threshold > 0.05:
message("warning", {
"title": "High Threshold Warning",
"body": f"Threshold of {threshold} is quite high. Consider using a lower value (e.g., 0.05) for more sensitive results."
})
return True
```
## latch.functions.operators
**⚠️ DEPRECATED** - This module is deprecated and may be removed in future versions.
This module provides utilities for data manipulation operations inspired by Nextflow channel operators. It includes functions for dictionary joins, tuple grouping, filtering, and Cartesian products.
### Functions
#### `left_join(left: Dict[str, Any], right: Dict[str, Any]) -> Dict[str, Any]`
Performs a left join on two dictionaries, keeping all keys from the left dictionary.
**Parameters:**
* `left` (Dict\[str, Any]): Left dictionary (all keys preserved)
* `right` (Dict\[str, Any]): Right dictionary (matched keys only)
**Returns:**
* `Dict[str, Any]`: Dictionary with all left keys, combined with right values where keys match
\***\*Example:\*\***
```python theme={null}
left = {"a": 1, "b": 2, "c": 3}
right = {"b": 20, "c": 30, "d": 40}
result = left_join(left, right)
# Result: {"a": 1, "b": [2, 20], "c": [3, 30]}
```
#### `right_join(left: Dict[str, Any], right: Dict[str, Any]) -> Dict[str, Any]`
Performs a right join on two dictionaries, keeping all keys from the right dictionary.
**Parameters:**
* `left` (Dict\[str, Any]): Left dictionary (matched keys only)
* `right` (Dict\[str, Any]): Right dictionary (all keys preserved)
**Returns:**
* `Dict[str, Any]`: Dictionary with all right keys, combined with left values where keys match
\***\*Example:\*\***
```python theme={null}
left = {"a": 1, "b": 2, "c": 3}
right = {"b": 20, "c": 30, "d": 40}
result = right_join(left, right)
# Result: {"b": [2, 20], "c": [3, 30], "d": 40}
```
#### `inner_join(left: Dict[str, Any], right: Dict[str, Any]) -> Dict[str, Any]`
Performs an inner join on two dictionaries, keeping only keys present in both dictionaries.
**Parameters:**
* `left` (Dict\[str, Any]): Left dictionary
* `right` (Dict\[str, Any]): Right dictionary
**Returns:**
* `Dict[str, Any]`: Dictionary containing only keys present in both inputs, with combined values
\***\*Example:\*\***
```python theme={null}
left = {"a": 1, "b": 2, "c": 3}
right = {"b": 20, "c": 30, "d": 40}
result = inner_join(left, right)
# Result: {"b": [2, 20], "c": [3, 30]}
```
#### `outer_join(left: Dict[str, Any], right: Dict[str, Any]) -> Dict[str, Any]`
Performs an outer join on two dictionaries, keeping all keys from both dictionaries.
**Parameters:**
* `left` (Dict\[str, Any]): Left dictionary
* `right` (Dict\[str, Any]): Right dictionary
**Returns:**
* `Dict[str, Any]`: Dictionary containing all keys from both inputs, with combined values where keys match
\***\*Example:\*\***
```python theme={null}
left = {"a": 1, "b": 2, "c": 3}
right = {"b": 20, "c": 30, "d": 40}
result = outer_join(left, right)
# Result: {"a": 1, "b": [2, 20], "c": [3, 30], "d": 40}
```
#### `group_tuple(channel: List[Tuple], key_index: Optional[int] = None) -> List[Tuple]`
Groups tuples by a specified key index, mimicking Nextflow's `groupTuple` operator.
**Parameters:**
* `channel` (List\[Tuple]): List of tuples to group
* `key_index` (Optional\[int]): Index to group by (defaults to 0)
**Returns:**
* `List[Tuple]`: List of grouped tuples, one per distinct key
\***\*Example:\*\***
```python theme={null}
channel = [(1, 'A'), (1, 'B'), (2, 'C'), (3, 'B'), (1, 'C'), (2, 'A'), (3, 'D')]
result = group_tuple(channel) # Group by first element (index 0)
# Result: [(1, ['A', 'B', 'C']), (2, ['C', 'A']), (3, ['B', 'D'])]
# Group by second element (index 1)
result2 = group_tuple(channel, key_index=1)
# Result: [('A', [1, 2]), ('B', [1, 3]), ('C', [2, 1]), ('D', [3])]
```
#### `latch_filter(channel: List[Any], predicate: Union[Callable, re.Pattern, type, None]) -> List[Any]`
Filters a list using a predicate function, regex pattern, or type check.
**Parameters:**
* `channel` (List\[Any]): List to filter
* `predicate` (Union\[Callable, re.Pattern, type, None]): Filter criteria:
* `Callable`: Function that returns True/False for each item
* `re.Pattern`: Regex pattern to match against strings
* `type`: Type to filter by (e.g., `str`, `int`)
* `None`: Returns original list unchanged
**Returns:**
* `List[Any]`: Filtered list based on the predicate
**Examples:**
```python theme={null}
import re
# Filter by function
numbers = [1, 2, 3, 4, 5, 6]
evens = latch_filter(numbers, lambda x: x % 2 == 0)
# Result: [2, 4, 6]
# Filter by regex pattern
strings = ["hello", "world", "test123", "abc"]
pattern = re.compile(r'\d')
with_numbers = latch_filter(strings, pattern)
# Result: ["test123"]
# Filter by type
mixed = [1, "hello", 2.5, "world", 3]
strings_only = latch_filter(mixed, str)
# Result: ["hello", "world"]
```
#### `combine(channel_0: List[Any], channel_1: List[Any], by: Optional[int] = None) -> Union[List, Dict[str, List[Any]]]`
Creates a Cartesian product of two lists, with optional grouping by a tuple index.
**Parameters:**
* `channel_0` (List\[Any]): First list to combine
* `channel_1` (List\[Any]): Second list to combine
* `by` (Optional\[int]): If provided, group tuples by this index before combining
**Returns:**
* `Union[List, Dict[str, List[Any]]]`:
* If `by` is None: List of tuples representing the Cartesian product
* If `by` is provided: Dictionary with grouped products
**Examples:**
```python theme={null}
# Basic Cartesian product
c0 = ['hello', 'ciao']
c1 = [1, 2, 3]
result = combine(c0, c1)
# Result: [('hello', 1), ('hello', 2), ('hello', 3), ('ciao', 1), ('ciao', 2), ('ciao', 3)]
# With grouping by tuple index
c0_tuples = [('A', 1), ('A', 2), ('B', 3)]
c1_tuples = [('A', 'x'), ('A', 'y'), ('B', 'z')]
result = combine(c0_tuples, c1_tuples, by=0) # Group by first element
# Result: {
# 'A': [('A', 1, 'A', 'x'), ('A', 1, 'A', 'y'), ('A', 2, 'A', 'x'), ('A', 2, 'A', 'y')],
# 'B': [('B', 3, 'B', 'z')]
# }
```
**Note:** When using `by`, all elements in both lists must be tuples of the same length.
## latch.functions.secrets
Module for securely retrieving secrets stored in Latch workspaces. Secrets are encrypted values that can be used to store sensitive information like API keys, database passwords, or authentication tokens.
### Functions
#### `get_secret(secret_name: str) -> str`
Retrieves a secret value from the Latch workspace.
**Parameters:**
* `secret_name` (str): Name of the secret to retrieve
**Returns:**
* `str`: The decrypted secret value
**Examples:**
```python expandable theme={null}
from latch.functions.secrets import get_secret
@small_task
def process_with_api_key() -> str:
# Retrieve API key from secrets
api_key = get_secret("my-api-key")
# Use the API key for authentication
response = make_api_call(api_key)
return response
```
## latch.ldata
Module for working with Latch Data (LData) - Latch's cloud storage system. This module provides the `LPath` class for interacting with files and directories stored in Latch Data, including operations like uploading, downloading, copying, and metadata retrieval.
### Classes
#### `LPath`
Represents a remote file or directory path hosted on Latch Data. Provides a pathlib-like interface for working with cloud storage.
**Constructor:**
```python theme={null}
LPath(path: str)
```
**Parameters:**
* `path` (str): The Latch path, must start with "latch://"
**Key Features:**
* **Lazy Loading**: Metadata is fetched on-demand to minimize network requests
* **Caching**: Metadata is cached after first fetch for improved performance
* **Path Operations**: Supports path joining with `/` operator
* **File/Directory Operations**: Upload, download, copy, delete, and directory listing
* **Metadata Access**: Get file size, content type, version ID, and node information
**Properties and Methods:**
**Metadata Methods:**
* `fetch_metadata()`: Force refresh of all cached metadata
* `node_id(load_if_missing=True)`: Get the unique node ID
* `name(load_if_missing=True)`: Get the file/directory name
* `type(load_if_missing=True)`: Get the node type (file, directory, etc.)
* `size(load_if_missing=True)`: Get file size in bytes
* `size_recursive(load_if_missing=True)`: Get total size including subdirectories
* `content_type(load_if_missing=True)`: Get MIME content type
* `version_id(load_if_missing=True)`: Get version identifier
* `is_dir(load_if_missing=True)`: Check if path is a directory
* `exists(load_if_missing=True)`: Check if path exists
**Directory Operations:**
* `iterdir()`: List contents of directory (non-recursive)
* `mkdirp()`: Create directory and all parent directories
* `rmr()`: Recursively delete files and directories
**File Operations:**
* `upload_from(src: Path, show_progress_bar=False)`: Upload local file/directory
* `download(dst=None, show_progress_bar=False, cache=False)`: Download to local path
* `copy_to(dst: LPath)`: Copy to another LPath
**Path Operations:**
* `__truediv__(other)`: Join paths using `/` operator
**Examples:**
```python expandable theme={null}
from latch.ldata import LPath
from pathlib import Path
# Create LPath instances
data_dir = LPath("latch:///my_workspace/data")
input_file = LPath("latch:///my_workspace/inputs/sample.fastq")
output_dir = LPath("latch:///my_workspace/results")
# Check if paths exist and get metadata
if data_dir.is_dir():
print(f"Directory size: {data_dir.size_recursive()} bytes")
# List directory contents
for item in data_dir.iterdir():
print(f"{item.name()}: {item.type()}")
# Upload local files
local_file = Path("local_data.csv")
data_dir.upload_from(local_file)
# Download files
downloaded_path = input_file.download()
print(f"Downloaded to: {downloaded_path}")
# Copy between Latch paths
backup_file = LPath("latch:///my_workspace/backups/sample.fastq")
input_file.copy_to(backup_file)
# Create directories
new_dir = LPath("latch:///my_workspace/new_analysis")
new_dir.mkdirp()
# Path joining
results_file = output_dir / "analysis_results.txt"
print(f"Full path: {results_file.path}")
# Workflow integration
@small_task
def process_data(input_path: LPath) -> LPath:
# Download input
local_input = input_path.download()
# Process the file
result = analyze_file(local_input)
# Upload result
output_path = LPath("latch:///my_workspace/results/processed.txt")
output_path.upload_from(Path(result))
return output_path
# Batch operations
@small_task
def batch_upload(input_dir: Path) -> List[LPath]:
uploaded_paths = []
for file_path in input_dir.glob("*.csv"):
# Create corresponding LPath
latch_path = LPath(f"latch:///my_workspace/data/{file_path.name}")
# Upload file
latch_path.upload_from(file_path)
uploaded_paths.append(latch_path)
return uploaded_paths
```
**Error Handling:**
```python theme={null}
from latch.ldata import LPath, LatchPathError
try:
# This will raise LatchPathError if path doesn't exist
file_path = LPath("latch:///nonexistent/file.txt")
size = file_path.size()
except LatchPathError as e:
print(f"Path error: {e}")
print(f"Remote path: {e.remote_path}")
print(f"Account ID: {e.acc_id}")
```
**Best Practices:**
* Use `load_if_missing=False` when you know metadata is already cached
* Call `fetch_metadata()` to refresh stale cache when needed
* Use `cache=True` in `download()` for repeated downloads of the same file
* Handle `LatchPathError` for robust error handling
* Use path joining with `/` operator for cleaner code
* Check `is_dir()` before calling directory-specific methods
#### `LatchPathError`
Exception raised when LPath operations fail.
**Attributes:**
* `message` (str): Error description
* `remote_path` (Optional\[str]): The Latch path that caused the error
* `acc_id` (Optional\[str]): Account ID associated with the error
#### `LDataNodeType`
Enum representing different types of Latch Data nodes.
**Values:**
* `account_root`: Root directory of an account
* `dir`: Regular directory
* `obj`: File object
* `mount`: Mounted storage
* `link`: Symbolic link
* `mount_gcp`: Google Cloud Platform mount
* `mount_azure`: Azure mount
\***\*Example:\*\***
```python theme={null}
from latch.ldata import LPath, LDataNodeType
path = LPath("latch:///my_workspace/data")
node_type = path.type()
if node_type == LDataNodeType.dir:
print("This is a directory")
elif node_type == LDataNodeType.obj:
print("This is a file")
```
# Bulk Import Data Using a CSV
Source: https://wiki.latch.bio/registry/add-records-to-a-table/bulk-link
Alternatively, you can easily use an existing CSV that you have locally to populate the table in Registry. To do so, you can click on the “Import” button and choose “Import CSV”.
As an exercise, we will use the [metadata sheet](https://docs.google.com/spreadsheets/d/1i3HdGhWC4P7RYlmswxnE6LjcfAroSx61PQR20q6mCZM/edit?usp=sharing) from Yost et. al (2019) here.
Note that Registry CSV import only supports **.csv** at the moment. If you
have an Excel file (.xls, .xlsx) or text file (.txt), please make sure to save
them as a CSV first.
Select “Upload Files” to upload the metadata sheet downloaded in the previous step.
New tables only have one default existing column, which is “Name”. Let’s change the mapped column for the “Sample Name” (in the original CSV) to “Name” (in the Registry).
As an exercise, we can change the type of the columns “organism\_name” and “Strandedness” to “Select”.
Once the import finishes, you will see your Registry table populated like so.
**Pro-tip:** If you want to import a CSV with new columns and one of the
columns contains values that match record names in the Registry, the columns
and their values will be linked with those records automatically.
# Bulk Link Sequencing Files to Existing Records
Source: https://wiki.latch.bio/registry/add-records-to-a-table/import-data
A viewer of your files on Latch will be displayed.
Latch automatically looks through the files provided and infers the sample name and associated files based on the common structure of samples — one or more technical replicates per sample, each with either single end or paired end reads.
For example, the files `/test-data-sc-rna-seq-tcr-yost-et-al-1680568204.353618/SRR8315738/su002_pre_All_RNA_S1_L001_R1_001.fastq.gz and /test-data-sc-rna-seq-tcr-yost-et-al-1680568204.353618/SRR8315738/su002_pre_All_RNA_S1_L001_R2_001.fastq.gz` have the sample names `su002_pre_All_RNA_S1` as that is the common prefix between both files.
To do so, we can click on “Custom”.
The original file name will be split by characters to give you a list of word chunks that you can concatenate to create the custom sample name.
Click “**View Results**” to see the custom sample names.
Because there are no existing columns to choose from, let’s create a new column “**Reads**”.
Click “**Import**” to start importing reads. A new column called “**Reads**” will be created and populated with the read files if they exist on Latch.
**Pro-tip:** Record names are helpful for linking data to particular records. If
you have sequencing files and their names match existing record names, you can
associate them with those records in bulk.
# Manually Create Single Records
Source: https://wiki.latch.bio/registry/add-records-to-a-table/single-records
A record with the name “Record 0” will be created. You can change the record names to anything you like, as long as record names are unique within the table.
You will see a dropdown menu of different types that you can assign to the column.
For example, here we are creating a column called “Sequencing Read”. The cells within the column are required to be files on Latch and end with the file extension fastq.gz. The cell can also contain multiple files.
# Benchling Integration
Source: https://wiki.latch.bio/registry/benchling-sync
Latch Registry allows you to perform a one-way sync to bring entities from [Benchling Registry](https://www.benchling.com/resources/benchling-registry-product-sheet) and [Benchling Inventory](https://www.benchling.com/resources/benchling-inventory-product-sheet) to Latch Registry as tables.
Once Benchling data is transformed into table forms on Latch, you can:
* Easily search, sort, filter, and join data across tables.
* Directly sync sequences from Benchling Protein entities, for example, and kick-start hundreds of AlphaFold2 for protein prediction or DNA Chisel for codon optimization.
This document walks through the process of setting up the Benchling one-way data sync to the Latch Registry.
The list of currently supported Benchling schemas are Custom Entities, DNA Sequences, AA Sequences, Mixtures, DNA Oligos, RNA Oligos, Molecules, and Plates.
## Setup Benchling Sync
The integration works by using your Benchling developer API key.
In [Latch Console](https://console.latch.bio/settings/developer), go to Workspace Settings > Developer, and click on `Benchling`.
Follow the official [Benchling tutorial](https://help.benchling.com/hc/en-us/articles/9714802977805-Access-the-Benchling-Developer-Platform#h_2962600be3) to get your personal user API key.
Ex. `sk_example_key`.
Include the full tenant URL including `https://`.
To find the tenant URL, log into your Benchling account or organization and copy the URL in the address bar as indicated in the image below.
Ex. `https://latch.benchling.com/`.
## Syncing Data Using Benchling Sync
After successfully adding your Benchling credentials to Latch, you can go to the Latch Registry and sync your Benchling data to a new project on Latch.
Only one-way sync from Benchling to Latch is supported at the moment.
These schemas will be synced into the tables under the project that you have selected in step 4. If the entity schema you selected links to other schemas, the related schemas will be automatically selected for an sync as well. This is to ensure the parent-child relationships in Benchling are also propagated to Latch Registry tables.
## (Optional) Enable Automatic Sync
If this option is enabled, your data will be automatically synced from Benchling to Latch every 30 minutes.
Depending on the size and the amount of schemas that you are syncing, this might take a couple of minutes. Please keep the tab with the sync open. If you need to use the rest of the platform, please open a new tab and go to the Console page there.
# Connect Records Across Tables
Source: https://wiki.latch.bio/registry/connect-records-across-tables
As you centralize your biological data in Latch Registry, you will often find that some records are related or even dependent on one another. Linked records offer a powerful way for you to define relationships between records from different tables, enhancing your data analysis and enabling new insights that may have been difficult to discover without linked records.
## What are linked records?
Linked records allow you to capture relationships between records from different tables.
Let’s explore how linked records can be used to navigate complex relationships between tables via a biological example.
For instance, in a study aiming to identify how the immune system responds to a specific disease or treatment at the single-cell level, researchers would collect samples from multiple patients. These samples would undergo single-cell sequencing and TCR sequencing to analyze genetic and transcriptomic profiles of individual immune cells and track the clonal expansion and diversity of T cells, respectively. By monitoring changes in the immune response over time in patients with multiple samples, researchers can gain insights into disease pathology and potential therapeutic targets.
The diagram above outlines how the experiments and their data can be represented in Latch Registry. We have a Gene Expression Library table and TCR Library that contain results from 10X Cell Ranger V(D)J and Cell Ranger Count pipeline, respectively. These libraries are linked to raw sequencing reads from the Sequencing Reads table.
## When should I create linked records?
Linked records are used in a project when there is a one-to-many relationship between two tables.
For example, imagine you are conducting a study where you extract multiple blood samples per patient for analysis. A patient can have many blood samples, but each sample can only belong to one patient.
In this scenario, you would create two tables: one for patients and one for blood samples, with a link between them based on the sample ID.
If you have a situation where there is a one-to-one relationship between two tables, it might make more sense to keep everything in one table. For example, each patient can only have one name, so you might consider keeping all of that information in a single table.
## Create Linked Records
As an example, we have a table called “Patients”, and we want to link records from the “Samples” to specify which samples belong to which patient.
The Target Table is a table whose records we want to link. Here, let’s select the table Samples as the reference table.
The linkage enables easy navigation between records that are interdependent on each other.
# Registry Basics
Source: https://wiki.latch.bio/registry/create-a-project
Learn how to set up your registry to manage your data.
## 1. Create your first project
### Discover optimal antibody candidates through multiple rounds of phage display assays.
To identify the most suitable antibody candidates, scientists may employ several rounds of phage display assays. To facilitate this, we can create a table consisting of SRA IDs and their corresponding FastQ files in Latch Registry. Each biological sample is accompanied by information regarding the selection method employed for the phage display assay, as well as the experimental conditions. Following data acquisition, this table can be incorporated into a Latch workflow to derive enrichment scores for diverse antibody sequences
### Explore top differentially expressed genes using public transcriptomics studies.
In this project, we imported several transcriptomics studies using bulk RNA-sequencing to identify differentially expressed genes and pathways across a range of biological conditions.
Now that you’ve explored what projects are, let’s create our first project! To do so, simply click on the “New Project” button on the top left.
## 2. Create a Table
A table is a collection of records. Each record, also known as a row, contains a unique record name and a set of attributes.
For example, the table IBD Study below contains different sample names, conditions, and sequencing reads.
To create a table, click on the project in which the table will be created. Here, we select “Bulk RNA-seq Analysis”. Then, click the plus sign to create a new table.
Enter your table name, and choose “Create”.
A new table will be created under your chosen project.
## 3. Add Records to a Table
You can add records manually, link existing files within latch, import data with a CSV, or sync data from Benchling.
## 4. Modify Records in a Table
There are multiple ways you can modify record(s) in a registry table:
1. [Edit a single cell value at once](/registry/create-a-project#edit-a-single-cell-value-at-a-time)
2. [Edit a multiple cell values at once](/registry/create-a-project#edit-multiple-cell-values-at-once)
### Edit a single cell value at a time
Similar to a spreadsheet interface, you can double click on each cell and assign it to a new value.
Alternatively, you can check the box next to the record you want to modify. The sidebar will display attributes associated with that record and provide an easy way where you can edit.
### Edit multiple cell values at once
If you want to assign the same value to multiple cells at once, you can bulk select multiple records, and change the attribute value using the sidebar.
# Account Objects
Source: https://wiki.latch.bio/registry/sdk/account-objects
An `Account` object describes an account on Latch. An `Account` can be instantiated either using the class method `Account.current()` (recommended), or directly using its ID.
```python theme={null}
from latch.account import Account
acc = Account.curent()
```
When calling `Account.current()`, the returned `Account` object is different depending on the context in which it is run:
* When running in an execution, the returned `Account` corresponds to the workspace in which the execution was run. This means that if User A runs an execution in Workspace B, the returned `Account` is for Team B.
* When running inside a Pod or Plot notebooik, the returned `Account` corresponds to the workspace in which the Pod or Plot notebook lives.
* When running outside of an execution, in e.g. `latch develop`, the returned `Account` corresponds to the setting of `latch workspace` at calling time, defaulting to the user if no setting is found.
`Account`s are lazy, in that they don't perform any network requests without an explicit call to `Account.load()` or to a property getter.
## Instance Methods
The only non-getter method on an `Account` is `Account.load()`. This method, if called, will perform a network request and cache values for each of the `Account`'s properties.
### Property Getters
All property getters have an optional `load_if_missing` boolean argument which, if `True`, will call `Account.load()` if the requested property has not been loaded already. This defaults to `True`.
* `Account.list_registry_projects()` will return a list of `Project` objects, each correspondng to a project within the calling `Account`.
```python theme={null}
from latch.account import Account, Project
# Get the current account and list all projects
account = Account.current()
projects = account.list_registry_projects()
print(projects)
```
```bash Outputs theme={null}
[Project(id=123, display_name="Project A"), Project(id=456, display_name="Project B")]
```
### Updater
A `Account` can be modified by using the `Account.update()` function. `Account.update()` returns a context manager (and hence must be called using `with` syntax) with the following methods:
* `upsert_project(name: str)` will create a project with name `name`.
```python theme={null}
with account.update() as updater:
updater.upsert_registry_project("New Project")
```
* `delete_project(id: str)` will delete the project with id `id`. If no such project exists, the method call will be a noop.
```python theme={null}
with account.update() as updater:
updater.delete_registry_project("")
```
# Overview
Source: https://wiki.latch.bio/registry/sdk/latch-sdk-registry-integration
Classes and utility methods for interacting with [Latch Registry](/registry/what-is-a-registry) are provided out of the box in the Latch SDK.
These are used during workflow execution to read from and write values to Tables in Registry.
Among others, classes for `Accounts`, `Projects`, `Tables`, and `Records` are provided.
## Structure
Just like its web counterpart, this API is designed hierarchically, so that `Account`s can list their constituent `Project`s, `Project`s can list their constituent `Table`s, and `Table`s can list their constituent `Records`.
Each of these can also be instantiated directly by their ID, providing that the workspace in which the execution is running has access to them.
For more detailed documentation about all of these classes' behavior/methods, see their respective pages.
## Usage Example
The following is a typical example of usage.
```python theme={null}
import os
from pathlib import Path
from latch.registry.table import Table
from latch.resources.tasks import small_task
from latch.types.file import LatchFile
@small_task
def registry_task(record_name: str, file: LatchFile) -> LatchFile:
file_path = Path(file.local_path)
file_size = os.stat(file_path).st_size
tbl = Table(id="1234")
with tbl.update() as updater:
updater.upsert_record(
name=record_name,
File=file,
Size=file_size
)
return file
```
Inside a task, a `Table` object is instantiated with id `"1234"` and a record with name `record_name` in this table is updated (or inserted if necessary) with the provided column values.
# Record Objects
Source: https://wiki.latch.bio/registry/sdk/record-objects
A `Record` object describes a Registry Record, and can be created either from an `Table` via `Table.list_records()` or directly using its ID.
`Record`s are lazy, in that they don't perform any network requests without an explicit call to `Record.load()` or to a property getter.
## Instance Methods
The only non-getter method on a `Record` is `Record.load()`. This method, if called, will perform a network request and cache values for each of the `Record`'s properties.
### Property Getters
All property getters have an optional `load_if_missing` boolean argument which, if `True`, will call `Record.load()` if the requested property has not been loaded already. This defaults to `True`.
* `Record.get_name()` will return the `name` of the calling `Record` as a string.
* `Record.get_values()` will return a dictionary of the calling `Record`'s values. The keys of the dictionary are strings and must be valid column keys of the calling `Record`'s containing `Table`. The values of the dictionary can either be valid python values, or the special values `EmptyCell` or `InvalidValue`.
* `Record.get_creation_time()` will return a datetime object corresponding to when the Record was created.
* `Record.get_last_updated()` will return a datetime object corresponding to when the Record was last modified.
# Registry Projects
Source: https://wiki.latch.bio/registry/sdk/registry-projects
A `Project` object describes a Registry Project, and can be created either from an `Account` via `Account.list_projects()` or directly using its ID.
```python Via an Account theme={null}
from latch.account import Account, Project
# Get the current account and list all projects
account = Account.current()
projects = account.list_registry_projects()
print(projects)
# Outputs
# [Project(id=123, display_name="Project A"), Project(id=456, display_name="Project B")]
```
```python Via the project ID theme={null}
from latch.account import Project
project = Project("12345")
```
`Project`s are lazy, in that they don't perform any network requests without an explicit call to `Project.load()` or to a property getter.
## Instance Methods
The only non-getter method on a `Project` is `Project.load()`. This method, if called, will perform a network request and cache values for each of the `Project`'s properties.
### Property Getters
All property getters have an optional `load_if_missing` boolean argument which, if `True`, will call `Project.load()` if the requested property has not been loaded already. This defaults to `True`.
* `Project.get_display_name()` will return the `display_name` of the calling `Project` as a string.
* `Project.list_tables()` will return a list of `Table` objects, each corresponding to a table within the calling `Project`.
### Updater
A `Project` can be modified by using the `Project.update()` function. `Project.update()` returns a context manager (and hence must be called using `with` syntax) with the following methods:
* `upsert_table(name: str)` will create a table with name `name`.
```python theme={null}
with project.update() as updater:
updater.upsert_table("New Table")
```
* `delete_table(id: str)` will delete the table with id `id`. If no such table exists, the method call will be a noop.
```python theme={null}
with project.update() as updater:
updater.delete_table("")
```
# Table Objects
Source: https://wiki.latch.bio/registry/sdk/table-objects
`Table` objects describe Registry Tables. A `Table` object can either be instantiated via a call to `Project.list_tables()` or directly using its ID.
```python Using Project theme={null}
from latch.account import Project
project = Project("12345")
tables = project.list_tables()
# Outputs
# [Table(id=123, display_name="Table A"), Table(id=456, display_name="Table B")]
```
```python Using the table ID theme={null}
from latch.registry.table import Table
table = Table("1234")
```
`Table`s are for the most part lazy, in that they don't perform any network requests without an explicit call to `Table.load()` or to a property getter. Two exceptions to this are `Table.list_records()` and `Table.update()`, both of which are discussed below.
## Instance Methods
* `Table.load()`, if called, will perform a network request and cache values for each of the `Table`'s properties.
* `Table.list_records()` will return a generator that yields a paginated dictionary of `Record`s that are present in the calling `Table`. The keys of this dictionary are Record IDs and the values are the corresponding `Record` objects. This function also takes an optional keyword-only `page_size` argument that dictates the size of the returned page. The value of this argument must be a postive integer. If not provided, the default is a page size of 100. Pages are ordered by Record ID, with lower IDs being yielded first.
An example of typical usage of `Table.list_records()` is below.
```python theme={null}
from latch.registry.table import Table
tbl = Table(id="1234")
for page in tbl.list_records():
for record_id, record in page.items():
# do stuff with the Record `record`.
...
```
Unlike the rest of this API, `Table.list_records()` will always perform a network request for each returned page.
### Property Getters
All property getters have an optional `load_if_missing` boolean argument which, if `True`, will call `Account.load()` if the requested property has not been loaded already. This defaults to `True`.
* `Table.get_display_name()` will return the `display_name` of the calling `Table` as a string
* `Table.get_columns()` will return a dictionary containing the columns of the calling `Table`. The keys of the dictionary are column names, and its values are `Column` objects. `Column` is a convenience dataclass with the properties
* `Column.key`: the key of the column.
* `Column.type`: the (python) type of the column.
* `Column.upstream_type`: similar to `Column.type`. However, this is a dataclass which contains an internal representation of the column's data type, and should not be accessed or modified directly.
### Updater
A `Table` can be modified by using the `Table.update()` function. `Table.update()` returns a context manager (and hence must be called using `with` syntax) with the following methods:
#### Upsert a record
* `upsert_record(record_name: str, column_data: Dict[str, Any])` will either (up)date or in(sert) a record with name `record_name` with the column values prescribed in `column_data`.
Each key of `column_data` must be a valid column key (meaning that **there must be a column in the calling `Table` with the same key**), and the value corresponding to that key **must be same type as the column** (meaning that it is an instance of the column's (python) type).
```python theme={null}
# Example: Updating a record to have a new Latch directory under the column cellrager_output
from latch.types import LatchDir
with table.update() as updater:
updater.upsert_record(
"",
cellranger_output=LatchDir("latch://12345.account/cellranger_count_output")
)
```
```python theme={null}
# If your column name contains spaces
from latch.types import LatchDir
with table.update() as updater:
updater.upsert_record(
"",
**{"Output Directory": LatchDir("latch://12345.account/cellranger_count_output")}
)
```
#### Delete a record
* `delete_record(name: str)` will delete the record with name `name`. If no such record exists, the method call will be a noop.
```python theme={null}
with table.update() as updater:
updater.delete_record("")
```
#### Upsert a column
* `upsert_column(key: str, type: RegistryPythonType, *, required: bool = False)` will create a column with key `key` and type `type`. For now, updating column types (i.e. calling `upsert_column` with a key that already exists, and a type that differs from the type of the column) is not allowed, and attempting to do so will raise an exception.
### Export to `pandas`
A `Table` can be exported as a `pandas.DataFrame` using the `Table.get_dataframe()` function. This requires `pandas` to be installed. Doing so will load the entire table from the network into memory, so it can be costly for larger tables.
```python3 theme={null}
>>> t = Table(id=345)
>>> t.get_dataframe()
experiment_accession ... total_size total_spots Name
0 SRX17527395 ... 383793732 12300558 SRR21524988
1 SRX17527394 ... 414766909 13238380 SRR21524989
2 SRX17527393 ... 406432082 13029979 SRR21524990
3 SRX17527392 ... 445083594 14249689 SRR21524991
4 SRX17527391 ... 392081937 12545386 SRR21524992
5 SRX17527390 ... 438156525 14020607 SRR21524993
6 SRX17527389 ... 434284549 13945947 SRR21524994
7 SRX17527388 ... 450489579 14452049 SRR21524995
8 SRX17527387 ... 404992915 12876927 SRR21524996
[9 rows x 24 columns]
```
### Planned Methods (Not Implemented Yet)
* `delete_column(column_name: str)`
The following is an example for how to update a `Table`.
```python theme={null}
from latch.registry.table import Table
t = Table(id="1234")
with t.update() as updater:
updater.upsert_record(
name="record 1",
Size=10
)
updater.upsert_record(
name="record 2",
Size=15
)
```
The code above will upsert two records, called `record 1` and `record 2`, with the provided values for the column `Size`.
When using an updater, no network requests are made until the end of the `with` block. This mimics transactions in relational database systems, and has several similar behaviors, namely that
* If any exception is thrown inside the `with` block, none of the updates made inside the `with` block will be sent over the network, so no changes will be made to the `Table`.
* All updates are made at once in a single network request at the end of the `with` block. This significantly boosts performance when a large amount of updates are made at once.
# What is Latch Registry?
Source: https://wiki.latch.bio/registry/what-is-a-registry
Connect your sample sheets, metadata, and analysis — all in one place.
Latch Registry is a flexible sample management system for cross-functional wet and dry lab teams. Through a familiar spreadsheet interface, scientists can link sequencing files to contextual metadata collected in a lab. Computational biologists can easily bring samples and metadata into bioinformatics workflows on Latch.
## Get Started
Learn about projects, tables, and how to use them.
Add records manually, link files, import CSVs, or sync data from Benchling.
Define relationships between records from different tables.
Use our Python framework to upload custom bioinformatics pipelines for an auto generated user interface on Latch.
## The Anatomy of Latch Registry
The Registry consists of Projects and Tables which can be edited, filtered, and nagivated.
## Who is Latch Registry for?
Latch Registry is the source of truth that enables reliable, reproducible, and shareable computational analysis that is accessible to everyone on the team – from biologists, to bioinformaticians, to executives.
* An intuitive spreadsheet interface to input experimental metadata and autolink them with sequencing files.
* Effortless import of data in bulk via CSV file uploads.
* A streamlined process for searching and filtering bioinformatics results and sequencing files next to experimental metadata from the lab.
* Programmatic access to manipulate data in Registry.
* Batch execution of Registry samples through bioinformatics workflows.
* Automatic population of workflow outputs into Registry.
* A single place to track all your files, metadata, and analyses, so that you never incorrectly enter information or lose files again.
* Quickly search and filter top candidates for a drug discovery campaign, and audit past decisions with ease.
# Frequently Asked Questions
Source: https://wiki.latch.bio/resources/faq
## What is your data policy?
All data is secure & private. Latch is SOC 2 Type II compliant. Our team, software, and procedures demonstrated best-in-class security and data privacy practices during a three-month independent audit, including penetration tests. Learn more at our [Trust Center](https://trust.latch.bio).
## What if I'm running into an error?
Please report it using the intercom button the bottom left. We will be responsive on intercom from 9am to 9pm PST every day of the week.
If it's really bad, feel free to tweet at us [@latchbio](https://twitter.com/LatchBio).
## How do I report a bug?
Please report it using the intercom button the bottom left. We will be responsive on intercom from 9am to 9pm PST every day of the week.
Or tweet at us [@latchbio](https://twitter.com/LatchBio).
## How do I request features or changes?
You can make a request through intercom, email any of the founders ([kyle@latch.bio](mailto:kyle@latch.bio) or [alfredo@latch.bio](mailto:alfredo@latch.bio)) or send us a tweet.
# Latch Privacy Policy
Source: https://wiki.latch.bio/resources/privacy-policy
This Privacy Policy describes how Latch Bio, Inc. (“we”, “us”, “our”, or the “Company”) handles personal information that we collect through our digital properties that link to this Privacy Policy, including our website (collectively, the “Service”), as well as through social media, our marketing activities, and other activities described in this Privacy Policy.
*Effective as of May 13, 2026.*
## What We *Don't* Do With Your Data
* **No Ownership:** Your data, code, and analyses remain solely yours.
* **No Monetization:** We never sell or monetize your data.
* **No Model Training:** Your data isn't used to train machine learning models.
* **No Business Influence:** Your data doesn't inform our decisions, except for helping you debug and give you the best customer service.
* **Purely Hosting:** We are a hosting platform and interact with your data only for that purpose.
## Privacy Policy
LatchBio, Inc. ("LatchBio," "we," "us" or "our") provides data analysis solutions for biotechnology research and development. This Privacy Policy describes how LatchBio processes personal information that we collect through our digital or online properties or services that link to this Privacy Policy (including, as applicable, our website, platform and social media pages) as well as our marketing and other activities described in this Privacy Policy (collectively, the "Service"). LatchBio may provide additional or supplemental privacy policies to individuals for specific products or services that we offer at the time we collect personal information.
This Privacy Policy does not apply to information that we process on behalf of enterprise customers while providing the LatchBio services to them if we have entered into a separate customer agreement with you that contains data processing terms that override the terms of this privacy policy. If you have questions regarding your personal information that we process on behalf of an enterprise customer, please direct your questions to that customer.
**European Users:** Please see the 'Notice to European Users' section below for additional information for individuals located in the European Economic Area or the United Kingdom (which we refer to as "Europe," and "European" should be understood accordingly).
## Index
* [Personal information we collect](#personal-information-we-collect)
* [Tracking & other technologies](#tracking--other-technologies)
* [How we use your personal information](#how-we-use-your-personal-information)
* [How we share your personal information](#how-we-share-your-personal-information)
* [Your choices](#your-choices)
* [Other sites and services](#other-sites-and-services)
* [Security](#security)
* [International data transfer](#international-data-transfer)
* [Children](#children)
* [Changes to this Privacy Policy](#changes-to-this-privacy-policy)
* [How to contact us](#how-to-contact-us)
* [Notice to European Users](#notice-to-european-users)
* [Dispute Resolution and Binding Arbitration](#dispute-resolution-and-binding-arbitration)
## Personal information we collect
**Information you provide to us.** Personal information you may provide to us through the Service or otherwise includes:
* **Contact data**, such as your first and last name, salutation, email address, mailing address, professional title and company name, and phone number.
* **Demographic data**, such as your city, state, country of residence, and postal code.
* **Communications data** based on our exchanges with you, including when you contact us through the Service, social media, or otherwise.
* **Marketing data**, such as your preferences for receiving our marketing communications and details about your engagement with them.
* **User content data**, such as experimental data that you upload to our platform.
* **Other data** not specifically listed here, which we will use as described in this Privacy Policy or as otherwise disclosed at the time of collection.
**Third-party sources.** We may combine personal information we receive from you with personal information that we obtain from other sources, such as:
* **Public sources**, such as government agencies, public records, and other publicly available sources.
* **Private sources**, such as data providers, social media platforms and data licensors.
* **Marketing partners**, such as joint marketing partners and event co-sponsors.
* **Service providers** that provide services on our behalf or help us operate the Service or our business.
* **Business transaction partners**. We may receive personal information in connection with an actual or prospective business transaction (e.g., a merger, acquisition, sale of assets, or similar transaction, or in the context of an insolvency, bankruptcy, or receivership).
**Automatic data collection.** We, our service providers, and our business partners may automatically log information about you, your computer or mobile device, and your interaction over time with the Service, our communications and other online services, such as:
* **Device data**, such as your computer or mobile device's operating system type and version, manufacturer and model, browser type, screen resolution, RAM and disk size, CPU usage, device type (e.g., phone, tablet), IP address, unique identifiers, language settings, mobile device carrier, radio/network information (e.g., Wi-Fi, LTE, 3G), and general location information such as city, state or geographic area.
* **Online activity data**, such as pages or screens you viewed, content you viewed or otherwise engaged with, how long you spent on a page or screen, the website you visited before browsing to the Service, navigation paths between pages or screens, information about your activity on a page or screen, access times and duration of access, and whether you have opened our emails or clicked links within them.
* **Communication interaction data** such as your interactions with our email, text or other communications (e.g., whether you open and/or forward emails) – we may do this through use of pixel tags (which are also known as clear GIFs), which may be embedded invisibly in our emails.
## Tracking & other technologies
**Cookies and other technologies.** Some of the automatic collection described above is facilitated by the following technologies:
* **Cookies**, which are small text files that websites store on user devices and that allow web servers to record users' web browsing activities and remember their submissions, preferences, and login status as they navigate a site. Cookies used on our sites include both "session cookies" that are deleted when a session ends, "persistent cookies" that remain longer, "first party" cookies that we place and "third party" cookies that our third-party business partners and service providers place.
* **Local storage technologies**, like HTML5, that provide cookie-equivalent functionality but can store larger amounts of data on your device outside of your browser in connection with specific applications.
* **Web beacons**, also known as pixel tags or clear GIFs, which are used to demonstrate that a webpage or email was accessed or opened, or that certain content was viewed or clicked.
## How we use your personal information
We may use your personal information for the following purposes or as otherwise described at the time of collection:
**Service delivery and operations.** We may use your personal information to:
* provide the Service and operate our business;
* enable security features of the Service;
* communicate with you about the Service, including by sending Service-related announcements, updates, security alerts, and support and administrative messages; and
* provide support for the Service, and respond to your requests, questions and feedback.
**Service personalization**, which may include using your personal information to:
* understand your needs and interests;
* personalize your experience with the Service and our Service-related communications; and
* remember your selections and preferences as you navigate webpages.
**Service improvement and analytics.** We may use your personal information to analyze your usage of the Service, improve the Service, improve the rest of our business, help us understand user activity on the Service, including which pages are most and least visited and how visitors move around the Service, as well as user interactions with our emails, and to develop new products and services. For example, we may use LinkedIn Analytics for this purpose.
**Marketing.** We and our service providers may collect and use your personal information for marketing purposes. We may send you direct marketing communications and may personalize these messages based on your needs and interests. You may opt-out of our marketing communications as described in the Opt-out of communications section below.
**Compliance and protection.** We may use your personal information to:
* comply with applicable laws, lawful requests, and legal process, such as to respond to subpoenas, investigations or requests from government authorities;
* protect our, your or others' rights, privacy, safety or property (including by making and defending legal claims);
* audit our internal processes for compliance with legal and contractual requirements or our internal policies;
* enforce the terms and conditions that govern the Service; and
* prevent, identify, investigate and deter fraudulent, harmful, unauthorized, unethical or illegal activity, including cyberattacks and identity theft.
**To create aggregated, de-identified and/or anonymized data.** We may create aggregated, de-identified and/or anonymized data from your personal information and other individuals whose personal information we collect. We may use this data and share it with third parties for our lawful business purposes, including to analyze and improve the Service and promote our business.
## How we share your personal information
We may share your personal information with the following parties (or as otherwise described in this Privacy Policy, in other applicable notices, or at the time of collection).
**Service providers.** Third parties that provide services on our behalf or help us operate the Service or our business (such as hosting, information technology, customer support, email delivery, marketing, consumer research and website analytics).
**Third parties designated by you.** We may share your personal information with third parties where you have instructed us or provided your consent to do so.
**Partners.** Third parties with whom we partner, including parties with whom we co-sponsor events or promotions, with whom we jointly offer products or services, or whose products or services may be of interest to you.
**Professional advisors.** Professional advisors, such as lawyers, auditors, bankers and insurers, where necessary in the course of the professional services that they render to us.
**Authorities and others.** Law enforcement, government authorities, and private parties, as we believe in good faith to be necessary or appropriate for the Compliance and protection purposes described above.
**Business transferees.** We may disclose personal information in the context of actual or prospective business transactions (e.g., investments in or financings of LatchBio, public stock offerings, or the sale, transfer or merger of all or part of our business, assets or shares).
## Your choices
**Opt-out of communications.** You may opt-out of marketing-related emails by following the opt-out or unsubscribe instructions at the bottom of the email, or by contacting us. Please note that if you choose to opt-out of marketing-related emails, you may continue to receive service-related and other non-marketing emails.
**Cookies and other technologies.** Most browsers let you remove or reject cookies. To do this, follow the instructions in your browser settings. Many browsers accept cookies by default until you change your settings. If you set your browser to disable cookies, the Service may not work properly. For more information about cookies, visit [www.allaboutcookies.org](http://www.allaboutcookies.org).
**Do Not Track.** Some Internet browsers may be configured to send "Do Not Track" signals to the online services that you visit. We currently do not respond to "Do Not Track" signals.
**Declining to provide information.** We need to collect personal information to provide certain services. If you do not provide the information we identify as required or mandatory, we may not be able to provide those services.
## Other sites and services
The Service may contain links to websites, mobile applications, and other online services operated by third parties. These links and integrations are not an endorsement of, or representation that we are affiliated with, any third party. We do not control these third parties and are not responsible for their actions. We encourage you to read their privacy policies.
## Security
We employ technical, organizational and physical safeguards designed to protect the personal information we collect. However, security risk is inherent in all internet and information technologies and we cannot guarantee the security of your personal information.
## International data transfer
We are headquartered in the United States and may use service providers that operate in other countries. Your personal information may be transferred to the United States or other locations where privacy laws may not be as protective as those in your state, province, or country. Users in Europe should also read the information provided about transfers of personal information to recipients outside Europe contained in the 'Notice to European Users' below.
## Children
The Service is not intended for use by anyone under 18 years of age. If you are a parent or guardian of a child from whom you believe we have collected personal information in a manner prohibited by law, please contact us. If we learn that we have collected personal information through the Service from a child without the consent of the child's parent or guardian as required by law, we will comply with applicable legal requirements to delete the information.
## Changes to this Privacy Policy
We reserve the right to modify this Privacy Policy at any time. If we make material changes to this Privacy Policy, we will notify you by updating the date of this Privacy Policy and posting it on the Service or other appropriate means. Any modifications to this Privacy Policy will be effective upon our posting the modified version (or as otherwise indicated at the time of posting). In all cases, your use of the Service after the effective date of any modified Privacy Policy indicates your acknowledging that the modified Privacy Policy applies to your interactions with the Service and our business.
## How to contact us
If you have questions about our practices or if you would like to exercise any privacy-related right that may be available to you depending upon applicable law, please contact us.
* **Email:** [compliance@latch.bio](mailto:compliance@latch.bio)
* **Mail:** 185 Berry Street, Suite 1800, San Francisco, CA 94107
## Notice to European Users
### General
**Where this Notice to European Users applies.** The information provided in this 'Notice to European Users' section applies only to individuals located in the European Economic Area (EEA) or the United Kingdom (UK) (i.e., "Europe" as defined at the top of this Privacy Policy).
**Personal information.** References to "personal information" in this Privacy Policy should be understood to include a reference to "personal data" as defined in the GDPR (i.e., the General Data Protection Regulation 2016/679 ("EU GDPR")) and the EU GDPR as it forms part of the laws of the United Kingdom ("UK GDPR"). Under the GDPR, "personal data" means information about individuals from which they are either directly identified or can be identified.
**Controller / Processor roles.** LatchBio acts as a data controller in respect of personal information that it collects directly through its public website, marketing activities, and prospect/customer contact records. LatchBio acts as a data processor in respect of personal information that enterprise customers upload to or process through the LatchBio platform; for that data, LatchBio processes the data only on the documented instructions of the enterprise customer (the controller) under a written data processing agreement, and this Privacy Policy does not apply to such customer-controlled data (please refer to your agreement with the relevant enterprise customer).
**Our GDPR Representatives.** We have appointed the following representatives in Europe as required by the GDPR – you can contact them directly should you wish:
* **Our Representative in the EU:** Dr. Loredana Tassone. Contact: [eurep@grcsolutions.io](mailto:eurep@grcsolutions.io)
* **Our Representative in the UK:** Dr. Loredana Tassone. Contact: [ukrep@grcsolutions.io](mailto:ukrep@grcsolutions.io)
### Our legal bases for processing
In respect of each of the purposes for which we use your personal information, the GDPR requires us to ensure that we have a "legal basis" for that use. Our legal bases for processing your personal information described in this Privacy Policy are listed below.
* **Contractual Necessity.** Where we need to process your personal information in order to deliver the Service to you, or where you have asked us to take specific action which requires us to process your personal information.
* **Legitimate Interests.** Where it is necessary for our legitimate interests and your interests and fundamental rights do not override those interests.
* **Compliance with Law.** Where we need to comply with a legal or regulatory obligation.
* **Consent.** Where we have your specific consent to carry out the processing for the Purpose in question.
We have set out below, in a table format, the legal bases we rely on in respect of the relevant Purposes for which we use your personal information:
| Purpose | Categories of personal information involved | Legal basis |
| ---------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Service delivery and operations | • Contact data • Demographic data • Communications data • User content data • Device data • Online activity data • Communication interaction data | • Contractual Necessity. • Legitimate Interests. We have a legitimate interest in ensuring the ongoing security and proper operation of our Service (including, where relevant, responding to any contact via any "contact us" feature or similar), our business and associated IT services, systems and networks. |
| Service personalization | • Contact data • Demographic data • Communications data • User content data • Device data • Online activity data • Communication interaction data | • Legitimate Interests. We have a legitimate interest in providing you with a good service via the Service, which is personalized to you and that remembers your selections and preferences. • Consent, in respect of any optional processing relevant to personalization (including processing directly associated with any optional cookies used for this purpose). |
| Service improvement and analytics | • Contact data • Demographic data • Communications data • User content data • Device data • Online activity data • Communication interaction data | • Legitimate Interests. We have a legitimate interest in providing you with a good service and analyzing how you use it so that we can improve it over time, as well as developing and growing our business. • Consent, in respect of any optional cookies used for this purpose. |
| Marketing | • Contact data • Demographic data • Communications data • Device data • Online activity data • Communication interaction data | • Legitimate Interests. We have a legitimate interest in promoting our operations and goals as an organization and sending marketing communications for that purpose. • Consent, in circumstances or in jurisdictions where consent is required under applicable data protection laws to the sending of any given marketing communications. |
| Compliance and protection | • Any and all data types relevant in the circumstances | • Compliance with Law. • Legitimate Interests. Where Compliance with Law is not applicable, we have a legitimate interest in participating in, supporting, and following legal process and requests, including through co-operation with authorities. We may also have a legitimate interest of ensuring the protection, maintenance, and enforcement of our rights, property, and/or safety. |
| Data sharing in the context of corporate events | • Any and all data types relevant in the circumstances | • Legitimate Interests. We have a legitimate interest in providing information to relevant third parties who are involved in an actual or prospective corporate event (including to enable them to investigate – and, where relevant, to continue to operate – all or relevant part(s) of our operations). |
| To create aggregated, de-identified and/or anonymized data | • Any and all data types relevant in the circumstances | • Legitimate Interests. We have legitimate interest in taking steps to preserve the privacy of our users. |
| Further uses | • Any and all data types relevant in the circumstances | • The original legal basis relied upon, if the relevant further use is compatible with the initial purpose for which the personal information was collected. • Consent, if the relevant further use is not compatible with the initial purpose for which the personal information was collected. |
### Retention
We retain personal information for as long as necessary to fulfil the purposes for which we collected it, including for the purposes of satisfying any legal, accounting, or reporting requirements, to establish or defend legal claims, or otherwise for the 'Compliance and protection' purposes outlined above. To determine the appropriate retention period for personal information, we consider the amount, nature, and sensitivity of the personal information, the potential risk of harm from unauthorized use or disclosure of your personal information, the purposes for which we process your personal information and whether we can achieve those purposes through other means, and the applicable legal requirements.
When we no longer require the personal information that we have collected about you, we will either delete or anonymize it or, if this is not possible (for example, because your personal information has been stored in backup archives), then we will securely store your personal information and isolate it from any further processing until deletion is possible.
### Other information
**No obligation to provide personal information.** You do not have to provide personal information to us. However, where we need to process your personal information either to comply with applicable law or to deliver our Service to you, and you fail to provide that personal information when requested, we may not be able to provide some or all of our Service to you.
**No sensitive information.** We ask that you not provide us with any sensitive personal information (e.g., social security numbers, information related to racial or ethnic origin, political opinions, religion or other beliefs, health, criminal background or trade union membership, or biometric or genetic characteristics other than as requested by us as part of the Service) on or through the Service, or otherwise to us.
**No automated decision-making and profiling.** As part of the Service, we do not engage in automated decision-making and/or profiling, which produces legal or similarly significant effects.
### Your additional rights
European data protection laws may give you certain rights regarding your personal information in certain circumstances. If you are located in Europe, you may ask the controller to take the following actions in relation to your personal information that we hold:
* **Access.** Provide you with information about our processing of your personal information and give you access to your personal information.
* **Correct.** Update or correct inaccuracies in your personal information.
* **Delete.** Delete your personal information where there is no good reason for us continuing to process it.
* **Transfer.** Transfer to you or a third party of your choice a machine-readable copy of your personal information which you have provided to us.
* **Restrict.** Restrict the processing of your personal information.
* **Object.** Object to our processing of your personal information where we are relying on Legitimate Interests – you also have the right to object where we are processing your personal information for direct marketing purposes.
* **Withdraw Consent.** When we use your personal information based on your consent, you have the right to withdraw that consent at any time.
**Exercising These Rights.** You may submit these requests by contacting us at [compliance@latch.bio](mailto:compliance@latch.bio). We may request specific information from you to help us confirm your identity and process your request. We try to respond to all legitimate requests within a month of receipt.
**Onward Transfers.** If we transfer personal data to a third party acting as our agent, we remain responsible under the EU-U.S. Data Privacy Framework and the UK Extension to the EU-U.S. Data Privacy Framework if that agent processes the data inconsistently with the EU-U.S. DPF Principles, unless we prove we are not responsible for the event giving rise to the damage.
### Dispute Resolution and Binding Arbitration
LatchBio complies with the EU-U.S. Data Privacy Framework (EU-U.S. DPF) and the UK Extension to the EU-U.S. DPF as set forth by the U.S. Department of Commerce. LatchBio has certified to the U.S. Department of Commerce that it adheres to the EU-U.S. Data Privacy Framework Principles (EU-U.S. DPF Principles) with regard to the processing of personal data received from the European Union in reliance on the EU-U.S. DPF and from the United Kingdom (and Gibraltar) in reliance on the UK Extension to the EU-U.S. DPF. If there is any conflict between the terms in this privacy policy and the EU-U.S. DPF Principles, the Principles shall govern.
To learn more about the Data Privacy Framework Program (DPF Program), and to view our certification, please visit [https://www.dataprivacyframework.gov/](https://www.dataprivacyframework.gov/).
Pursuant to the DPF Program, EU and UK individuals have the right to obtain our confirmation of whether we maintain personal information relating to you in the United States. Upon request, we will provide you with access to the personal information that we hold about you. You may also correct, amend, or delete the personal information we hold about you. An individual who seeks access, or who seeks to correct, amend, or delete inaccurate data transferred to the United States in reliance on the DPF Program should direct their query to [compliance@latch.bio](mailto:compliance@latch.bio). If requested to remove data, we will respond within a reasonable timeframe.
We will provide an individual opt-out choice, or opt-in for sensitive data, before we share your data with third parties other than our agents, or before we use it for a purpose other than which it was originally collected or subsequently authorized. To request to limit the use and disclosure of your personal information, please submit a written request to [compliance@latch.bio](mailto:compliance@latch.bio).
In certain situations, we may be required to disclose personal data in response to lawful requests by public authorities, including to meet national security or law enforcement requirements.
In compliance with the EU-U.S. Data Privacy Framework and the UK Extension to the EU-U.S. DPF, LatchBio commits to resolve complaints about our collection or use of personal data. EU and UK individuals with inquiries or complaints regarding our DPF compliance should first contact us at [compliance@latch.bio](mailto:compliance@latch.bio). LatchBio has further committed to refer unresolved privacy complaints to the BBB National Programs Data Privacy Framework Services, an independent dispute-resolution provider located in the United States. If you do not receive timely acknowledgment of your complaint, or if your complaint is not satisfactorily addressed, please visit [https://bbbprograms.org/dpf-complaints](https://bbbprograms.org/dpf-complaints) for more information or to file a complaint. This service is provided free of charge to you.
Under certain limited conditions, you may be entitled to invoke binding arbitration as a "last resort" mechanism if your complaint has not been resolved through these channels. See [https://www.dataprivacyframework.gov/framework-article/ANNEX-I-introduction](https://www.dataprivacyframework.gov/framework-article/ANNEX-I-introduction) for more information on this process.
**Regulatory Oversight.** The Federal Trade Commission has jurisdiction over LatchBio's compliance with the EU-U.S. Data Privacy Framework (EU-U.S. DPF) and the UK Extension to the EU-U.S. DPF.
### Your Right to Lodge a Complaint with your Supervisory Authority
Although we urge you to contact us first to find a solution for any concern you may have, in addition to your rights outlined above, if you are not satisfied with our response to a request you make, or how we process your personal information, you can make a complaint to the data protection regulator in your habitual place of residence.
* For users in the European Economic Area: [https://edpb.europa.eu/about-edpb/board/members\_en](https://edpb.europa.eu/about-edpb/board/members_en)
* For users in the UK: [https://ico.org.uk/make-a-complaint/](https://ico.org.uk/make-a-complaint/)
### Data Processing outside Europe
We are a U.S.-based company and many of our service providers, advisers, partners or other recipients of data are also based in the U.S. This means that, if you use the Service, your personal information will necessarily be accessed and processed in the U.S. It may also be provided to recipients in other countries outside Europe.
Where we share your personal information with third parties who are based outside Europe, we try to ensure a similar degree of protection is afforded to it by making sure one of the following mechanisms is implemented:
* **Transfers to territories with an adequacy decision.** We may transfer your personal information to countries or territories whose laws have been deemed to provide an adequate level of protection for personal information by the European Commission or the UK Government, as and where applicable, or under specific adequacy frameworks approved by the same, such as the EU-U.S. Data Privacy Framework or the UK Extension thereto.
* **Transfers to territories without an adequacy decision.** We may transfer your personal information to countries or territories whose laws have not been deemed to provide such an adequate level of protection. In these cases, we may use specific appropriate safeguards (such as standard contractual clauses approved by the relevant authorities) or, in limited circumstances, rely on a derogation (such as your explicit consent).
You may contact us at [compliance@latch.bio](mailto:compliance@latch.bio) if you want further information on the specific mechanism used by us when transferring your personal information out of Europe.
# Latch Terms of Service
Source: https://wiki.latch.bio/resources/terms-of-service
## What We *Don't* Do With Your Data
* **No Ownership:** Your data, code, and analyses remain solely yours.
* **No Monetization:** We never sell or monetize your data.
* **No Model Training:** Your data isn't used to train machine learning models.
* **No Business Influence:** Your data doesn't inform our decisions, except for helping you debug and give you the best customer service.
* **Purely Hosting:** We are a hosting platform and interact with your data only for that purpose.
# Our Terms of Service
By clicking “Accept,” you (“Customer”) agree to be bound by these terms of service (this “Agreement”), effective as of the date you accept (“Effective Date”), between Customer and LatchBio, Inc., with its principal place of business at 1800 Owens St, San Francisco, CA 94158 (“LatchBio”).
THIS AGREEMENT SETS FORTH THE LEGALLY BINDING TERMS AND CONDITIONS THAT GOVERN YOUR USE OF THE LATCHBIO PLATFORM. BY USING THE LATCHBIO PLATFORM, YOU ARE ACCEPTING THIS AGREEMENT (ON BEHALF OF YOURSELF OR THE ENTITY THAT YOU REPRESENT), AND YOU REPRESENT AND WARRANT THAT YOU HAVE THE RIGHT, AUTHORITY, AND CAPACITY TO ENTER INTO THIS AGREEMENT (ON BEHALF OF YOURSELF OR THE ENTITY THAT YOU REPRESENT). YOU MAY NOT ACCESS OR USE THE LATCHBIO PLATFORM OR ACCEPT THIS AGREEMENT IF YOU ARE NOT AT LEAST 18 YEARS OLD. IF YOU DO NOT AGREE WITH ALL OF THE PROVISIONS OF THIS AGREEMENT, DO NOT ACCESS AND/OR USE THE LATCHBIO PLATFORM.
## 1. DEFINITIONS.
Capitalized terms have the meaning set forth below or as defined within this Agreement.
**1.1 "AI Tools"** means generative artificial intelligence and machine learning services or applications that are integrated into the LatchBio Platform, including without limitation, third-party large language models.
**1.2 "Applicable Privacy Laws"** means the data protection, data security and privacy laws and regulations of any jurisdiction applicable to the LatchBio Platform under this Agreement.
**1.3 "Customer Content"** means any content or information uploaded or transmitted to the LatchBio Platform by Customer or Users, including from Third-Party Services, or other Customer materials provided by Customer or accessed by LatchBio in connection with the Professional Services. Customer Content does not include Performance Data.
**1.4 "Documentation"** means the technical materials provided by LatchBio to Customer in hard copy or electronic form describing the use and operation of the LatchBio Platform.
**1.5 "Fees"** mean all subscription fees, usage fees, fees for applicable credits, and any other amounts specified in an invoice issued under and governed by this Agreement.
**1.6 "LatchBio Platform"** means LatchBio’s cloud software application which enables data manipulation and analysis, organization, storage, and collaboration tools.
**1.7 "LatchBio Property"** means the LatchBio Platform, Performance Data, the Documentation, any deliverables provided as part of Professional Services, and all applicable software, data, or technical information used by LatchBio or provided to Customer in connection with the foregoing.
**1.8 "Personal Data"** means Customer Content that constitutes “personal data,” “personal information,” or “personally identifiable information” defined in Applicable Privacy Laws or information of a similar character regulated thereby, except that Personal Data does not include such information pertaining to Customer personnel who are business contacts for LatchBio, or such information received by LatchBio directly or from other sources (such as its other customers) independent of LatchBio’s relationship with Customer.
**1.9 "Performance Data"** means general performance and usage data about the LatchBio Platform, including Customer’s use of the LatchBio Platform (such as technical logs). Performance Data does not include any Customer Content.
**1.10 "Professional Services"** means any integration, onboarding, training, or other services related to the LatchBio Platform performed by LatchBio for Customer, as identified on a Professional Services Order Form.
**1.11 "Professional Services Order Form"** means an order form executed by the parties that references this Agreement which specifies the scope, schedule, fees, and applicable terms of any Professional Services provided by LatchBio.
**1.12 "Third-Party Service"** means any third-party service or application connected to, or integrated with, the LatchBio Platform by or on behalf of Customer.
**1.13 "Users"** means employees and independent contractors who are authorized by Customer to access the LatchBio Platform pursuant to Customer’s rights under this Agreement.
## 2. LATCHBIO PLATFORM; ACCESS; RESTRICTIONS.
**2.1 Subscription to the LatchBio Platform.** Subject to the terms and conditions of this Agreement, LatchBio hereby grants to Customer a revocable, non-sub-licensable, non-transferable (except as provided in Section 14.2), non-exclusive right to access and use the LatchBio Platform and accompanying Documentation solely for Customer’s internal business purposes.
**2.2 Access.** Each User will be provided access to and use of the LatchBio Platform through unique and confidential account credentials. These credentials cannot be shared or used by more than one individual User to access the LatchBio Platform. Customer is responsible for maintaining the confidentiality of all Users’ account credentials and is solely responsible for all activities that occur under these User accounts. Customer will promptly notify LatchBio of any actual or suspected unauthorized use or access to its account.
**2.3 Restrictions.** Customer will not, and will not permit any User or other party to: (a) allow any third party to access the LatchBio Property except as expressly allowed herein; (b) sublicense, lease, sell, resell, rent, loan, distribute, transfer or otherwise allow the use of the LatchBio Property for the benefit of any unauthorized third party; (c) reverse engineer, decompile, disassemble, or otherwise derive or determine or attempt to derive or determine the source code (or the underlying ideas, algorithms, structure or organization) of the LatchBio Property, except as permitted by law; (d) use any automated software, devices or other processes to “scrape,” extract, or download data from the LatchBio Property (other than Customer Content) without the prior written consent of LatchBio; (e) interfere in any manner with the operation of the LatchBio Property or the hardware and network used to operate the same, or attempt to probe, scan or test vulnerability of the LatchBio Property without the prior written consent of LatchBio; (f) attempt to access the LatchBio Property through any unapproved interface; (g) attempt to circumvent any usage restrictions of the LatchBio Property; (h) modify, copy or make derivative works based on any part of the LatchBio Property; (i) access or use the LatchBio Property to build a similar or competitive product or service or otherwise engage in competitive analysis or benchmarking; (j) remove, alter, or obscure any proprietary notices (including copyright and trademark notices) of LatchBio or its licensors on the LatchBio Property or any copies thereof; or (k) otherwise use the LatchBio Property in any manner that exceeds the scope of use permitted under Section 2.1 or in a manner inconsistent with applicable law, the Documentation or this Agreement.
**2.4 Suspension.** LatchBio reserves the right to suspend Customer’s or any User’s access to the LatchBio Platform at any time and for any reason or no reason including without limitation for any failure, or suspected failure, to comply with the restrictions set forth in Section 2.3. LatchBio may also suspend Customer’s or any User’s access to all or any part of the LatchBio Platform, without notice and without incurring any resulting obligation or liability, if: LatchBio believes, in its good faith and reasonable discretion, that Customer’s or any User’s use of the LatchBio Platform poses a risk to the security or integrity of LatchBio’s systems, interferes with LatchBio’s ability to reliably provide the LatchBio Platform to other customers, or may subject LatchBio to liability. LatchBio will use reasonable efforts to notify Customer or the applicable User(s) prior to suspension and will restore access to Customer or the applicable User(s) as soon as such risks no longer apply.
**2.5 Customer Content.** Customer will have the sole responsibility for the accuracy, quality, integrity, legality, reliability, and appropriateness of all Customer Content. The Customer Content will not: (a) be deceptive, defamatory, obscene, pornographic or unlawful; (b) knowingly contain any viruses, worms or other malicious computer programming codes intended to damage the LatchBio Platform; or (c) violate the intellectual property, privacy, or other rights of any third party or violate any Applicable Privacy Laws.
**2.6 Third-Party Services.** Customer may elect to link certain Third-Party Services to the LatchBio Platform. Customer is responsible for enabling the integration of each Third-Party Service, and by doing so, Customer acknowledges that: (a) LatchBio may access any Customer Content provided via a Third-Party Service so that it may be used in accordance with the terms of this Agreement, and (b) it is instructing LatchBio to share Customer Content (including Personal Data where directed) with the providers such Third-Party Services. Third-Party Services are not under the control of LatchBio and LatchBio is not responsible for any Third-Party Services. Customer’s use of the Third-Party Services is governed by the Customer’s agreement with providers of the Third-Party Services. Customer acknowledges and agrees that, for the purposes of Applicable Privacy Laws, each of LatchBio and providers of any Third-Party Service are not processors or subprocessors of Personal Data with respect to each other.
Customer acknowledges that LatchBio may make Open Source Software (“OSS”) available on the LatchBio Platform. Such OSS is provided as-is, subject to its original license terms, and LatchBio assumes no liability or warranty with respect to (i) the accuracy, performance, or functionality of such OSS or (ii) any agreements between Customer and the OSS providers.
**2.7 Use of AI Tools.** The LatchBio Platform may incorporate or be provided with the assistance of AI Tools. Customer Content will be shared with Third-Party Services that provide the AI Tools in order to provide the LatchBio Platform. CUSTOMER ACKNOWLEDGES THAT THE SERVICES LEVERAGE AI TOOLS AND THAT LATCHBIO IS NOT LIABLE, AND CUSTOMER AGREES NOT TO SEEK TO HOLD LATCHBIO LIABLE, FOR ANY THIRD-PARTY AI TOOLS. CUSTOMER IS SOLELY RESPONSIBLE FOR ENSURING THAT ITS USE OF THE LATCHBIO PLATFORM COMPLY WITH ALL APPLICABLE LAWS. CUSTOMER WILL BE SOLELY RESPONSIBLE FOR CUSTOMER’S USE OF THE LATCHBIO PLATFORM. CUSTOMER SHOULD EVALUATE THE FITNESS OF ANY INFORMATION FROM THE LATCHBIO PLATFORM TO DETERMINE IF IT IS APPROPRIATE FOR CUSTOMER’S SPECIFIC USE CASE.
## 3. PROFESSIONAL SERVICES.
**3.1 Services.** LatchBio will provide the Professional Services as set forth in a Professional Services Order Form. The Professional Services and any deliverables provided as a part thereof may only be used in conjunction with the LatchBio Platform. All Professional Services will be provided remotely unless otherwise agreed in the applicable Professional Services Order Form.
**3.2 Cooperation.** Customer will reasonably cooperate with LatchBio in the performance of the Professional Services. Such cooperation may include (a) the appointment of a single point of contact for all matters related to the Professional Services, (b) the provision of reasonable remote network access to those Customer systems that utilize the Professional Services, and (c) making suitably trained personnel with sufficient knowledge of Customer’s systems available during normal business hours. Customer acknowledges that in order to perform the Professional Services, LatchBio may be required to have access to certain Customer Content.
## 4. SUPPORT.
Subject to the terms and conditions of this Agreement, LatchBio may (but is under no obligation to) provide Customer with support or maintenance services for the LatchBio Platform in accordance with industry standards. However, LatchBio does not guarantee the availability of any specific support or response times and is not obligated to provide any particular level of support.
## 5. FEES AND PAYMENT.
**5.1 Fees.** Customer will pay LatchBio the Fees set forth in the applicable invoice within thirty (30) days from the date of such invoice. Fees are non-refundable (except as expressly set out in this Agreement) and are not eligible for set off. Customer will maintain complete, accurate and up-to-date Customer billing and contact information. LatchBio reserves the right to adjust the Fees at any time. Any such Fee increase will be effective at the start of your next billing cycle following the notice period, provided that LatchBio delivers written notice at least thirty (30) days in advance email to suffice. Customer’s continued use of the LatchBio Platform after receiving notice of the Fee increase will constitute acceptance of the change.
**5.2 Taxes.** All Fees owed by Customer in connection with this Agreement are exclusive of, and Customer will pay, all sales, use, excise and other taxes and applicable export and import fees, customs duties and similar charges that may be levied upon Customer in connection with this Agreement, except for employment taxes and taxes based on LatchBio’s income.
**5.3 Late Payment.** Payments by Customer that are past due will be subject to interest at the rate of one and one-half percent (1½%) per month (or, if less, the maximum allowed by applicable law) of that overdue balance. LatchBio reserves the right (in addition to any other rights or remedies LatchBio may have) to suspend Customer’s access to the LatchBio Platform if any Fees set forth in the applicable invoice are more than thirty (30) days overdue until such amounts are paid in full.
## 6. PROPRIETARY RIGHTS.
**6.1 LatchBio Property.** Customer acknowledges that LatchBio retains all right, title and interest in and to the LatchBio Property, including any enhancements, improvements, or derivatives thereto, and that the LatchBio Property is protected by intellectual property rights owned by or licensed to LatchBio. Other than as expressly set forth in this Agreement, no license or other rights in the LatchBio Property are granted to the Customer.
**6.2 Customer Content.** Customer retains all right, title and interest in and to the Customer Content. Customer hereby grants to LatchBio a non-exclusive, worldwide, royalty-free and fully paid-up license during the Term to access and use Customer Content to provide the LatchBio Platform, Professional Services, and any accompanying support to Customer as set forth in this Agreement.
**6.3 Performance Data.** LatchBio may monitor Customer’s use of the LatchBio Platform and may collect and compile Performance Data. As between LatchBio and Customer, all right, title, and interest in the Performance Data, and all intellectual property rights therein, belong to and are retained solely by LatchBio. LatchBio may use Performance Data to operate, improve, analyze, and support the LatchBio Platform and for other lawful business purposes, provided that the Performance Data will not identify Customer as the source of such information.
**6.4 Feedback.** Customer or its Users may give feedback to LatchBio on the use, operation, and functionality of the LatchBio Platform and Professional Services, including information about operating results, known or suspected bugs, errors, or compatibility problems, suggested modifications, and user-desired features, functionality, or workflows (collectively, “Feedback”). LatchBio may use and incorporate such Feedback connection with its business, products and services without restriction or consideration to Customer. LatchBio will not identify Customer as the source of any such Feedback. LatchBio acknowledges that all Feedback is provided to LatchBio on an “as is” basis and that Customer is not responsible for LatchBio’s use of any Feedback, including any results therefrom.
## 7. PRIVACY.
By using the LatchBio Platform, the Customer acknowledges and agrees that any Personal Data uploaded or submitted by the Customer is done at the Customer’s sole risk and responsibility. The Customer is solely responsible for ensuring that it has provided all necessary notices and obtained all required consents, permissions, and rights from relevant third parties to permit LatchBio to receive, process, and use such Personal Data in connection with providing the LatchBio Platform and performing its obligations under this Agreement, in compliance with applicable law.
## 8. TERM AND TERMINATION.
**8.1 Term.** The term of this Agreement will commence on the Effective Date and will remain in full force and effect for so long as Customer continues to access or use the LatchBio Platform (“Term”).
**8.2 Termination.** LatchBio may terminate this Agreement for any reason or no reason at all, at its sole discretion, by providing notice to Customer and
Customer may terminate this Agreement at any time by providing notice to LatchBio and ceasing all access to and use of the LatchBio Platform.
**8.3 Effect of Termination.** Upon the expiration or termination of this Agreement for any reason, the rights and licenses granted to Customer hereunder will immediately terminate and Customer will cease use of the LatchBio Platform and Documentation. Termination of this Agreement will not relieve Customer of its obligation to pay all Fees that accrued prior to such termination. Sections 1, 2.3, 5, 6 (excluding any term-limited license grants), 8.3, 9, and 13 will survive the termination of this Agreement.
## 9. LIMITED WARRANTIES.
Customer represents and warrants that it has all rights necessary to upload and use the Customer Content with the LatchBio Platform and to grant LatchBio all licenses to Customer Content in this Agreement without violating any third-party intellectual property, privacy or other rights, including Applicable Privacy Laws. During the Term, LatchBio warrants that the LatchBio Platform, when used in accordance with the Documentation and the terms of this Agreement, will operate as described in the Documentation in all material respects. If Customer notifies LatchBio of any breach of the foregoing warranty, LatchBio will, as Customer’s sole and exclusive remedy, use commercially reasonable efforts to repair and fix the non-conforming portion of the LatchBio Platform. LatchBio also warrants that the Professional Services will be performed in a professional and workmanlike manner. If Customer notifies LatchBio of any breach of the foregoing warranty, LatchBio will, as Customer’s sole and exclusive remedy, at its option re-perform the Professional Services.
## 10. DISCLAIMER.
EXCEPT AS EXPRESSLY PROVIDED HEREIN, AND TO THE MAXIMUM EXTENT PERMITTED BY APPLICABLE LAW: (A) THE LATCHBIO PROPERTY IS PROVIDED “AS IS” AND “AS AVAILABLE” AND (B) LATCHBIO AND ITS SUPPLIERS MAKE NO OTHER WARRANTIES, EXPRESS OR IMPLIED, BY OPERATION OF LAW OR OTHERWISE, AND HEREBY EXPRESSLY DISCLAIM ANY AND ALL OTHER WARRANTIES INCLUDING, WITHOUT LIMITATION, ANY IMPLIED WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE, TITLE, OR NON-INFRINGEMENT. LATCHBIO DOES NOT WARRANT OR REPRESENT THAT THE LATCHBIO PROPERTY WILL BE FREE FROM BUGS OR UNINTERRUPTED OR ERROR-FREE, OR MAKE ANY OTHER REPRESENTATIONS REGARDING THE USE, OR THE RESULTS OF THE USE, OF THE LATCHBIO PROPERTY IN TERMS OF CORRECTNESS, ACCURACY, RELIABILITY, OR OTHERWISE. CUSTOMER ACKNOWLEDGES AND AGREES THAT LATCHBIO IS NOT LIABLE, AND CUSTOMER AGREES IT WILL NOT SEEK TO HOLD LATCHBIO LIABLE, FOR THE CONDUCT OF THIRD PARTIES, INCLUDING ANY THIRD-PARTY SERVICE, AND THAT THE RISK OF INJURY FROM ANY THIRD PARTY RESTS ENTIRELY WITH CUSTOMER.
## 11. INDEMNIFICATION.
**11.1 Indemnification by Customer.** If any claim, action, demand, suit, or proceeding is brought by a third party against LatchBio or its affiliates, officers, directors, employees, or agents (collectively, the “LatchBio Indemnitees”) arising out of or relating to: (a) Customer Content, including any actual or alleged infringement, misappropriation, or violation of any intellectual property or proprietary rights; (b) Customer’s breach or alleged breach this Agreement; or (c) Customer’s access to or use of the Platform, including any misuse or violation of applicable laws, rules, or regulations, then Customer shall, at its sole cost and expense, (i) defend LatchBio Indemnitees against such claim using counsel reasonably acceptable to LatchBio, and (ii) indemnify and hold harmless the LatchBio Indemnitees from and against any and all damages, losses, liabilities, costs, and expenses (including reasonable attorneys’ fees and court costs) arising from or relating to such claim.
LatchBio shall promptly notify Customer of any such claim; however, any delay or failure to provide such notice shall not relieve Customer of its indemnification obligations except to the extent Customer is materially prejudiced by such delay or failure. LatchBio may participate in the defense of any claim with counsel of its own choosing at its own expense. Customer shall not settle any claim without LatchBio’s prior written consent, which shall not be unreasonably withheld, conditioned, or delayed.
## 12. LIMITATION OF LIABILITY.
TO THE EXTENT PERMITTED BY LAW, IN NO EVENT WILL LATCHBIO BE LIABLE FOR SPECIAL, INCIDENTAL, CONSEQUENTIAL OR PUNITIVE DAMAGES OR LOST PROFITS IN ANY WAY RELATING TO THIS AGREEMENT. IN NO EVENT WILL LATCHBIO’S AGGREGATE, CUMULATIVE LIABILITY IN ANY WAY RELATING TO THIS AGREEMENT EXCEED THE AMOUNT OF FEES ACTUALLY RECEIVED BY LATCHBIO FROM CUSTOMER DURING THE TWELVE (12) MONTHS PRECEDING THE CLAIM. THE FOREGOING LIMITATIONS WILL NOT APPLY TO LIABILITIES THAT CANNOT BE LIMITED BY LAW. THE PARTIES WOULD NOT HAVE ENTERED INTO THIS AGREEMENT BUT FOR SUCH LIMITATIONS.
## 13. GENERAL PROVISIONS.
**13.1 Governing Law.** This Agreement will be governed by, and all disputes arising under or in connection with this Agreement will be resolved in accordance with, the laws of the State of Delaware, exclusive of conflict or choice of law rules. Notwithstanding the foregoing, nothing will prevent a party from seeking relief in any court of competent jurisdiction for any misuse or misappropriation of that party’s intellectual property rights.
**13.2 Assignment; Subcontractors.** Neither party may assign this Agreement, including any rights or obligations arising hereunder, without the prior written consent of the other, except that LatchBio may assign this Agreement without the consent of Customer in connection with a merger, acquisition, corporate reorganization, or sale of all or substantially all of its assets. Any attempted assignment or transfer in violation of the foregoing will be null and void. This Agreement will be binding upon each party’s respective permitted successors and assigns. Customer agrees that LatchBio may subcontract certain aspects of the LatchBio Platform to qualified third parties, provided that any such subcontracting arrangement will not relieve LatchBio of any of its obligations hereunder.
**13.3 Notices.** Any notice under this Agreement must be given in writing. Customer notices to LatchBio shall be sent by email to [compliance@latch.bio](mailto:compliance@latch.bio). LatchBio notices to Customer shall be sent to the email address associated with Customer’s workspace administrator. Notices sent by email are deemed received upon transmission unless a delivery failure is received. To be deemed effective, any email notice of the other party’s material breach pursuant to Section 9.2 must reference Section 9.2.
**13.4 Force Majeure.** Any delay in the performance of any duties or obligations of either party (except for the obligation to pay Fees owed) will not be considered a breach of this Agreement if such delay is caused by a labor dispute, shortage of materials, war, fire, earthquake, typhoon, flood, natural disasters, governmental action, pandemic/epidemic, cloud-service provider outage, or any other event beyond the control of such party (collectively, a “Force Majeure Event”), provided that such party uses reasonable efforts, under the circumstances, to notify the other party of the circumstances causing the delay and to resume performance as soon as possible.
**13.5 Publicity.** LatchBio may use Customer’s name and logo to identify Customer as a customer, including on LatchBio’s website, social media and in sales and marketing materials, in the same manner in which it uses the names of its other customers. LatchBio will use Customer’s name and logo in accordance with any provided branding guidelines if applicable and LatchBio may not use Customer’s name or logo in any other way without Customer’s prior written consent.
**13.6 Export.** Customer agrees not to use, export, re-export, or transfer, directly or indirectly, any U.S. technical data acquired from LatchBio, or any products utilizing such data, in violation of the United States export laws or regulations. Further, each party agrees to comply with all relevant export laws and regulations of the United States and the country or territory in which the LatchBio Platform provided (“Export Laws”) to assure that neither any deliverable, if any, nor any direct product thereof is (1) exported, directly or indirectly, in violation of Export Laws or (2) intended to be used for any purposes prohibited by the Export Laws, including without limitation nuclear, chemical, or biological weapons proliferation. Customer further represents that (i) Customer is not located in a country that is subject to a U.S. Government embargo, or that has been designated by the U.S. Government as a “terrorist supporting” country and (ii) Customer is not listed on any U.S. Government list of prohibited or restricted parties. Customer acknowledges and agrees that products, services or technology provided by LatchBio are subject to the export control laws and regulations of the United States, agrees to comply with these laws and regulations, and agrees that it will not, without prior U.S. government authorization, export, re-export, or transfer LatchBio products, services or technology, either directly or indirectly, to any country in violation of such laws and regulations.
**13.7 Anti-Bribery.** Neither Customer nor any of its Users, personnel, directors, affiliates or officers or any other person acting on their behalf has directly or indirectly made any bribes, rebates, payoffs, influence payments, kickbacks, illegal payments, illegal political contributions, or other payments, in the form of cash, gifts, or otherwise, or taken any other action, in violation of the Foreign Corrupt Practices Act of 1977 or any other anti-bribery or anti-corruption law (collectively, the “Anti-Bribery Laws”). Customer is not, and has not been, the subject of any investigation or inquiry by any governmental body with respect to potential violations of Anti-Bribery Laws. Customer will immediately notify LatchBio of any breach, suspected breach of, or any investigation into the suspected breach of, the Anti-Bribery Laws by it or any of the aforementioned persons and, upon such notice, LatchBio may, in its discretion, immediately terminate this Agreement.
**13.8 U.S. Government Restricted Rights.** If Customer is a government end user, then this provision also applies to Customer. The software contained within the LatchBio Platform and provided in connection with this Agreement has been developed entirely at private expense, as defined in FAR section 2.101, DFARS section 252.227-7014(a)(1) and DFARS section 252.227- 7015 (or any equivalent or subsequent agency regulation thereof), and is provided as “commercial items,” “commercial computer software” and/or “commercial computer software documentation.” Consistent with DFARS section 227.7202 and FAR section 12.212, and to the extent required under U.S. federal law, the minimum restricted rights as set forth in FAR section 52.227-19 (or any equivalent or subsequent agency regulation thereof), any use, modification, reproduction, release, performance, display, disclosure or distribution thereof by or for the U.S. Government will be governed solely by this Agreement and will be prohibited except to the extent expressly permitted by this Agreement.
**13.9 Miscellaneous.** This Agreement (as modified by the parties from time to time) is the entire understanding and agreement of the parties, and supersedes any and all previous and contemporaneous understandings. Only a written amendment signed by both parties may modify this Agreement. This Agreement may be executed in counterparts, which taken together will form one legal instrument. In the event that any provision of this Agreement is held to be invalid or unenforceable, the valid or enforceable portion thereof and the remaining provisions of this Agreement will remain in full force and effect. Any waiver or failure to enforce any provision of this Agreement on one occasion will not be deemed a waiver of any other provision or of such provision on any other occasion. All waivers must be in writing. The headings of Sections of this Agreement are for convenience and are not to be used in interpreting this Agreement. As used in this Agreement, the word “including” means “including but not limited to.” The parties to this Agreement are independent contractors, and no agency, partnership, franchise, joint venture or employee-employer relationship is intended or created by this Agreement. There are no third-party beneficiaries of this Agreement.
# What is LatchBio?
Source: https://wiki.latch.bio/start/introduction
Latch is a platform for you to store, analyze, and visualize multiomics data.
Latchbio is a cloud platform for handling and analyzing biological data. Alongside a developer-focused SDK and API, it consists of five core components.
## Core pillars
With the 5 core pillars of Latch: Data, Visualizations, Registry, and Workflows, you can design and manage the entire data lifecycle.
}
href="/data/overview"
>
Store & share unlimited amounts of raw data. Visualize all types of biological data.
}
href="/registry/what-is-a-registry"
>
Connect your sample sheets, metadata, and analysis to facilitate collaboration between the wet lab and dry lab.
}
href="/workflows/overview"
>
Access community workflows like bulk RNA-seq and Nextflow. Create pipelines & no-code UIs with our SDK in Python.
}
href="/pods/overview"
>
Access on-demand computational resources, scalable notebooks, & flexible apps.
}
href="/plots/overview"
>
Create interactive visualizations & data transformations.
## Beginner Tutorials
To further explore, follow one of our guides to see how our core pillars translate to your use case.
## Additional Features
We also support creating interactive visualizations, workspaces, and organizations.
Manage members & data access.
Manage multiple workspaces under a single organization.
# Quickstart
Source: https://wiki.latch.bio/start/quickstart
To create an account on Latch simply continue with a Google, GitHub, or Microsoft account. Latch offers several single sign-on (SSO) options:
Some Microsoft organization accounts require additional setup to be used. Alternatively non SSO accounts can be administered by request.
If you need help setting up your account, contact the team at Latch at [support@latch.bio](mailto:support@latch.bio).
Every new account starts with a Personal Workspace. To collaborate with team members on Latch you can create or join a team Workspace.
To join a team, a team member can share the team invite code with you, which you can enter in the Join Workspace modal
A team member can also send a team email. Look for a team invite email and click the Join Team button and follow the prompts.
After you've created an account (and optionally joined a team workspace) you can explore your workspace.
The left navbar contains tabs to switch between the different aspects of the platform, these are:
* **Workspace Avatar:** Here you can switch workspaces and access a workspace settings.
* **Latch Data:** A cloud file system to store experiment files and results.
* **Latch Registry:** Keep track of experiment metadata and files in table interface.
* **Latch Workflows:** Run analysis workflows through a user-friendly interface.
* **Latch Pods:** Run downstream analysis through preconfigured apps and notebooks.
* **Help Button:** Find help resources and contact Latch support
* The Help Menu has a list of resources (this Wiki included) and also allows you to
easily contact the Latch team through Intercom chat. Our Intercom is always answered
by a real person and we always try to answer quickly but for best results contact
during Pacific Time US business hours.
The "Eyesore Help Button Mode" changes the style of the help button to something more muted. An engineer added it because he thought the darker button was an eyesore.
# ATAC Seq
Source: https://wiki.latch.bio/workflows/ATAC-Seq
## Upload your ATAC Seq data
Use the ‘Upload’ modal found on the top right, and upload your raw .fastq or .fastq.gz files to Latch Data with the upload [modal](https://wiki.latch.bio/data/basic-uploading-and-downloading). Alternatively, you can also use the command line interface to upload your [data](https://wiki.latch.bio/data/data-command-line#command-line-interface-data-upload-download).
## Set up sample sheet on Latch Registry
1. Navigate to the [Latch Registry](http://wiki.latch.bio/registry/what-is-a-registry) tab on the left panel
2. Create a new table.
Navigate to import and select **Bulk Import Sequencing Run** and navigate to the directory containing sequencing data.
Create a samplesheet and add a column to include replicate numbers
## Launch NFCore/ATACSeq Workflow
1. Navigate to the Latch Workflows tab on the left panel.
2. Choose the ‘nf-core/atacseq’ workflow in ‘All Workflows’ or My Workflows’ (if you have added it).
3. Import rows from the registry.
4. Specify the reference genome. Choose from the latch-verified custom reference genome or input your own reference genome.
5. Specify the aligner used to align reads to the reference genome.
6. Specify options used to run MACS2, which is a peak calling software.
7. After configuring the workflow parameters, hit launch workflow
## Results from running the NFCore/ATACSeq workflow
### Key Takeaways
1. The results from the ATAC Seq library preparation are available in the **\[output directory]/\[run name]** on ldata
2. The workflow produces alignments, peak files, bigwig files that can loaded into IGV, and peak annotations with HOMER.
3. Sample level analysis can be found at,
* The peak files are found at *\[output directory]/\[run name]/\[aligner name]/merged\_replicate/macs2/broad\_peak/\[sample id].mRp.clN\_peaks.xls*
* The peak annotations are found at *\[output directory]/\[run name]/\[aligner name]/merged\_replicate/macs2/broad\_peak/\[sample id].mRp.clN\_peaks.annotatePeaks.txt*
* The bigwig files that can be viewed with IGV can be at *\[output directory]/\[run name]/\[aligner name]/merged\_replicate/macs2/bigwig/\[sample id].mRp.clN.bigWig*
4. Replicate level analysis can be found at,
* The peak files are found at *\[output directory]/\[run name]/\[aligner name]/merged\_replicate/macs2/bigwig/\[sample id].mRp.clN\_peaks.xls*
* The peak annotations are found at *\[output directory]/\[run name]/\[aligner name]/merged\_replicate/macs2/bigwig/\[sample id].mRp.clN\_peaks.annotatePeaks.txt*
* The bigwig files that can be viewed with IGV can be at *\[output directory]/\[run name]/\[aligner name]/merged\_replicate/macs2/bigwig/\[sample id].mRp.clN.bigWig*
5. Results from running differential accessibility analysis can be found here at,
* Results from PCA can be found here at, *\[output directory]/\[run name]/\[aligner name]/merged\_library/macs2/broad\_peak/consensus/deseq2/consensus\_peaks.mLb.clN.pca.vals.txt*
* The PCA distance matrix is available here at, *\[output directory]/\[run name]/\[aligner name]/merged\_library/macs2/broad\_peak/consensus/deseq2/consensus\_peaks.mLb.clN.sample.dists.txt*
### Supplementary Results
1. The intermediate alignments, fastqc reports, multiqc reports, genome information, and the trimmed read information is available here at, *\[output directory]/\[run name]/\[aligner name]*, *\[output directory]/\[run name]/fastqc*, *\[output directory]/\[run name]/genome*, *\[output directory]/\[run name]/multiqc*, and *\[output directory]/\[run name]/trimgalore*
2. The pipeline also creates two other directories namely *\[output directory]/\[run name]/R\_Plots* and *\[output directory]/\[run name]/cov\_parquet/* that hosts the data matrices required for plotting results with the Latch Verified ATACSeq Plots layout.
### Sample registry tables
Further, the workflow creates a table in the registry with the run name within the project “ATAC\_Seq\_Results”. This table carries data tables computed as a part of the workflow that can be loaded with the verified ATAC Seq plots layout, which helps visualize the results from the workflow.
## Plotting Layout
1. Create a new plotting template by choosing the Verified ATAC Seq Plots Layout from the list of available plots layout,
2. Load the data matrices by loading the registry table created as a part of the workflow,
3. The plotting layout automatically loads all the dataframes needed to make plots and produces the following plots.
The distribution of fragment lengths obtained from a paired-end ATAC seq library has an inherent periodicity to it and the distribution decays exponentially. The first peak corresponds to nucleosomal regions, the second peak to mononucleosomal regions, the third peak to dinucleosomal regions, etc., This curve is characteristic of ATAC Seq libraries and is an essential step in quality control analysis.
A good ATAC seq library has a clear peak with periodicity (of about 200 bases), and errors in library prep could result in the largest peak at nucleosome-bound portions, on the other hand, a sub-optimally transposed library has no visible peaks at nucleosome-bound regions. These curves often serve as a certificate of goodness for ATAC seq library preparation.
As described early on, the pileup of reads in nucleosome-free regions is the highest with ATAC seq libraries. Promoters of active regions typically, found in open chromatin regions of the chromosome are captured by ATAC seq libraries. Thus, fragments shorter than 100 bases are typically indicative of nucleosome-free segments. The concentration of signal immediately around Transcription Start Sites(TSS) is enriched with nucleosome-free regions. Similarly, about 200 bases from TSS, we see an enrichment for nucleosome-bound regions. We extract the signal in the TSS and disaggregate the signal from fragments with nucleosome-free and nucleosome-bound regions of the chromosome. These curves are also used in the quality control analysis of ATAC seq data. A good library would suggest that there is a larger concentration of the signal from nucleosome-free fragments near TSS.
To estimate the impact of PCR duplicates on the library preparation, we plot the number of unique fragments for different amounts of putative segments sequenced. The curves help compare biases originating from library preparation between different samples.
We plot the principal component transformed “peak count” matrix as a scatter plot along the top PCs. The scatter points are also annotated with the sample names, making it immensely easy to compare between samples and replicates.
We also plot a heatmap of the pairwise distances which provides an alternate view of the same data.
4. The plotting layout further makes it very easy to visualize peaks across samples, and provides functionality to search by genes and chromosomes.
The ATAC seq peaks constitute the most important aspect of the analysis of ATAC seq data. Conventionally, scientists have relied upon IGV to identify these segments of interest. Here in addition, to IGV sessions, we also provide an interactive peak visualization dashboard, that allows the user to select peaks based on genes/chromosomes.
# What is ATAC seq?
Source: https://wiki.latch.bio/workflows/ATAC-Seq-Deep-Dive
ATAC (assay for transposase-accessible chromatin) Sequencing is a powerful sequencing tool that has been used to study the epigenetic signature of genomes. ATAC seq aims to capture the open chromatin parts of the genome and throws light on the effect of chromatin packaging on gene expression and gene regulation. ATAC sequencing uses a hyperactive mutant of the TN5 transposase, which inserts itself into the open chromatin regions of the genome. Further, this transposase cleaves the double-stranded DNA and attaches adaptors to the fragments. These fragments are then purified, PCR-amplified, and sequenced using NGS. The workflow to process the raw ATAC sequencing reads is presented in the NFCore ATACseq workflow.
The workflow primarily aims at aligning reads against the genomes and computes a pile-up of reads at every base along the genome. The heart of the workflow is to clean up the alignments and compute “peaks”- more than expected pileup of reads along specific parts of the genome, likely to correspond to open chromatin portions of the genome. The workflow uses a series of tools and provides the user with various choices for every step in the process.
In this article, we present the steps in this pipeline and the set of software tools used to manipulate ATAC seq data.
## Quality Control Analysis of Sequencing Reads
The ATAC Seq pipeline relies upon a set of tools to ensure data quality and remove any artifacts resulting from poor-quality reads.
1. **FastQC**-FastQC performs read quality analysis by aggregating per base quality scores across reads and plots key metrics. This can be used to filter out reads and trim portions of the read of poor quality.
2. **Trim Galore!** - Trimgalore is used in this analysis to remove adapter sequences from the sequencing reads.
## Read Alignments
In this part of the workflow, we aim to align reads against the reference genome. The outputs from this step are key in identifying segments of the genome enriched in chromatin-accessible elements. The ATAC Seq pipelines offers 4 choices of short read aligners for aligning reads to the genome and the read alignment is one of the most compute-heavy portions of the workflow.
BWA uses Burrows Wheeler transform to align reads against the genome. It is efficient and has a low memory footprint compared to other methods and this is the default aligner used by the workflow.
BowTie2 is one of the most commonly used short-read aligners, which also uses Burrows Wheeler transform as an indexing kernel.
STAR is another method for performing read alignments and relies on a suffix array data structure to compute alignments of short reads against the genome.
Chromap- Chromap is a relatively new, fast method for processing high-throughput ChIP and ATAC seq data. In addition to aligning, chromap, removes duplicates and performs a Tn5 shift, analyses specific to ChIP seq/ATAC seq data.
## Post-processing read alignments
### Filtering Alignments
Upon computing the alignments, the workflow uses PICARD to merge samples from the same library. The merged alignments obtained from the previous step are filtered to retain only alignments that are free of PCR duplicates, and poor-quality alignments. To that end, the workflow relies upon SAMtools, PiCard, and bedtools. The workflow uses PICARD to mark duplicates that are often a result of PCR amplification biases and if not removed can artificically boost the signal confidence. The reads that are marked as duplicates are removed from further analysis. The number of duplicates also serves as a method to gauge the library complexity. Further, the workflow uses SAMtools to remove reads aligning to the mitochondrial DNA, blacklisted portions of the genome that tend to attract the TN5 transposase, read alignments that are marked as secondary alignments, unmapped reads, reads containing over 4 mismatches, reads alignments that are soft-clipped, read pairs aligning to different chromosomes, and reads that do not align with concordant orientation.
### Peak calling and peak annotation
The most important signal extracted from these filtered alignments is the ATAC Seq peak information. Since the library preparation step performs a targetted biased tagmentation of the open chromatin regions, the coverage of reads aligning to the genome will not be uniform. The coverage is expected to be spiky, with an increased percapita coverage to the chromatin-accessible parts of the genome. These segments are often referred to as "peaks" in literature and the rest of the workflow spins around computing, visualizing, and annotating the peaks. To that end,
The workflow relies upon Picard and preseq to estimate the library complexity and study the effect of PCR duplication on the library size
1. **BedTools** to create bigWig files, that can be loaded with IGV to visualize coverage signals,
2. **Deeptools** to generate gene-body meta-profile from the bigWig files and compute genome-wide enrichment of the ATAC seq reads. In case, the samples are annotated as cases and controls, the enrichment is calculated concerning controls.
3. **MACS2** is used to call peaks. MACS2 is a count-based peak calling software, that identifies sections of the genome that have a significant pile-up of reads compared to the background. MACS2 can either identify broad or narrow peaks, and by default, the workflow identifies broad peaks. Narrow peaks are regions where the concentration of the read coverage signal (e.g., binding sites of a transcription factor) is very sharp and localized. These peaks typically represent short regions of high signal intensity. On the other hand, broad peaks, represent regions where the signal is spread out over a broader genomic area. The enrichment is not as sharply defined as in narrow peaks and can cover a wider region of DNA. These are likely to correspond to histone modifications.
4. **HOMER** is employed to annotate the peaks relative to gene features. Since the chromatin-accessible regions are often present closer to the gene body, annotating the peaks with the nearest gene is often useful for downstream tasks.
5. The workflow also relies on BEDTools to merge peaks across all samples and create consensus peaks, which retain only the peaks that are found in all samples and remove peaks that are present in sample-specific. The set of consensus peaks establishes a basis for studying peaks that are used to perform downstream tasks such as differential expression analysis between cases and controls. To count reads in consensus peaks, the workflow uses the featureCounts package.
6. The matrix of peak counts obtained from the previous step is then used to perform a "differential accessibility analysis". Differential accessibility analysis is very similar in vein to differential abundance testing usually performed for gene counts. The same statistical machinery is extended to peaks in this context of ATAC Seq data. This is a powerful method to identify peaks that are differentially enriched between different samples and can also help detect potential batch effects, and ensure that biological replicates have similar peaks. The workflow uses DESeq2 to perform the differential accessibility analysis and projects the counts onto the top 2 PCs.
7. **ATAQV** tool kit is used to make QC plots and renders the QC metrics as an HTML report.
While the analysis thus far focused on individual samples, if there are multiple replicates available, the workflow combines alignments from all the replicates and reruns all of the analysis on the merged replicates.
The workflow in addition to running all of the aforementioned analysis, also creates an interactive dashboard on Latch Plots. The workflow creates a registry table with the "run name", and pulls all the data that needs to be plotted, into the registry table. This can then be loaded into the layout of the plot, and visualize the results from ATAC Seq QC, Differential accessibility analysis and, peaks. We use the R package, ATACseqQC, to calculate these metrics of interest.
# AlphaFold
Source: https://wiki.latch.bio/workflows/alphafold
AlphaFold produces highly accurate protein structure predictions from amino acid sequences.
## How to run AlphaFold on Latch
1. **Find AlphaFold in your Workspace**
1. Find **AlphaFold** in "All Workflows" and open the workflow
2. **Enter the parameters for AlphaFold**
1. First supply your Amino Acid sequences.
1. Amino Acid sequences must be provided using FASTA format and can either be input from a file or simply pasted in. More details on the format can be found [here](https://github.com/deepmind/alphafold#examples).
```
>sequence_name
```
2. AlphaFold2 can be run on either monomers or multimer and is inferred from whether your input has a single or multiple chains.
3. Things to note:
1. The amount of time AlphaFold takes to run is increases rapidly relative the size of the Amino Acid. So large sequences can be run, but will take large amount of time and resource to produce an output
2. **Next supply the Tuning Parameters**
1. Number of Models
1. Number of models to use. **Single** uses 1 model, whereas **Multi** mode will generate 5 results, each using weights trained using a different random seed.
2. Default: Single (1 Model)
2. Optional Parameters
1. Database Size
1. **Reduced** will be faster, whereas **Full** will be slightly more accurate
2. Default: Reduced
2. Template Date
1. By default this is set to 2022-01-01.
2. If you are predicting the structure of a protein that is already in the [Protein Structure Database](https://alphafold.ebi.ac.uk/) and you wish to avoid using it as a template, then set this date before release date of the structure. For example, if we are running the simulation on Jully 2nd 2022, we set it to 2022-07-02.
3. ISO-8601 format i.e. YYYY-MM-DD
3. **Specify the output Run Name and Location**
1. By default AlphaFold outputs will be put at default location in the data tab - AlphaFold2 Outputs/"Run Name”
2. A custom output path can be supplied and if the folder path does not exist in your data it will be created.
4. **Click Launch Execution**
1. You can check the status of the workflow execution in the Execution tab on the AlphaFold page or in All Executions. Once the workflow has finished your output files and protein structures can be found on the sidebar on the execution page or in the data tab.
# Bulk RNAseq Quantification Walkthrough
Source: https://wiki.latch.bio/workflows/bulk-rna-seq
## Upload your RNAseq data
Use the ‘Upload’ modal found on the top right, and upload your raw .fastq or .fastq.gz files to Latch Data with the upload modal.
### Set up samplesheet on Latch Registry
Create new Project (if needed) and a new Sheet under that Project for the experiment being run.
### Launch ‘nf-core/rnaseq’ Latch Workflow
Choose the ‘nf-core/rnaseq’ workflow in ‘All Workflows’ or My Workflows’ (if you have added it).
Click on the (x) for strandedness in most cases - only use strandedness if you have an nf-core specific strandedness column in your metadata.
Or choose your own Reference FASTA and GTF in the ‘Custom Reference Genome’ tab.
Do not use spaces in the Run Name.
We recommend leaving the Output Directory to its default location.
(Optional - Advanced) Choose other parameters in ‘Optional Arguments’.
There are descriptions for every parameter available when you hover above the (i) symbol on a parameter name.
Double click the execution to be taken to detailed logs.
Useful outputs are the run HTML report and all the computational outputs in the folder that matches the name of the aligner you used.
## Differential Gene Expression
### Launch ‘DESeq2 (Differential Expression)’ Latch Workflow
Choose the ‘DESeq2 (Differential Expression)’ workflow in ‘All Workflows’ or My Workflows’ (if you have added it).
All outputs from ‘nf-core/rnaseq’ have an output folder called ‘deseq2\_counts’ with a TSV file that is the optimal input for DESeq2.
Or choose advanced conditions for your samples in the ‘File/Registry’ tab through Latch Data or Latch Registry.
We recommend leaving the Output to its default location.
### Visualize differential gene expression outputs in Latch Plots
Choose the ‘Differential Gene Expression Visualizer (0.0.6)’ template.
Click on the (x) for strandedness in most cases - only use strandedness if you have an nf-core specific strandedness column in your metadata.
## Pathway Enrichment
### Launch ‘Pathway Enrichment Analysis’ Latch Workflow
Choose the ‘Pathway Enrichment Analysis’ workflow in ‘All Workflows’ or My Workflows’ (if you have added it).
Each run will have a ‘Data/Contrast’ folder with a file for every comparison created in DESeq2.
}
>
For a detailed overview of how Bulk-RNA Seq works, read our article.
# What is Bulk RNAseq?
Source: https://wiki.latch.bio/workflows/bulk-rna-seq-deep-dive
Bulk RNA-sequencing (RNA-seq) is a powerful technique for studying gene expression. By sequencing and analyzing RNA molecules within a sample—typically a collection of cells or tissues—RNA-seq allows researchers to identify and quantify the entire transcriptome. This approach enables the comparison of gene expression levels across different samples or conditions, making it possible to pinpoint differentially expressed genes that may be linked to specific biological processes or diseases.
Beyond identifying individual genes, bulk RNA-seq offers a comprehensive view of gene expression, uncovering entire pathways or networks of genes involved in various biological functions. Additionally, it can reveal novel transcripts or splice variants that may have been previously unannotated, providing deeper insights into the complexity of the transcriptome.
On this page, we will discuss important technical concepts needed during bioinformatics processing of Bulk RNA-seq data. These concepts will be discussed in order of an actual end-to-end run.
## Quantification
### Data Trimming
RNA sequencing data often contains unwanted adapter sequences and low-quality regions that need to be removed before analysis. Tools like **TrimGalore!** or **fastp** are used to trim these regions, ensuring that the data is clean and ready for accurate downstream analysis.
### Data Filtering
After trimming, depending on the quality of the data, it may be important to filter out any remaining contaminants and irrelevant sequences. **BBSplit** can be employed to remove potential contaminants from other genomes, while **SortMeRNA** can be used to specifically eliminate ribosomal RNA.
### Alignment and Quantification
#### Traditional Alignment and Quantification
Traditional alignment methods map RNA sequences (reads) to a reference genome, providing a precise, base-by-base alignment of each read to a specific location in the genome. This process is computationally intensive but results in a highly accurate mapping, which is crucial for downstream analyses that require detailed positional information. Methods implemented in the nf-core/rnaseq pipeline on Latch are:
**STAR (Spliced Transcripts Alignment to a Reference)** is a highly efficient aligner that performs full, base-by-base alignment of RNA sequences to the reference genome. STAR is specifically optimized for RNA-seq data, handling spliced reads effectively by mapping them across exon-exon junctions. This accurate mapping is crucial for identifying splice variants and other complex RNA features.
After alignment, **Salmon** is used to quantify transcript levels. Salmon takes the aligned reads (in BAM format) and estimates transcript abundances by considering the positional information provided by STAR. This approach ensures that the quantification is based on reads that are accurately mapped to specific transcript regions, providing reliable gene expression estimates.
Similar to the STAR + Salmon method, STAR performs the initial alignment. However, **RSEM (RNA-Seq by Expectation-Maximization)** is then used for transcript quantification. RSEM employs probabilistic models to assign reads to transcripts, taking into account uncertainties that arise from overlapping transcripts. This method provides detailed quantification at both the gene and isoform levels, making it particularly valuable for analyzing complex transcriptomes with multiple isoforms.
**HISAT2** is another aligner optimized for speed and memory efficiency. It uses a hierarchical indexing strategy to quickly align reads to the reference genome, making it well-suited for large datasets or environments with limited computational resources. However, in this workflow, HISAT2 is used without subsequent quantification, typically serving as a fast, standalone alignment tool for applications where only the alignment is needed.
#### Pseudo-alignment and Quantification
Pseudo-alignment methods offer an efficient alternative to traditional alignment by mapping reads to a set of transcripts they likely originate from, without assigning them to exact genomic positions. While this approach is faster and less computationally intensive, it still maintains a high level of accuracy in quantifying gene and transcript expression.
In practice, pseudo-alignment provides results comparable to traditional methods for many RNA-seq analyses, particularly when the focus is on expression quantification rather than detailed genomic features. This makes pseudo-alignment well-suited for large-scale studies or when computational resources are limited.
**Salmon** in its pseudo-alignment mode directly quantifies gene expression without performing a full alignment. It matches RNA sequences to a reference transcriptome by identifying k-mers (short, fixed-length sequences) that are unique to specific transcripts. This method efficiently determines the potential origin of each read based on these k-mers, quickly estimating transcript abundances.
**Kallisto** operates similarly to Salmon, using a k-mer-based approach to match reads to a transcriptome. It constructs an index of k-mers from the reference transcripts and uses this index to rapidly assign reads to potential transcripts. Kallisto’s algorithm is highly efficient, allowing for fast quantification of gene expression across large datasets.
### Alignment Post-Processing
After alignment, the data undergoes additional processing to ensure accuracy and reliability.
**SAMtools** is used to sort and index the aligned sequences, making them more manageable for downstream analysis.
**UMI-tools** and **Picard MarkDuplicates** are then employed to identify and mark duplicate reads. These duplicates can arise from true biological duplication, especially in highly expressed genes, or from PCR amplification during library preparation.
In RNA-seq data, it is generally not recommended to remove these duplicates unless unique molecular identifiers (UMIs) are used, as they can represent true biological signals. The pipeline, therefore, marks duplicates to gauge the overall level of duplication, but does not remove them by default unless UMIs are used or the `--skip_markduplicates parameter` is explicitly specified.
### Quality Control (QC) Statistics
To ensure the integrity and accuracy of the data, multiple quality control tools are applied:
* **FastQC** provides an initial quality check on raw reads.
* **RSeQC** and **Qualimap** offer metrics on RNA-seq data quality and alignment accuracy.
* **dupRadar** assesses the level of duplication in the data.
* **Preseq** estimates library complexity, helping predict how much sequencing would be needed for deeper coverage.
* **featureCounts** measures read counts relative to gene biotypes.
* **DESeq2** generates PCA plots and pairwise distance heatmaps to assess sample similarity and quality.
Finally, MultiQC consolidates all QC results into a single, comprehensive report, making it easier to review and interpret the quality metrics.
### Transcript Assembly and Quantification
**StringTie** is used to assemble transcripts from aligned RNA sequences and quantify their expression levels. It utilizes a novel network flow algorithm to reconstruct full-length transcripts, including multiple splice variants for each gene locus. StringTie also offers an optional de novo assembly step to identify novel transcripts.
### Coverage File Creation
To visualize how the RNA sequences cover the genome, **BEDTools** and **bedGraphToBigWig** are used to generate coverage files. These files can be viewed in genome browsers, allowing researchers to assess the distribution and depth of sequencing coverage across the genome.
Refer to [https://nf-co.re/rnaseq/3.14.0/docs/output/](https://nf-co.re/rnaseq/3.14.0/docs/output/) for more information.
## Differential Gene Expression
### Input Matrix
The input matrix used for differential gene expression analysis is the .merged.gene\_counts\_length\_scaled.tsv file from the nf-core/rnaseq pipeline. This matrix contains gene counts that have been bias-corrected and scaled by transcript length, making it well-suited for analyses where variations in transcript length across samples need to be accounted for.
### Model Fitting
For differential gene expression analysis, DESeq2 is employed. The process involves the following steps:
* **Model Building:** DESeq2 constructs a statistical model using the observed count data from the input matrix. This model captures the relationship between gene expression levels and the experimental conditions being studied.
* **Parameter Estimation:** DESeq2 uses a method called maximum likelihood estimation to find the parameter values that best fit the observed data. These parameters describe the underlying distribution of gene expression levels.
* **Shrinkage Estimation:** After parameter estimation, DESeq2 applies a Bayesian shrinkage technique to adjust the estimates of gene expression. Genes with low information content (i.e., genes with low expression or high variability) have their estimates pulled towards the overall average, while genes with high information content are adjusted minimally. This shrinkage process improves the stability and reliability of the differential expression estimates, making them more robust for downstream analysis.
* **Significance Testing:** Finally, DESeq2 performs statistical tests to determine which genes are differentially expressed between conditions, accounting for multiple testing to control the false discovery rate.
### Visualization
Several types of plots are generated to visualize the results of the differential gene expression analysis:
* **Volcano Plots:** Volcano plots display the relationship between fold-change (fold-change refers to the ratio of expression levels between two conditions; it indicates how much a gene's expression has increased or decreased) and statistical significance for each gene, highlighting those that are both highly differentially expressed and statistically significant. These plots help in identifying key genes of interest.
* **MA Plots:** MA plots show the relationship between the average expression (mean) and the log2 fold-change for each gene. This visualization helps to identify systematic biases in the data and to see how expression levels vary across the experiment.
* **Heatmaps:** Heatmaps are used to visualize the expression patterns of the top differentially expressed genes across all samples. They provide a clear overview of how gene expression varies between conditions, often revealing clusters of co-regulated genes.
* **PCA Plots:** Principal Component Analysis (PCA) plots are generated to assess the overall similarity and variability between samples based on their gene expression profiles. These plots help to identify potential batch effects or outliers and to see how well samples group according to the experimental conditions.
## Pathway Enrichment
### Input Matrix
The input for pathway enrichment analysis is derived from the contrast files output from differential gene expression (DGE) results. These files contain log2 fold changes, p-values, and adjusted p-values (FDR) for each gene between the two conditions being compared in the contrast file.
### Methods
The analysis employs two main methods to identify enriched pathways:
* **Gene Set Enrichment Analysis (GSEA):** This method ranks all genes based on their expression changes and tests whether predefined gene sets (e.g., pathways) are overrepresented at the extremes (top or bottom) of this ranked list. GSEA is particularly useful for detecting subtle but coordinated changes in gene expression across a pathway.
* **Over Representation Analysis (ORA):**
* **Upregulated ORA:** Focuses on the subset of genes that are significantly upregulated, testing whether these genes are overrepresented in known biological pathways or functions.
* **Downregulated ORA:** Similarly, this analysis identifies pathways that are significantly enriched with downregulated genes.
### Databases
The analysis utilizes several key databases for pathway and function enrichment:
* **KEGG (Kyoto Encyclopedia of Genes and Genomes):** A comprehensive resource that links genomic information with higher-order functional information, providing detailed pathway maps that are widely used in biological research.
* **Gene Ontology (GO):** A standardized system that organizes genes into hierarchical categories based on three main aspects: biological process, molecular function, and cellular component. It allows for the annotation and analysis of gene functions across species.
* **Molecular Signatures Database (MSigDB):** A collection of annotated gene sets designed for use with GSEA. It helps to identify and characterize biological processes and pathways that are enriched in specific experimental conditions.
* **WikiPathways:** An open-source platform where pathways are curated by the scientific community. It offers a wide range of pathways that can be analyzed for gene enrichment.
* **Disease Ontology:** A structured classification that standardizes the representation of diseases. It is used to link gene expression changes to disease-related pathways and processes.
### Visualization
The results of the pathway enrichment analysis are visualized using various plot types to facilitate interpretation:
* **Dot Plots:** Show the significance and gene ratio of enriched pathways.
* **Cnet Plots (Category Net Plots):** Visualize the relationship between genes and pathways, showing how different genes contribute to the enrichment of multiple pathways.
* **Heat Plots:** Highlight the expression patterns of key genes across different pathways, providing insights into how gene expression changes are coordinated within these pathways.
* **Tree Plots:** Display hierarchical clustering of enriched pathways, revealing the similarity and relationships between different pathways based on gene overlap.
* **Emap Plots (Enrichment Map Plots):** Show the network of enriched pathways, allowing for the visualization of pathway interconnections based on shared genes.
* **Bar Plots:** Represent the top enriched pathways with bar height corresponding to significance or gene ratio.
* **Ridge Plots:** Display the distribution of gene expression changes across pathways, highlighting the enrichment patterns for GSEA results.
}
>
For detailed intructions on using Bulk RNA-Seq, read our tutorial here.
# CAS-OFFinder
Source: https://wiki.latch.bio/workflows/cas-offinder
CAS-OFFinder is an algorithm that searches for potential off-target sites of Cas9 RNA-guided endonucleases. It is one of the most highly cited & consistent tools for this purpose.
## How to run CAS-OFFinder on Latch
1. **Add CAS-OFFinder to your Workspace**
1. Find CAS-OFFinder in "All Workflow" in the Workflows tab and click Add to add it to your workflows
2. Open CAS-OFFinder in "Workflows" by selecting and clicking Openew or double clicking it
2. **Enter parameters for Cas-OFFinder**
1. First add your Spacers, these should be your guide RNA sequences without the PAM
2. Select your Target Genome from the list
3. Select your PAM based on the protein you are using in your experiment
4. Specify the mismatch number, when selecting this number it should be the total number of mismatches between your query sequence and target genome that you are ok with.
5. Then fill out the Output Location and click Launch Workflow.
3. **Within no time your results will show up in the Data tab!**
## Parameters
### Spacers
* This is your guide RNA sequences without the PAM (e.x. no NGG for SpCas9)
* These are your crRNA sequences you are searching for in your target genome
* Enter these query sequences (5' to 3'), one sequence per line.
* Please write crRNA sequences without PAMs.
* The length of each query sequence should be between **15 and 25 nt, and all be the same length**.
* Please note that large number of bulge size will significantly increase the calculation time!
* [Mixed bases](http://www.rgenome.net/cas-offinder/portable#mixedbases) are allowed.
* The count of query sequence must be less than 1000.
* Example Value: SpCas9 from Streptococcus pyogenes: 5'-NGG-3'
### Target Genome
* Your genome of interest
### PAM
* PAM is a Protospace Adjacent Motif. Every RGEN (RNA-Guided Endonuclease) has it's own unique PAM. For example, Cas9 uses 'NGG. Select your PAM based on the protein you are using in your lab.
* Example Value: SpCas9 from Streptococcus pyogenes: 5'-NGG-3'
### Mismatch Number
* The number of allowed mismatches between query & target genome. This is important as this parameter affects the prediction results significantly. When selecting this number it should be the total number of mismatches between your query sequence and target genome that you are ok with.
* Note: As the number of mismatches increases, the total number of potential off-target sites dramatically increases as well.
### Output Location
* The directory where the files produced by this workflow will be placed. A path can either be selected or if a new path is typed in field Latch will automatically create the folders in the data viewer.
## Outputs
| Id | Bulge type | CrRNA | DNA | Chromosome | Location | Direction | Mismatches | Bulge Size |
| ---- | ---------- | ------------------------- | ------------------------- | ---------- | -------- | --------- | ---------- | ---------- |
| Seq1 | DNA | GGCCGACCTGTCGCTGA--CGCNNN | GGCCGtCCTGTtGCTGAGACtCGGG | chr1 | 17408102 | - | 3 | 2 |
| Seq2 | RNA | CGCCAGCGTCAGCGACGAAGGTNNN | tGCCAGCGgCAGCGA-GAAGtTTAG | chr1 | 8462729 | + | 3 | 1 |
| ... | | | | | 0 | | 0 | 0 |
| Seq2 | DNA | CG--CCAGCGTCAGCGACAGGTNNN | CaCTCCAGCcTCAGCGACAGGcAAG | chr1 | 18173251 | - | 3 | 2 |
| Seq2 | RNA | CGCCGCAGCGTCAGCGACAGGTNNN | CGC-GCAGCGaCAGgGAgAGGTGAG | chr1 | 1273663 | - | 3 | 1 |
| Seq1 | DNA | GGCCGACCTGTCGCT--GACGCNNN | GGCCGtCCTGTtGCTGAGACtCGGG | chr1 | 17408102 | - | 3 | 2 |
| Seq2 | RNA | CGCCAGCGTCGTAGCGACAGGTNNN | CGCCtGCGg-GgAGCtACAGGTGAG | chr1 | 18888560 | - | 3 | 1 |
| Seq1 | DNA | GGCCGACC--TGTCGCTGACGCNNN | GGCCcAgCTCTGTCGCTGACGgGAG | chr1 | 40979785 | - | 3 | 2 |
| Seq2 | DNA | C--GCCAGCGTCAGCGACAGGTNNN | CACtCCAGCcTCAGCGACAGGcAAG | chr1 | 18173251 | - | 3 | 2 |
| Seq1 | DNA | GGCCGACCTGTCGCTG--ACGCNNN | GGCCGtCCTGTtGCTGAGACtCGGG | chr1 | 17408102 | - | 3 | 2 |
| Seq2 | DNA | CGC--CAGCGTCAGCGACAGGTNNN | CaCTCCAGCcTCAGCGACAGGcAAG | chr1 | 18173251 | - | 3 | 2 |
| Seq2 | RNA | CGNCCCAGCGTCAGCGACAGGTNNN | t-CtCCAGCcTCAGCGACAGGcAAG | chr1 | 18173254 | - | 3 | 1 |
| Seq2 | RNA | CGCCAGCGTCAGCGGCACAGGTNNN | CcCCAGaGTCAGC-GCACAGaTGGG | chr1 | 4006295 | - | 3 | 1 |
| Seq2 | RNA | CGCCGCAGCGTCAGCGACAGGTNNN | CG-CGCAGCGaCAGgGAgAGGTGAG | chr1 | 1273663 | - | 3 | 1 |
| Seq2 | RNA | CGCCAGCGTCGCAGCGACAGGTNNN | aGCCAGCt-CtCAGCGACAGcTGAG | chr1 | 91631879 | - | 3 | 1 |
| Seq2 | RNA | CGNCCCAGCGTCAGCGACAGGTNNN | C-CCCCAGtGTCActGACAGGTGGG | chr1 | 5502832 | - | 3 | 1 |
| ... | | | | | 0 | | 0 | 0 |
| Seq2 | DNA | CGCCAGCGTCAGCGACAGG--TNNN | CcCCAGtGTCAGCcACAGGGCTCAG | chr1 | 34978273 | - | 3 | 2 |
| Seq2 | RNA | CGCCAGCGTCGCAGCGACAGGTNNN | CGCCtGCG-CGgAGCtACAGGTGAG | chr1 | 18888560 | - | 3 | 1 |
| Seq2 | X | CGCCAGCGTCAGCGACAGGTNNN | CtCCAGCcTCAGCGACAGGcAAG | chr1 | 18173253 | - | 3 | 0 |
# CRISPOR
Source: https://wiki.latch.bio/workflows/crispor
[CRISPOR](http://crispor.org/) is a website that helps select and express CRISPR guide sequences, described in two papers ([Gen Biol 2016](https://genomebiology.biomedcentral.com/articles/10.1186/s13059-016-1012-2) and [NAR 2018](https://academic.oup.com/nar/article/46/W1/W242/4995687)). In its default mode, the user pastes an input DNA sequence and chooses the genome.
CRISPOR is made to be fast and easy on Latch. If anything is confusing, you may refer to Maximilian's excellent documentation [here](http://crispor.tefor.net/manual/manual.html#enzymes).
## How to run CRISPOR on Latch
1. **Add CRISPOR to your Workspace**
1. Find CRISPOR in "All Workflows" and open the workflow
2. **Enter the parameters for CRISPOR**
1. Enter a single genomic sequence, \< 2300 bp, typically an exon
1. NOTE: Text case is preserved (e.g. ATCG & atcg both work)
2. You can paste multiple sequences >23bp, separated by N characters.
3. Avoid using cDNA sequences as input, CRISPR guides that straddle splice sites are unlikely to work.
2. Select your genome
1. Select from 704 different genomes! Contact CRISPOR support if yours is missing.
2. Find links to pre-calculated exonic guides for each genome here on the UCSC genome browser.
3. Select a Protospacer Adjacent Motif (PAM)
1. Select from \~40 options
2. Support for cas9, cas12, casX, & many more
3. See notes on enzymes for more info
4. Then select the Output Location and click Launch Workflow.
3. **Within no time your results will show up in the Data tab!**
## Parameters
### Sequence Name
* Just a semantic name for your sequence data
### Sequence
* Enter a single genomic sequence, `<2300` base pairs, typically an exon
### PAM
* Protospacer Adjacent Motif (PAM)
* For most current applications of the CRISPR-Cas system, Streptococcus pyogenes Cas9 nuclease is used and the corresponding PAM is NGG.
* However, you can choose other enzymes and corresponding PAMs from the dropdown box.
### Genome
* Select your genome of interest from the list
### Output Location
* The directory where the files produced by this workflow will be placed. A path can either be selected or if a new path is typed in field Latch will automatically create the folders in the data viewer.
## Outputs
### Output 1: Annotated input sequence
The main output of CRISPOR is a page that shows the annotated input sequence at the top and the list of possible guides in the input sequence at the bottom.
4.6KB
Shown below the input sequence are the guide target sequences, one per PAM. For spCas9, the PAM is NGG and the targets are 20bp long.
Column 1 - guide name
* this is the position of the PAM on the input sequence and the strand, e.g. “13+”
Column 2 - guide sequence
* the sequence of the guide target and the PAM and the link to its “PCR and cloning primers” (see the [Primers section](http://crispor.tefor.net/manual/#primers)
Column 3 - specificity score
* a prediction of how much an RNA guide sequence for this target may lead to off-target cleavage somewhere else in the genome.
Column 4 - efficiency scores
* the efficiency score is a prediction of how well this target may be cut by its RNA guide sequence.
Column 5 - out-of-frame score
* this score (0-100) is a prediction how likely a guide is to lead to out-of-frame deletions.
Column 6 - off-target mismatch counts
* the number of possible off-targets in the genome, for each number of mismatches.
Column 7 - off-targets
* the locations of all possible off-targets with up to four mismatches, annotated with additional information
# CRISPResso2
Source: https://wiki.latch.bio/workflows/crispresso2
CRISPResso2 is a software pipeline for the analysis of genome editing experiments. It is designed to enable rapid and intuitive interpretation of results produced by amplicon sequencing.
Briefly, CRISPResso2
* aligns sequencing reads to a reference sequence
* quantifies insertions, mutations and deletions to determine whether a read is modified or unmodified by genome editing
* summarizes editing results in intuitive plots and datasets
## How to run CRISPResso2 on Latch
1. **Open CRISPResso2**
1. Find CRISPResso2 in "All Workflows" and open the workflow
2. **Enter the parameters for CRISPResso2**
1. First add your **Fastq read files**, make sure they have been uploaded to Latch in the Data tab and then you can select them in the modal.
1. If your files are **single end reads** then you only have to select a file for the Read 1 parameter.
2. If the file you selected is **interleaved** (paired end reads in a single fastq file) make sure to enable the *Read 1 is Interleaved* parameter.
3. If you have **paired end reads** then make sure to also select a file for the Read 2 parameter.
2. The add the **Amplicon Sequences** used, if you have multiple click the plus button to add an additional sequences .
1. You can add a name for each amplicon sequence given. If you have multiple amplicon make sure the number and order of the names correspond to the amplicons given above. By default CRISPResso uses "Reference" as the amplicon sequence name.
3. *(Optional)* Then add your **Guide Sequences** (sgRNA).
1. Same as with amplicons, you can add a name for each guide sequence given. If you have multiple guides make sure the number and order of the names correspond to the guides given above.
4. Then fill out the Output Prefix and Output Location and click Launch Workflow.
3. **Within no time your results will show up in the Data tab!**
## FYI
* If you want to run multiple executions of this workflow click the large plus button at the bottom of the parameters to add an additional execution of the count workflow.
* We have hidden many of the optional parameters under Hidden Parameters, you can click that if you would like to fine tune your execution run or want to use any of the advanced parameters.
## Main Parameters
### Read 1
* The first FastQ file, if this is the only Fastq file put as an input CRISPResso will assume it contains single end reads and run it as such.
### Read 1 is Interleaved
* Marks the file in Read 1 as containing interleaved reads. CRISPResso will split the paired end reads into two files before running. Do not enable this if Read 2 has an input.
### Read 2
* The second Fastq file for paired end reads, if both Read 1 and Read 2 contain Fastq files CRISPResso will assume they contain paired end reads and run it as such.
### Amplicon Sequence
* A name for the reference amplicon can be given. If multiple amplicons are given, multiple names can be specified here.
### Amplicon Name (optional)
* A name for the reference amplicon can be given, multiple names can be specified here and the order must correspond to the amplicon sequences given above.
* By default it is just named "Reference" is used.
### Guide Sequence (sgRNA) (optional)
* sgRNAs should be input as the guide RNA sequence (usually 20 nt) immediately adjacent to but not including the PAM sequence (5' (left) of NGG for SpCas9). If the sgRNA is not provided, quantification may include modifications far from the predicted editing site and may result in overestimation fo editing rates.
### Guide Sequence (sgRNA) Name (optional)
* A name for the guide sequence can be given. Multiple names can be specified here and the order must correspond to the guide sequences given above.
* By default it is just named "sgRNA" is used.
### Output Name
* The output name of the html report and files.
### Output Location
* The directory where the files produced by this workflow will be placed. A path can either be selected or if a new path is typed in field Latch will automatically create the folders in the data viewer.
## Hidden Parameters
### Amplicon and Read Matching
### Minimum Homology % For Alignment to an Amplicon
* Sequences must have at least this homology percentage score with the amplicon to be aligned. After reads are aligned to a reference sequence, the homology is calculated as the number of bp they have in common. If the aligned read has a homology less than this parameter, it is discarded. This is useful for filtering erroneous reads that do not align to the target amplicon, for example arising from alternate primer locations.
* Default: 60%
## sgRNA Settings
### Discard Guide Positions that Extend Beyond end of Amplicon
* If set, for guides that align to multiple positions, guide positions will be discarded if plotting around those regions would included bp that extend beyond the end of the amplicon.
### Quantification Window Center \[Base Pairs Relative to 3' of sgRNA]
* Center of quantification window to use within respect to the 3' end of the provided sgRNA sequence. Remember that the sgRNA sequence must be entered without the PAM. For cleaving nucleases, this is the predicted cleavage position.
* Example Values
* Cas9: -3 (Which is the CRISPResso Default)
* Cpf1: 1
* Base Editors: -17
### Quantification Window Size
* Defines the size (in bp) of the quantification window extending from the position specified by the Quantification Window Center parameter in relation to the provided guide RNA sequences. Mutations within this number of base pairs from the quantification window center are used in classifying reads as modified or unmodified. For example setting this to 1bp extends the window on each side of the cleavage position for a total length of 2bp. Disabling this window (setting it to 0) causes all indels in the entire amplicon to be considered.
* Example Values
* Cas9: 1 (Which is the CRISPResso Default)
* Cpf1: 1
* Base Editors: 10
### Plot Window Size
* This defines the size of the window extending from the quantification window center to plot. Nucleotides within the *Plot Window Size* of the *Quantification Window Center* for each guide are plotted.
* Default is 20
### Ignore Substitutions
* Enabling this causes substitutions events for the quantification and visualization to be ignored.
### Ignore Insertions
* Enabling this causes insertion events for the quantification and visualization to be ignored.
### Ignore Deletions
* Enabling this causes deletion events for the quantification and visualization to be ignored.
### Ignore Indel Reads
* Enabling this causes reads with indels in the quantification window to be discarded from the analysis.
## Prime Editing Parameters
### Spacer Sequence
* Include this instead of sgRNA when doing analysis on Prime Editing. pegRNA spacer sgRNA sequence used in prime editing. The spacer should not include the PAM sequence. The sequence should be given in the RNA 5'->3' order, so for Cas9, the PAM would be on the right side of the given sequence.
### Extension Sequence
* Extension sequence used in prime editing. The sequence should be given in the RNA 5'->3' order, such that the sequence starts with the RT template including the edit, followed by the Primer-binding site (PBS).
### pegRNA Extension Quantification Window Size
* Quantification window size (in bp) at flap site for measuring modifications anchored at the right side of the extension sequence. Similar to the **Quantification Window** parameter, the total length of the quantification window will be 2x this parameter.
* Default: 5bp (so a 10bp total window size)
### Nicking sgRNA
* The nicking sgRNA sequence used in prime editing. The sgRNA should not include the PAM sequence. The sequence should be given in the RNA 5'->3' order, so for Cas9, the PAM would be on the right side of the sequence.
### Scaffold Sequence
* If given, reads containing any of this scaffold sequence before the Prime Editing *Extension Sequence* will be classified as 'Scaffold-incorporated'. The sequence should be given in the 5'->3' order such that the RT template directly follows this sequence. A common value ends with 'GGCACCGAGUCGGUGC'.
### Specify Prime Edited Reference Sequence
* If given, this sequence will be used as the prime-edited reference sequence. This may be useful if the prime-edited reference sequence has large indels or the algorithm cannot otherwise infer the correct reference sequence.
## Base Editing Parameters
### Base Editing Output
* Enable this when doing analysis on Base Editing. Will output plots showing the frequency of substitutions in the quantification window are generated. The target and result bases can also be set to measure the rate of on-target conversion at bases in the quantification window.
### Base Editor Target Base
* For base editor plots, this is the nucleotide targeted by the base editor.
* Default: C
### Base Editor Output Base
* For base editor plots, this is the nucleotide produced by the base editor.
* Default: T
## Optional Settings
### Include HDR Sequence
* Amplicon sequence expected after HDR. The expected HDR amplicon sequence can be provided to quantify the number of reads showing a successful HDR repair.
### Include Exon Coding Sequence
* Subsequences of the amplicon sequence covering one or more coding sequences for frameshift analysis. Sequences of exons within the amplicon sequence can be provided to enable frameshift analysis and splice site analysis by CRISPResso2. Users should provide the subsequences of the reference amplicon sequence that correspond to coding sequences and not the whole exon sequences.
## Quality Filtering
### Minimum Average Read Quality
* Minimum average quality score (phred33) to keep a read.
* Default: No Filter (0)
### Minimum Single Base Pair Quality
* Minimum single bp score (phred33) to keep a read
* Default: No Filter (0)
### Replace Bases With N That Have a Quality Lower Than
* Bases with a quality score (phred33) less than this value will be set to "N".
* Default: No Filter (0)
## Base Pair Exclusion From Amplicon Sequence for Quantification of Mutations
### Base Pairs Excluded from the Left Side
* Exclude bp from the left side of the amplicon sequence for the quantification of the indels.
### Base Pairs Excluded from the Right Side
* Exclude bp from the right side of the amplicon sequence for the quantification of the indels.
## Trimmomatic Trimming
### Enable Trimming Adaptor
* Enable the trimming of Illumina adapters with Trimmomatic. By default this uses the conda-installed trimmomatic.
## Alignment
### Expand Ambiguous Alignments
* If more than one reference amplicon is given, reads that align to multiple reference amplicons will count equally toward each amplicon. Default behavior is to exclude ambiguous alignments.
### Needleman Wunsch Gap Open
* Gap open option for Needleman-Wunsch alignment.
* Default: -20
### Needleman Wunsch Gap Incentive
* Gap incentive value for inserting indels at cut sites.
### Needleman Wunsch Gap Extend
* Gap extend option for Needleman-Wunsch alignment.
## FLASH Merging
### Minimum Length Required for Confident Overlap Between Two Reads
* Parameter for the FLASH read merging step. Minimum required overlap length between two reads to provide a confident overlap.
* Default: 10
### Maximum Overlap Length Expected in \~90% of Read Pairs
* Maximum overlap length expected in approximately 90% of read pairs. Please see the FLASH manual for more information.
* Default: 100
### Use Stringent Flash Merging
* Use stringent parameters for flash merging. In the case where flash could merge R1 and R2 reads ambiguously, the expected overlap is calculated as `2 \* Average Read Length - Amplicon Length`.
* The flash parameters for for minimum and maximum overlap above will be set to prefer merged reads with length within 10bp of the expected overlap. These values override the *Minimum Length Required for Confident Overlap Between Two Reads* or *Minimum Overlap Length Expected in \~90% of Read Pairs* CRISPResso parameters.
## Report Settings
### Plot Histogram Outliers
* If set, all values will be shown on histograms. By default (if unset), histogram ranges are limited to plotting data within the 99 percentile.
## Allele Plot Parameters
### Maximum Rows Reported in the Alleles Table
* Maximum number of rows to report in the alleles table plot.
### Minimum % Reads Required To Report an Allele in Table Plot
* Minimum % reads required to report an allele in the alleles table plot. This parameter only affects plotting. All alleles will be reported in data files.
### Annotate Wildtype Allele
* Wildtype alleles in the allele table plots will be marked with this string (e.g. \*\*).
### Show Percentage As Reads Aligned to Assigned Reference
* If set, in the allele plots, the percentages will show the percentage as a percent of reads aligned to the assigned reference. Default behavior is to show percentage as a percent of all reads.
### Include Alignment Scores for Each Read Sequence in Allele Table
* If set, a detailed allele table will be written including alignment scores for each read sequence.
### Force Allele Plot and Allele Table To Be the Same
* If set, alleles with different modifications in the quantification window (but not necessarily in the plotting window (e.g. for another sgRNA)) are plotted on separate lines, even though they may have the same apparent sequence. To force the allele plot and the allele table to be the same, set this parameter. If unset, all alleles with the same sequence will be collapsed into one row.
## Output Settings
### Output FastQ File for Each Read
* If set, a fastq file with annotations for each read will be produced.
### Use CRISPResso1 Output Mode
* Output as in CRISPResso1. In particular, if this flag is set, the old output files 'Mapping\_statistics.txt', and 'Quantification\_of\_editing\_frequency.txt' are created, and the new files 'nucleotide\_frequency\_table.txt' and 'substitution\_frequency\_table.txt' and figure 2a and 2b are suppressed, and the files 'selected\_nucleotide\_percentage\_table.txt' are not produced when Base Editor Output is enabled.
### Place Report in Same Folder as Output Data
* If true, report will be written inside the CRISPResso output folder. By default, the report will be written one directory up from the report output.
### Set File Prefix For Plots and Tables
* File prefix for output plots and table.
### Plot Output as PDF Only
* Suppress output report, plots output as .pdf only (not .png).
### Suppress Output Plots
* Suppress output plots.
## Miscellaneous Parameters
### Read 1 (BAM)
* Aligned reads for processing in bam format. This parameter can be given instead of fastq\_r1 to specify that reads are to be taken from this bam file. An output bam is produced that contains an additional field with CRISPResso2 information.
### BAM Chromosome Location
* Chromosome location in bam for reads to process. For example: "chr1:50-100" or "chrX".
### Include dsODN Sequence
* Reads containing the dsODN are labeled and quantified.
## Outputs
The output of CRISPResso2 consists of a set of informative graphs that allow for the quantification and visualization of the position and type of outcomes within an amplicon sequence.
The main output file is **CRISPResso2\_report.html** which is a summary report that can be viewed in a web browser containing all of the output plots and summary statistics.
You can view a more detailed explanations of the outputs at the CRISPResso Manual.
## More Resources
* [Source on Github](https://github.com/pinellolab/CRISPResso2)
* [CRISPResso Manual](https://crispresso.pinellolab.partners.org/help)
# CSV Parameter Import
Source: https://wiki.latch.bio/workflows/csv-import
Every workflow in Latch allows you to import a CSV containing values for its parameters. This is another way to import data when doing bulk runs of a workflow.
The goal of this feature is intended to streamline bringing in your experiment
data when running workflows into Latch and we would love to hear from you on
ways this could be improved. And to be completely honest the best way to use
the CSV import is to write a script that will automatically generate a CSV
based on your data.
## Preparing Your CSV
* Each row of the CVS will be imported as one run of the workflow and each column for that row will be imported to its corresponding parameter.
* Each parameter has a column name that the importer can use automatically map them (we don't expose these anywhere yet but we're working on it), but CSV columns can also be mapped manually to a parameter.
* Each parameter has specific formatting requirements to be properly imported. (I'm gonna work on the documentation for all of the formatting standards because this can be a pain to get right.)
* If you're exporting it from a spreadsheet application you're using here are some guides:
* [Excel](https://support.microsoft.com/en-us/office/import-or-export-text-txt-or-csv-files-5250ac4c-663c-47ce-937b-339e391393ba)
* [Numbers](https://support.apple.com/guide/numbers/export-to-excel-or-another-file-format-tan3b922d4ad/mac)
* [Google Sheets](https://support.airtable.com/hc/en-us/articles/203423579-How-to-export-a-spreadsheet-from-another-source)
### Adding File Paths to your CSV
If one of the columns in your CSV requires a file path, you have to ensure that the file path matches that on Latch.
## Using CSV Import
CSV Import is not available for Bulk RNAseq, which instead has the option of using Salmon’s selective alignment method and sample conditions for differential expression analysis.
Some Workflows also have a CSV template you can use to import your data.
or select from your computer
When a column is matched to a parameter it will either show:
1. A green check mark which means all of values in that column have passed the validation and are formatted correctly for that parameter.
— or —
2. A red warning triangle which means that some of the data in the matched column is formatted incorrectly for that parameter.
Any errors can be fixed in the next step.
If the importer is unable to automatically match a column it won't display any icon. You can manually map it to a parameter by clicking the input and selecting its corresponding parameter.
Any cells with errors will be marked with a red warning triangle which you can hover over to view details on the formatting error. You click into the cell to edit and fix any errors before importing.
# MAGeCK - Count
Source: https://wiki.latch.bio/workflows/mageck-count
This is the count sub command from MAGeCK. This subcommand collects sgRNA read count information from fastq files or raw count files. The output count table can be used directly in the [MAGeCK Test](https://latch.wiki/mageck-test) or the [MAGeCK MLE](https://latch.wiki/mageck-mle) workflow.
## How to run MAGeCK Count on Latch
1. Find MAGeCK Count in your Workspace
1. Find **MAGeCK Count** in "All Workflows" and open the workflow
2. **Enter the parameters for MAGeCK Count**
1. First add your Sample Labels, the labels you add should correspond to the Sample FastQ files you will give MAGeCK. Ex. "L1", "CTRL"
2. Then add your Sample FastQ file, these should correspond order wise to the Sample Labels you gave in the previous step.
1. If you have technical replicates for a sample, add them within the same box.
3. Then select your List Sequence File.
1. You can learn more about the format of this file below.
4. Then fill out the Output Prefix and Output Location and click Launch Workflow.
3. **Within no time your results will show up in the Data tab!**
### FYI
* If you want to run multiple executions of this workflow click the large plus button at the bottom of the parameters to add an additional execution of the count workflow.
* We have hidden many of the optional parameters under Hidden Parameters, you can click that if you would like to fine tune your execution run or want to use any of the advanced parameters.
## Required Parameters
### Sample Labels
* The labels of each sample, these labels will be used to specify whether the samples are treatment or control in later MAGeCK steps
* This defaults to sample1, sample2, etc… but would recommend specifying them yourself in this step as they are needed in later subcommands.
### Fastq reads for each sample
* The reads for each sample and should correspond to each sample label, each sample can have Technical Replicates added as well.
* Accepted Files
* fastq
* fastq.gz
* SAM/BAM
*FYIs for Fastqs*
* If the sample reads are paired ends, the *2nd Fastq can be added to 2nd FastQ for Paired End Reads* in the hidden parameters accordion. The files given here must correspond orderwise to the files given in the first Fastq parameter.
* If you have Biological Replicates treat them as separate samples in MAGeCK Count and then you will be able to specify them as such in the MAGeCK Test and MAGeCK MLE steps when doing analysis.
### List Sequence File
* A file containing the list of sgRNA names, their sequences and associated genes. When starting from FASTQ, FASTQ.GZ or BAM files, MAGeCK needs to know the sgRNA sequences and targeting genes.
* Accepted Files
* .tsv
* .csv
* .txt with tab or comma separated values
* Example: - You can download (right click to download) an example txt tab separated library file here:
87.7KB
* There are three columns in the library file: the sgRNA ID, the sequence, and
the gene it is targeting.
| sgRNA ID | Sequence | Gene |
| -------- | -------------------- | ----- |
| s\_10007 | TGTTCACAGTATAGTTTGCC | CCNA1 |
| s\_10008 | TTCTCCCTAATTGCTTGCTG | CCNA1 |
| s\_10027 | ACATGTTGCTTCCCCTTGCA | CCNC |
### Output Prefix
* The prefix appended to all of the outputted files
### Output Location
* The directory where the files produced by this subcommand will be placed. A path can either be selected or if a new path is typed in field Latch will automatically create the folders in the data viewer.
## Hidden Parameters
### FastQ Parameters
### 2nd FastQs for Paired End Reads
* The 2nd fastqs for paired end reads for each sample. These should correspond to each sample label, and each sample can have technical replicates added as well.
## Quality Control Parameters
### Day Zero Label
* Specifying this will turn on the negative selection quality control and specify the label as the control sample (usually day 0 or plasmid). For every other sample label, the negative selection quality control will compare it with day0 sample, and estimate the degree of negative selections in essential genes.
### Length of 5' End Read Trimming
* Length of trimming the 5' of the reads. Default 0
### Disable Discarding of sgRNAs Containing 'N' in FastQ Reads
* Enabling this will count sgRNAs with Ns. By default, sgRNAs containing Ns are discarded by MAGeCK
* It is expected that the first few thousand reads in an Illumina sequence fastq file are of comparatively low quality and frequently contain “N”s. An “N” means that the Illumina software was not able to make a basecall for this base. The reads at the beginning and end of the sequence data files originate from the edges of the flowcells, where imaging is more difficult, thus these reads show below average quality which is why MAGeCK by default discards them.
### Reverse Complement the Sequences in Library for Read Mapping
* Enabling this has MAGeCK reverse complement the sequences in the library for read mapping. By default read mapping will be performed with the sequences as they are in the library.
### Method for Normalization
* By default MAGeCK will use Median normalization.
* Options:
* **None**: no normalization
* **Median**: median normalization, default
* **Total**: normalization by total read counts
* **Control**: normalization by control sgRNAs specified by the Control sgRNAs option. The median factor used for normalization will be calculated based on control sgRNAs only, rather than all the sgRNAs
### Control sgRNAs
* A list of control sgRNAs for normalization and for generating the null distribution of RRA. Alternatively Control Genes can be specified instead of this parameter. This option tells MAGeCK to use provided negative control sgRNAs to generate the null distribution when calculating the p values. By providing the corresponding sgRNA IDs in this parameter, MAGeCK will have a better estimation of p values.
* When using this option, you will need to provide a plain text file just containing negative control sgRNA IDS (one per each line). For example,
```
NonTargetingControlGuideForHuman_0001
NonTargetingControlGuideForHuman_0002
NonTargetingControlGuideForHuman_0003
NonTargetingControlGuideForHuman_0004
```
### Control Genes
* A list of genes whose sgRNAs are used as control sgRNAs for normalization and for generating the null distribution of RRA. Alternatively Control sgRNA can be specified instead of this parameter. There are several issues that you need to keep in mind:
* You should have enough number of negative control guides (>100 recommended) for accurate p value estimation and normalization.
* It is known that for growth based screens, non-targeting controls may lead to high false positives (e.g., [Morgens et al. 2017](https://www.nature.com/articles/ncomms15178). Use non-targeting controls carefully.
* By default MAGeCK will generate the null distribution of RRA scores by assuming all of the genes in the library are non-essential. This approach is sometimes over-conservative, and you can improve this if you know some genes are not essential.
### Use Custom Pathway File For Quality Control (GMT Format)
* The pathway file used for QC, in GMT format. By default it will use the GMT file provided by MAGeCK ([mageckQC.gmt](https://www.gsea-msigdb.org/gsea/msigdb/cards/KEGG_RIBOSOME).
* More information about GMT format can be found [here](https://software.broadinstitute.org/cancer/software/gsea/wiki/index.php/Data_formats#GMT:_Gene_Matrix_Transposed_file_format_.28.2A.gmt.29) and a repository for pathway files can be found [here](https://www.gsea-msigdb.org/).
## Output Settings
### sgRNA Length
* The length of the sgRNA. The program will automatically determine the sgRNA length from library file, so this parameter should likely be toggled off. If toggled on and given an sgRNA length, will put umapped reads to a file for viewing.
### Keep Intermediate Files
* Keeps intermediate files for this subcommand which are the .r, .rmb,.rnw files which can brought into an R software environment to plot the results of the execution
## Run Settings
### Test Run Using First 1M Records For Each File
## Outputs
### count.txt
* A tab-separated count table, each line in the table should will the sgRNA name (1st column), the targeting gene (2nd column) and the read counts in each sample. Each item will be separated by the tab ('\t').
* For example in the studies of [T. Wang et al. Science 2014](http://www.ncbi.nlm.nih.gov/pubmed/24336569), there are 4 CRISPR screening samples, and they are labeled as: HL60.initial, KBM7.initial, HL60.final, KBM7.final. Here are a few example lines of the count file:
| sgRNA | Gene | HL60.initial | KBM7.initial | HL60.final | KBM7.final |
| --------------- | ---- | ------------ | ------------ | ---------- | ---------- |
| A1CF\_m52595977 | A1CF | 213 | 274 | 883 | 175 |
| A1CF\_m52596017 | A1CF | 294 | 412 | 1554 | 1891 |
| A1CF\_m52596056 | A1CF | 421 | 368 | 566 | 759 |
| A1CF\_m52603842 | A1CF | 274 | 243 | 314 | 855 |
| A1CF\_m52603847 | A1CF | 0 | 50 | 145 | 266 |
* This count file will be used for the count table parameter in [MAGeCK Test](/wiki/workflows/mageck-test) and [MAGeCK MLE](/wiki/workflows/mageck-mle) workflows.
### count\_normalized.txt
* A normalized count file. Please forgive me as I'm not really sure what the significance of this file is, but will update this once I figure it out. Or if you can help explain this to me please contact me at [nathan@latch.bio](mailto:nathan@latch.bio).
### countsummary.txt
* This file is generated by count command, and summarizes QC measurements of the fastq (or count table) files. Learn more about it from the [MAGeCK Wiki](https://sourceforge.net/p/mageck/wiki/Home/#count_summary_txt).
### countssummary.R
* This file contains code that can be executed within the R software environment to plot the data from the count subcommand and create a PDF from it. This file can be used in a program such as [RStudio](https://www.rstudio.com/).
### countsummary.Rnw
* This file is called by the counts summary.R file and has the specific code for plotting the results.
### Log File
* This file contains all of the logs of the execution. This file is mostly a bunch of techno gobbledygook but you can view it to view any errors the execution might have encountered.
## What is MAGeCK
Model-based Analysis of Genome-wide CRISPR-Cas9 Knockout ([MAGeCK](https://genomebiology.biomedcentral.com/articles/10.1186/s13059-014-0554-4) is a computational tool to identify important genes from the recent genome-scale CRISPR-Cas9 knockout screens (or GeCKO) technology. MAGeCK can be used for prioritizing single-guide RNAs, genes and pathways in genome-scale CRISPR/Cas9 knockout screens. MAGeCK identifies both positively and negatively selected genes simultaneously and reports robust results across different experimental conditions. MAGeCK is developed and maintained by Wei Li and Han Xu from [Prof. Xiaole Shirley Liu's lab](http://liulab.dfci.harvard.edu/) at the Department of Biostatistics and Computational Biology, Dana-Farber Cancer Institute and Harvard School of Public Health. MAGeCK has been used to identify functional lncRNAs from screens with close to [100% validation rate](https://sourceforge.net/p/mageck/wiki/Home/).
# MAGeCK - MLE
Source: https://wiki.latch.bio/workflows/mageck-mle
This is the mle sub command from MAGeCK. Similar to [MAGeCk Test](https://latch.wiki/mageck-test), this subcommand outputs a gene ranking, but uses maximum-likelihood estimation for gene essentiality scores instead of RRA. This subcommand takes the count summary file (*.count.txt) output from [MAGeCk Count](https://latch.wiki/mageck-count).
## How to run MAGeK Test on Latch
1. Find **MAGeCK MLE in your Workspace**
1. Find **MAGeCK MLE** in "All Workflows" and open the workflow
2. **Enter the parameters for MAGeCK MLE**
1. First specify the design matrix for your samples.
This can either be done by providing a .txt file with the design matrix in it (**see how to format below**).
— or —
By having MAGeCK create a design matrix for you by specifying the Labels for the Day 0 Samples in your count table.
2. Select the count table, if you used MAGeCK Count to generate your count table it will be \*.count.txt file from the count outputs.
3. Then fill out the *Output Prefix* and set an *Output Location* and click Launch Workflow.
3. **Within no time your results will show up in the Data tab!**
### FYI
* If you want to run multiple executions of this workflow click the large plus button at the bottom of the parameters to add an additional execution of the test workflow.
* We have hidden many of the optional parameters under Hidden Parameters, you can click that if you would like to fine tune your execution run or want to use any of the advanced parameters.
## Inputs
### Required Inputs
### Count Table
* A tab-separated count table, each line in the table should include sgRNA name (1st column), targeting gene (2nd column) and read counts in each sample. If you used MAGeCK Count to generate your count table it will \*.count.txt file from the count outputs.
* The read count file should list the names of the sgRNA, the gene it is targeting, followed by the read counts in each sample. Each item should be separated by the tab ('\t'). A header line is optional. For example in the studies of [T. Wang et al. Science 2014](http://www.ncbi.nlm.nih.gov/pubmed/24336569), there are 4 CRISPR screening samples, and they are labeled as: HL60.initial, KBM7.initial, HL60.final, KBM7.final. Here are a few lines of the read count file:
| sgRNA | Gene | HL60.initial | KBM7.initial | HL60.final | KBM7.final |
| --------------- | ---- | ------------ | ------------ | ---------- | ---------- |
| A1CF\_m52595977 | A1CF | 213 | 274 | 883 | 175 |
| A1CF\_m52596017 | A1CF | 294 | 412 | 1554 | 1891 |
| A1CF\_m52596056 | A1CF | 421 | 368 | 566 | 759 |
| A1CF\_m52603842 | A1CF | 274 | 243 | 314 | 855 |
| A1CF\_m52603847 | A1CF | 0 | 50 | 145 | 266 |
### Design Matrix File
* A design matrix .txt file can be supplied for MLE. The design matrix file indicates which sample is affected by which condition. It is generally a binary matrix indicating which sample (indicated by the first column) is affected by which condition (indicated by the first row). To create a design matrix file, **copy the following content to a text editing software, and save it as a plain txt file:**
```
Samples baseline HL60 KBM7
HL60.initial 1 0 0
KBM7.initial 1 0 0
HL60.final 1 1 0
KBM7.final 1 0 1
```
Or you can download this example design matrix txt file for formatting:
0.3KB
Remember the following rules of a design matrix file:
1. The design matrix file must include a header line of condition labels;
2. The first column is the sample labels that must match sample labels in read count file;
3. The second column must be a "baseline" column that sets all values to "1";
4. The element in the design matrix is either "0" or "1";
5. You must have at least one sample of "initial state" (e.g., day 0 or plasmid) that has only one "1" in the corresponding row. That only "1" must be in the baseline column.
In the design matrix above, we have four samples, two corresponding to the initial states of two cell lines, and two corresponding to the final states of two cell lines. We design two conditions (HL60 and KBM7) that model the cell type-specific effects.
For creating a more complicated design matrix you can reference the [Advanced Design Matrix MAGeCK](https://sourceforge.net/p/mageck/wiki/advanced_tutorial/#tutorial-4-make-full-use-of-mageck-mle-for-more-complicated-experimental-design-eg-paired-samples-time-series) documentation directly.
— or —
### Specify the Day Zero Label
* The name of the control Sample Labels (usually the day 0 or plasmid label) which will tell the MAGeCK MLE module to treat it as a single condition and generate a corresponding design matrix.
### Output Prefix
* The prefix appended to all of the outputted files
### Output Location
* The directory where the files produced by this subcommand will be placed. A path can either be selected or if a new path is typed in field Latch will automatically create the folders in the data viewer.
## Quality Control & Trimming
### Number of Genes For Mean-Variance Modeling
* The number of genes for mean-variance modeling. By default MAGeCK uses 1000 (but might also only use 0, not entirely sure, the documentation is conflicting on this one).
### Number of Rounds For Permutation
* The rounds for permutation. The permutation time is `Number of Genes * x for x Rounds of Permutation`. MAGeCK defaults to 2 rounds but suggests 10 (which may take a longer time).
### Perform Permutation on Genes Separately
* By default gene permutation is performed separately by their number of sgRNAs. Enabling this will perform permutation on all genes together and will make the program faster, but the p value estimation is accurate only if the number of sgRNAs per gene is approximately the same.
### Maximum sgRNAs Per Gene
* MAGeCK won't calculate beta scores or p vales if the number of sgRNAs per gene is greater than this number. This will save a lot of time if some isolated regions are targeted by a large number of sgRNAs (usually hundreds). By default the maximum sgRNAs per gene is 40.
### Remove Outliers
* Enabling this will have MAGeCK try to remove outliers. Turning this option on will slow the algorithm.
### sgRNA Efficiency Prediction File
* An optional file of sgRNA efficiency prediction. The efficiency prediction will be used as an initial guess of the probability an sgRNA is efficient. Must contain at least two columns, one containing sgRNA ID, the other containing sgRNA efficiency prediction.
### sgRNA ID Column in sgRNA Efficiency Prediction File (0 = 1st column)
* The sgRNA ID column in the sgRNA efficiency prediction file (specified by the sgRNA Efficiency Prediction File parameter).
### sgRNA Efficiency Prediction Column in sgRNA Efficiency Prediction File (1 = 2nd column)
* The sgRNA efficiency prediction column in sgRNA efficiency prediction file specified by the sgRNA Efficiency Prediction File parameter).
### Iteratively Update sgRNA Efficiency During EM Iteration
* This will tell MAGeCK to Iteratively update sgRNA efficiency during EM iteration.
### Use Experimental Bayes module to Estimate Gene Essentiality
* This will tell MAGeCK to use the experimental Bayes module to estimate gene essentiality.
### Incorporate PPI As Prior
* This will tell MAGeCK that you want to incorporate PPI as prior.
### Use Weighting Value To Calculate PPI Prior
* This where you can supply the weighting used to calculate PPI prior. If no value is provided MAGeCK will use iterations.
### Labels of Samples For Estimating Variance (Label name must match name given in Sample Labels)
* The gene name of negative controls. The corresponding sgRNA will be viewed independently.
### Method for Normalization
* By default MAGeCK will use Median normalization.
* Options:
* **None**: no normalization
* **Median**: median normalization, default
* **Total**: normalization by total read counts
* **Control**: normalization by control sgRNAs specified by the Control sgRNA option. The median factor used for normalization will be calculated based on control sgRNAs only, rather than all the sgRNAs
### Control sgRNAs
* A list of control sgRNAs for normalization and for generating the null distribution of RRA. Alternatively Control Genes can be specified instead of this parameter. This option tells MAGeCK to use provided negative control sgRNAs to generate the null distribution when calculating the p values. By providing the corresponding sgRNA IDs in this parameter, MAGeCK will have a better estimation of p values.
* When using this option, you will need to provide a plain text file just containing negative control sgRNA IDS (one per each line). For example,
```
NonTargetingControlGuideForHuman_0001
NonTargetingControlGuideForHuman_0002
NonTargetingControlGuideForHuman_0003
NonTargetingControlGuideForHuman_0004
```
### Control Genes
* A list of genes whose sgRNAs are used as control sgRNAs for normalization and for generating the null distribution of RRA. Alternatively Control sgRNA can be specified instead of this parameter. There are several issues that you need to keep in mind:
* You should have enough number of negative control guides (>100 recommended) for accurate p value estimation and normalization.
* It is known that for growth based screens, non-targeting controls may lead to high false positives (e.g., [Morgens et al. 2017](https://www.nature.com/articles/ncomms15178). Use non-targeting controls carefully.
* By default MAGeCK will generate the null distribution of RRA scores by assuming all of the genes in the library are non-essential. This approach is sometimes over-conservative, and you can improve this if you know some genes are not essential.
### Copy Number Variation (CNV) Matrix for Normalization
* A matrix of copy number variation data across cell lines to normalize CNV-biased sgRNA scores prior to gene ranking.
### BED File with Gene Positions For Copy Number Variation (CNV) Estimation
* Estimate CNV profiles from screening data. A BED file with gene positions are required as input. The CNVs of these genes are to be estimated and used for copy number bias correction.
## Run Settings
### Debug Mode
* Debug mode to output detailed information of the running.
### Run Debug Mode with Single Gene for MLE Task
* Debug mode to only run one gene with specified ID.
## Outputs
### gene\_summary.txt
* This file is a table is pretty similar to the gene summary outputted by the test subcommand with some different columns. You can learn more about the format of it at the MAGeCK Wiki.
### sgrna\_summary.txt
* A summary of sgrnas. Please forgive me as I'm not really sure what the complete significance of this file is, but will update this once I figure it out. Or if you can help explain this to me please contact me at [nathan@latch.bio](mailto:nathan@latch.bio).
### Log File
* This file contains all of the logs of the execution. This file is mostly a bunch of techno gobbledygook but you can view it to view any errors the execution might have encountered.
## What is MAGeCK
Model-based Analysis of Genome-wide CRISPR-Cas9 Knockout ([MAGeCK](https://genomebiology.biomedcentral.com/articles/10.1186/s13059-014-0554-4) is a computational tool to identify important genes from the recent genome-scale CRISPR-Cas9 knockout screens (or GeCKO) technology. MAGeCK can be used for prioritizing single-guide RNAs, genes and pathways in genome-scale CRISPR/Cas9 knockout screens. MAGeCK identifies both positively and negatively selected genes simultaneously and reports robust results across different experimental conditions. MAGeCK is developed and maintained by Wei Li and Han Xu from [Prof. Xiaole Shirley Liu's lab](http://liulab.dfci.harvard.edu/) at the Department of Biostatistics and Computational Biology, Dana-Farber Cancer Institute and Harvard School of Public Health. MAGeCK has been used to identify functional lncRNAs from screens with close to [100% validation rate](https://sourceforge.net/p/mageck/wiki/Home/).
# Overview - MAGeCK
Source: https://wiki.latch.bio/workflows/mageck-overview
Model-based Analysis of Genome-wide CRISPR-Cas9 Knockout
[MAGeCK](https://genomebiology.biomedcentral.com/articles/10.1186/s13059-014-0554-4) is a computational tool to identify important genes from the recent genome-scale CRISPR-Cas9 knockout screens (or GeCKO) technology. MAGeCK can be used for prioritizing single-guide RNAs, genes and pathways in genome-scale CRISPR/Cas9 knockout screens. MAGeCK identifies both positively and negatively selected genes simultaneously and reports robust results across different experimental conditions. MAGeCK is developed and maintained by Wei Li and Han Xu from [Prof. Xiaole Shirley Liu's lab](http://liulab.dfci.harvard.edu/) at the Department of Biostatistics and Computational Biology, Dana-Farber Cancer Institute and Harvard School of Public Health. MAGeCK has been used to identify functional lncRNAs from screens with close to [100% validation rate](https://sourceforge.net/p/mageck/wiki/Home/).
## How to run MAGeCK on Latch
On Latch we have split up the MAGeCK workflow into its subcommands to be run. These are:
You can get an overview on how these subcommands work and feed into one another through this graph:
1284.5 KB
# MAGeCK - Pathway
Source: https://wiki.latch.bio/workflows/mageck-pathway
This is the pathway sub command from MAGeCK. This subcommand takes the Gene Ranking output (*.gene_summary.txt) from [MAGeCK Test](https://latch.wiki/mageck-test) and invokes Gene Set Enrichment Analysis (GSEA) or RRA (Robust Rank Aggregation) to test if a pathway is enriched in one particular gene ranking.
## How to run MAGeCK Pathway on Latch
1. Find MAGeCK Pathway in your Workspace
1. Find **MAGeCK Count** in "All Workflows" and open the workflow
2. **Enter the parameters for MAGeCK Count**
1. First add your Gene Ranking file, if you used MAGeCK test to generate your Gene Ranking file it will be \*.gene\_summary.txt file from the test outputs.
2. Then add your Pathway file in GMT format (**learn more about this file and format below)**.
3. TThen fill out the Output Prefix and Output Location and click Launch Workflow.
3. **Within no time your results will show up in the Data tab!**
### FYI
* If you want to run multiple executions of this workflow click the large plus button at the bottom of the parameters to add an additional execution of the count workflow.
* We have hidden many of the optional parameters under Hidden Parameters, you can click that if you would like to fine tune your execution run or want to use any of the advanced parameters.
## Required Parameters
### Gene Ranking
* The gene ranking file generated by MAGeCK Test. This will be the \*.gene\_summary.txt from the outputs.
### Pathway File in GMT Format Used For Analysis
* The GMT file format stores the pathway information and is consistent with the GMT file in Gene Set Enrichment Analysis (GSEA). The details of the GMT format can be found at [GSEA website](http://www.broadinstitute.org/cancer/software/gsea/wiki/index.php/Data_formats#GMT:_Gene_Matrix_Transposed_file_format_.28.2A.gmt.29).
* You can also download different pathway files directly from GSEA [MSigDB](http://www.broadinstitute.org/gsea/downloads.jsp) database. They can be used directly by MAGeCK.
### Gene Summary is Single Ranking File
* Enabling this tells MAGeCK that the provided file is a (single) gene ranking file, either positive or negative selection and only one enrichment comparison will be performed.
### Pathway Summary Analysis Method
* The method used by MAGeCK for testing pathway enrichment. By default MAGeCK uses \[GSEA]\( (Gene Set Enrichment Analysis), but also is able to use [RRA](https://sourceforge.net/p/mageck/wiki/Home/#rra) (Robust Rank Aggregation).
### Output Prefix
* The prefix appended to all of the outputted files.
### Output Location
* The directory where the files produced by this subcommand will be placed. A path can either be selected or if a new path is typed in field Latch will automatically create the folders in the data viewer.
## Hidden Parameters
### Analysis Settings
### Default Alpha Value For RRA Pathway Enrichment
* The default alpha value for RRA pathway enrichment. By default MAGeCK uses 0.25.
### GSEA Permutation
* The permutation for GSEA. By default MAGeCK uses 1000.
### Negative Selection Score Ranking Column Index (2 = 3rd Column)
* Column number index in the gene summary file for gene ranking. By default MAGeCK uses 2 (the 3rd column) which is the **neg|score**.
### Positive Selection Score Ranking Column Index (8 = 9th Column)
* Column number in the gene summary file for gene ranking. This value is used to determine the column for positive selections and is disabled if *Single Ranking* is specified. Default "8" (the 9th column).
## Output Settings
### Sort Criteria for Output Summaries
* Tells MAGeCK to sort summaries either by negative selection (neg) or positive selection (pos). By default MAGeCK will sort by negative selection.
### Keep Intermediate Files
* This will have MAGeCK keep the \_.pathway.high.txt and \_.pathway.low\.txt files which are used in generating the pathway summary file and normally deleted at the end of the execution by MAGeCK.
## Outputs
### pathway\_summary.txt
* The output of the pathway summary is similar to the gene summary. You can learn more about the format of it at the [MAGeCK Wiki](https://sourceforge.net/p/mageck/wiki/output/#pathway_summary_txt).
### Log File
* This file contains all of the logs of the execution. This file is mostly a bunch of techno gobbledygook but you can view it to view any errors the execution might have encountered.
## Temporary Files
### pathway.high.txt
* An intermediate file used in pathway analysis.
### pathway.low\.txt
* An intermediate file used in pathway analysis.
## What is MAGeCK
Model-based Analysis of Genome-wide CRISPR-Cas9 Knockout ([MAGeCK](https://genomebiology.biomedcentral.com/articles/10.1186/s13059-014-0554-4) is a computational tool to identify important genes from the recent genome-scale CRISPR-Cas9 knockout screens (or GeCKO) technology. MAGeCK can be used for prioritizing single-guide RNAs, genes and pathways in genome-scale CRISPR/Cas9 knockout screens. MAGeCK identifies both positively and negatively selected genes simultaneously and reports robust results across different experimental conditions. MAGeCK is developed and maintained by Wei Li and Han Xu from [Prof. Xiaole Shirley Liu's lab](http://liulab.dfci.harvard.edu/) at the Department of Biostatistics and Computational Biology, Dana-Farber Cancer Institute and Harvard School of Public Health. MAGeCK has been used to identify functional lncRNAs from screens with close to [100% validation rate](https://sourceforge.net/p/mageck/wiki/Home/).
# MAGeCK - Plot
Source: https://wiki.latch.bio/workflows/mageck-plot
This is the pathway sub command from MAGeCK. This subcommand takes the Gene Ranking output (*.gene_summary.txt) from [MAGeCK Test](https://latch.wiki/mageck-test) and invokes Gene Set Enrichment Analysis (GSEA) or RRA (Robust Rank Aggregation) to test if a pathway is enriched in one particular gene ranking.
## How to run MAGeCK Pathway on Latch
1. Find MAGeCK Plot in your Workspace
1. Find **MAGeCK Plot** in "All Workflows" and open the workflow
2. **Enter the parameters for MAGeCK Plot**
1. First add your Gene Ranking file, if you used MAGeCK test to generate your Gene Ranking file it will be \*.gene\_summary.txt file from the test outputs.
2. Then add your Pathway file in GMT format (**learn more about this file and format below)**.
3. TThen fill out the Output Prefix and Output Location and click Launch Workflow.
3. **Within n30 seconds your results will show up in the Data tab!**
### FYI
* If you want to run multiple executions of this workflow click the large plus button at the bottom of the parameters to add an additional execution of the count workflow.
* We have hidden many of the optional parameters under Hidden Parameters, you can click that if you would like to fine tune your execution run or want to use any of the advanced parameters.
## Required Parameters
### Gene Ranking File
* The gene ranking file generated by MAGeCK Test. This will be the \*.gene\_summary.txt from the outputs.
### Count Table
* A tab-separated count table, each line in the table should include sgRNA name (1st column), targeting gene (2nd column) and read counts in each sample. If you used MAGeCK Count to generate your count table it will \*.count.txt file from the count outputs.
### Output Prefix
* The prefix appended to all of the outputted files
### Output Location
* The directory where the files produced by this subcommand will be placed. A path can either be selected or if a new path is typed in field Latch will automatically create the folders in the data viewer.
## Hidden Parameters
### Plot Settings
### Method for Normalization
* By default MAGeCK will use Median normalization.
* Options:
* **None**: No normalization
* **Median**: Median normalization, default
* **Total**: Normalization by total read counts
* **Control**: Normalization by control sgRNAs specified by the Control sgRNA option. The median factor used for normalization will be calculated based on control sgRNAs only, rather than all the sgRNAs
### Control sgRNAs
* A list of control sgRNAs for normalization and for generating the null distribution of RRA. Alternatively Control Genes can be specified instead of this parameter. This option tells MAGeCK to use provided negative control sgRNAs to generate the null distribution when calculating the p values. By providing the corresponding sgRNA IDs in this parameter, MAGeCK will have a better estimation of p values.
* When using this option, you will need to provide a plain text file just containing negative control sgRNA IDS (one per each line). For example,
```
NonTargetingControlGuideForHuman_0001
NonTargetingControlGuideForHuman_0002
NonTargetingControlGuideForHuman_0003
NonTargetingControlGuideForHuman_0004
```
### Control Genes
* A list of genes whose sgRNAs are used as control sgRNAs for normalization and for generating the null distribution of RRA. Alternatively Control sgRNA can be specified instead of this parameter. There are several issues that you need to keep in mind:
* You should have enough number of negative control guides (>100 recommended) for accurate p value estimation and normalization.
* It is known that for growth based screens, non-targeting controls may lead to high false positives (e.g., [Morgens et al. 2017](https://www.nature.com/articles/ncomms15178). Use non-targeting controls carefully.
* By default MAGeCK will generate the null distribution of RRA scores by assuming all of the genes in the library are non-essential. This approach is sometimes over-conservative, and you can improve this if you know some genes are not essential.
### Specify Specific Genes To Be Plotted
* A list of genes to be plotted.
### Specify Specific Samples To Be Plotted
* A list of samples to be plotted. By default MAGeCK uses all samples in the count table.
## Outputs
### PDF of Plots
* Just a PDF of the plots. It isn't very pretty though.
### .R File
* This file contains code that can be executed within the R software environment to plot the data from the count subcommand and create a PDF from it. This file can be used in a program such as [RStudio](https://www.rstudio.com/).
### plot\_summary.Rnw
* This file is called by the counts summary.R file and has the specific code for plotting the results.
### Log File
* This file contains all of the logs of the execution. This file is mostly a bunch of techno gobbledygook but you can view it to view any errors the execution might have encountered.
## What is MAGeCK
Model-based Analysis of Genome-wide CRISPR-Cas9 Knockout ([MAGeCK](https://genomebiology.biomedcentral.com/articles/10.1186/s13059-014-0554-4) is a computational tool to identify important genes from the recent genome-scale CRISPR-Cas9 knockout screens (or GeCKO) technology. MAGeCK can be used for prioritizing single-guide RNAs, genes and pathways in genome-scale CRISPR/Cas9 knockout screens. MAGeCK identifies both positively and negatively selected genes simultaneously and reports robust results across different experimental conditions. MAGeCK is developed and maintained by Wei Li and Han Xu from [Prof. Xiaole Shirley Liu's lab](http://liulab.dfci.harvard.edu/) at the Department of Biostatistics and Computational Biology, Dana-Farber Cancer Institute and Harvard School of Public Health. MAGeCK has been used to identify functional lncRNAs from screens with close to [100% validation rate](https://sourceforge.net/p/mageck/wiki/Home/).
# MAGeCK - Test
Source: https://wiki.latch.bio/workflows/mageck-test
This is the test sub command from MAGeCK. This subcommand tests and ranks sgRNAs and genes based on the read count tables provided using [Robust Rank Aggregation](https://pubmed.ncbi.nlm.nih.gov/22247279/) (RRA). This subcommand takes the count summary file (*.count.txt) output from [MAGeCk Count](https://latch.wiki/mageck-count) and its outputs can be passed into [MAGeCk Pathway](https://latch.wiki/mageck-pathway) for gene pathway analysis and to [MAGeCK Plot](https://latch.wiki/mageck-plot) to generate graphics for selected genes.
## How to run MAGeK Test on Latch
1. Find **MAGeCK Test in your Workspace**
1. Find **MAGeCK Test** in "All Workflows" and open the workflow
2. **Enter the parameters for MAGeCK Test**
1. First add your *Sample Labels*, these labels should correspond to the labels in your count table. Ex. "L1", "CTRL"
2. Then, specify which labels are treatment and which are control.
This can either be done by listing each in Sample Types and must correspond to the Sample Labels given in the same order.
— or —
You can specify the name of a single *Sample Label* (usually the day 0 or plasmid label) in the *Specify Single Control Label* parameter which will tell MAGeCK to treat all other samples as treatments.
3. Select the count table, if you used MAGeCK Count to generate your count table it will be \*.count.txt file from the count outputs.
4. Then fill out the *Output Prefix* and set an *Output Location* and click Launch Workflow.
3. **Within no time your results will show up in the Data tab!**
### FYI
* If you want to run multiple executions of this workflow click the large plus button at the bottom of the parameters to add an additional execution of the test workflow.
* We have hidden many of the optional parameters under Hidden Parameters, you can click that if you would like to fine tune your execution run or want to use any of the advanced parameters.
## Required Parameters
### Sample Labels
* The labels of each sample in the count table. The names and number of labels listed must correspond to samples listed in the count table.
*Which samples are treatment or control, this can be done in one of two ways:*
### Sample Types
* A list that specifies whether each of the sample labels listed above are a treatment or a control sample. This list must correspond to the list of Sample Labels given.
— or —
### Specify Single Control Label
* The name of a single Sample Label (usually the day 0 or plasmid label) which will tell MAGeCK to treat all other samples as treatments.
### Sample Inputs Are Paired
* Enabling this tells MAGeCK to do paired sample comparisons.
* When enabled, the sample labels given must be listed paired, so treatment-1, control-1, treatment-2, control-2, etc...
**For example:**
Sample Labels: HL60.final, HL60.intial, KBM7.final, KBM7.intial\
Sample Types: Treatment, Control, Treatment, Control
### Count Table
* A tab-separated count table, each line in the table should include sgRNA name (1st column), targeting gene (2nd column) and read counts in each sample. If you used MAGeCK Count to generate your count table it will \*.count.txt file from the count outputs.
* The read count file should list the names of the sgRNA, the gene it is targeting, followed by the read counts in each sample. Each item should be separated by the tab ('\t'). A header line is optional. For example in the studies of [T. Wang et al. Science 2014](http://www.ncbi.nlm.nih.gov/pubmed/24336569), there are 4 CRISPR screening samples, and they are labeled as: HL60.initial, KBM7.initial, HL60.final, KBM7.final. Here are a few lines of the read count file:
| sgRNA | Gene | HL60.initial | KBM7.initial | HL60.final | KBM7.final |
| --------------- | ---- | ------------ | ------------ | ---------- | ---------- |
| A1CF\_m52595977 | A1CF | 213 | 274 | 883 | 175 |
| A1CF\_m52596017 | A1CF | 294 | 412 | 1554 | 1891 |
| A1CF\_m52596056 | A1CF | 421 | 368 | 566 | 759 |
| A1CF\_m52603842 | A1CF | 274 | 243 | 314 | 855 |
| A1CF\_m52603847 | A1CF | 0 | 50 | 145 | 266 |
### Output Prefix
* The prefix appended to all of the outputted files.
### Output Location
* The directory where the files produced by this subcommand will be placed. A path can either be selected or if a new path is typed in field Latch will automatically create the folders in the data viewer.
## Hidden Parameters
### Quality Control & Trimming
### Method for Normalization
* By default MAGeCK will use Median normalization.
* Options:
* **None**: No normalization
* **Median**: Median normalization – Default
* **Total**: Normalization by total read counts
* **Control**: Normalization by control sgRNAs specified by the Control sgRNA option. The median factor used for normalization will be calculated based on control sgRNAs only, rather than all the sgRNAs
### Control sgRNAs
* A list of control sgRNAs for normalization and for generating the null distribution of RRA. Alternatively Control Genes can be specified instead of this parameter. This option tells MAGeCK to use provided negative control sgRNAs to generate the null distribution when calculating the p values. By providing the corresponding sgRNA IDs in this parameter, MAGeCK will have a better estimation of p values.
* When using this option, you will need to provide a plain text file just containing negative control sgRNA IDS (one per each line). For example,
```
NonTargetingControlGuideForHuman_0001
NonTargetingControlGuideForHuman_0002
NonTargetingControlGuideForHuman_0003
NonTargetingControlGuideForHuman_0004
```
### Control Genes
* A list of genes whose sgRNAs are used as control sgRNAs for normalization and for generating the null distribution of RRA. Alternatively Control sgRNA can be specified instead of this parameter. There are several issues that you need to keep in mind:
* You should have enough number of negative control guides (>100 recommended) for accurate p value estimation and normalization.
* It is known that for growth based screens, non-targeting controls may lead to high false positives (e.g., [Morgens et al. 2017](https://www.nature.com/articles/ncomms15178). Use non-targeting controls carefully.
* By default MAGeCK will generate the null distribution of RRA scores by assuming all of the genes in the library are non-essential. This approach is sometimes over-conservative, and you can improve this if you know some genes are not essential.
### p-Value Threshold For FDR Gene Test
* The p value threshold to determine the alpha value of RRA in gene test. The default value is set as 0.25.
### sgRNA-Level p-Value Adjustment Method
* The method for sgrna-level p-value adjustment, by default MAGeCK will use False Discovery Rate (fdr). Holm's Method (holm) and Pounds's Method (pounds) can also be used.
### Labels of Samples for Estimating Variance
* Sample label or sample index for estimating variances. The label names given here must match the name given in Sample Labels.
### Remove sgRNAs Whose Mean Value is Zero In
* Specify where sgRNAs whose mean value is zero should be removed, this can be either remove none, only the treatment, only the control, both the treatment and control, or any sgRNA where the mean value is zero.
* MAGeCK defaults to removing from both the treatment and control sgRNA.
### Remove Zeros Threshold
* The sgRNA normalized count threshold to be considered removed in the *Remove sgRNAs Whose Mean Value Is Zero* option. By default this threshold is 0.
### Log2 Fold Changes (LFC) Calculation Method
* Method to calculate gene log2 fold changes (LFC) from sgRNA LFCs. Available methods include the median/mean of all sgRNAs (median/mean), or the median/mean sgRNAs that are ranked in front of the alpha cutoff in RRA (alphamedian/alphamean), or the sgRNA that has the second strongest LFC (secondbest). In the alphamedian/alphamean case, the number of sgRNAs correspond to the "goodsgrna" column in the output, and the gene LFC will be set to 0 if no sgRNA is in front of the alpha cutoff. The default value is median.
### Copy Number Variation (CNV) Matrix for Normalization
* A matrix of copy number variation data across cell lines to normalize CNV-biased sgRNA scores prior to gene ranking.
### Cell Line Name For Copy Number Variation (CNV) Normalization
* The name of the cell line to be used for copy number variation normalization. Must match one of the column names in the file provided for Copy Number Variation (CNV) Matrix.
### BED File with Gene Positions For Copy Number Variation (CNV) Estimation
* Estimate CNV profiles from screening data. A BED file with gene positions are required as input. The CNVs of these genes are to be estimated and used for copy number bias correction.
## Output Settings
### Sort Criteria for Output Summaries
* Tells MAGeCK to sort summaries either by negative selection (neg) or positive selection (pos). By default MAGeCK will sort by negative selection.
### Generate PDF Report of Analysis
* Enabling this might do something, not sure…
### Generate File With Normalized Read Counts
* Save unmapped reads to file, with sgRNA lengths specified by sgRNA Length parameter which might be combine with this one or be a separate parameter, I'm not sure yet...
### Keep Intermediate Files
* This will have MAGeCK keep the \_.gene.high.txt, \_.gene.low\.txt, phigh.txt and plow\.txt which are used in generating the gene/sgrna ranking and normally deleted at the end of the execution by MAGeCK.
## Outputs
### gene\_summary.txt
* This file is a table with the p-values and FDRs of all genes computed by MAGeCK. You can learn more about the format of it at the [MAGeCK Wiki](https://sourceforge.net/p/mageck/wiki/output/#gene_summary_txt).
### sgrna\_summary.txt
* Results by guide. You can learn more about the format of it at the [MAGeCK Wiki](https://sourceforge.net/p/mageck/wiki/output/#gene_summary_txt).
### .R File
* This file contains code that can be executed within the R software environment to plot the data from the count subcommand and create a PDF from it. This file can be used in a program such as [RStudio](https://www.rstudio.com/).
### summary.Rnw
* This file is called by the counts summary.R file and has the specific code for plotting the results.
### Log File
* This file contains all of the logs of the execution. This file is mostly a bunch of techno gobbledygook but you can view it to view any errors the execution might have encountered.
## Temporary Files
### gene.high.txt
* The gene ranking results (positively selected genes). Used in the RRA analysis.
### gene.low\.txt
* The gene ranking results (negatively selected genes). Used in the RRA analysis.
### phigh.txt
* An sgrna ranking file created and used by MAGeCK for RRA analysis.
### plow\.txt
* An sgrna ranking file created and used by MAGeCK for RRA analysis.
## What is MAGeCK
Model-based Analysis of Genome-wide CRISPR-Cas9 Knockout ([MAGeCK](https://genomebiology.biomedcentral.com/articles/10.1186/s13059-014-0554-4) is a computational tool to identify important genes from the recent genome-scale CRISPR-Cas9 knockout screens (or GeCKO) technology. MAGeCK can be used for prioritizing single-guide RNAs, genes and pathways in genome-scale CRISPR/Cas9 knockout screens. MAGeCK identifies both positively and negatively selected genes simultaneously and reports robust results across different experimental conditions. MAGeCK is developed and maintained by Wei Li and Han Xu from [Prof. Xiaole Shirley Liu's lab](http://liulab.dfci.harvard.edu/) at the Department of Biostatistics and Computational Biology, Dana-Farber Cancer Institute and Harvard School of Public Health. MAGeCK has been used to identify functional lncRNAs from screens with close to [100% validation rate](https://sourceforge.net/p/mageck/wiki/Home/).
# What are Latch Workflows?
Source: https://wiki.latch.bio/workflows/overview
Latch's Workflow Manager comes with out-of-the-box community workflows and a Python SDK that allows uploading of custom workflows.
Define serverless bioinformatics workflows using plain Python & deploy associated no-code interfaces with single command.
Access our suite of pre-built, optimized workflows designed to address common bioinformatics challenges.
## Bring your own workflow
Latch providers a robust development toolkit that allows developers to upload an existing pipeline written in Snakemake, Nextflow, or Python.
Key benefits of the Latch SDK:
* **Instant no-code interfaces** for **accessibility and publication**.
* **Containerization and versioning** of **every registered change**.
* **Reliable and scalable** managed cloud infrastructure.
* **Automatically run workflows** on top of folders in Latch Data.
### Get Started with the Latch SDK
The fastest way to get started-ideal for those with ad-hoc scripts to create a workflow.
}
>
Create GUIs from Nextflow projects with minimal added boilerplate & code.
}
>
Integrate your existing Snakemake pipelines with Latch, and easily create a GUI.
## Out-of-the-box Verified Workflows
Latch offers ready-to-use Verified Workflows for a variety of common assays, including bulk RNA-seq, scRNA-seq, AlphaFold, ColabFold, and more.
These Verified Workflows are developed using the Latch Python SDK by Latch engineers and have been used by top 10 pharmaceutical companies and hundreds of biotech firms to enhance their research and discovery efforts.
Examples of Latch Verified Workflows:
}
>
Perform alignment and quantification on Bulk RNA-Sequencing reads.
}
>
Estimate variance-mean dependence in count data from high-throughput sequencing assays.
}
>
Use differential expression contrast data to calculate the gene ontology and pathways for the most significant genes.
}
>
Generate highly accurate protein structures predictions.
}
>
The ColabFold version of AlphaFold2 is optimized for extremely fast predictions on small proteins.
}
>
Analysis of deep sequencing data for rapid and intuitive interpretation of genome editing experiments.
# Registry Usage Tutorial
Source: https://wiki.latch.bio/workflows/sdk/api/registry-usage-tutorial
This tutorial walks through a practical example of integrating **Latch Registry** into a workflow.
* Code: [https://github.com/latchbio/fancy\_samplesheet\_workflow/tree/main](https://github.com/latchbio/fancy_samplesheet_workflow/tree/main)
* Workflow UI: [https://console.latch.bio/workflows/111268/parameters](https://console.latch.bio/workflows/111268/parameters)
## What You Will Achieve
By the end of this tutorial, your workflow will let scientists seamlessly connect Registry tables to workflow execution. Here's the user experience you are enabling:
1. In the UI, scientists click **“Import from Registry”**, choose a table, and select specific rows.
2. A modal appears to match Registry column names with the workflow input parameters you define in code.
3. Once confirmed, the selected rows are imported directly into the workflow.
4. Users can launch the workflow with the imported data.
5. The workflow then upserts results back into the same Registry records.
6. Updated records are visible in the original Registry table, linking inputs with outputs.
## Importing rows from Registry
### Usage Example
```python expandable theme={null}
from dataclasses import dataclass
from latch.resources.tasks import small_task
from latch.resources.workflow import workflow
from latch.types.file import LatchFile
from latch.types.metadata import LatchAuthor, LatchMetadata, LatchParameter
from latch.types.samplesheet_item import SamplesheetItem
# Define a dataclass to represent a row in the samplesheet
@dataclass
class Row:
sample_name: str
fastq_1: LatchFile
fastq_2: LatchFile
metadata = LatchMetadata(
display_name="Test Record from Samplesheet Input",
author=LatchAuthor(
name="CHANGE ME",
),
parameters={
"rows": LatchParameter(
display_name="Test",
samplesheet=True, # Enable samplesheet input display in the UI
batch_table_column=True, # Show this parameter in batched mode.
),
},
)
@small_task
def task(rows: list[SamplesheetItem[Row]]) -> None: # Wrap the `Row` dataclass in `SamplesheetItem`
for row in rows:
if row.record is None: # Check if the row was imported from Registry
print(f"{row.data.sample_name}: Data is not from registry")
continue
# If the row was imported from Registry, we can access the Record object
print(f"{row.data.sample_name}:")
print(f" -> From Record {row.record.id} in Table {row.record.get_table_id()}")
print(f" -> Created at {row.record.get_creation_time().isoformat()}")
print(f" -> Last updated at {row.record.get_last_updated().isoformat()}")
@workflow(metadata)
def fancy_samplesheet_wf(rows: list[SamplesheetItem[Row]]) -> None:
return task(rows=rows)
```
### Core Ideas
To import a table from Registry into your workflow, follow these steps:
1. **Define a dataclass:**
Create a Python dataclass that represents a single row in the samplesheet.
2. **Mark it as a samplesheet:**
In the LatchMetadata, set samplesheet=True to indicate that this dataclass should be treated as a samplesheet.
3. **Match Registry columns:**
The fields in your dataclass should match the column names in the Registry table (or be a subset). If your dataclass fields use the exact same names as the Registry columns, the workflow UI will automatically align them in the “column matching” modal.
4. **Wrap rows in SamplesheetItem:**
Each row should be wrapped in a SamplesheetItem, which allows the workflow to detect whether the row came from Registry.
5. **A `SamplesheetItem` has two fields:**
* `data` – the actual row data. For example, `row.data.sample_name` will give you the value from the sample\_name column.
* `record` – the Registry Record object for that row.
* If the row was imported from Registry, `record` will be populated with the corresponding Record.
* If the row was created manually (not imported), `record` will be `None`.
## Upserting rows to Registry
A `Table` can be modified by using the `Table.update()` function. `Table.update()` returns a context manager (and hence must be called using `with` syntax) with an `upsert_record` method. Visit the [Table Object](/registry/sdk/table-objects) page for the API reference.
### Usage Example
```python expandable theme={null}
from latch.registry.table import Table
from latch.types.directory import LatchDir
@small_task
def task(rows: list[SamplesheetItem[Row]]) -> None: # Wrap the `Row` dataclass in `SamplesheetItem`
for row in rows:
if row.record is None: # Check if the row was imported from Registry
print(f"{row.data.sample_name}: Data is not from registry")
continue
# If the row was imported from Registry, we can access the Record object
print(f"{row.data.sample_name}:")
print(f" -> From Record {row.record.id} in Table {row.record.get_table_id()}")
print(f" -> Created at {row.record.get_creation_time().isoformat()}")
print(f" -> Last updated at {row.record.get_last_updated().isoformat()}")
# Imagine a directory object that we want to upsert
cellranger_output = LatchDir(...)
# Upsert the record
table = Table(id=row.record.get_table_id())
with table.update() as updater:
updater.upsert_record(
"",
cellranger_output=cellranger_output
)
```
### Core Ideas
* Retrieve the Table ID by calling `get_table_id()` on the `Record` object.
* Initialize a `Table` object by calling `Table(id=table_id)`.
* Call `Table.update()` to get a context manager with an `upsert_record` method.
# Storing and Using Secrets
Source: https://wiki.latch.bio/workflows/sdk/api/storing-and-using-secrets
Often a workflow can depend on _secret data_, such as an API key, to function correctly. To make storing and using secret data easy, the Latch SDK comes with special utilities that handle this securely.
## Adding Secrets
To add a secret, simply navigate to the [Latch Console](https://console.latch.bio)
and head to Account Settings.
From there, navigate to Developer Settings
From there, scroll down to the 'Secrets' section and add your secrets.
Secrets consist of key-value pairs where keys are unique across a workspace.
Secrets are also immutable, so the only way to change the value of a given
secret is to delete it and add a new one with the same key.
## Using Secrets
To use a secret in a workflow, simply use the `get_secret` function built into
the Latch SDK. This function takes in a key and returns the value of the secret
with that key as a string. When run locally, secrets are looked up in the user's
personal workspace only (for security reasons). When running a workflow in the
console, secrets are looked up in the workspace in which the workflow was
registered. Moreover, such workflows will only succeed if ran in the registered
workspace, meaning that no one outside of your team will be able to access your
secrets.
As an example, the following task will get the value of the secret `API_KEY` and
use it to send a request to a server.
```python theme={null}
from latch import small_task
from latch.functions.secrets import get_secret
import requests
@small_task
def send_fake_data_task(fake_data: str) -> bool:
token = get_secret("API_KEY")
response = requests.post(
"https://fake.example.com/fake/endpoint",
headers={"Authorization": f"Bearer {token}"}
json={
"fake_data": fake_data
}
)
return response.status_code == 200
```
# Remote Files
Source: https://wiki.latch.bio/workflows/sdk/api/working-with-files
The Latch SDK provides a convenient means of referencing files or directories hosted on Latch within task functions.
## Downloading Files
To download files locally:
```python theme={null}
from latch.ldata.path import LPath
if __name__ == '__main__':
latch_path = LPath("latch:///welcome/deseq2/design.csv")
local_path = latch_path.download()
print(local_path.read_text())
```
To download files to a pre-determined local path:
```python theme={null}
from latch.ldata.path import LPath
from pathlib import Path
if __name__ == '__main__':
local_path = Path("./test.txt")
latch_path = LPath("latch:///welcome/deseq2/design.csv")
latch_path.download(local_path)
print(local_path.read_text())
```
## Caching File Downloads
By default, the `download` method will *not* cache the file. To enable caching, pass `cache=True`.
```python theme={null}
from latch.ldata.path import LPath
from pathlib import Path
latch_path = LPath("latch:///welcome/deseq2/design.csv")
local_path = Path(f"{latch_path.node_id()}.csv") # Provides local destination path to download to
latch_path.download(local_path, cache=True) # Enable caching
```
If you do not provide a local destination path, the file will be downloaded to the default `~/.latch/` directory. Without caching enabled, this can result in multiple downloads of the same file, unnecessarily increasing storage usage. To avoid this, it is **strongly recommended** to set a destination path and enable caching, especially when using LPath in Latch Pods or Latch Plots.
## Uploading Files
To upload files from a local path to a Latch path:
```python theme={null}
from latch.ldata.path import LPath
if __name__ == '__main__':
latch_path = LPath("latch:///welcome/deseq2/design.csv")
latch_path.upload_from("./test.txt")
print(local_path.read_text())
```
To upload to a remote path, the parent directory of the
remote path must already exist. To ensure that the parent directory
exists, use `LPath("latch:///parent_directory").mkdirp()`.
## Copying Between Latch Paths
Copy data from one Latch path to another:
```python theme={null}
from latch.ldata.path import LPath
src_path = LPath("latch:///welcome/deseq2/design.csv")
dst_path = LPath("latch:///design_copy.csv")
src_path.copy_to(dst_path)
```
## Deleting Latch Files
Recursively remove a remote file or directory:
```python theme={null}
from latch.ldata.path import LPath
latch_path = LPath("latch:///welcome/deseq2/design.csv")
latch_path.rmr()
```
## Fetching File Metadata
Use the following methods to fetch metadata of your remote files
without downloading the file first:
1. `node_id()`
2. `name()`
3. `content_type()`
4. `size()`
LPath objects will cache metadata information for the lifetime of the object
after any `LPath` method is invoked. To re-populate the cache, use the
`LPath().fetch_metadata()` method. For example:
```python theme={null}
from latch.ldata.path import LPath
latch_path = LPath('latch:///dir/file.txt')
name = latch_path.name() # metadata is fetched, name = "file.txt"
# rename the file in the Latch Console to file2.txt
latch_path.name() # returns "file.txt"
latch_path.fetch_metadata()
latch_path.name() # returns "file2.txt"
```
## Working with Directories
LPath also provides the methods for working with remote directories. For example:
```python theme={null}
from latch.ldata.path import LPath
latch_path = LPath('latch:///welcome')
latch_path.is_dir() # returns True
paths = latch_path.iterdir() # returns an Iterator; does not traverse nested directories
next(paths) # returns LPath(path='latch:///welcome/CRISPResso2')
latch_path.size_recursive() # returns 10467327039
```
The `size_recursive` method can be very slow on large directories and should only be used if absolutely necessary.
# Data Addition Trigger
Source: https://wiki.latch.bio/workflows/sdk/automation/example-data-addition
This document is a work in progress and is subject to change.
We will walk through the process of creating an [automation](/workflows/sdk/automation/overview) using the `Data Addition` trigger type on Latch which will run a *target workflow* on all children of the target directory. We assume that you understand how to write and register [Workflows](/workflows/sdk/python/what-is-a-workflow) on Latch.
**Prerequisites:**
* *Target directory* in [Latch Data](https://console.latch.bio/data): this is the folder which is watched by the automation. The automation workflow will be triggered if a child is added to this folder.
**Terms:**
* *Automation Workflow*: workflow which will be called by automation. This is the workflow we create in [steps 3-5](#3-create-the-automation-workflow) of this tutorial.
* *Target Workflow*: workflow which will be ran by automation workflow on child of the *target directory*. This workflow should contain the logic on how to process the files in child directories. This is the workflow we create in [step 1](#1-create-the-target-workflow) of this tutorial.
* *Registry Table*: we use a Registry Table in this tutorial to record child directories which are processed by the target workflow to avoid reprocessing same directories in consequent runs of automation. We create this table in [step 2](#2-create-a-new-registry-table) of this tutorial.
## 1: Create the Target Workflow
This example requires another *target workflow* which will get executes on every child folder when *automation workflow* gets triggered. Below is a simple workflow example which reads every file in a child directory and prints out its Latch Path.
1. Initialize a new workflow using `latch init test-workflow`.
2. Replace `__init__.py` and `task.py` with the following sample code.
```python theme={null}
# __init__.py
from wf.task import task
from latch.resources.workflow import workflow
from latch.types.directory import LatchDir, LatchOutputDir
from latch.types.file import LatchFile
from latch.types.metadata import LatchAuthor, LatchMetadata, LatchParameter
metadata = LatchMetadata(
display_name="Target Workflow",
author=LatchAuthor(
name="Your Name",
),
parameters={
"input_directory": LatchParameter(
display_name="Input Directory",
batch_table_column=True, # Show this parameter in batched mode.
),
"output_directory": LatchParameter(
display_name="Output Directory",
batch_table_column=True, # Show this parameter in batched mode.
),
},
)
@workflow(metadata)
def template_workflow(
input_directory: LatchDir, output_directory: LatchOutputDir
) -> LatchOutputDir:
return task(input_directory=input_directory, output_directory=output_directory)
```
```python theme={null}
# task.py
import os
from logging import Logger
from urllib.parse import urljoin
from latch import message
from latch.resources.tasks import small_task
from latch.types.directory import LatchDir, LatchFile, LatchOutputDir
from latch.account import Account
log = Logger("wf.task")
@small_task
def task(input_directory: LatchDir, output_directory: LatchOutputDir) -> LatchOutputDir:
# iterate through all directories of the child input directories using iterdir()
for file in input_directory.iterdir():
log.error(f"{file} {file.remote_path}") # note: `error` is used here since its the highest logging level
return output_directory
```
3. Register the sample target workflow with Latch using `latch register --remote --yes test-workflow`.
4. Record the ID of your workflow on the sidebar which we will use later in the example.
5. Test the workflow by running it on Latch
6. You will need to pass the parameters into your target workflow from your automation. To obtain the JSON representation of the workflow inputs, navigate to a previous execution of your workflow. Select **Graph and Logs**, click on square box around the first task, and select **Inputs**. Copy the workflow parameters inside the `literal` object, and pass it to `params`.
\
\
i.e.
```json theme={null}
{
"literals": {
# copy everything inside the brackets
}
}
```
## 2: Create a New Registry Table
In this example, we record all processed child directories in the Registry Table to not reprocess directories when automation workflow is runs again. This example requires you to create a new table with no existing columns. The automation workflow will add a column `Processed Directory` with the directory name of processed children.
For many common use cases, Registry serves as the location to track workflow inputs and outputs, and hence we include an example of it here. However, having a registry table is not required, if you don't want to use Registry as a mean to track your inputs and outputs.
To create a new table to be used with the automation:
1. Go to [Latch Registry](https://console.latch.bio/registry).
2. Select an existing project, and click `New Table`.
3. Record the Table ID on the sidebar which we will use later in the example.
## 3: Create the Automation Workflow
This is the workflow which will be run when automation gets triggered. To create the automation workflow, clone the [Automation Workflow Template](https://github.com/latchbio/automation-wf) and navigate to the `automation-wf/wf` directory.
```shell-session theme={null}
$ git clone git@github.com:latchbio/automation-wf.git
Cloning into 'automation-wf'...
remote: Enumerating objects: 33, done.
remote: Counting objects: 100% (33/33), done.
remote: Compressing objects: 100% (24/24), done.
remote: Total 33 (delta 9), reused 28 (delta 6), pack-reused 0
Receiving objects: 100% (33/33), 8.52 KiB | 1.42 MiB/s, done.
Resolving deltas: 100% (9/9), done.
$ cd automation-wf/wf
```
File Tree:
```shell-session theme={null}
├── Dockerfile
├── README.md
├── version
└── wf
├── __init__.py
├── automation.py
└── util.py
```
* `__init__.py` calls the automation task defined in `automation.py`.
* `automation.py` contains the Python logic to determine how a workflow should be launched.
* `util.py` contains the utility function which launches target workflow.
## 4. Configure the Target Workflow
To specify the target workflow and the registry table which you have just created, configure the following parameters in `wf/__init__.py` and specify your name in workflow metadata:
* `output_directory`: The Latch Path to the output folder which this automation workflow will populate. i.e. `latch://...`
* `target_wf_id`: The ID of the target workflow that you have just created.
* `params`: The parameters for your workflow. Refer to [Create The Target Workflow](#1-create-the-target-workflow) to get the parameters.
* `table_id`: The ID of the table which you created that stores metadata for this automation. Refer to [Create A New Registry Table](#2-create-a-new-registry-table) to create a table and get the ID.
> **Important**:
> Currently, automations are only passing `input_directory` as the parameter to the automation workflow. If your workflow has different parameters automation will fail to start it.
> \
> In case you need more parameters to pass to your automation workflow, we suggest to hard-code them into the workflow while we are working on adding parameter support for automations.
```python theme={null}
# __init__.py
from latch.resources.workflow import workflow
from latch.types.directory import LatchDir, LatchOutputDir
from latch.types.metadata import LatchAuthor, LatchMetadata, LatchParameter
from wf.automation import automation_task
metadata = LatchMetadata(
# MODIFY NAMING METADATA BELOW
display_name="Automation Template",
author=LatchAuthor(
name="Your Name Here",
),
# MODIFY NAMING METADATA ABOVE
# IMPORTANT: these exact parameters are required for the workflow to work with automations
parameters={
"input_directory": LatchParameter(
display_name="Input Directory",
)
},
)
@workflow(metadata)
def automation_workflow(input_directory: LatchDir) -> None:
output_directory = LatchOutputDir(
path="latch://FIXME" # fixme: change to remote path of desired output directory
)
automation_task(
input_directory=input_directory,
output_directory=output_directory,
target_wf_id="FIXME", # fixme: change wf_id to the desired workflow id
table_id="FIXME", # fixme: change table_id to the desired registry table
)
```
(Optional) Change the parameters object in `automation.py` from [step 1.6](#1-create-the-target-workflow) if your target workflow takes different parameters than `input_directory` and `output_directory`:
```python theme={null}
# automation.py
...
params = {
"input_directory": {
"scalar": {
"blob": {
"metadata": {"type": {"dimensionality": "MULTIPART"}},
"uri": input_directory.remote_path,
}
}
},
"output_directory": {
"scalar": {
"blob": {
"metadata": {"type": {"dimensionality": "MULTIPART"}},
"uri": output_directory.remote_path,
}
}
},
}
...
```
**Usage Notes**:
* The `input_directory` refers to the child directory (i.e. the trigger directory) to be passed to the target workflow.
* The `output_directory` refers to directory where the output of the target workflow will be stored.
## 5. (Optional) Modify Automation Logic
The file `wf/automation.py` contains the logic that determines how an execution for the target workflow should be launched.
The `automation_task` defines the logic that is used to launch the workflow. The code below checks a registry table to see whether an output directory exists, and launches an execution for the target workflow if that is not the case.
Modify the function below to change the logic for launching target workflows.
```python theme={null}
# automation.py
import uuid
from typing import Set
from latch.registry.table import Table
from latch.resources.tasks import small_task
from latch.types.directory import LatchDir, LatchOutputDir
from latch.types.file import LatchFile
from .utils import launch_workflow
@small_task
def automation_task(
input_directory: LatchDir,
output_directory: LatchOutputDir,
target_wf_id: str,
table_id: str,
) -> None:
"""
Logic on how to process the input directory and launch the target workflows.
"""
# fetch the table using Latch SDK
automation_table = Table(table_id)
processed_directory_column = "Processed Directory"
# [PARAMS OMITTED]
# check if the provided table contains column `Processed Directory` and creates one if it isn't present
# we use Latch SDK to get the columns of the table and try to get the column by name
if automation_table.get_columns().get(processed_directory_column, None) is None:
with automation_table.update() as automation_table_updater: # create an update context for the table
automation_table_updater.upsert_column(processed_directory_column, LatchDir)
# fetch all the directories that have been processed and recorded in the Registry table previously
resolved_directories: Set[str] = set()
# list_records() returns a generator of records(rows) of the Registry Table
for page in automation_table.list_records():
for _, record in page.items():
value = record.get_values()[processed_directory_column]
assert isinstance(
value, LatchDir
) # we only allow processing of child directories
resolved_directories.add(str(value))
assert isinstance(input_directory.remote_path, str)
assert isinstance(output_directory.remote_path, str)
# Launch the target workflow for each child directory which hasn't been processed yet.
# Record the processed directory in the Registry table.
# iterdir() returns an iterator of the child files and directories of the input directory
for child in input_directory.iterdir():
# skip files, output directory and directories that have been processed
if (
isinstance(child, LatchFile)
or str(child) == str(output_directory)
or str(child) in resolved_directories
):
continue
with automation_table.update() as automation_table_updater:
# use a util function to launch the target workflow with the right parameters
launch_workflow(
target_wf_id=target_wf_id,
params=params,
)
# update registry table with the processed directory
automation_table_updater.upsert_record(
str(uuid.uuid4()),
**{
processed_directory_column: child,
},
)
```
## 5. Register Automation Workflow
Register the automation workflow to your Latch workspace.
```shell-session theme={null}
$ latch register --remote --yes automation-wf
```
## 6. Create Automation
Navigate to [Automations](https://console.latch.bio/automations) tab via **Worfklows** > **Automations** and click on the **Create Automation** button.
1. Input an **Automation Name** and **Description**.
2. Select the `Event Type` as `Data Added`.
3. Specify `Follow-up Update Period` to something short like 30 seconds to make your automation easy to test.
4. Select a folder where files/folders will be uploaded using the `Select Target` button. Any items uploaded to this folder will trigger the automation workflow.
5. Select the automation workflow that you have just registered with Latch.
## 7. Test Your Automation
To test your automation, go to the target directory that you have specified when creating automation, and create a couple of folders. Upload any files to the folders, and wait for the trigger timer to expire.
Go to **Worfklows** > **All Executions**. There should be 1 automation workflow execution, and a target workflow execution for each child in your target directory. Each target workflow should print out
# Interval Trigger
Source: https://wiki.latch.bio/workflows/sdk/automation/example-interval
This document is a work in progress and is subject to change.
We will walk through the process of creating an [automation](/workflows/sdk/automation/overview) using an `Interval` trigger type on Latch that will run an automation workflow hourly. We assume that you understand how to write and register [Workflows](/workflows/sdk/python/what-is-a-workflow) on Latch.
**Terms:**
* *Automation Workflow*: workflow which will be called by automation. This is the workflow we create in [step 1](#1-create-the-automation-workflow) of this tutorial.
## 1: Create the Automation Workflow
Below is a simple workflow example which creates folder `output` with a file locally and pushes it to Latch Data.
1. Initialize a new workflow using `latch init automation-wf`.
2. Replace `__init__.py` and `task.py` with the following sample code.
```python theme={null}
# __init__.py
from wf.task import task
from latch.resources.workflow import workflow
from latch.types.directory import LatchDir, LatchOutputDir
from latch.types.file import LatchFile
from latch.types.metadata import LatchAuthor, LatchMetadata, LatchParameter
metadata = LatchMetadata(
display_name="Interval Automation Workflow",
author=LatchAuthor(
name="Your Name",
),
# Note: parameters have to be empty for this workflow to be successfully run by the automation
parameters={},
)
@workflow(metadata)
def workflow() -> None:
task()
```
```python theme={null}
# task.py
import os
from urllib.parse import urljoin
from latch import message
from latch.resources.tasks import small_task
from latch.types.directory import LatchDir, LatchFile, LatchOutputDir
@small_task
def task() -> LatchDir:
os.mkdir("output")
with open("output/hello_world.txt", 'w') as file:
file.write("Hello World!")
return LatchDir("output", "LDATA PATH FOR THE DIRECTORY")
```
3. Register the sample target workflow with Latch using
```shell-session theme={null}
$ latch register --yes automation-wf
```
5. Test the workflow by running it on Latch
## 2. Create Automation
Navigate to [Automations](https://console.latch.bio/automations) tab via **Worfklows** > **Automations** and click on the **Create Automation** button.
1. Input an **Automation Name** and **Description**.
2. Select the `Event Type` as `Interval`.
3. Specify `Interval` to 1 hour.
4. Select the automation workflow that you have just registered with Latch.
# Overview
Source: https://wiki.latch.bio/workflows/sdk/automation/overview
## Description
Automations allow you to automatically run workflows on top of folders in Latch Data when triggered by specific events such as when files are added to folders or after a regular interval of time has passed. Automations consist of a [*trigger*](/workflows/sdk/automation/example-data-addition) and an [*automation workflow*](/workflows/sdk/automation/example-interval).
Additionally, you can inactivate and reactivate automations by toggling the status radio on the sidebar.
## Triggers
Automation triggers specify the conditions needed to run the automation, such as "child got added to the target directory" or "time interval expired".
Triggers are created and configured in the [Latch console](https://console.latch.bio/automations/new).
### Available Trigger Types
#### Data Added
This trigger type runs an [automation workflow](#automation-workflow) if a new child has been added to the target directory at any depth (level of nested directory). The automation will not run if a child has been modified or deleted.
*Trigger Parameters*:
* `Input Target`: the target directory to watch for new children.
* `Follow-up Update Period`: this is the wait period after the last trigger event after which the workflow will run.\
For example, if this value is 10 minutes, the automation will run 10 minutes after a child has been added to the target directory.
*Example*: an automation with the `Data Added` trigger type configured with `Input Target` of directory `/test` and `Follow-up Update Period` of 10 minutes will run the [automation workflow](#automation-workflow) 10 minutes after the last child is added at any depth to `/test` directory in Latch Data.
#### Interval
This trigger type runs [automation workflow](#automation-workflow) on a regular time interval specified by the user.
*Trigger Parameters*:
* `Interval`: the time interval that will activate a trigger
*Example*: an automation with the `Interval` trigger type configured with `Interval` of `1 hour` will run the [automation workflow](#automation-workflow) hourly.
## Automation Workflow
This is the [workflow](/workflows/sdk/python/what-is-a-workflow) that will run whenever the automation has been [triggered](#triggers).
#### Usage Note:
* When using [`Data Added`](#data-added) trigger, the automation workflow function must have `input_directory: LatchDir` as the *only* parameter, else the automation will fail to start.
*Required Workflow Definition*:
```python theme={null}
# __init__.py
from latch.resources.workflow import workflow
from latch.types.directory import LatchDir, LatchOutputDir
from latch.types.metadata import LatchAuthor, LatchMetadata, LatchParameter
from wf.automation import automation_task
metadata = LatchMetadata(
# MODIFY NAMING METADATA BELOW
display_name="Workflow Name",
author=LatchAuthor(
name="Your Name Here",
),
# MODIFY NAMING METADATA ABOVE
# IMPORTANT: these exact parameters are required for the workflow to work with automations
parameters={
"input_directory": LatchParameter(
display_name="Input Directory",
)
},
)
@workflow(metadata)
def automation_workflow(input_directory: LatchDir) -> None:
pass
```
* When using [`Interval`](#interval) trigger, the automation workflow function must have no parameters, else the automation will fail to start.
*Required Workflow Definition*
```python theme={null}
# __init__.py
from latch.resources.workflow import workflow
from latch.types.directory import LatchDir, LatchOutputDir
from latch.types.metadata import LatchAuthor, LatchMetadata, LatchParameter
from wf.automation import automation_task
metadata = LatchMetadata(
# MODIFY NAMING METADATA BELOW
display_name="Workflow Name",
author=LatchAuthor(
name="Your Name Here",
),
# IMPORTANT: these exact parameters are required for the workflow to work with automations
parameters={
},
)
@workflow(metadata)
def automation_workflow() -> None:
pass
```
In case you need more parameters to pass your workflow, we suggest to hard-code them into your workflow while we are working on adding parameter support for automations.
### Examples
For step-by-step instructions on how to create automations, checkout our examples on how to create [Data Added](/workflows/sdk/automation/example-data-addition) and [Interval](/workflows/sdk/automation/example-interval) automations.
## Creating an Automation
1. Author an automation workflow in Python with the Latch SDK and register it with Latch. See [Usage Note](#usage-note) to make sure that your workflow can be run by automations.
2. Navigate to [Automations](https://console.latch.bio/automations) tab via **Worfklows** > **Automations** and click on the **Create Automation** button.
1. Input an **Automation Name** and **Description**.
2. Select the `Event Type`. Refer to the [Available Trigger Types](#available-trigger-types) for explanation of trigger behaviors.
3. Specify `Follow-up Update Period` or `Interval` depending on the type of the trigger you have selected.
4. (For [`Data Added`](#data-added) trigger) select a folder where files/folders will be uploaded using the `Select Target` button. Any items uploaded to this folder will trigger the specified workflow.
5. Select the [automation workflow](#automation-workflow) that you have just registered with Latch.
See our [examples](#examples) for step-by-step instructions on how to create automations.
## Configuring Automations
If you want to configure the name, description or wait intervals or delete your automation, you can do so in automation settings.
1. Navigate to [Automations](https://console.latch.bio/automations) tab via **Worfklows** > **Automations** and click on any of your automations.
2. Click on the settings tab on the selected automation overview page.
3. Update any information that you want on the settings page.
4. Click `Save Changes` to persist your updated settings.
# Commands
Source: https://wiki.latch.bio/workflows/sdk/cli/commands
# Overview
The Latch CLI is a command-line interface for interacting with the Latch platform. It provides tools for managing workflows, data, and development sessions. This document covers all available commands and their options.
## Installation
The Latch CLI is available as a Python package and can be installed with:
```bash theme={null}
mamba create -n latch python=3.11
pip install latch
```
For best behavior, it is recommended to install `latch` in a new virtual environment.
The Latch CLI currently requires Python `>=3.9` and `<=3.11`.
## Authentication Commands
### `latch login`
Authenticates a user with Latch and stores an access token in `~/.latch/token` in the machine the command is run on.
**Options:**
* `--connection `: Specific Auth0 connection name if Single-Sign-On is enabled for the workspace.
**Description:**
Initiates a OAuth2.0 flow. If a browser is available, the user will be redirected to login. Otherwise, the user will be prompted to paste a Personal API Token (or Workspace API Token if they only need to access a single workspace from this machine), which can be generated from the [Developer Settings](https://console.latch.bio/settings/developer) page under **Access Tokens**.
In the case where the user logs in with a SSO connection, a connection string needs to be provided to the `latch login` command.
Latch supports Okta and Microsoft Azure as IdP providers. Visit documentation below to see how to configure SSO for your organization.
Okta SSO Configuration
Microsoft Azure SSO Configuration
**Example:**
```bash theme={null}
latch login
latch login --connection "sso-connection"
```
### `latch workspace`
Opens an interactive terminal prompt allowing users to choose which workspace they want to work in.
**Description:**
Displays a list of available workspaces and allows switching between them. The currently selected workspace is marked.
**Example:**
```bash theme={null}
latch workspace
```
## Workflow Development Commands
### `latch init `
Initializes boilerplate for local workflow code. Only used for the [Python SDK](/workflows/sdk/python/quick-start). Not applicable for [Nextflow](/workflows/sdk/nextflow/overview) or [Snakemake](/workflows/sdk/snakemake-v2/overview) workflows.
**Options:**
* `-t, --template `: Template to use for the workflow (choices: `empty`, `docker`, `subprocess`, `r`, `conda`, `nfcore`)
* `-d, --dockerfile`: Create a user editable Dockerfile for this workflow
* `-b, --base-image `: Which base image to use for the Dockerfile (choices: `default`, `cuda`, `opencl`, default: `default`)
**Description:**
Creates a new workflow package with the specified name and optional template. Sets up the basic directory structure and files needed for a Latch workflow. The template determines the initial code structure and dependencies.
**Available Templates:**
* `empty`: Minimal workflow structure with basic files
* `docker`: Workflow example for running a Docker container
* `subprocess`: Workflow example with Python `subprocess` calling commands
* `r`: Workflow example with R environment setup
* `conda`: Workflow example with `conda` environment setup
* `nfcore`: Workflow example using `subprocess` to call a Nextflow nf-core workflow (Not recommended. If you have Nextflow workflows, use the [Nextflow SDK](/workflows/sdk/nextflow/overview) instead.)
**Available Base Images:**
* `default`: Standard base image for most workflows
* `cuda`: CUDA-enabled base image for GPU workflows
* `opencl`: OpenCL-enabled base image for GPU workflows
**Example:**
```bash theme={null}
# Create a basic workflow
latch init my-workflow
# Create an R-based workflow with Dockerfile
latch init my-r-workflow --template r --dockerfile
# Create a CUDA-enabled workflow
latch init my-gpu-workflow --template docker --base-image cuda
# Create a Nextflow workflow
latch init my-nextflow-workflow --template nfcore
```
### `latch dockerfile `
Generates a user editable Dockerfile for a workflow.
**Options:**
* `-s, --snakemake`: Generate a Dockerfile with arguments needed for [Snakemake workflows](/workflows/sdk/snakemake-v2/overview).
* `-n, --nextflow`: Generate a Dockerfile with arguments needed for [Nextflow workflows](/workflows/sdk/nextflow/overview).
* `-f, --force`: Overwrite existing Dockerfile without confirming
* `-a, --apt-requirements `: Path to a text file containing apt packages to install
* `-r, --r-env `: Path to an environment.R file containing R packages to install
* `-c, --conda-env `: Path to an environment.yml file to install via conda
* `-i, --pyproject `: Path to a setup.py / buildable pyproject.toml file to install
* `-p, --pip-requirements `: Path to a requirements.txt file to install via pip
* `-d, --direnv `: Path to a direnv file (.env) containing environment variables
**Description:**
Creates a Dockerfile tailored for the specified workflow type and dependencies. Supports various package managers and environment configurations.
**Recommended Usage**: Use this command when starting a new Python SDK workflow or uploading an existing Snakemake or Nextflow workflow to Latch. It generates a Dockerfile with the correct arguments. Re-running it will overwrite any existing Dockerfile(s).
**Example:**
```bash theme={null}
latch dockerfile my-workflow --snakemake
```
### `latch generate-metadata [config_file]`
Generates a `__init__.py` and `parameters.py` file from a config file.
**Options:**
* `--metadata-root `: Path to directory containing Latch metadata
* `--yes, -y`: Overwrite an existing `parameters.py` file without confirming
* `--snakemake, -s` \[**DEPRECATED**]: Generate Latch metadata for Snakemake. This command is deprecated and no longer works for `latch >= 2.55.0.a6`
* `--nextflow, -n`: Generate Latch metadata for Nextflow
* `--no-infer-files, -I` \[**DEPRECATED**]: Don't parse strings with common file extensions as file parameters (Snakemake only). This command is deprecated and no longer works for `latch >= 2.55.0.a6`
* `--no-defaults, -D`: Don't generate defaults for parameters
**Description:**
Automatically generates Latch metadata files from workflow configuration files. Supports both Snakemake and Nextflow workflows.
**Example:**
```bash theme={null}
latch generate-metadata nextflow_schema.json --nextflow
```
### `latch develop `
Starts a local development session for workflow development.
**Options:**
* `--yes, -y`: Skip the confirmation dialog
* `--wf-version, -v `: Use the container environment of a specific workflow version
* `--disable-sync, -d`: Disable the automatic syncing of local files to develop session
* `--instance-size, --size, -s `: Size of machine to provision (choices: small\_task, medium\_task, large\_task, small\_gpu\_task, large\_gpu\_task, v100\_x1\_task, g6e\_xlarge\_task)
**Description:**
Creates a cloud-based development environment that mirrors the workflow's runtime environment. Allows testing and debugging workflows in their intended execution context.
**Example:**
```bash theme={null}
latch develop my-workflow --instance-size large_task
```
### `latch exec`
Drops the user into an interactive shell from within a running task on Latch.
**Description:**
Provides interactive access to running or completed workflow executions for debugging and inspection purposes.
**Options:**
* `--execution-id, -e `: Optional execution ID to inspect
* `--egn-id, -g `: Optional task execution ID to inspect
* `--container-index, -c `: Optional container index to inspect (only used for Map Tasks)
To find these values, navigate to the [Executions tab](https://console.latch.bio/executions) → Double click on the Execution you want to inspect → Go to the **Graph & Logs** tab → Click on the rectangle representing the task you want to inspect → Copy the `latch exec` command from the right sidebar.
**Example:**
```bash theme={null}
latch exec --execution-id abc123
```
## Workflow Registration Commands
### `latch register `
Registers local workflow code to Latch.
**Options:**
* `-d, --disable-auto-version`: Whether to automatically bump the version of the workflow each time register is called
* `--remote/--no-remote`: Use a remote server to build workflow (default: True)
* `--docker-progress `: Docker build progress display (choices: plain, tty, auto, default: auto)
* `-y, --yes`: Skip the confirmation dialog
* `--open, -o`: Automatically open the registered workflow in the browser
* `--mark-as-release, -m`: Mark the registered workflow as a release
* `--workflow-module, -w `: Module containing Latch workflow to register (default: `wf`)
* `--metadata-root `: Directory containing Latch metadata (Nextflow and Snakemake only)
* `--snakefile ` \[**DEPRECATED**]: Path to a Snakefile to register.
* `--cache-tasks/--no-cache-tasks, -c/-C` \[**DEPRECATED**]: Whether or not to cache snakemake tasks.
* `--nf-script `: Path to a nextflow script to register
* `--nf-execution-profile `: Set execution profile for Nextflow workflow
* `--staging`: Register the workflow in "staging" mode. Build the workflow container image but do not publish a new workflow version on Latch Console. Recommended for testing and development before registering the workflow to your team workspace.
**Description:**
Builds and registers a workflow on the Latch platform. Registration triggers a new container image build and automatically creates a new workflow version in the Latch Console. When the --staging flag is used, no version is published.
**Example:**
```bash theme={null}
latch register my-workflow
latch register my-workflow --nf-script main.nf --nf-execution-profile test, docker
```
### `latch preview `
Creates a preview of your workflow interface.
**Description:**
Generates a preview of the workflow's user interface based on the defined parameters and metadata.
**Example:**
```bash theme={null}
latch preview my-workflow
```
## Workflow Management Commands
### `latch get-wf [--name ]` \[**DEPRECATED**]
This command is deprecated and will be removed in a future version of the CLI.
Lists workflows.
**Options:**
* `--name `: Filter by workflow name and display all versions. To find a workflow name, run latch get-wf without options and check the "Name" column in the output.
**Description:**
Displays a list of all workflows in the current workspace, including their IDs, names, and versions.
**Example:**
```bash theme={null}
latch get-wf
latch get-wf --name "nf_nf_core_rnaseq"
```
### `latch get-executions` \[**DEPRECATED**]
Spawns an interactive terminal UI that shows all executions in a given workspace.
This command is deprecated and will be removed in a future version of the CLI.
**Description:**
Provides an interactive interface to view workflow executions and their statuses.
**Example:**
```bash theme={null}
latch get-executions
```
## Data Management Commands
### Latch URLs
Latch URLs are a way to reference files and directories that live on [Latch Data](/data/overview).
When you are using the below CLI commands, you must use Latch URLs when refering remote files on Latch.
API and Usage Examples
### `latch cp `
Copy files between Latch Data and local, or between two Latch Data locations.
**Options:**
* `--progress `: Type of progress information to show while copying (choices: tasks, none, default: tasks)
* `--verbose, -v`: Print file names as they are copied
* `--no-glob, -G`: Don't expand globs in remote paths
* `--cores `: Manually specify number of cores to parallelize over
* `--chunk-size-mib `: Manually specify the upload chunk size in MiB (must be >= 5)
**Description:**
Behaves like `cp -R` in Unix. Directories are copied recursively. Supports copying between local and remote locations, and between remote locations.
**Example:**
```bash theme={null}
latch cp local_file.txt latch://.account/path/on/latch
latch cp latch://.account/path/on/latch latch://.account/path/on/latch
latch cp latch://.account/path/on/latch*.txt ./local_folder/
```
To find your remote Latch Data path: open your workspace, go to the [Latch Data tab](https://console.latch.bio/data), click the file or folder, then check the right sidebar for the path and use the copy icon.
### `latch mv `
Move remote files in LatchData.
**Options:**
* `--no-glob, -G`: Don't expand globs in remote paths
**Description:**
Moves files and directories within the Latch Data storage system.
**Example:**
```bash theme={null}
latch mv latch://.account/old/path/on/latch latch://.account/new/path/on/latch
```
### `latch ls [paths]`
List the contents of a Latch Data directory.
**Options:**
* `--group-directories-first, --gdf`: List directories before files
**Description:**
Lists the contents of specified remote directories. If no paths are provided, defaults to the root directory.
**Example:**
```bash theme={null}
latch ls
latch ls latch://.account/my-folder/
latch ls latch://.account/folder1/ latch://.account/folder2/ --group-directories-first
```
### `latch rmr `
Deletes a remote entity.
**Options:**
* `-y, --yes`: Skip the confirmation dialog
* `--no-glob, -G`: Don't expand globs in remote paths
* `--verbose, -v`: Print all files when deleting
**Description:**
Recursively deletes files and directories from Latch Data storage.
**Example:**
```bash theme={null}
latch rmr latch://.account/old-folder/ --yes
```
### `latch mkdirp `
Creates a new remote directory.
**Description:**
Creates directories in Latch Data storage, including parent directories as needed.
**Example:**
```bash theme={null}
latch mkdirp latch://.account/new-folder/subfolder/
```
### `latch sync ... `
Update the contents of a remote directory with local data.
**Options:**
* `--delete`: Delete extraneous files from destination
* `--ignore-unsyncable`: Synchronize even if some source paths do not exist or refer to special files
* `--cores `: Number of cores to use for parallel syncing
**Description:**
Synchronizes local files and directories with remote storage, similar to `rsync`. Currently only supports local to remote synchronization.
**Example:**
```bash theme={null}
latch sync ./local_folder/ latch://remote/path/
latch sync ./file1.txt ./file2.txt latch://remote/destination/ --delete
```
## Nextflow Commands
### `latch nextflow version `
Get the Latch version of Nextflow installed for the current project.
**Description:**
Displays the Nextflow version that will be used for the workflow execution.
**Example:**
```bash theme={null}
latch nextflow version my-nextflow-workflow-directory
```
### `latch nextflow generate-entrypoint `
Generate a `wf/entrypoint.py` file from a Nextflow workflow.
**Options:**
* `--metadata-root `: Directory containing Latch metadata
* `--nf-script `: Path to the nextflow entrypoint to register (required)
* `--execution-profile `: Set execution profile for Nextflow workflow
**Description:**
Creates a Python entrypoint file that wraps the Nextflow workflow for execution on Latch.
**Example:**
```bash theme={null}
# currently in the root directory of the nextflow workflow
latch nextflow generate-entrypoint . --nf-script main.nf
```
### `latch nextflow attach`
Drops the user into an interactive shell to inspect the workdir of a nextflow execution.
**Options:**
* `--execution-id, -e `: Optional execution ID to inspect. Find the execution ID by navigating to the desired execution in the [Executions tab](https://console.latch.bio/executions) and copying the execution ID from the sidebar.
**Description:**
Provides interactive access to Nextflow workflow execution directories for debugging and inspection.
**Example:**
```bash theme={null}
latch nextflow attach --execution-id abc123
```
### `latch nextflow register ` \[**EXPERIMENTAL**]
This command is only applicable if you are using **Forch** - Latch's new architecture that allows you to run Nextflow pipelines within your own AWS account.
Register a Nextflow workflow with Latch.
**Options:**
* `--yes, -y`: Skip confirmation dialogs
* `--no-ignore, --all, -a`: Add all files (including those excluded by .gitignore/.dockerignore) to workflow archive
* `--disable-auto-version, -d`: Only use the contents of the version file for workflow versioning
* `--disable-git-version, -G`: When the package root is a git repository, do not append the current commit hash to the version
* `--script-path `: Path to the entrypoint nextflow file (default: "main.nf")
**Description:**
Registers a Nextflow workflow with Latch, handling versioning and packaging automatically.
**Example:**
```bash theme={null}
latch nextflow register my-nextflow-workflow-directory --script-path workflow.nf
```
## Pod Management Commands
### `latch pods stop [pod_id]`
Stops a [Latch Pod](/pods/overview) given a pod\_id or the pod from which the command is run.
**Description:**
Shuts down a running pod. If no `pod_id` is provided, the command attempts to stop the pod from which the command is executed. Useful for autoshutting down the pod after a long-running script finishes to save costs.
**Example:**
```bash theme={null}
latch pods stop 12345
latch pods stop # Stops the current pod
```
## Test Data Commands
### `latch test-data upload `
Uploads test data to a public Latch S3 bucket. Useful for releasing public test data for a workflow without setting up your own public S3 bucket.
**Options:**
* `--dont-confirm-overwrite, -d`: Automatically overwrite any files without asking for confirmation
**Description:**
Uploads test data files to a managed public Latch S3 bucket for use in workflow development and testing.
**Example:**
```bash theme={null}
latch test-data upload ./test_data.csv
```
### `latch test-data ls`
List test data objects.
**Description:**
Lists all test data objects in the managed bucket by their full S3 paths.
**Example:**
```bash theme={null}
latch test-data ls
```
### `latch test-data remove `
Remove test data object.
**Description:**
Removes test data objects from the managed bucket.
**Example:**
```bash theme={null}
latch test-data remove s3://latch-public/test_data.csv
```
## Deprecated Commands
### `latch get-params ` \[**DEPRECATED**]
This command is deprecated and will be removed in a future version of the CLI.
Generate a python parameter map for a workflow.
**Description:**
This command is deprecated and frequently broken. For programmatic workflow execution, use the [Python API](/workflows/sdk/testing-and-debugging-a-workflow/programmatic-execution) instead.
### `latch launch ` \[**DEPRECATED**]
This command is deprecated and will be removed in a future version of the CLI.
Launch a workflow using a python parameter map.
**Description:**
This command is deprecated and frequently broken. For programmatic workflow execution, use the [Python API](/workflows/sdk/testing-and-debugging-a-workflow/programmatic-execution) instead.
## Global Options
* `--version`: Show the version and exit
* `--help`: Show help message and exit
## Examples
### Complete Nextflow Workflow Upload Flow
```bash theme={null}
# 1. Navigate to your Nextflow workflow directory
cd my-nextflow-workflow
# 2. Generate Latch metadata to define the graphical user interface on Latch from your Nextflow schema
latch generate-metadata nextflow_schema.json --nextflow
# 3. Register the workflow with Latch
latch register . --nf-script main.nf --nf-execution-profile docker,test
# 4. The workflow is now available in the Latch Console
# You can launch it via the web interface or programmatically
```
### Data Management Workflow
```bash theme={null}
# 1. Upload data
latch cp ./local_data/ latch://.account/folder/on/latch
# 2. List contents
latch ls latch://.account/folder/on/latch
# 3. Sync updates
latch sync ./updated_data/ latch://.account/folder/on/latch
# 4. Clean up
latch rmr latch://.account/folder/on/latch
```
## Notes
* Most commands require authentication via `latch login`
* The CLI automatically checks for updates and warns if you're using an outdated version
* Development sessions provide cloud-based environments for testing workflows
* Data operations support both local and remote paths using the `latch://` prefix
# Overview
Source: https://wiki.latch.bio/workflows/sdk/console/execution-monitoring
Monitor all workflow executions through Latch Console with comprehensive visibility into execution status, logs, inputs/outputs, and provenance tracking.
This page provides a top-down overview of the Workflows product tab in Latch Console. It is useful for understanding what the tabs mean and how to navigate to them.
First, navigate to the Workflows product tab on Latch Console by clicking on the icon on the left sidebar.
There are three tabs for Workflows in the Latch Console:
1. **Workflows**: Include private and public workflows
2. **Executions**: Include all executions that have been launched for all workflows in the current workspace
3. **Automations**: Include all automations that have been created in the current workspace
# Workflows
Include private workflows within a workspace and all public workflows.
### My Workflows
* Shows all workflows that have been uploaded to your workspace, or added from the All Workflows tab.
* For developers, any workflow you have registered with the `latch register` command will show up here.
### All Workflows
* Shows all publicly available workflows.
* Workflows with the "Verified" tag have been curated and battle-tested by the Latch engineering team. Community-built workflows are not actively vetted so their quality may vary.
### For a specific workflow
When you double-click on a specific workflow in "My Workflows" or "All Workflows", you'll be taken to the workflow's dedicated page, which contains:
* **About page**: Where the workflow author includes a description of the workflow, and any other relevant information. (For developers, learn how to customize the About page [here](/workflows/sdk/ui/latch-metadata)).
* **Parameters page**: Where you can fill out parameters and launch the workflow. For developers, learn how to customize the Parameters page [here](/workflows/sdk/ui/latch-metadata).
* **Graph page**: A visual representation of the workflow's directed acyclic graph (DAG). When the workflow is launched, the DAG will be populated with the workflow's task logs.
* **Executions page**: All past executions that have been launched for this workflow. You can filter by workflow version, status, and who it was run by.
* **(Optional) Development page**: If you are the developer who registered the workflow, you will also see a Development tab, which tracks all workflow versions, creation date, release status, and associated Git commit. Visit the [Development page](/workflows/sdk/console/versioning) to learn more.
# Executions
Show all executions that have been launched for all workflows in the current workspace.
### For a specific execution
When you double click on a specific execution, you will see:
* **Inputs page**: The inputs that were used to launch the workflow.
* **Results page**: The outputs that were generated by the workflow. (For developers: You can customize this page to highlight specific files you want to show scientists. Visit docuemntation [here](/workflows/sdk/ui/results))
* **Graph and Logs**: Statuses and logs for all processes that were run as part of the workflow.
* **Messages**: Any messages that were generated by the workflow (For developers: You can customize this page to highlight specific messages you want to show scientists. Visit documentation [here](/workflows/sdk/ui/messages))
* **Usage report**: A summary of the resources that were used to run the workflow. (For developers: Learn more how to use the usage report to optimize your workflow here [here](/workflows/sdk/console/usage-report))
* **Sidebar**: For every execution, on the sidebar, you can see duration, cost, who launched the workflow, inputs and outputs.
* **Execution controls**: On the same sidebar, and buttons to abort, relaunch, and relaunch from failed task.
* *Abort*: Button is available if the workflow is still running and you want to stop it.
* *Relaunch*: Button is available if the workflow has completed and you want to run it again.
* *Relaunch with a dropdown for "Relaunch from failed task"*: Button is available if the workflow has completed but failed and you want to run it again from the failed task without rerunning successful upstream tasks.
# Automations
Place to create and manage automations.
* Visit [Automations page](/workflows/sdk/automation) to learn how to create and manage automations.
# Resource Monitoring
Source: https://wiki.latch.bio/workflows/sdk/console/resource-monitoring
Workflows on Latch provide visibility into the resource usage of each task execution, enabling developers to easily debug and optimize their workflow.
To view the resource usage for a workflow, navigate to the `Usage Report` tab for a workflow execution.
The following is a usage report for a nf-core/methylseq execution.
The report collects 5 key metrics for each workflow task:
1. **CPU**: Each data point represents the number of cores used by the task over a time period.
This time period is determined by the operating system and defaults to 100 milliseconds.
For example, a value of 2.0 cores means that the task used 2 cores in the past 100 milliseconds.
*Note: The number of cores used may be temporarily higher than the number of cores allocated.
This can happen if the task is scheduled on a machine with more cores than what was requested by the task.
This is expected behavior.*
2. **Memory**: Number of bytes of memory allocated by the task.
3. **Disk**: Number of bytes of local disk space (EBS) used by the task.
4. **Network Rx**: Bytes received over the network. Only displayed on task completion.
5. **Network Tx:** Bytes transmitted over the network. Only displayed on task completion.
For running tasks, the usage report shows the *latest* usage for each metric.
For completed tasks, it shows the *average* usage.
To further investigate usage for a particular task, select the blue icon next to the metric to view
a graph of usage over time.
You can easily navigate to your highest usage tasks by selecting a header to sort the table by.
# Versioning
Source: https://wiki.latch.bio/workflows/sdk/console/versioning
Workflows on Latch are versioned to track changes to the codebase and ensure reproducibility. The Latch SDK automatically
generates a unique version string. The workflow version has two components `-`
1. `version` is a user-defined string (ex. "0.0.1") read from your project root directory's `version` file. It can be overridden
to provide a user-friendly name for the workflow version.
2. `directory_hash` is a hash of the project directory. It ensures a unique version string is generated if the directory
contents change.
## Git Versioning
Workflows on Latch can be versioned using Git. If the SDK detects that the project directory is a Git repository,
it will append the first six digits of the latest commit hash to the workflow version.
`--`
If the git repository has uncommitted changes, the SDK will append `-wip` to the commit-hash.
`--wip-`
## Remote Repositories
Developers may provide a link to the remote repository where their source code is hosted in the `LatchMetadata` object:
```python theme={null}
from latch import LatchMetadata
metadata = LatchMetadata(
...
repository="https://github.com/latchbio/latch",
)
```
If a remote repository is specified, a link to the commit associated with each workflow version
will be available under the `Development` tab on the workflow page.
# Caching and Resuming
Source: https://wiki.latch.bio/workflows/sdk/nextflow/caching
The Nextflow integration leverages Nextflow's built-in caching mechanism to
store intermediate results of a workflow execution.
These cached outputs are retained after the execution has
completed, allowing users to make changes to their workflow and relaunch
without re-running the entire workflow.
By default, Latch will not store the intermediate outputs of a workflow after
completion. To enable this feature, update the `storage_expiration_hours` field
in the `NextflowResourceRuntime` object in your `latch_metadata`. This field
configures the number of hours the cache will be available for relaunch after
failure. If the workflow succeeds, the cache will be deleted immediately.
```python theme={null}
from latch.types.metadata import NextflowMetadata, NextflowRuntimeResources
NextflowMetadata(
...
runtime_resources=NextflowRuntimeResources(
storage_expiration_hours=7
)
)
```
The Nextflow work directory is stored in AWS EFS; therefore, increasing the `storage_expiration_hours`
for your workflow can significantly increase its cost.
The storage costs associated with Nextflow workflows can be found under "Nextflow EFS"
section on the Latch Console billing page.
Once you have configured the `storage_expiration_hours` and launched your updated
workflow, you can resume failed executions from the Latch Console.
To resume a Nextflow pipeline from a failed task, click the "Relaunch from
Failed Task" button in the sidebar of your workflow execution:
# Debugging Nextflow
Source: https://wiki.latch.bio/workflows/sdk/nextflow/debugging
Available in `latch >= 2.53.8`
To enable developers to easily debug failed Nextflow workflows on Latch, the Latch SDK provides support
for inspecting the contents of an execution's work directory. This allows users to inspect/create/update
files in the work directory and relaunch the workflow using the updated state.
*Note: Once an execution's work directory has expired, it can no longer be inspected. See [Caching and Resuming](/workflows/sdk/nextflow/caching) for information
on how to extend the expiration of an execution's work directory.*
To get started, verify that you are using `latch >= 2.53.8`.
```bash theme={null}
latch --version
```
To debug an execution, run the following command:
```bash theme={null}
latch nextflow attach
```
This will prompt you to select the name of the execution you wish to debug:
After selecting an execution, the Latch SDK will connect you to a container containing the contents of that execution's work directory.
The work directory is mounted under `/nf-workdir` inside the container. Once you are connected, you can inspect, create, and/or update
files. Any changes made inside the container will be reflected in the work directory of the execution.
# Dependencies
Source: https://wiki.latch.bio/workflows/sdk/nextflow/dependencies
Latch's Nextflow integration is built on top of Nextflow 23.11.0 and includes additional functionality
to support execution on the Latch platform.
Latch's patched version of Nextflow is included in the Dockerfile generated by the Latch SDK.
This Dockerfile is generated at `.latch/Dockerfile` in your project directory when a Nextflow workflow
is registered.
## Updating Nextflow
The Latch development team will periodically update the Nextflow version to include new features, optimizations, and bug fixes.
The full changelog of features can be found [here](https://github.com/latchbio/nextflow/blob/dynamic-rewrite/CHANGELOG.md).
You can view the version of Nextflow that your workflow is running by inspecting the `.latch/Dockerfile` in your project directory.
The `FROM` line at the top of the file will include the Nextflow version that your workflow is running. For example, the following
Dockerfile is using Nextflow version 1.1.3:
```dockerfile, theme={null}
# DO NOT CHANGE
from 812206152185.dkr.ecr.us-west-2.amazonaws.com/latch-base-nextflow:v1.1.3
...
```
To upgrade to the latest version, you can modify your `.latch/config` file to include the desired version of Nextflow.
For example, to upgrade to version `1.1.4`, you can update the `base_image` field in your `.latch/config` file:
```json theme={null}
{"latch_version": "2.50.3", "base_image": "812206152185.dkr.ecr.us-west-2.amazonaws.com/latch-base-nextflow:v1.1.4", "date": "2024-07-15T16:48:40.691490"}
```
Once you re-register your workflow, the Latch SDK will generate a new Dockerfile with the updated Nextflow version.
When updating your version of Nextflow, it is also highly recommended to update your version of the Latch SDK to the latest version.
# Using GPU Accelerators
Source: https://wiki.latch.bio/workflows/sdk/nextflow/gpus
Latch supports using Nextflow [accelerators](https://www.nextflow.io/docs/latest/reference/process.html#accelerator) to allow processes to leverage GPU compute.
## Usage
Modify your Nextflow process code to include the accelerator type.
```nextflow theme={null}
process {
accelerator 4, type : "nvidia-v100"
}
```
The above examples will request 4 GPUs of type `nvidia-v100` (See the full GitHub repository [here](https://github.com/latchbio-nfcore/methylseq/blob/0cc4f84668575491cb06ced2bf099cfc07fad2db/modules/nf-core/AriocP/align/main.nf#L2)).
## Caveats
GPU enabled nodes have very strictly constrained compute parameters. As a result, specifying an accelerator will override any `cpu/memory` settings, with overridden values changing depending on the chosen accelerator.
## Supported Accelerators
Latch supports the following accelerator types:
1. `nvidia-t4`: This allows a process to use an Nvidia T4 GPU for compute. A process specifying `type: 'nvidia-t4'` can use only 1 GPU. Choosing `nvidia-t4` will override and set `cpu: 7` and `memory: "30Gi"`.
2. `nvidia-a10g`: This allows a process to use an Nvidia A10G GPU for compute. A process specifying `type: 'nvidia-a10g'` can use only 1 GPU. Choosing `nvidia-a10g` will override and set `cpu: 64` and `memory: "256Gi"`.
3. `nvidia-v100`: This allows a process to use an Nvidia V100 GPU for compute. A process specifying `type: 'nvidia-v100'` can choose between 1, 4, or 8 GPUs. Choosing `nvidia-v100` will override and set resources differently depending on the number of GPUs specified:
* Choosing 1 GPU will override and set `cpu: 7` and `memory: "48Gi"`,
* Choosing 4 GPUs will override and set `cpu: 30` and `memory: "230Gi"`, and
* Choosing 8 GPUs will override and set `cpu: 62` and `memory: "400Gi"`.
# Overview
Source: https://wiki.latch.bio/workflows/sdk/nextflow/overview
Latch's Nextflow integration allows developers to build graphical interfaces to expose their Nextflow workflows to wet lab teams.
It also provides managed cloud infrastructure to execute, debug, and analyze your workflows.
A primary goal for the Nextflow integration is to allow developers to register existing Nextflow projects with minimal added boilerplate and modifications
to code.
## How it works
Latch's Nextflow integration is built on top of [Latch Workflows](/workflows/sdk/python/what-is-a-workflow). When registering a Nextflow project
on Latch, the Latch SDK generates a workflow that runs the Nextflow pipeline. The generated workflow consists of two tasks:
1. `Initialization`: provisions a shared storage device containing a filesystem that will store processes' inputs and outputs. Costs associated with
the shared filesystem are NOT included in the workflow costs. The shared filesystem costs can be found on the Billing page under "Nextflow EFS".
2. `Nextflow Runtime`: stages the input files on the shared filesystem and executes the Nextflow workflow as a subprocess. The Nextflow runtime contains a
patched version of the Nextflow Kubernetes plugin to execute processes in a containerized environment. As the workflow launches processes,
the Latch SDK will monitor the workflow's progress and update the Latch Console with the workflow's status.
To see the integration in action, check out the [Nextflow tutorial](/workflows/sdk/nextflow/tutorial).
# Execution Profiles
Source: https://wiki.latch.bio/workflows/sdk/nextflow/profiles
Latch supports Nextflow [execution profiles](https://www.nextflow.io/docs/latest/config.html#config-profiles)
which allows users to group related configuration parameters. Users can specify
which configuration profile to use when running their pipeline statically
at registration time or dynamically when launching their workflow in the Latch UI.
## Configuring profiles at workflow registration
To specify an execution profile to use when running the workflow on Latch, pass the
`--nf-execution-profile` flag to the `latch register` command.
For example, to specify the `docker` profile:
```bash theme={null}
latch register . --nf-script main.nf --nf-execution-profile docker
```
The execution profile specified will be hidden from the user on the frontend,
and cannot be changed without re-registering the workflow.
## Configuring profiles at workflow execution
To enable users to dynamically select an execution profile when launching a workflow,
use the `execution_profiles` parameter in the `NextflowMetadata` object as follows:
```python theme={null}
from latch.types.metadata import (
NextflowMetadata,
LatchAuthor,
NextflowRuntimeResources
)
from latch.types.directory import LatchDir
from .parameters import generated_parameters
NextflowMetadata(
display_name='Workflow Name',
author=LatchAuthor(
name="Your Name",
),
parameters=generated_parameters,
execution_profiles=["docker", "test"], # ADDED
log_dir=LatchDir("latch:///your_log_dir"),
)
```
This will generate the following dropdown in the Latch UI, enabling users to select
a subset of the execution profiles provided when launching the workflow:
# Private Registries
Source: https://wiki.latch.bio/workflows/sdk/nextflow/registries
When executing Nextflow workflows, processes may use container images hosted in private registries that the Latch cloud cannot access.
## Granting Permissions
To grant Latch workflows access to your private registries, navigate to the Latch Console and head to Workspace Settings.
From there, navigate to Developer Settings
From there, scroll down and select the `Docker` widget
Then, enter the username, password, and registry URL for the private registry you wish to grant access to.
You should now be able to run workflows that use images from your private registry.
# Shared Storage
Source: https://wiki.latch.bio/workflows/sdk/nextflow/shared-storage
## Overview
One of the main requirements of Nextflow workflows is having a shared, POSIX-compliant file system among all workflow tasks. All of the input files are downloaded and staged into a "workdir," a mounted shared filesystem directory. The workflow tasks then access these files as part of their computation and write intermediate or output files back to the workdir.
A shared filesystem is required since the inputs to workflows might be extremely large, with multiple terabytes of data, and tasks must share files even if they are scheduled on different nodes in the cluster. Having a shared filesystem allows the tasks to write an unlimited amount of data without requesting a lot of storage resources.
Latch provides two options for shared storage when running Nextflow workflows: EFS and ObjectiveFS.
## EFS
[EFS](https://docs.aws.amazon.com/efs/latest/ug/whatisefs.html) is a shared file system with nearly unlimited storage capacity and high throughput which is offered by AWS. EFS is mounted into every process in Nextflow and can be accessed as any other directory.
EFS scales with the growing need for storage so it can support both small and large workloads without suffering performance degradation. EFS provides strong data consistency and file locking which is one of the requirements for Nextflow shared file systems.
## OFS
[ObjectiveFS](https://objectivefs.com/)(OFS) is a serverless shared filesystem built on top of AWS S3 as its storage layer. It has a different architecture from EFS as it processes file operations directly on the host and not on a set of central servers.
OFS filesystem is POSIX compliant and can scale up to 1 PB of data. OFS provides read-and-write consistency guarantees and the same durability and availability guarantees as AWS S3 while having high read-and-write performance and enforced data encryption.
## Usage Examples
By default, all new workflows generated with `latch init` will use OFS as an underlying storage. Follow the [Nextflow Tutorial](/workflows/sdk/nextflow/tutorial) in order to generate a Nextflow project on Latch.
To configure your filesystem, you can change the `initialize` method in `wf/entrypoint.py` file.
1. `initialize` step of the workflow will provision a shared filesystem. Here you can configure which filesystem you want to use for your workflow.
```python theme={null}
@custom_task(cpu=0.25, memory=0.5, storage_gib=1)
def initialize() -> str:
"""
Initialize the workflow by provisioning a shared storage volume.
This function requests a shared storage volume from the Nextflow dispatcher service
and returns the name of the provisioned volume.
Returns:
str: The name of the provisioned storage volume.
Raises:
RuntimeError: If the execution token is not available.
"""
token = os.environ.get("FLYTE_INTERNAL_EXECUTION_ID")
if token is None:
raise RuntimeError("failed to get execution token")
headers = {"Authorization": f"Latch-Execution-Token {token}"}
print("Provisioning shared storage volume... ", end="")
resp = requests.post(
### CHANGE THE URL HERE TO PROVISION OFS OR EFS
"http://nf-dispatcher-service.flyte.svc.cluster.local/provision-storage-ofs",
headers=headers,
json={
"version": 2,
"storage_expiration_hours": 100, #storage will expire in 100 hours after start of execution
# "fs_size_tb": 10, # OFS only: specify expected file system size in order to provision more memory for tasks
},
)
resp.raise_for_status()
print("Done.")
return resp.json()["name"]
```
2. Use the URL of the request above to `http://nf-dispatcher-service.flyte.svc.cluster.local/provision-storage-ofs` to provision OFS storage or use `http://nf-dispatcher-service.flyte.svc.cluster.local/provision-storage-efs` to provision EFS storage.
3. You can specify multiple parameters to configure your shared filesystem for your workload.
* `storage_expiration_hours` option specifies when to clean up the data in your storage. Set to `0` hours to delete storage after execution completes. Set this parameter to a non-zero value to keep storage for relaunching.
* EFS storage expiration defaults to 0 hours.
* OFS storage expiration defaults to 30 days.
* `version` option specifies the version of Nextflow integration to use. For most cases, it should always be set to `2` for new workflows unless you are running a legacy workflow built on version `1` of Nextflow integration.
* `fs_size_tb`(OFS only) - approximate expected size in TBs for the filesystem. OFS requires you to specify the filesystem size ahead of time to provision more memory for the task. See [OFS task memory requirement](#ofs-task-memory-requirement) for more details.
### OFS task memory requirement
Unlike EFS, OFS is not an NFS filesystem and does not use an external server to process file requests. OFS runs as a FUSE process on every node in the cluster and mounts the filesystem into every workflow task. OFS uses node memory to store the file system index and local cache in order to speed up file operations and it requires each workflow task to request extra memory to properly account for OFS memory usage.
With the `fs_size_tb` parameter you can specify an approximate storage size of your filesystem which will change the memory requirement for each workflow task. The following are the memory requirements for file system size:
| Filesystem Size(TB) | Additional Task Memory Request(GB) |
| ------------------- | ---------------------------------- |
| 0-1 | 2 |
| 2-10 | 3 |
| 11-20 | 4 |
| 21-30 | 5 |
| 31-40 | 6 |
| 41-50 | 7 |
You can approximate the size of your filesystem by adding up all input file sizes and multiplying by 2 to account for intermediate files.
## Comparison
### Cost
The main difference between EFS and OFS is their cost models and the underlying storage layer.
EFS pricing model includes charges for data storage and data access. OFS uses S3 as its storage layer, so the pricing model includes charges for mounting OFS filesystems, S3 storage, and the additional RAM provisioned for the tasks.
| | EFS | ObjectiveFS |
| ------------------------------- | ---- | ----------- |
| Storage(\$/GB/month) | 0.30 | 0.023 |
| Throughput Reads (\$/GB/month) | 0.03 | N/A |
| Throughput Writes (\$/GB/month) | 0.06 | N/A |
| Mount Cost(\$/mount/hr) | N/A | 0.18 |
| RAM cost(\$/GiB/hr) | N/A | 0.009972 |
### Performance
OFS has a better performance overall on 1 mount benchmarks. However, EFS throughput is higher in a Nextflow environment with many tasks reading and writting to the same file system due to slow distributed file locking in OFS. Both systems perform well on common Nextflow workloads.
| | EFS | ObjectiveFS |
| ----------------------------------- | ------ | ----------- |
| Sequential Read(MB/s) | 92.55 | 122.23 |
| Sequential Write(MB/s) | 124.20 | 125.07 |
| Random Read(MB/s) | 58.39 | 77.79 |
| Random Write(MB/s) | 73.69 | 87.90 |
| Staging to workdir from LData(MB/s) | 212.31 | 188.40 |
| Writing to LData from workdir(MB/s) | 246.64 | 208.74 |
Notes:
* To get the sequential read/write benchmarks, we measured the time to copy a 1GB file to and from the file system.
* To get the random read/write benchmarks, we measured the time to copy 1GB by randomly choosing 1MB chunks and writing to/from the file system.
* To get the staging benchmarks, we measured the total time to download the file to/from LData to filesystem and vice versa.
* OFS benchmarks were performed on pre-warmed cache
## Choosing Shared Storage Option
The correct storage solution depends on your workload and budget requirements. Here is the summary of the file system comparison:
| | EFS | ObjectiveFS |
| -------------- | --- | ----------- |
| Cost | +++ | + |
| Performance | +++ | ++ |
| Execution time | + | ++ |
### EFS:
Pros:
* Stable high throughput on Nextflow workloads
Cons:
* Expensive. The throughput and storage costs of EFS can be very significant depending on the input size and the workload.
* Storing data for relaunch can be expensive
### OFS
Pros:
* Lower cost due to using S3. Does not have throughput charges.
* Good performance with pre-warmed cache
Cons:
* Throughput can vary more on Nextflow workloads
* Requires all tasks to provision extra memory
## Summary
For most workloads, OFS is a better, more cost-effective option. OFS performs well on most workloads and allows for cheaper experiments. The executions are usually bound by the CPU processing time of the inputs therefore the decreased file system throughput in Nextflow environment doesn't impact workflow performance significantly on most workloads.
# Tutorial
Source: https://wiki.latch.bio/workflows/sdk/nextflow/tutorial
Learn how to upload a Nextflow workflow on Latch.
This tutorial will outline the steps required to launch a Nextflow pipeline on Latch.
## Prerequisites
* Register for an account and log into the [Latch Console](https://console.latch.bio)
* Install the Latch SDK `>= 2.67.5`
Example on Ubuntu:
```bash theme={null}
$ python3 -m venv env
$ source env/bin/activate
$ pip install latch
```
It's highly recommended to install the Latch SDK in a fresh environment for best behavior.
## Step 1: Clone your Nextflow pipeline
We will use nf-core's [rnaseq](https://nf-co.re/rnaseq/3.14.0) as an example; however, feel free to follow along with any Nextflow pipeline.
```bash theme={null}
git clone https://github.com/nf-core/rnaseq
cd rnaseq
```
## Step 2: Define metadata and workflow graphical interface
The input parameters need to be explicitly defined to construct a graphical interface for a Nextflow pipeline. These parameters will be exposed to scientists in a web interface once the workflow is uploaded to Latch.
The Latch SDK provides a command to automatically generate the metadata file from an existing `nextflow_schema.json` file. When developers change their workflow in the future, they can simply update the `nextflow_schema.json` file and re-run the `generate-metadata` command again to update the metadata file.
```bash theme={null}
latch generate-metadata nextflow_schema.json --nextflow
```
The command parses parameters defined in the `nextflow_schema.json` and generates two files:
```
latch_metadata/generated.py
latch_metadata/__init__.py
```
### `latch_metadata/generated.py`
This file defines workflow parameters and controls how they appear in the UI.
````python latch_metadata/generated.py expandable theme={null}
# This file is auto-generated, PLEASE DO NOT EDIT DIRECTLY! To update, run
#
# $ latch generate-metadata --nextflow nextflow_schema.json
#
# Add any custom logic or parameters in `latch_metadata/__init__.py`.
import typing
from dataclasses import dataclass, field
from enum import Enum
import typing_extensions
from flytekit.core.annotation import FlyteAnnotation
from latch.ldata.path import LPath
from latch.types.directory import LatchDir
from latch.types.file import LatchFile
from latch.types.metadata import Params, Section, Spoiler, Text
from latch.types.samplesheet_item import SamplesheetItem
class StrandednessType(Enum):
forward = 'forward'
reverse = 'reverse'
unstranded = 'unstranded'
auto = 'auto'
@dataclass
class InputType:
sample: typing_extensions.Annotated[str, FlyteAnnotation({'display_name': 'Sample', 'default': None, 'samplesheet': False, 'output': False, 'required': True, 'errorMessage': 'Sample name must be provided and cannot contain spaces'})]
fastq_1: typing_extensions.Annotated[LatchFile, FlyteAnnotation({'display_name': 'Fastq 1', 'default': None, 'samplesheet': False, 'output': False, 'required': True, 'errorMessage': "FastQ file for reads 1 must be provided, cannot contain spaces and must have extension '.fq.gz' or '.fastq.gz'"})]
fastq_2: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Fastq 2', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'errorMessage': "FastQ file for reads 2 cannot contain spaces and must have extension '.fq.gz' or '.fastq.gz'"})]
strandedness: typing_extensions.Annotated[StrandednessType, FlyteAnnotation({'display_name': 'Strandedness', 'default': None, 'samplesheet': False, 'output': False, 'required': True, 'errorMessage': "Strandedness must be provided and be one of 'auto', 'forward', 'reverse' or 'unstranded'"})]
class PseudoAlignerType(Enum):
salmon = 'salmon'
kallisto = 'kallisto'
class SalmonQuantLibtypeType(Enum):
A = 'A'
IS = 'IS'
ISF = 'ISF'
ISR = 'ISR'
IU = 'IU'
MS = 'MS'
MSF = 'MSF'
MSR = 'MSR'
MU = 'MU'
OS = 'OS'
OSF = 'OSF'
OSR = 'OSR'
OU = 'OU'
SF = 'SF'
SR = 'SR'
U = 'U'
class ContaminantScreeningType(Enum):
kraken2 = 'kraken2'
kraken2_bracken = 'kraken2_bracken'
class TrimmerType(Enum):
trimgalore = 'trimgalore'
fastp = 'fastp'
class UmiDedupToolType(Enum):
umitools = 'umitools'
umicollapse = 'umicollapse'
class UmitoolsGroupingMethodType(Enum):
unique = 'unique'
percentile = 'percentile'
cluster = 'cluster'
adjacency = 'adjacency'
directional = 'directional'
class AlignerType(Enum):
star_salmon = 'star_salmon'
star_rsem = 'star_rsem'
hisat2 = 'hisat2'
class BrackenPrecisionType(Enum):
D = 'D'
P = 'P'
C = 'C'
O = 'O'
F = 'F'
G = 'G'
S = 'S'
class PublishDirModeType(Enum):
symlink = 'symlink'
rellink = 'rellink'
link = 'link'
copy = 'copy'
copyNoFollow = 'copyNoFollow'
move = 'move'
@dataclass
class NextflowSchemaArgsType:
input: typing_extensions.Annotated[typing.List[SamplesheetItem[InputType]], FlyteAnnotation({'display_name': 'Input', 'default': None, 'samplesheet': True, 'output': False, 'required': True, 'description': 'Path to the sample sheet (CSV) containing metadata about the experimental samples.', 'help_text': 'Provide the full path to a comma-separated sample sheet with 4 columns and a header row. This file is required to run the pipeline. See the [nf-core/rnaseq sample sheet documentation](https://nf-co.re/rnaseq/usage#samplesheet-input) for example format.', 'errorMessage': "The input must be a valid CSV file path with no spaces, ending in '.csv', and must exist."})]
outdir: typing_extensions.Annotated[LatchDir, FlyteAnnotation({'display_name': 'Outdir', 'default': None, 'samplesheet': False, 'output': True, 'required': True, 'description': 'The output directory where the results will be saved. You have to use absolute paths to storage on Cloud infrastructure.'})]
email: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Email', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Email address for completion summary.', 'help_text': "Provide your email address to receive a summary report when the workflow completes. If set in your user config file (`~/.nextflow/config`), you don't need to specify this for each run.", 'errorMessage': "The email must be a valid address in the format 'name@example.com' and must not contain spaces."})]
multiqc_title: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Multiqc Title', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'MultiQC report title. Printed as page header, used for filename if not otherwise specified.'})]
genome: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Genome', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Name of iGenomes reference.', 'help_text': 'If using a reference genome configured with iGenomes (not recommended), provide the ID for the reference (e.g., `--genome GRCh38`). This builds paths for all required reference files. See the [nf-core documentation](https://nf-co.re/usage/reference_genomes) for details.', 'errorMessage': 'The genome name must not contain spaces and must be a valid identifier.'})]
fasta: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Fasta', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to FASTA genome file.', 'help_text': "This parameter is mandatory if `--genome` is not specified. If you don't have the appropriate alignment index, it will be generated automatically. Use with `--save_reference` to store the index for future runs.", 'errorMessage': 'The FASTA file path must end with .fa, .fna, .fasta optionally with .gz, must not contain spaces, and must exist.'})]
gtf: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Gtf', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to GTF annotation file.', 'help_text': 'This parameter is mandatory if `--genome` is not specified.', 'errorMessage': 'The GTF file must have a .gtf or .gtf.gz extension, must not contain spaces, and must exist.'})]
gff: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Gff', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to GFF3 annotation file.', 'help_text': 'This parameter must be specified if neither `--genome` nor `--gtf` is provided.', 'errorMessage': 'The GFF file must have a .gff or .gff.gz extension, must not contain spaces, and must exist.'})]
gene_bed: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Gene Bed', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to BED file containing gene intervals. This will be created from the GTF file if not specified.', 'errorMessage': 'The BED file must have a .bed or .bed.gz extension, must not contain spaces, and must exist.'})]
transcript_fasta: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Transcript Fasta', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to FASTA transcriptome file.'})]
additional_fasta: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Additional Fasta', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'FASTA file to concatenate to genome FASTA file e.g. containing spike-in sequences.', 'help_text': 'If provided, sequences in this file will be concatenated to the genome FASTA file. A GTF file will be automatically created using these sequences, and alignment indices will be created from the combined files. Use `--save_reference` to reuse these indices in future runs.'})]
splicesites: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Splicesites', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Splice sites file required for HISAT2.'})]
star_index: typing_extensions.Annotated[typing.Optional[LPath], FlyteAnnotation({'display_name': 'Star Index', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to directory or tar.gz archive for pre-built STAR index.'})]
hisat2_index: typing_extensions.Annotated[typing.Optional[LPath], FlyteAnnotation({'display_name': 'Hisat2 Index', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to directory or tar.gz archive for pre-built HISAT2 index.'})]
rsem_index: typing_extensions.Annotated[typing.Optional[LPath], FlyteAnnotation({'display_name': 'Rsem Index', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to directory or tar.gz archive for pre-built RSEM index.'})]
salmon_index: typing_extensions.Annotated[typing.Optional[LPath], FlyteAnnotation({'display_name': 'Salmon Index', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to directory or tar.gz archive for pre-built Salmon index.'})]
kallisto_index: typing_extensions.Annotated[typing.Optional[LPath], FlyteAnnotation({'display_name': 'Kallisto Index', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to directory or tar.gz archive for pre-built Kallisto index.'})]
gencode: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Gencode', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Specify if your GTF annotation is in GENCODE format.', 'help_text': 'If your GTF file is in GENCODE format and you want to run Salmon (using `--pseudo_aligner salmon`), enable this parameter to build the Salmon index correctly.'})]
igenomes_ignore: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Igenomes Ignore', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Do not load the iGenomes reference config.', 'help_text': 'Prevent loading of `igenomes.config` when running the pipeline. Use this option if you encounter conflicts between custom parameters and those in the iGenomes configuration.'})]
extra_trimgalore_args: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Extra Trimgalore Args', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Extra arguments to pass to Trim Galore! command in addition to defaults defined by the pipeline.'})]
extra_fastp_args: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Extra Fastp Args', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Extra arguments to pass to fastp command in addition to defaults defined by the pipeline.'})]
bbsplit_fasta_list: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Bbsplit Fasta List', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to comma-separated file containing a list of reference genomes to filter reads against with BBSplit. You have to also explicitly set `--skip_bbsplit false` if you want to use BBSplit.', 'help_text': 'The file should contain 2 columns: short name and full path to reference genome(s), for example:\n```\nmm10,/path/to/mm10.fa\necoli,/path/to/ecoli.fa\n```'})]
bbsplit_index: typing_extensions.Annotated[typing.Optional[LPath], FlyteAnnotation({'display_name': 'Bbsplit Index', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to directory or tar.gz archive for pre-built BBSplit index.', 'help_text': 'The BBSplit index must be built at least once with this pipeline. Use `--save_reference` to save the index, which can then be provided via `--bbsplit_index` for future runs.'})]
sortmerna_index: typing_extensions.Annotated[typing.Optional[LPath], FlyteAnnotation({'display_name': 'Sortmerna Index', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Path to directory or tar.gz archive for pre-built sortmerna index.', 'help_text': 'The SortMeRNA index must be built at least once with this pipeline. Use `--save_reference` to save the index, which can then be provided via `--sortmerna_index` for future runs.'})]
remove_ribo_rna: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Remove Ribo Rna', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Enable the removal of reads derived from ribosomal RNA using SortMeRNA.', 'help_text': 'Any patterns found in sequences defined by the `--ribo_database_manifest` parameter will be used for filtering.'})]
with_umi: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'With Umi', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Enable UMI-based read deduplication.'})]
umitools_bc_pattern: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Umitools Bc Pattern', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': "The UMI barcode pattern to use e.g. 'NNNNNN' indicates that the first 6 nucleotides of the read are from the UMI.", 'help_text': 'Detailed information can be found in the [UMI-tools documentation](https://umi-tools.readthedocs.io/en/latest/reference/extract.html#extract-method).'})]
umitools_bc_pattern2: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Umitools Bc Pattern2', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'The UMI barcode pattern to use if the UMI is located in read 2.'})]
umi_discard_read: typing_extensions.Annotated[typing.Optional[int], FlyteAnnotation({'display_name': 'Umi Discard Read', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'After UMI barcode extraction discard either R1 or R2 by setting this parameter to 1 or 2, respectively.'})]
umitools_umi_separator: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Umitools Umi Separator', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'The character that separates the UMI in the read name. Most likely a colon if you skipped the extraction with UMI-tools and used other software.', 'errorMessage': "The UMI separator must not contain spaces and must be a single character (e.g., ':')."})]
umitools_dedup_stats: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Umitools Dedup Stats', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Generate output stats when running "umi_tools dedup".', 'help_text': 'Generating these output statistics can be time-consuming. See [issue #827](https://github.com/nf-core/rnaseq/issues/827) for more information.'})]
use_sentieon_star: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Use Sentieon Star', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Optionally accelerate STAR with Sentieon'})]
pseudo_aligner: typing_extensions.Annotated[typing.Optional[PseudoAlignerType], FlyteAnnotation({'display_name': 'Pseudo Aligner', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': "Specifies the pseudo aligner to use - available options are 'salmon'. Runs in addition to '--aligner'."})]
bam_csi_index: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Bam Csi Index', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Create a CSI index for BAM files instead of the traditional BAI index. This will be required for genomes with larger chromosome sizes.'})]
star_ignore_sjdbgtf: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Star Ignore Sjdbgtf', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'When using pre-built STAR indices do not re-extract and use splice junctions from the GTF file.'})]
salmon_quant_libtype: typing_extensions.Annotated[typing.Optional[SalmonQuantLibtypeType], FlyteAnnotation({'display_name': 'Salmon Quant Libtype', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': ' Override Salmon library type inferred based on strandedness defined in meta object.', 'help_text': 'Refer to the [Salmon documentation](https://salmon.readthedocs.io/en/latest/library_type.html) for details on library types.'})]
seq_center: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Seq Center', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Sequencing center information to be added to read group of BAM files.'})]
stringtie_ignore_gtf: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Stringtie Ignore Gtf', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Perform reference-guided de novo assembly of transcripts using StringTie i.e. don't restrict to those in GTF file.'})]
extra_star_align_args: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Extra Star Align Args', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Extra arguments to pass to STAR alignment command in addition to defaults defined by the pipeline. Only available for the STAR-Salmon route.'})]
extra_salmon_quant_args: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Extra Salmon Quant Args', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Extra arguments to pass to Salmon quant command in addition to defaults defined by the pipeline.'})]
extra_kallisto_quant_args: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Extra Kallisto Quant Args', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Extra arguments to pass to Kallisto quant command in addition to defaults defined by the pipeline.'})]
save_merged_fastq: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Save Merged Fastq', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Save FastQ files after merging re-sequenced libraries in the results directory.'})]
save_umi_intermeds: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Save Umi Intermeds', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'If this option is specified, intermediate FastQ and BAM files produced by UMI-tools are also saved in the results directory.'})]
save_non_ribo_reads: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Save Non Ribo Reads', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'If this option is specified, intermediate FastQ files containing non-rRNA reads will be saved in the results directory.'})]
save_bbsplit_reads: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Save Bbsplit Reads', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'If this option is specified, FastQ files split by reference will be saved in the results directory.'})]
save_reference: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Save Reference', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'If generated by the pipeline save the STAR index in the results directory.', 'help_text': 'If the pipeline generates an alignment index, use this parameter to save it to your results folder for future pipeline runs, reducing processing time.'})]
save_trimmed: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Save Trimmed', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Save the trimmed FastQ files in the results directory.', 'help_text': 'By default, trimmed FastQ files are not saved. Enable this option to copy these files to the results directory.'})]
save_align_intermeds: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Save Align Intermeds', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Save the intermediate BAM files from the alignment step.', 'help_text': 'By default, only final filtered BAM files are saved to conserve storage. Enable this option to also save intermediate BAM files from the alignment process.'})]
save_unaligned: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Save Unaligned', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Where possible, save unaligned reads from either STAR, HISAT2 or Salmon to the results directory.', 'help_text': 'Output may be in FastQ or BAM format depending on the options available for the specific alignment tool used.'})]
save_kraken_assignments: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Save Kraken Assignments', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Save read-by-read assignments from Kraken2.', 'help_text': 'The `--kraken_db` parameter must be provided to use this option.'})]
save_kraken_unassigned: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Save Kraken Unassigned', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Save reads that were not given assignment from Kraken2.', 'help_text': 'The `--kraken_db` parameter must be provided to use this option.'})]
contaminant_screening: typing_extensions.Annotated[typing.Optional[ContaminantScreeningType], FlyteAnnotation({'display_name': 'Contaminant Screening', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': "Tool to use for detecting contaminants in unaligned reads - available options are 'kraken2' and 'kraken2_bracken'"})]
kraken_db: typing_extensions.Annotated[typing.Optional[LatchDir], FlyteAnnotation({'display_name': 'Kraken Db', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Database when using Kraken2/Bracken for contaminant screening.', 'help_text': 'See the usage documentation for more information on setting up and using Kraken2 databases.'})]
skip_gtf_filter: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Gtf Filter', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip filtering of GTF for valid scaffolds and/or transcript IDs.', 'help_text': "If you're confident in your GTF file's compatibility with the genome FASTA file, or want to ignore filtering errors, enable this option."})]
skip_gtf_transcript_filter: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Gtf Transcript Filter', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': "Skip the 'transcript_id' checking component of the GTF filtering script used in the pipeline. Ensure the GTF file is valid."})]
skip_umi_extract: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Umi Extract', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip the UMI extraction from the read in case the UMIs have been moved to the headers in advance of the pipeline run.'})]
skip_linting: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Linting', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip linting checks during FASTQ preprocessing and filtering.'})]
skip_trimming: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Trimming', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip the adapter trimming step.', 'help_text': "Use this option if your FastQ files have already been trimmed or if you're certain they contain no adapter contamination."})]
skip_alignment: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Alignment', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip all alignment-based processes within the pipeline.'})]
skip_pseudo_alignment: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Pseudo Alignment', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip all pseudo-alignment-based processes within the pipeline.'})]
skip_markduplicates: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Markduplicates', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip picard MarkDuplicates step.'})]
skip_bigwig: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Bigwig', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip bigWig file creation.'})]
skip_stringtie: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Stringtie', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip StringTie.'})]
skip_fastqc: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Fastqc', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip FastQC.'})]
skip_dupradar: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Dupradar', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip dupRadar.'})]
skip_qualimap: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Qualimap', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip Qualimap.'})]
skip_rseqc: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Rseqc', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip RSeQC.'})]
skip_biotype_qc: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Biotype Qc', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip additional featureCounts process for biotype QC.'})]
skip_deseq2_qc: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Deseq2 Qc', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip DESeq2 PCA and heatmap plotting.'})]
skip_multiqc: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Multiqc', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip MultiQC.'})]
skip_qc: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Qc', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip all QC steps except for MultiQC.'})]
config_profile_name: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Config Profile Name', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Institutional config name.'})]
config_profile_description: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Config Profile Description', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Institutional config description.'})]
config_profile_contact: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Config Profile Contact', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Institutional config contact information.'})]
config_profile_url: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Config Profile Url', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Institutional config URL link.'})]
version: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Version', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Display version and exit.'})]
email_on_fail: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Email On Fail', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Email address for completion summary, only when pipeline fails.', 'help_text': 'Specify an email address to receive a summary report only when the pipeline fails to complete successfully.'})]
plaintext_email: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Plaintext Email', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Send plain-text email instead of HTML.'})]
monochrome_logs: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Monochrome Logs', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Do not use colored log outputs.'})]
hook_url: typing_extensions.Annotated[typing.Optional[LPath], FlyteAnnotation({'display_name': 'Hook Url', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Incoming Webhook URL for messaging service', 'help_text': 'URL for messaging service integration. Currently supports Microsoft Teams and Slack.'})]
multiqc_config: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Multiqc Config', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Custom config file to supply to MultiQC.'})]
multiqc_logo: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Multiqc Logo', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Custom logo file to supply to MultiQC. File name must also be set in the MultiQC config file.'})]
multiqc_methods_description: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Multiqc Methods Description', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Custom MultiQC yaml file containing HTML including a methods description.'})]
trace_report_suffix: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Trace Report Suffix', 'default': None, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Suffix to add to the trace report filename.', 'help_text': "You can use '{date}' as a placeholder which will be replaced with the current date and time in the format 'yyyy-MM-dd_HH-mm-ss'. For example, 'run_{date}' will become 'run_2023-05-15_14-30-45'.", 'errorMessage': 'The trace report suffix must only contain alphanumeric characters, underscores, hyphens, dots, and curly braces for date placeholders.'})]
hisat2_build_memory: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Hisat2 Build Memory', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': '200.GB'}}}, 'type': {'simple': 'STRING', 'structure': {'tag': 'str'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Minimum memory required to use splice sites and exons in the HISAT2 index build process.', 'help_text': 'HISAT2 requires significant RAM to build genome indices for large genomes with splice sites and exons (human genome typically needs 200GB). If you provide less memory than this threshold, splice sites and exons will be ignored, reducing memory requirements. For small genomes, set a lower value; for larger genomes, provide more memory.', 'errorMessage': "Memory format must be a valid string like '200.GB', '16.MB', '8KB'."})] = field(default='200.GB')
gtf_extra_attributes: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Gtf Extra Attributes', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'gene_name'}}}, 'type': {'simple': 'STRING', 'structure': {'tag': 'str'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'By default, the pipeline uses the `gene_name` field to obtain additional gene identifiers from the input GTF file when running Salmon.', 'help_text': 'Modify this parameter to change which attributes are extracted from the GTF file when running Salmon. You can specify multiple values separated by commas (e.g., `--gtf_extra_attributes gene_id,transcript_id`).'})] = field(default='gene_name')
gtf_group_features: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Gtf Group Features', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'gene_id'}}}, 'type': {'simple': 'STRING', 'structure': {'tag': 'str'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Define the attribute type used to group features in the GTF file when running Salmon.'})] = field(default='gene_id')
featurecounts_group_type: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Featurecounts Group Type', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'gene_biotype'}}}, 'type': {'simple': 'STRING', 'structure': {'tag': 'str'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'The attribute type used to group feature types in the GTF file when generating the biotype plot with featureCounts.'})] = field(default='gene_biotype')
featurecounts_feature_type: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Featurecounts Feature Type', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'exon'}}}, 'type': {'simple': 'STRING', 'structure': {'tag': 'str'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': "By default, the pipeline assigns reads based on the 'exon' attribute within the GTF file.", 'help_text': 'Specifies the feature type from the GTF file to use when generating the biotype plot with featureCounts.'})] = field(default='exon')
igenomes_base: typing_extensions.Annotated[typing.Optional[LatchDir], FlyteAnnotation({'display_name': 'Igenomes Base', 'default': {'scalar': {'union': {'value': {'scalar': {'blob': {'metadata': {'type': {'dimensionality': 'MULTIPART'}}, 'uri': 's3://ngi-igenomes/igenomes/'}}}, 'type': {'blob': {'dimensionality': 'MULTIPART'}, 'structure': {'tag': 'LatchDirPath'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'The base path to the igenomes reference files'})] = field(default_factory=lambda: LatchDir('s3://ngi-igenomes/igenomes/', remote_path='s3://ngi-igenomes/igenomes/'))
trimmer: typing_extensions.Annotated[typing.Optional[TrimmerType], FlyteAnnotation({'display_name': 'Trimmer', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'trimgalore'}}}, 'type': {'enumType': {'values': ['trimgalore', 'fastp']}, 'structure': {'tag': 'DefaultEnumTransformer'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': "Specifies the trimming tool to use - available options are 'trimgalore' and 'fastp'."})] = field(default=TrimmerType.trimgalore)
min_trimmed_reads: typing_extensions.Annotated[typing.Optional[int], FlyteAnnotation({'display_name': 'Min Trimmed Reads', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'integer': '10000'}}}, 'type': {'simple': 'INTEGER', 'structure': {'tag': 'int'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Minimum number of trimmed reads below which samples are removed from further processing. Some downstream steps in the pipeline will fail if this threshold is too low.'})] = field(default=10000)
ribo_database_manifest: typing_extensions.Annotated[typing.Optional[LatchFile], FlyteAnnotation({'display_name': 'Ribo Database Manifest', 'default': {'scalar': {'union': {'value': {'scalar': {'blob': {'metadata': {'type': {}}}}}, 'type': {'blob': {}, 'structure': {'tag': 'LatchFilePath'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Text file containing paths to fasta files (one per line) that will be used to create the database for SortMeRNA.', 'help_text': 'By default, [rRNA databases](https://github.com/biocore/sortmerna/tree/master/data/rRNA_databases) from the SortMeRNA GitHub repository are used. See the example in `assets/rrna-default-dbs.txt`. Note: commercial/non-academic entities require [SILVA licensing](https://www.arb-silva.de/silva-license-information) for these databases.'})] = field(default_factory=lambda: LatchFile('${projectDir}/workflows/rnaseq/assets/rrna-db-defaults.txt'))
umi_dedup_tool: typing_extensions.Annotated[typing.Optional[UmiDedupToolType], FlyteAnnotation({'display_name': 'Umi Dedup Tool', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'umitools'}}}, 'type': {'enumType': {'values': ['umitools', 'umicollapse']}, 'structure': {'tag': 'DefaultEnumTransformer'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': "Specifies the tool to use for UMI deduplication - available options are 'umitools' and 'umicollapse'."})] = field(default=UmiDedupToolType.umitools)
umitools_extract_method: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Umitools Extract Method', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'string'}}}, 'type': {'simple': 'STRING', 'structure': {'tag': 'str'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': "UMI pattern to use. Can be either 'string' (default) or 'regex'.", 'help_text': 'Detailed information can be found in the [UMI-tools documentation](https://umi-tools.readthedocs.io/en/latest/reference/extract.html#extract-method).'})] = field(default='string')
umitools_grouping_method: typing_extensions.Annotated[typing.Optional[UmitoolsGroupingMethodType], FlyteAnnotation({'display_name': 'Umitools Grouping Method', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'directional'}}}, 'type': {'enumType': {'values': ['unique', 'percentile', 'cluster', 'adjacency', 'directional']}, 'structure': {'tag': 'DefaultEnumTransformer'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Method to use to determine read groups by subsuming those with similar UMIs. All methods start by identifying the reads with the same mapping position, but treat similar yet nonidentical UMIs differently.'})] = field(default=UmitoolsGroupingMethodType.directional)
aligner: typing_extensions.Annotated[typing.Optional[AlignerType], FlyteAnnotation({'display_name': 'Aligner', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'star_salmon'}}}, 'type': {'enumType': {'values': ['star_salmon', 'star_rsem', 'hisat2']}, 'structure': {'tag': 'DefaultEnumTransformer'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': "Specifies the alignment algorithm to use - available options are 'star_salmon', 'star_rsem' and 'hisat2'."})] = field(default=AlignerType.star_salmon)
pseudo_aligner_kmer_size: typing_extensions.Annotated[typing.Optional[int], FlyteAnnotation({'display_name': 'Pseudo Aligner Kmer Size', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'integer': '31'}}}, 'type': {'simple': 'INTEGER', 'structure': {'tag': 'int'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Kmer length passed to indexing step of pseudo-aligners', 'help_text': 'Setting an appropriate kmer size is crucial for quantification with Kallisto or Salmon. This is particularly important for short reads (<50bp), where the default size of 31 can cause problems.'})] = field(default=31)
min_mapped_reads: typing_extensions.Annotated[typing.Optional[float], FlyteAnnotation({'display_name': 'Min Mapped Reads', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'floatValue': 5.0}}}, 'type': {'simple': 'FLOAT', 'structure': {'tag': 'float'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Minimum percentage of uniquely mapped reads below which samples are removed from further processing.', 'help_text': 'Downstream pipeline steps may fail if this threshold is set too low.'})] = field(default=5.0)
kallisto_quant_fraglen: typing_extensions.Annotated[typing.Optional[int], FlyteAnnotation({'display_name': 'Kallisto Quant Fraglen', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'integer': '200'}}}, 'type': {'simple': 'INTEGER', 'structure': {'tag': 'int'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'In single-end mode Kallisto requires an estimated fragment length. Specify a default value for that here. TODO: use existing RSeQC results to do this dynamically.'})] = field(default=200)
kallisto_quant_fraglen_sd: typing_extensions.Annotated[typing.Optional[int], FlyteAnnotation({'display_name': 'Kallisto Quant Fraglen Sd', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'integer': '200'}}}, 'type': {'simple': 'INTEGER', 'structure': {'tag': 'int'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'In single-end mode, Kallisto requires an estimated standard error for fragment length. Specify a default value for that here. TODO: use existing RSeQC results to do this dynamically.'})] = field(default=200)
stranded_threshold: typing_extensions.Annotated[typing.Optional[float], FlyteAnnotation({'display_name': 'Stranded Threshold', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'floatValue': 0.8}}}, 'type': {'simple': 'FLOAT', 'structure': {'tag': 'float'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'The fraction of stranded reads that must be assigned to a strandedness for confident assignment. Must be at least 0.5.'})] = field(default=0.8)
unstranded_threshold: typing_extensions.Annotated[typing.Optional[float], FlyteAnnotation({'display_name': 'Unstranded Threshold', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'floatValue': 0.1}}}, 'type': {'simple': 'FLOAT', 'structure': {'tag': 'float'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': "The difference in fraction of stranded reads assigned to 'forward' and 'reverse' below which a sample is classified as 'unstranded'. By default the forward and reverse fractions must differ by less than 0.1 for the sample to be called as unstranded."})] = field(default=0.1)
extra_fqlint_args: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Extra Fqlint Args', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': '--disable-validator P001'}}}, 'type': {'simple': 'STRING', 'structure': {'tag': 'str'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Extra arguments to pass to the fq lint command.'})] = field(default='--disable-validator P001')
deseq2_vst: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Deseq2 Vst', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'boolean': True}}}, 'type': {'simple': 'BOOLEAN', 'structure': {'tag': 'bool'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Use vst transformation instead of rlog with DESeq2.', 'help_text': 'See the [DESeq2 documentation](http://bioconductor.org/packages/devel/bioc/vignettes/DESeq2/inst/doc/DESeq2.html#data-transformations-and-visualization) for details on transformations.'})] = field(default=True)
rseqc_modules: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Rseqc Modules', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'bam_stat,inner_distance,infer_experiment,junction_annotation,junction_saturation,read_distribution,read_duplication'}}}, 'type': {'simple': 'STRING', 'structure': {'tag': 'str'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Comma-separated list of RSeQC modules to run.', 'help_text': 'Available modules include: bam_stat, inner_distance, infer_experiment, junction_annotation, junction_saturation, read_distribution, read_duplication.', 'errorMessage': 'The RSeQC modules must be a comma-separated list of valid module names.'})] = field(default='bam_stat,inner_distance,infer_experiment,junction_annotation,junction_saturation,read_distribution,read_duplication')
bracken_precision: typing_extensions.Annotated[typing.Optional[BrackenPrecisionType], FlyteAnnotation({'display_name': 'Bracken Precision', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'S'}}}, 'type': {'enumType': {'values': ['D', 'P', 'C', 'O', 'F', 'G', 'S']}, 'structure': {'tag': 'DefaultEnumTransformer'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Taxonomic level for Bracken abundance estimations.', 'help_text': 'Use the first letter of taxonomic levels: Domain, Phylum, Class, Order, Family, Genus, or Species.'})] = field(default=BrackenPrecisionType.S)
skip_bbsplit: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Bbsplit', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'boolean': True}}}, 'type': {'simple': 'BOOLEAN', 'structure': {'tag': 'bool'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip BBSplit for removal of non-reference genome reads.'})] = field(default=True)
skip_preseq: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Skip Preseq', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'boolean': True}}}, 'type': {'simple': 'BOOLEAN', 'structure': {'tag': 'bool'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Skip Preseq.'})] = field(default=True)
custom_config_version: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Custom Config Version', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'master'}}}, 'type': {'simple': 'STRING', 'structure': {'tag': 'str'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Git commit id for Institutional configs.'})] = field(default='master')
custom_config_base: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Custom Config Base', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'https://raw.githubusercontent.com/nf-core/configs/master'}}}, 'type': {'simple': 'STRING', 'structure': {'tag': 'str'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Base directory for Institutional configs.', 'help_text': 'When running offline, Nextflow cannot retrieve institutional configuration files from the internet. If needed, download these files from the repository and specify their location with this parameter.'})] = field(default='https://raw.githubusercontent.com/nf-core/configs/master')
publish_dir_mode: typing_extensions.Annotated[typing.Optional[PublishDirModeType], FlyteAnnotation({'display_name': 'Publish Dir Mode', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': 'copy'}}}, 'type': {'enumType': {'values': ['symlink', 'rellink', 'link', 'copy', 'copyNoFollow', 'move']}, 'structure': {'tag': 'DefaultEnumTransformer'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Method used to save pipeline results to output directory.', 'help_text': "Controls how files are saved to the output directory through Nextflow's `publishDir` directive. See the [Nextflow documentation](https://www.nextflow.io/docs/latest/process.html#publishdir) for available options."})] = field(default=PublishDirModeType.copy)
max_multiqc_email_size: typing_extensions.Annotated[typing.Optional[str], FlyteAnnotation({'display_name': 'Max Multiqc Email Size', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'stringValue': '25.MB'}}}, 'type': {'simple': 'STRING', 'structure': {'tag': 'str'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'File size limit when attaching MultiQC reports to summary emails.'})] = field(default='25.MB')
validate_params: typing_extensions.Annotated[typing.Optional[bool], FlyteAnnotation({'display_name': 'Validate Params', 'default': {'scalar': {'union': {'value': {'scalar': {'primitive': {'boolean': True}}}, 'type': {'simple': 'BOOLEAN', 'structure': {'tag': 'bool'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Boolean indicating whether to validate parameters against the schema at runtime'})] = field(default=True)
pipelines_testdata_base_path: typing_extensions.Annotated[typing.Optional[LatchDir], FlyteAnnotation({'display_name': 'Pipelines Testdata Base Path', 'default': {'scalar': {'union': {'value': {'scalar': {'blob': {'metadata': {'type': {'dimensionality': 'MULTIPART'}}}}}, 'type': {'blob': {'dimensionality': 'MULTIPART'}, 'structure': {'tag': 'LatchDirPath'}}}}}, 'samplesheet': False, 'output': False, 'required': False, 'description': 'Base URL or local path to location of pipeline test dataset files'})] = field(default_factory=lambda: LatchDir('https://raw.githubusercontent.com/nf-core/test-datasets/7f1614baeb0ddf66e60be78c3d9fa55440465ac8/'))
generated_flow = [Section('Input/output options', Text('Define where the pipeline should find input data and save output data.'), Params('input', 'outdir'), Spoiler('Optional Parameters', Params('email', 'multiqc_title'))), Spoiler('Reference genome options', Text('Reference genome related files and options required for the workflow.'), Params('genome', 'fasta', 'gtf', 'gff', 'gene_bed', 'transcript_fasta', 'additional_fasta', 'splicesites', 'star_index', 'hisat2_index', 'rsem_index', 'salmon_index', 'kallisto_index', 'hisat2_build_memory', 'gencode', 'gtf_extra_attributes', 'gtf_group_features', 'featurecounts_group_type', 'featurecounts_feature_type', 'igenomes_ignore', 'igenomes_base')), Spoiler('Read trimming options', Text('Options to adjust read trimming criteria.'), Params('trimmer', 'extra_trimgalore_args', 'extra_fastp_args', 'min_trimmed_reads')), Spoiler('Read filtering options', Text('Options for filtering reads prior to alignment'), Params('bbsplit_fasta_list', 'bbsplit_index', 'sortmerna_index', 'remove_ribo_rna', 'ribo_database_manifest')), Spoiler('UMI options', Text('Options for processing reads with unique molecular identifiers'), Params('with_umi', 'umi_dedup_tool', 'umitools_extract_method', 'umitools_bc_pattern', 'umitools_bc_pattern2', 'umi_discard_read', 'umitools_umi_separator', 'umitools_grouping_method', 'umitools_dedup_stats')), Spoiler('Alignment options', Text('Options to adjust parameters and filtering criteria for read alignments.'), Params('aligner', 'use_sentieon_star', 'pseudo_aligner', 'pseudo_aligner_kmer_size', 'bam_csi_index', 'star_ignore_sjdbgtf', 'salmon_quant_libtype', 'min_mapped_reads', 'seq_center', 'stringtie_ignore_gtf', 'extra_star_align_args', 'extra_salmon_quant_args', 'extra_kallisto_quant_args', 'kallisto_quant_fraglen', 'kallisto_quant_fraglen_sd', 'stranded_threshold', 'unstranded_threshold')), Spoiler('Optional outputs', Text('Additional output files produced as intermediates that can be saved'), Params('save_merged_fastq', 'save_umi_intermeds', 'save_non_ribo_reads', 'save_bbsplit_reads', 'save_reference', 'save_trimmed', 'save_align_intermeds', 'save_unaligned', 'save_kraken_assignments', 'save_kraken_unassigned')), Spoiler('Quality Control', Text('Additional quality control options.'), Params('extra_fqlint_args', 'deseq2_vst', 'rseqc_modules', 'contaminant_screening', 'kraken_db', 'bracken_precision')), Spoiler('Process skipping options', Text('Options to skip various steps within the workflow.'), Params('skip_gtf_filter', 'skip_gtf_transcript_filter', 'skip_bbsplit', 'skip_umi_extract', 'skip_linting', 'skip_trimming', 'skip_alignment', 'skip_pseudo_alignment', 'skip_markduplicates', 'skip_bigwig', 'skip_stringtie', 'skip_fastqc', 'skip_preseq', 'skip_dupradar', 'skip_qualimap', 'skip_rseqc', 'skip_biotype_qc', 'skip_deseq2_qc', 'skip_multiqc', 'skip_qc')), Spoiler('Institutional config options', Text('Parameters used to describe centralized config profiles. These should not be edited.'), Params('custom_config_version', 'custom_config_base', 'config_profile_name', 'config_profile_description', 'config_profile_contact', 'config_profile_url')), Spoiler('Generic options', Text('Less common options for the pipeline, typically set in a config file.'), Params('version', 'publish_dir_mode', 'email_on_fail', 'plaintext_email', 'max_multiqc_email_size', 'monochrome_logs', 'hook_url', 'multiqc_config', 'multiqc_logo', 'multiqc_methods_description', 'validate_params', 'pipelines_testdata_base_path', 'trace_report_suffix'))]
````
Complex workflows with dozens of parameters can overwhelm scientists when displayed as a simple list. To address this, the file also includes an additional `generated_flow` parameter that organizes parameters using `Section` (visible groupings) and `Spoiler` (collapsible sections) to reduce visual clutter and help users focus on essential parameters while keeping advanced options accessible.
### `latch_metadata/__init__.py`
```python latch_metadata/__init__.py expandable theme={null}
from dataclasses import dataclass
from latch.types.metadata import (
LatchAuthor,
NextflowMetadata,
NextflowParameter,
NextflowRuntimeResources
)
from latch.types.directory import LatchDir
from .generated import NextflowSchemaArgsType, generated_flow
@dataclass
class WorkflowArgsType(NextflowSchemaArgsType):
# add any custom parameters here
...
NextflowMetadata(
display_name='nf-core/rnaseq',
author=LatchAuthor(
name="Your Name",
),
parameters={
"args": NextflowParameter(type=WorkflowArgsType)
},
runtime_resources=NextflowRuntimeResources(
cpus=4,
memory=8,
storage_gib=100,
),
log_dir=LatchDir("latch:///your_log_dir"),
flow=generated_flow,
)
```
This file holds the [`NextflowMetadata`](/sdk/ui/latch-metadata#nextflowmetadata) object, which contains relevant fields for the workflow:
* **`display_name`**: The display name of the workflow, as it will appear on the Latch UI.
* **`author`**: Name of the person or organization that publishes the workflow
* **`parameters`**: Input parameters to the workflow, defined as `NextflowParameter` objects. This will contain a single entry for the `WorkflowArgsType` dataclass, and should not be modified.
* **`runtime_resources`**: The resources the Nextflow Runtime requires to execute the workflow. The `storage_gib` field will configure the storage size in GiB for the shared filesystem.
* **`log_dir`**: Latch directory to dump `.nextflow.log` file on workflow failure.
### Overwriting behavior
When re-running the `generate-metadata` command, the `__init__.py` file will not be touched and the `generated.py` file will be overwritten. Any changes should be made to `__init__.py` so that they can persist across `generate-metadata` calls.
## Step 3: Register the workflow
To register a Nextflow pipeline on Latch, type:
```bash theme={null}
latch login
latch register . --nf-script main.nf --nf-execution-profile docker,test
```
Let's break down the above command:
* `latch register .`: Searches for a Latch workflow in the current directory and registers it to Latch.
* `--nf-script main.nf`: Specifies the Nextflow script passed to the Nextflow command at runtime. For this workflow: `nextflow run main.nf`
* `--nf-execution-profile docker,test`: Defines the execution profile to use when running the workflow on Latch. We specify the `docker` configuration profile to execute processes in a containerized environment.
After running the above command, the Latch SDK will generate two files:
1. `latch.config` - a Nextflow configuration file passed to Nextflow via the `-config` flag.
2. `wf/entrypoint.py` - the generated Latch SDK workflow code that executes the Nextflow pipeline.
Once the workflow is registered, click on the link provided in the output of the `latch register` command. This will take you to an interface like the one below:
As a part of the registration process, we build a docker image which is specified in a `Dockerfile`. Normally this `Dockerfile` is autogenerated and stored in `.latch`, but if there is already a `Dockerfile` in the workflow directory prior to registering, it will be used to build this image. This can result in errors down the line if the Dockerfile is not generated by Latch.
## Step 4: Execute the workflow
Before executing the workflow, we need to upload test data to Latch. You can find sample test data [here](https://console.latch.bio/s/6307004346171604).
Copy the test data to your Latch workspace by clicking the `Copy to Workspace` button in the top right corner.
Now, let's create the samplesheet in Latch Registry.
1. Navigate to the [Latch Registry](https://console.latch.bio/registry) and create a new Table.
2. Select the table you just created and click "Import CSV". This will open up the Latch Data filesystem. Import the `samplesheet.csv` file you copied from the provided test data.
Your data is now uploaded to Latch and ready to be processed!
Navigate to the [Workflows tab](https://console.latch.bio/workflows) in the Latch Console and select the workflow you previously registered.
Then, select the appropriate input parameters from the test data you uploaded and click `Launch Workflow` in the bottom right corner to execute the workflow.
## Step 5: Monitoring the workflow
After launching the workflow, you can monitor progress by clicking on the appropriate execution under the `Executions` tab of your workflow.
Under the `Graph & Logs` tab, you can view the generated two-stage DAG with the initialization step and the Nextflow runtime task.
If you click on the Nextflow runtime node, you can view the runtime logs generated by Nextflow.
Once the Nextflow runtime starts executing the workflow, a `Process Nodes` tab will appear in the menu bar where you can monitor the status of each process in the workflow.
Each node in the DAG represents a process in the Nextflow pipeline.
To more easily navigate the graph, you can filter the process nodes by
execution status by clicking the "Filter by Status" button in the top right
corner.
Click on a process node to see details of every invocation of that process, including the resources provisioned, execution time, and logs.
Once the workflow is complete, you can view any published outputs in Latch Data. It is convention for Nextflow workflows to use the `outdir` parameter
to prepend publishDir paths. For example, if we set our `outdir` parameter to `latch:///nf-rnaseq/outputs`, all pipeline outputs will be published to the
`nf-rnaseq/outputs` directory in Latch Data.
## Step 6 (Optional): Adding Python Tasks for Pre- and Post-Processing
The `latch register` command generates a Latch workflow that runs your Nextflow pipeline. You can add custom Python tasks that interact with Latch (e.g. modify the workflow execution name on [Latch Executions page](/workflows/sdk/console/execution-monitoring#executions)) without modifying your original Nextflow code. This allows you to extend functionality while keeping your pipeline unchanged.
In this tutorial, we will modify the generated `wf/entrypoint.py` and the `latch_metadata/__init__.py` files to add a `Run Name` parameter that will be used to namespace the outputs of the Nextflow pipeline.
To do this, add the `run_name` field to the `WorkflowArgsType` dataclass in `latch_metadata/__init__.py` as below:
```python latch_metadata/__init__.py# theme={null}
@dataclass
class WorkflowArgsType(NextflowSchemaArgsType):
run_name: str
```
Now, we can update the logic of the `nextflow_runtime` task to use this new parameter:
```python theme={null}
@nextflow_runtime_task(cpu=4, memory=8, storage_gib=100)
def nextflow_runtime(
pvc_name: str,
args: WorkflowArgsType
) -> None:
args.outdir = LatchDir(f"{args.outdir.remote_path}/{args.run_name}") # Updated
...
```
We will now re-register the workflow with the above updates. We purposely exclude the `--nf-script` flag in the `latch register` command to avoid re-generating the Latch SDK workflow code (which will overwrite our updates).
```bash theme={null}
latch register .
```
***
## What You've Learned
**Core Concepts:**
* **Nextflow on Latch** allows running containerized pipelines with a graphical web interface.
* **Metadata generation** (`latch generate-metadata`) converts `nextflow_schema.json` into Python definitions for parameters and UI configuration.
* **Latch Registry integration** can replace error-prone CSV inputs with a structured and type-safe Registry UI.
**Development Workflow:**
1. **Clone** your Nextflow pipeline (e.g., nf-core/rnaseq).
2. **Generate metadata** from `nextflow_schema.json`.
3. **Register** the pipeline with `latch register --nf-script main.nf` and required execution profiles.
4. **Upload** test data to Latch and select inputs from the Console.
5. **Monitor** execution with the Graph & Logs and Process Nodes views.
6. **Customize** the generated `entrypoint.py` for additional pre- or post-processing logic.
7. **Re-register** without `--nf-script` to preserve your code modifications.
## Next Steps
* Explore [custom workflow interfaces](/workflows/sdk/ui/latch-metadata)
* Learn about [testing and debugging workflows](/workflows/sdk/testing-and-debugging-a-workflow/development-and-debugging)
* Learn how [caching and retries](/workflows/sdk/nextflow/caching) work to speed up iteration
# Tutorial
Source: https://wiki.latch.bio/workflows/sdk/python/authorizing-your-own-workflow
In this demonstration, we will examine a workflow which sorts and assembles COVID sequencing data.
This document aims to be an extension to the [Quickstart](/workflows/sdk/python/quick-start) to help you better understand the structure of a workflow and write your own.
**Prerequisite:**
* Complete the [Quickstart](/workflows/sdk/python/quick-start) guide.
**What you will learn:**
## 1. Initialize Workflow Directory
Bootstrap a new workflow directory by running `latch init` from the command line. In this tutorial, we will be using the `covid-wf` template.
```shell-session theme={null}
$ latch init covid-wf --template subprocess
Created a latch workflow in `covid-wf`
Run
$ latch register covid-wf
To register the workflow with console.latch.bio.
```
File Tree:
```shell-session theme={null}
covid-wf
├── LICENSE
├── README.md
├── bowtie2
│ ├── bowtie2
│ └── ...
├── reference
│ ├── wuhan.1.bt2
│ └── ...
├── system-requirements.txt
├── version
└── wf
├── __init__.py
├── assemble.py
└── sort.py
```
Once your boilerplate workflow has been created successfully, you should see a folder called `covid-wf`.
## 2. Build your Workflow
### Define Individual Tasks
A **task** is a Python function that:
* Takes typed inputs (e.g., LatchFile, LatchDir)
* Runs code inside the workflow container
* Returns outputs to the Latch platform or to another task
Example from `covid-wf/wf/assemble.py`: This task ingests two sequencing reads and outputs an assembled SAM file.
```python theme={null}
from latch.types import LatchFile, LatchOutputDir
from pathlib import Path
import subprocess
@small_task
def assembly_task(
read1: LatchFile, # LatchFile refers to remote files stored on Latch Data
read2: LatchFile,
output_directory: LatchOutputDir # Refers to the output directory for results on Latch Data
) -> LatchFile:
# Build the bowtie2 command with local file paths
bowtie2_cmd = [
"bowtie2/bowtie2",
"--local",
"--very-sensitive-local",
"-x", "wuhan",
"-1", read1.local_path, # .local_path automatically downloads the file and returns the local path
"-2", read2.local_path,
"-S", "covid_assembly.sam"
]
# Execute the bowtie2 command
subprocess.run(bowtie2_cmd, check=True)
local_file = Path("covid_assembly.sam")
# LatchFile(local_path, remote_path) uploads the local file to Latch
return LatchFile(local_file, "latch:///covid_assembly.sam")
```
When building a workflow with multiple tasks, it can be difficult to decide when to split larger tasks into smaller tasks. Some of the tradeoffs are listed below to guide this decision:
**Benefits of splitting a task into mulitple smaller tasks:**
* It is easier to manage the dependencies and environments of tasks with less code
* Tasks can be reused between different workflows.
* Each task can be assigned different computing resources.
* Task functions define clear boundaries between steps in a workflow, allowing for quicker isolation of problems, especially if the tasks are smaller.
* It is easier to retry workflows from the last failed task if tasks are small. The last succeeded task will be “further along” in the workflow.
* Splitting up tasks creates new nodes in the graph representation of the workflow. If each node has one function, may be easier to interpret for biologists.
**Downsides of splitting a task into multiple smaller tasks:**
* File I/O overhead - files passed between tasks are uploaded to S3 by the first task and then downloaded by the second task. with the appropriate resources to be present before it can run and this can take time.
* Scheduling overhead - each task in a workflow waits for an available machine with the appropriate resources to be ready before it begins executing. While this process usually takes under a minute, it can be a significant fraction of the total runtime for fast-running workflows.
### Chain Tasks Together into a Workflow
Once **tasks** are defined, chain them in a **workflow** function. You can do this by:
* Calling each task in sequence
* Passing task outputs as inputs to downstream tasks
Example: The workflow calls `assembly_task` first, then passes its output to `sort_bam_task`.
```python theme={null}
@workflow
def assemble_and_sort(read1: LatchFile, read2: LatchFile) -> LatchFile:
sam = assembly_task(read1=read1, read2=read2)
return sort_bam_task(sam=sam)
```
## 3. Customize compute and storage requirements for each task
A task decorator can be used to specify compute and storage requirements.
```python theme={null}
from latch import small_task
@small_task # 2 cpus, 4 gigs of memory, 0 gpus
def my_task(
...
):
...
@large_gpu_task #31 cpus, 120 gigs of memory, 1 gpu
def inference(
...
):
...
```
See an exhaustive reference to larger CPU and GPU tasks [here](/workflows/sdk/python/defining-cloud-resources).
## 4. Define dependencies
Latch uses Dockerfiles for dependency management. You can automatically generate Dockerfiles from existing environment files or create them manually.
### Automatic Generation
Use the `latch dockerfile` command to generate a Dockerfile from your existing environment files:
```bash theme={null}
latch dockerfile [OPTIONS] OUTPUT_DIRECTORY
```
```bash theme={null}
# From requirements.txt
latch dockerfile -p requirements.txt .
# From pyproject.toml
latch dockerfile -i pyproject.toml .
```
```bash theme={null}
# From apt-requirements.txt
latch dockerfile -a apt-requirements.txt .
```
```bash theme={null}
# From environment.R
latch dockerfile -r environment.R .
```
```bash theme={null}
# From environment.yml
latch dockerfile -c environment.yml .
```
```bash theme={null}
# From .env file
latch dockerfile -d .env .
```
### Manual Creation
You can create Dockerfiles manually following standard Docker best practices. However, certain Latch-specific elements are required for your workflow to function properly. These elements include:
* The Latch base image
* Command to install the Latch SDK
* Latch internal tagging system and expected root directory
Below is a template you can use to get started. Pay attention to how the core commands to install dependencies should live in the middle of the Dockerfile.
```Dockerfile expandable theme={null}
# latch base image + dependencies for latch SDK --- removing these will break the workflow
from 812206152185.dkr.ecr.us-west-2.amazonaws.com/latch-base:ace9-main
run pip install latch==2.12.1 # or any other version of the Latch SDK
run mkdir /opt/latch
# install your requirements here
# copy all code from package (use .dockerignore to skip files)
copy . /root/
# set environment variables
# latch internal tagging system + expected root directory --- changing these lines will break the workflow
arg tag
env FLYTE_INTERNAL_IMAGE $tag
workdir /root
```
## 5. Customize user interface
There are two pages that you can customize: the **About** page for your workflow and a **Parameters** page for workflow input parameters.
To modify the About page, simply write your description in Markdown in the docstring of the workflow function.
Latch provides a suite of front-end components out-of-the-box that can be defined by using Python objects `LatchMetadata` and `LatchParameter`:
```python theme={null}
from latch.types import LatchAuthor, LatchDir, LatchFile, LatchMetadata, LatchParameter
...
"""The metadata included here will be injected into your interface."""
metadata = LatchMetadata(
display_name="Assemble and Sort FastQ Files",
documentation="your-docs.dev",
author=LatchAuthor(
name="John von Neumann",
email="hungarianpapi4@gmail.com",
github="github.com/fluid-dynamix",
),
repository="https://github.com/your-repo",
license="MIT",
parameters={
"read1": LatchParameter(
display_name="Read 1",
description="Paired-end read 1 file to be assembled.",
batch_table_column=True, # Show this parameter in batched mode.
),
"read2": LatchParameter(
display_name="Read 2",
description="Paired-end read 2 file to be assembled.",
batch_table_column=True, # Show this parameter in batched mode.
),
},
)
...
```
The `metadata` variable then needs to be passed into the `@workflow` decorator to apply the interface to the workflow.
```python theme={null}
@workflow(metadata)
def assemble_and_sort(read1: LatchFile, read2: LatchFile) -> LatchFile:
...
```
See API documentation on all options to customize the workflow interface [here](/workflows/sdk/ui/latch-metadata.mdx).
## 6. Add test data for your workflow
Use Latch `LaunchPlan` to add test data to your workflow.
```python theme={null}
from latch.resources.launch_plan import LaunchPlan
# Add launch plans at the end of your wf/__init__.py
LaunchPlan(
assemble_and_sort,
"Protocol Template 1",
{
"read1": LatchFile("s3://latch-public/init/r1.fastq"),
"read2": LatchFile("s3://latch-public/init/r2.fastq"),
},
)
LaunchPlan(
assemble_and_sort,
"Protocol Template 2",
{
"read1": LatchFile("s3://latch-public/init/r1.fastq"),
"read2": LatchFile("s3://latch-public/init/r2.fastq"),
},
)
```
These default values will be available under the 'Test Data' dropdown at Latch Console.
## 7. Register your workflow to Latch
You can release a live version of your workflow by registering it on Latch:
```bash theme={null}
latch register --remote
```
The registration process will:
* Build a Docker image containing your workflow code
* Serialize your code and register it with your LatchBio account
* Push your docker image to a managed container registry
When registration has completed, you should be able to navigate [here](https://console.latch.bio/workflows) and see your new workflow in your account.
## 8. Test your workflow
To test your first workflow on Console, select the **Test Data** and click Launch. Statuses of workflows can be monitored under the **Executions** tab.
## 9. Iterative Development: Local Testing before Registration
You can test workflows locally during development to catch errors before registering. Use `latch develop` to build your workflow's Docker image and start an interactive shell in the same container environment it will run in on Latch. Inside the shell, you can write mock test code and run tasks to verify workflow behavior in a production-like environment.aviour in an environment as close to the production one as possible.
See the [Development and Debugging](/workflows/sdk/testing-and-debugging-a-workflow/development-and-debugging) to learn more.
***
## What You've Learned
**Core Concepts:**
* **Tasks** are Python functions that process inputs and return outputs
* **Workflows** chain multiple tasks together to create complex pipelines
* **LatchFile/LatchDir** types handle remote file operations automatically
**Development Workflow:**
1. **Initialize** with `latch init` to create boilerplate code
2. **Build** individual tasks, then chain them into workflows
3. **Configure** compute resources using task decorators
4. **Manage** dependencies with automatic or manual Dockerfile creation
5. **Customize** the user interface with metadata and parameters
6. **Test** locally with `latch develop` before registration
7. **Register** with `latch register --remote` to deploy
## Next Steps
* Customize your [workflow interface](/workflows/sdk/ui/latch-metadata)
* Learn about [testing and debugging](/workflows/sdk/testing-and-debugging-a-workflow/development-and-debugging).
* Explore advanced workflow features such as [caching, retries](/workflows/sdk/python/caching), and [parallelization](/workflows/sdk/python/map-task)
# Caching and Resuming
Source: https://wiki.latch.bio/workflows/sdk/python/caching
Running large workflows can be time-consuming and expensive, especially when tasks have already produced valid outputs in previous runs. Latch provides two ways to avoid recomputing work:
1. **Retry from failed task** – ideal for resuming failed runs without changing inputs.
2. **Task-level caching** – useful for skipping specific tasks across multiple runs, even when inputs change.
These features help save compute resources, shorten iteration cycles, and speed up debugging.
## 1. Default: "Retry from Failed Task"
By default, when a workflow fails, the Latch Console provides a Retry from failed task option. This resumes the workflow from the point of failure. Upstream tasks are skipped and their previous outputs are reused.
This is ideal when:
* Your inputs have not changed
* You fixed a bug in your code and want to re-run without repeating completed steps
## 2. Custom Caching for Select Tasks
If you want to launch multiple executions with different **workflow-level** inputs, but avoid re-running certain expensive tasks whose **own** inputs have not changed (e.g., rebuilding reference genomes), you can enable task-level caching.
This lets you persist outputs for those tasks across workflow runs, regardless of changes to unrelated workflow inputs upstream.
```python theme={null}
import time
from latch import small_task
@small_task(cache=True)
def do_sleep(foo: str) -> str:
time.sleep(60)
return foo
```
### Versioning Your Cache
Use `cache_version` to manually control when caches are invalidated:
```python theme={null}
@small_task(cache=True, cache_version="0.0.0")
def do_sleep_with_version(foo: str) -> str:
time.sleep(60)
return foo
```
* Change the version string to invalidate the cache, even if the code has not changed.
* Keep the same version to preserve cache even if the task body changes.
### Caching Rules
A task's cache is independent of the workflow it's in, meaning:
* Caches persist across workflow re-registrations if the task is unchanged.
* Caches are preserved if the task is reused in a different workflow.
Cache is invalidated when:
* Task code changes (non-comment)
* Function name or parameter types change
* `cache_version` changes
Cache is preserved when:
* Task code and signature remain identical (comments don't count)
* Task is reused in a new workflow without changes
# Conditional Sections
Source: https://wiki.latch.bio/workflows/sdk/python/conditional-sections
In order to support the functionality of an `if-elif-else` clause within the body of a workflow, we introduce the method `create_conditional_section`. This method creates a new conditional section in a workflow, allowing a user to conditionally execute a task based on the value of a task result.
Conditional sections are akin to ternary operators -- they return the output of the branch result. However, they can be n-ary with as many *elif* clauses as desired.
It is possible to consume the outputs from conditional nodes. And to pass in outputs from other tasks to conditional nodes.
The boolean expressions in the condition use `&` and `|` as and / or operators. Additionally, binary expressions are not allowed. Thus if a task returns a boolean and we wish to use it in a condition of a conditional block, we must use built in truth checks: `result.is_true()` or `result.is_false()`
```python theme={null}
from latch import small_task
from latch import create_conditional_section
@small_task
def square(n: float) -> float:
"""
Parameters:
n (float): name of the parameter for the task is derived from the name of the input variable, and
the type is automatically mapped to Types.Integer
Return:
float: The label for the output is automatically assigned and the type is deduced from the annotation
"""
return n * n
@small_task
def double(n: float) -> float:
"""
Parameters:
n (float): name of the parameter for the task is derived from the name of the input variable
and the type is mapped to ``Types.Integer``
Return:
float: The label for the output is auto-assigned and the type is deduced from the annotation
"""
return 2 * n
@workflow
def multiplier(my_input: float) -> float:
result_1 = double(n=my_input)
result_2 = (
create_conditional_section("fractions")
.if_((result_1 < 0.0)).then(double(n=result_1))
.elif_((result_1 > 0.0)).then(square(n=result_1))
.else_().fail("Only nonzero values allowed")
)
result_3 = double(n=result_2)
return result_3
```
# Defining Cloud Resources
Source: https://wiki.latch.bio/workflows/sdk/python/defining-cloud-resources
When a workflow is executed and tasks are scheduled, the machines needed to run the task are provisioned automatically and managed for the user until task completion. Tasks can be annotated with the resources they are expected to consume (eg. CPU, RAM, GPU) at runtime and these requests will be fullfilled during the scheduling process.
## Prespecified Task Resource
The Latch SDK currently supports a set of prespecified task resource requests
represented as decorators:
* `small_task`: 2 cpus, 4 gigs of memory, 0 gpus
* `medium_task`: 32 cpus, 128 gigs of memory, 0 gpus
* `large_task`: 96 cpus, 192 gig sof memory, 0 gpus
* `small_gpu_task`: 8 cpus, 32 gigs of memory, 1 gpu (24 gigs of VRAM, 9,216 cuda cores)
* `large_gpu_task`: 31 cpus, 120 gigs of memory, 1 gpu (24 gigs of VRAM, 9,216 cuda cores)
* `v100_x1_task`: 16 cpus, 64 gigs of memory, 1 V100 gpu (16 gigs of VRAM, 5,120 cuda cores)
* `v100_x4_task`: 64 cpus, 256 gigs of memory, 4 V100 gpus (64 gigs of VRAM, 20,480 cuda cores)
* `v100_x8_task`: 128 cpus, 512 gigs of memory, 8 V100 gpus (128 gigs of VRAM, 40,960 cuda cores)
* `g6e_xlarge_task`: 4 cpus, 32 gigs of memory, 1 L40s gpu
* `g6e_2xlarge_task`: 8 cpus, 64 gigs of memory, 1 L40s gpu
* `g6e_4xlarge_task`: 16 cpus, 128 gigs of memory, 1 L40s gpu
* `g6e_8xlarge_task`: 32 cpus, 256 gigs of memory, 1 L40s gpu
* `g6e_12xlarge_task`: 48 cpus, 384 gigs of memory, 1 L40s gpu
* `g6e_16xlarge_task`: 64 cpus, 512 gigs of memory, 1 L40s gpu
* `g6e_24xlarge_task`: 96 cpus, 768 gigs of memory, 4 L40s gpus
We use the tasks as follows:
```python theme={null}
from latch.resources.tasks import small_task, large_gpu_task, v100_x1_task, g6e_xlarge_task
@small_task
def my_task(
...
):
...
@large_gpu_task
def inference(
...
):
...
```
## Custom Task Resource
You can also arbitrarily specify task resources using `@custom_task`:
```python theme={null}
from latch import custom_task
@custom_task(cpu, memory) # cpu: int, memory: int
def my_task(
...
):
...
```
THe maximum available resources are 126 cpus, 975 GiB memory, and 4949 GiB ephemeral storage.
## Dynamic Task Resource
You can dynamically define task resources based on the tasks' input
parameters by passing functions as arguments for the `custom_task` decorator.
The provided functions will execute at runtime, and the task will launch
with the resulting resource values:
```python theme={null}
...
from latch import custom_task
from latch.types.file import LatchFile
def allocate_cpu(files: List[LatchFile], **kwargs) -> int: # number of cores to allocate
return min(8, len(files))
def allocate_storage(files: List[LatchFile], **kwargs) -> int: # GiBs of storage to allocate
return sum([1.5 * file.size() for file in files]) // 1024**3
@custom_task(cpu=allocate_cpu, memory=8, storage_gib=allocate_storage)
def my_task(files: List[LatchFile], count: int):
...
```
In the provided example, the `allocate_cpu` function is designed to process the
input parameters `files`. Upon execution, the function returns an integer representing
the total number of CPU cores that should be allocated to the task based on the input
file size.
The parameters passed to the resource functions at runtime are the same as
those passed to the task function. Therefore, the resource functions must only
accept parameters that exist in the task function signature. See how the
`my_task` function and the `allocate_cpu` function both accept a parameter
named `files` of type `List[LatchFile]`.
# Latch URLs
Source: https://wiki.latch.bio/workflows/sdk/python/latch-urls
Files and directories on Latch can be referred to in code or through the CLI using **Latch URLs**.
## Grammar
The basic structure of a Latch URL is `latch://`, followed by a (possibly empty) **Domain**, finally ending with an absolute `/`-separated path. This is summarized below.
```plaintext theme={null}
latch://
```
In some CLI commands (notably [`latch cp`](../cli/cp.md) and [`latch mv`](../cli/mv.md)), the `latch` prefix can be omitted, resulting in a URL of the form `://`.
### Domains
A domain can be in one of several different forms. Each of these domains affect the way that the path following it is resolved.
* `.account`: Resolve the path as if it were a path in the specified account.
* `.mount`: Resolve the path as if it were a path in the mounted S3 bucket specified. (Note: the bucket must be mounted to Latch first)
* `.node`: Resolve the path as if it were a relative path under the specified node.
* `shared..account`: Resolve the path as if it were shared in the specified account.
In addition to these, the empty domain (paths that look like `latch:///...`) and the domain `shared` are both valid. When used, their behavior depends on the workspace that the user is currently in.
Specifically, `latch:///...` is treated the same as `latch://.account/...`, and `latch://shared/...` is treated the same as `latch://shared..account/...`.
### Paths
The path following the domain, if provided, must be an absolute `/`-separated path. In `.node` domains, the path is resolved relative to the node specified. In `.mount` domains, the path is resolved as if it were an S3 key in the mounted bucket.
A path can be omitted altogether (i.e. a path of the form `latch://`) if and only if the domain is of the form `.node`.
Whether or not a path ends with a slash does not affect the file or directory it resolves to. However, it may affect the result of a command that uses it (e.g. [`latch cp`](../cli/cp.md)).
## Examples
* `latch:///` points to root directory in the user's current workspace.
* `latch://71.account/bottomly/genomic.fna/` points to the file at `/bottomly/genomic.fna` in the account with id `71`.
* `latch://shared/results/summary.csv` points to the file at `/results/summary.csv`, that was shared to the user's current workspace.
* `latch://mount-test.mount/11211a11.fastq` points to the file with key `11211a11.fastq` in the S3 bucket `mount-test`.
* `latch://2698497.node` points to the node with ID `2698497`.
* `latch://2698497.node/file.txt` points to the child of the node with ID `2698497` called `file.txt`.
# LatchFile / LatchDir (Legacy)
Source: https://wiki.latch.bio/workflows/sdk/python/legacy-file-support
When working with bioinformatics workflows, we are often passing around large files or directories between our tasks. These files are usually located in cloud object stores and are copied to the file systems of the machines on which the task is scheduled.
`LatchFile` / `LatchDir` and `LPath` are the two ways to work with remote files on Latch.\
`LPath` is the newer option, designed to mimic Python’s `pathlib.Path` for more intuitive and ergonomic file handling.
`LatchFile` / `LatchDir` remain fully supported and appear in many workflow examples, but we recommend using `LPath` for new workflows.
See [LPath API](/workflows/sdk/api/working-with-files) for details.
The Latch SDK provides a convenient means of referencing files or directories
within task functions without worrying about how or when the passed file objects
are copied to the task's machine at execution.
Let's look at an example.
```python theme={null}
from pathlib import Path
from latch import small_task
from latch.types import LatchFile, LatchDir
import subprocess
@small_task
def foo(fastq: LatchFile, output_dir: LatchDir) -> (LatchFile, LatchDir):
# When you pass parameter values of type LatchFile or LatchDir, the file will
# be automatically downloaded on whatever machine the task is scheduled on.
# Passing the parameter value to a python Path object and resolving it is a
# common pattern to retrieve the full path of the file on the local filesystem for
# downstream use.
local_fastq = Path(fastq).resolve()
local_output_dir = Path(output_dir).resolve()
# It's now easy to reference the contents of the file in a subprocessed
# program. Notice how we're 'placing' outputs in a directory we will return.
subprocess.call(["myprogram", "analyze", "local_fastq", "-o", str(local_output_dir)])
# We can also simply read out the contents of the file as we would normally.
with open(local_fastq) as fq:
reads = fq.read()
# Lets make a new file on this machine and return it along with the results of
# the previous subprocess.
with open("/root/foobar", "w") as fb:
fb.write("fizzbuzz")
# Notice when we return, we must specify *two* values - a local path and a
# remote path. We need to know where the file is coming from and where it's
# going. We'll discuss the latch URL scheme in a moment, but just understand
# it will go back in your filesystem on the LatchBio console for now.
return LatchFile("/root/foobar", "latch:///foobar.txt"), LatchDir(local_output_dir, output_dir.remote_path)
```
*Writing to an existing remote LatchDir will only add or update files that are in the local LatchDir.* It will not affect other files in the LatchDir. The two examples below illustrate how this works: the task updates `test.txt` without touching `foo.txt`.
```python theme={null}
# This task adds test.txt to an existing LatchDir.
@small_task
def update_dir(
output_dir: LatchDir,
) -> LatchDir:
os.mkdir('/root/output') # An empty dir
os.system('touch /root/output/test.txt') # A file in the dir
return LatchDir('/root/output', output_dir.remote_path)
```
```
Case 1: there is not an existing 'test.txt' file in the LatchDir.
. Original directory
├── foo.txt [Creation Time: 1/1/2022, 01:00:00 AM]
[Last Modified: 1/1/2022, 01:00:00 AM]
. New directory
├── foo.txt [Creation Time: 1/1/2022, 01:00:00 AM]
[Last Modified: 1/1/2022, 01:00:00 AM] # Note that it doesn't touch foo.txt
├── test.txt [Creation Time: 1/1/2022, 23:00:00 AM]
[Last Modified: 1/1/2022, 23:00:00 AM]
```
```
Case 2: there is an existing 'test.txt' file in the LatchDir.
. Original directory
├── foo.txt [Creation Time: 1/1/2022, 01:00:00 AM]
[Last Modified: 1/1/2022, 01:00:00 AM]
├── test.txt [Creation Time: 1/1/2022, 01:00:00 AM]
[Last Modified: 1/1/2022, 01:00:00 AM]
. New directory
├── foo.txt [Creation Time: 1/1/2022, 01:00:00 AM]
[Last Modified: 1/1/2022, 01:00:00 AM]
├── test.txt [Creation Time: 1/1/2022, 01:00:00 AM]
[Last Modified: 1/1/2022, 23:00:00 AM]
```
````
## Local Paths and Remote Paths
In the majority of cases, we can just use a value annotated with `LatchFile` or
`LatchDir` and expect it to yield a file handler pointing to a local file. This
gives good synergy with `Path` or `open` as we've seen above.
However, it is important to understand that these values _really_ have both a
local and remote path associated with them.
```python
# latch/types/directory.py
@property
def local_path(self) -> str:
"""File path local to the environment executing the task."""
return self._path
@property
def remote_path(self) -> Optional[str]:
"""A url referencing in object in LatchData or s3."""
return self._remote_directory
````
`local_path` will always be the absolute path on the task's machine where the
file has been copied to (the machine that your code is running on).
`remote_path` will be a remote object URL with `s3` or `latch` as its host.
There are cases when we would want
to access these `local_path` and `remote_path` attributes directly:
* Specifying the remote destination of a returned directory (eg. in the above return statement).
* Manually fetching additional files from s3 similar to a passed file's remote source.
* Using the Latch SDK to list other files similar to a passed file (eg. `latch ls latch:///foo`)
## Using Globs to Move Groups of Files
Often times logic is needed to move groups of files together based on a shared
pattern. For instance, you may wish to return all files that end with a
`fastq.gz` extension after a
[trimming](https://bmcbioinformatics.biomedcentral.com/articles/10.1186/s12859-016-1069-7#:~:text=Trimming%20of%20adapter%20sequences%20from,previously%20published%20adapter%20trimming%20tools.)
task has been run.
To do this in the SDK, you can leverage the `file_glob` function to construct
lists of `LatchFile`s defined by a pattern.
The class of allowed patterns are defined as
[globs](https://en.wikipedia.org/wiki/Glob_\(programming\)). It is likely you've
already used globs in the terminal by using wildcard characters in common
commands, eg. `ls *.txt`.
The second argument must be a valid latch URL pointing to a directory. This will
be the remote location of returned `LatchFile` constructed with this utility.
In this example, all files ending with `.fastq.gz` in the working directory of
the task will be returned to the `latch:///fastqc_outputs` directory:
```python theme={null}
from latch.types import file_glob
@small_task
def task():
...
return file_glob("*.fastq.gz", "latch:///fastqc_outputs")
```
### `latch:///` URLs
Recall that URLs (Uniform Resource Locators) describe the location of an object
on the internet.
A simplified representation of a URL string syntax can be denoted as:
```text theme={null}
scheme:///
```
Where `https://google.com` and `s3://my-bucket/dna.fa` are both valid descriptions of
objects, a webpage or a fasta file.
When referencing files stored within LatchBio's *managed filesystem* (called
LatchData) we must use the `latch` scheme to appropriately resolve objects to
the appropriate account.
For instance, `latch:///foo.txt` might meant two entirely different things in
the context of two different accounts. The resolution to retrieve the correct
object occurs based on the user that executed the workflow,
Some examples of valid latch URLs referencing objects in a user's filesystem:
* `latch:///guide_design/off_targets.csv`
* `latch:///foo.txt`
Note the three slashes. This is not accidental, but is in strict accordance with
the [URL specification](https://www.ietf.org/rfc/rfc1738.txt) as there is no
real user-facing "host" for latch objects.
### Shared `latch` URLs
Paths that are shared amongst accounts will bear the `latch://shared/`
syntax.
# Map Task
Source: https://wiki.latch.bio/workflows/sdk/python/map-task
There are many pipelines in bioinformatics that require running a processing step in parallel and aggregating their outputs at the end for downstream analysis. A prominent example of this is bulk RNA-sequencing, where alignment is performed to produce transcript abundances per sample, and gene counts of all samples are subsequently merged. Having a single count matrix makes it convenient to use in downstream steps, such as differential gene expression analysis. Another example is performing FastQC on multiple samples and summarizing the results in a MultiQC report.
The Latch SDK introduces a construct called `map_task` to help parallelize a
task across a list of inputs. This means you can run multiple instances of
the task at the same time inside a single workflow, providing valuable
performance gains.
Let's look at a simple example below!
First, import `map_task` into your workflow:
```python theme={null}
from typing import List
from latch import map_task, small_task, workflow
```
Next, define a task to use in the map task.
A map task can only accept **one input** and produce **one output**.
```python theme={null}
@small_task
def a_mappable_task(a: int) -> str:
inc = a + 2
stringified = str(inc)
return stringified
```
Let's also define a task that collects the mapped output and returns a string:
```python theme={null}
@small_task
def coalesce(b: List[str]) -> str:
coalesced = "".join(b)
return coalesced
```
We can run `a_mappable_task` across a collection of inputs using the `map_task` function. This function takes in `a_mappable_task` and returns a mapped version of that task. This mapped version takes as input a list of inputs to `a_mappable_task` , and returns a list of the outputs of `a_mappable_task` run on all inputs in the list in parallel.
```python theme={null}
@workflow
def my_map_workflow(a: typing.List[int]) -> str:
mapped_out = map_task(a_mappable_task)(a=a)
coalesced = coalesce(b=mapped_out)
return coalesced
```
That's it! You've successfully defined `a_mappable_task` that is passed to a
`map_task()` and run repeatedly on a list of inputs in parallel. You have also
defined a `coalesce` task to collect the list of outputs from the mapped task
and returns a string.
## Map a Task with Multiple Inputs
You may want to map a task with multiple inputs.
For example, the task below takes in 2 inputs, a base and a DNA sequence, and
returns the percentage of that base in the sequence:
```python theme={null}
@small_task
def count_task(base: str, dna_sequence: str) -> float:
return dna_sequence.count(base) / len(dna_sequence) * 100
```
But we only want to map this task with the `base` input while the
`dna_sequence` stays the same. Since a map task accepts only one input, we can
do this by creating a new task that prepares the map task’s inputs.
We start by putting the inputs in a Dataclass and `dataclass_json`.
```python theme={null}
from dataclasses import dataclass
@dataclass
class MapInput:
base: str
dna_sequence: str
```
Let's also define our helper task to prepare the map task’s inputs.
```python theme={null}
@small_task
def prepare_map_inputs(list_base: List[str], dna_sequence: str) -> List[MapInput]:
return [MapInput(base, dna_sequence) for base in list_base]
```
We now refactor the original `count_task`. Instead of 2 inputs, `count_task`
has a single input:
```python theme={null}
@small_task
def mappable_task(input: MapInput) -> float:
return input.dna_sequence.count(input.base) / len(input.dna_sequence) * 100
```
Let's use the new `mappable_task` in our workflow:
```python theme={null}
@workflow
def count_wf(list_base: List[str] = ["A", "T", "C", "G"], dna_sequence: str = "AAAATTTCCGG") -> List[float]:
prepared = prepare_map_inputs(list_base=list_base, dna_sequence=dna_sequence)
return map_task(mappable_task)(input=prepared)
```
Great! Now, we are able to use the `count_wf` to spin up four tasks in
parallel. The `map_task` returns a list of four floats, each of which is the
percentage of base pair in the DNA sequence.
## Bonus: Learning through a Biological Example
In the example below, we walk through a practical example of how we can use the
map task construct to run FastQC on multiple samples and summarize their
results in a MultiQC report.
First, we define a Dataclass that contains a sample name and its associated
FastQ file:
```python theme={null}
@dataclass
class Sample:
sample_name: str
fastq: LatchFile
```
Then, we create a task to run FastQC on a single sample and output the result
under the **FastQC Results** folder on Latch.
```python theme={null}
@small_task
def fastqc_task(sample) -> LatchDir:
outdir = Path("/root/fastqc_result").resolve()
outdir.mkdir(exist_ok=True)
_fastqc_cmd = [
"/root/FastQC/fastqc",
sample.fastq.local_path,
f"--outdir={outdir}"
]
subprocess.run(_fastqc_cmd, check=True)
return LatchDir("/root/fastqc_result", f"latch:///FastQC Results/{sample.sample_name}")
```
**Concept check**: Note how this task will later be mapped across a list of
samples. Therefore, the task is defined to accept one input and return one
output.
Next, define a second task to run MultiQC on a given directory for analysis
logs and compiles a HTML report.
```python theme={null}
@small_task
def multiqc_task(fastqc_results: List[LatchDir]) -> LatchDir:
outdir = Path("/root/multiqc_results").resolve()
outdir.mkdir(exist_ok=True)
fastqc_dirs = [result.local_path for result in fastqc_results]
_multiqc_cmd = ["multiqc"] + fastqc_dirs + ["-o", outdir]
subprocess.run(_multiqc_cmd, check=True)
return LatchDir(outdir, "latch:///MultiQC Results")
```
**Concept check**: Because the map task will return a list of `LatchDir`s,
each of which contains an individual sample's FastQC results, the
`multiqc_task` needs to also accept a list of `LatchDir`s.
Finally, we can specify our workflow, which accepts a list of `Sample`s and
returns a single directory with the MultiQC report:
```python theme={null}
@workflow(metadata)
def fastqc_multiqc_wf(samples: List[Sample]) -> LatchDir:
fastqc_results = map_task(fastqc_task)(sample=samples) # returns List[LatchDir]
return multiqc_task(fastqc_results=fastqc_results) # accepts a List[LatchDir] and return a single LatchDir with the MultiQC result
```
# Overview
Source: https://wiki.latch.bio/workflows/sdk/python/overview
The Latch Python SDK is an open-source toolchain to define serverless bioinformatics workflows with plain python and deploy associated no-code interfaces using single command.
## What is the Latch SDK?
The Python SDK lets you define computational workflows in Python, package them into Docker images, and run them on LatchBio's managed infrastructure.\
It provides:
* A Python API for defining **tasks** (individual steps) and **workflows** (task graphs)
* Instant no-code interfaces for accessibility and publication
* Containerization and versioning of every registered change
* Reliable and scalable managed cloud infrastructure
* Single line definition of arbitrary resource requirements (eg. CPU, GPU) for serverless execution
* Programmatic API endpoints for running workflows
## Workflows as DAGs
A **workflow** is a series of connected **tasks**, represented internally as a [directed acyclic graph](https://en.wikipedia.org/wiki/Directed_acyclic_graph) (DAG).
Each **task** is a Python function that:
* Declares its inputs via function parameters
* Returns outputs that can be passed to downstream tasks
* Contains any processing logic (Python or subprocess calls to other tools)
Example:
```python theme={null}
@small_task
def assembly_task(read1: LatchFile, read2: LatchFile) -> LatchFile:
# run bowtie2...
return LatchFile("covid_assembly.sam", "latch:///covid_assembly.sam")
@workflow
def assemble_and_sort(read1: LatchFile, read2: LatchFile) -> LatchFile:
sam = assembly_task(read1=read1, read2=read2)
return sort_bam_task(sam=sam)
```
## Next Steps
* Visit [Quick Start](/workflows/sdk/python/quick-start) to upload your first Python workflow in under 5 minutes.
* Visit [Tutorial](/workflows/sdk/python/authorizing-your-own-workflow) to understand how to author your workflow in details.
* Visit [UI](/workflows/sdk/ui/latch-metadata) for more details on how to customize your workflow interface.
# Quick Start
Source: https://wiki.latch.bio/workflows/sdk/python/quick-start
This requires an account on Latch. Register for a free account and log into the [Latch Console](https://console.latch.bio/signup)
## 1. Install Latch:
Run this in your terminal to install the Latch CLI and all of its dependancies:
```bash Terminal theme={null}
python3 -m pip install latch
```
We recommend installing Latch SDK in a fresh environment for best behavior.
### For Linux/ MacOS
You can use `venv` to a create an fresh enviroment to install the Latch SDK.
```bash theme={null}
python3 -m venv env
source env/bin/activate
```
### For Windows
The Latch SDK is a Python package, so we recommend installing Latch SDK in a fresh environment for best behavior. To do so, you can use `venv`.
1. First, install the WSL command:
```Powershell theme={null}
wsl --install
```
This command will enable the features necessary to run WSL and install the Ubuntu distribution of Linux.
2. Activate the Linux shell:
```Powershell theme={null}
wsl
```
Now, you are in a Linux environment and can create a virtual environment like so:
```bash theme={null}
python3 -m venv env
source env/bin/activate
```
## 3. Authenticate with Latch
Run this to authenticate your Latch CLI locally. This will open up a new browser window and authenticate the CLI using your account's API key.
```bash Terminal theme={null}
latch login
```
## 4. Create your first workflow from a template
This will download the subprocess workflow template using the Latch SDK framework to a directory called covid-wf.
```bash Terminal theme={null}
latch init covid-wf --template subprocess
```
## 5. Register your workflow
This will upload your workflow to your account here on Latch where you can then view the parameters and run it.
```bash Terminal theme={null}
latch register --yes --open covid-wf
```
To launch the workflow, use the Test Data button at the top of the parameters and click Launch.
5. ## Congratulations! You successfully uploaded your first workflow to Latch
Next steps are:
* Visit a detailed tutorial on [how to author your own workflow](/workflows/sdk/python/authorizing-your-own-workflow).
* Understand [how to test and debug your workflow](/workflows/sdk/testing-and-debugging-a-workflow/development-and-debugging).
# Environments for Individual Tasks
Source: https://wiki.latch.bio/workflows/sdk/python/workflow-environment/environments-for-individual-tasks
Different tasks in a workflow may need different sets of dependencies. Creating a single shared environment can be problematic as the some part of the workflow image will be unused in each task and slow down that task's startup proportionally to the size of the extraneous chunk. Different dependencies might also need different system package versions in which case installing them together might be impractical.
Instead, consider defining an individual environment for each task using the optional `dockerfile` parameter in the task definition. Include only the dependencies that each specific task needs.
The value passed to `dockerfile` must be `str` literal (meaning no variables or expressions, just a value). If the path is relative, it will be resolved against the package root.
```python theme={null}
# assemble/__init__.py
from pathlib import Path
from latch import small_task
from latch.types import LatchFile
# Path relative to the task directory
@small_task(dockerfile="wf/assemble/Dockerfile")
def assembly_task(read1: LatchFile, read2: LatchFile) -> LatchFile:
...
return LatchFile(str(sam_file), "latch:///covid_assembly.sam")
```
```python theme={null}
# sam_blaster/__init__.py
from pathlib import Path
from latch import small_task
from latch.types import LatchFile
@small_task(dockerfile="wf/sam_blaster/Dockerfile")
def sam_blaster(sam: LatchFile) -> LatchFile:
...
return LatchFile(blasted_sam, f"latch:///{blasted_sam.name}")
```
`Dockerfile`s can be organized as follows:
```shell-session theme={null}
Dockerfile
version
wf
├── __init__.py
├── assemble
│ ├── Dockerfile
│ └── __init__.py
└── sam_blaster
├── Dockerfile
└── __init__.py
```
The root directory used when building the images is always the workflow directory.
## Limitations
`latch develop` uses the `Dockerfile` in the workflow directory and not any of the individual `Dockerfiles`
# Workflow Environment
Source: https://wiki.latch.bio/workflows/sdk/python/workflow-environment/overview
Workflow code is rarely free of dependencies. It may require python or system packages or make use of environment variables. For example, a task that downloads compressed reference data from AWS S3 will need the `aws-cli` and `unzip` [APT](https://en.wikipedia.org/wiki/APT_\(software\)) packages, then use the `pyyaml` python package to read the included metadata.
The workflow environment is encapsulated in [a Docker container](https://en.wikipedia.org/wiki/Docker_\(software\)), which is created from a recipe defined in [a Dockerfile](https://docs.docker.com/engine/reference/builder/).
Latch provides automatic Dockerfile generation via the `latch dockerfile` command. You can pass a set of requirements files (detailed below) to this command to configure the generated Dockerfile to install specific dependencies in the environment.
### Python: `requirements.txt`
Dependencies from a [`requirements.txt` file](https://pip.pypa.io/en/stable/reference/requirements-file-format/) can be automatically installed using `pip`. In order to enable this, pass the path to your `requirements.txt` file to the `latch dockerfile` command using the `-p/--pip-requirements` option.
```
boto3==1.20.24
boto3-stubs[s3,sts,sns,ses,logs]
kubernetes awscli==1.22.24
```
```shell theme={null}
latch dockerfile -p requirements.txt .
```
```Dockerfile theme={null}
copy requirements.txt /opt/latch/requirements.txt
run pip install --requirement /opt/latch/requirements.txt
```
### Python: `setup.py`, PEP-621 `pyproject.toml`
Workflows with a package specification in a [`setup.py` file](https://docs.python.org/3/distutils/setupscript.html) or a [PEP-621 compliant `pyproject.toml` file](https://peps.python.org/pep-0621/) can be automatically installed using `pip`. Pass the path to either the `setup.py` or the `pyproject.toml` using the `-i/--pyproject` option.
[Poetry `pyproject.toml` files](https://python-poetry.org/docs/pyproject/) are not supported.
```python theme={null}
from setuptools import setup
setup(
name='alphafold',
version='2.2.3',
author='DeepMind',
...
)
```
```shell theme={null}
latch dockerfile -i setup.py .
```
```Dockerfile theme={null}
copy . /root/
run pip install --editable /root/
```
### Conda `environment.yaml`
The [Conda](https://docs.conda.io/en/latest/) environment in an [`environment.yaml` file](https://conda.io/projects/conda/en/latest/user-guide/tasks/manage-environments.html#create-env-file-manually) can be automatically installed using `mamba env create --file` with latest [mamba](https://mamba.readthedocs.io/en/latest/user_guide/mamba.html) installed via [Miniforge](https://github.com/conda-forge/miniforge). This environment will be used by default.
To enable, pass the path to the environment file using the `-c/--conda-env` option.
````yaml name: workflow channels: - conda-forge - defaults dependencies: - theme={null}
python=3.7 - bwakit=0.7.17 variables: reference: ~/covid19 ```
```shell
latch dockerfile -c environment.yaml .
````
```Dockerfile theme={null}
# Install Mambaforge
run apt-get update --yes && \
apt-get install --yes curl git && \
curl \
--location \
--fail \
--remote-name \
https://github.com/conda-forge/miniforge/releases/latest/download/Miniforge3-Linux-x86_64.sh && \
`# Docs for -b and -p flags: https://docs.anaconda.com/anaconda/install/silent-mode/#linux-macos` \
bash Miniforge3-Linux-x86_64.sh -b -p /opt/conda -u && \
rm Miniforge3-Linux-x86_64.sh
# Set conda PATH
env PATH=/opt/conda/bin:$PATH
run conda config --set auto_activate_base false
# Build conda environment
copy environment.yml /opt/latch/environment.yaml
run mamba env create \
--file /opt/latch/environment.yaml \
--name workflow
env PATH=/opt/conda/envs/workflow/bin:$PATH
```
### R: `environment.R`
A script in an `environment.R` file can be automatically executed when the Dockerfile is built. This is intended for installing dependencies but there are no actual limits on what the script does. The script is executed using [`rig`](https://github.com/r-lib/rig). By default, this uses the latest `R` version, though you can change this by editing the `run rig add release` line (shown below).
To enable this, pass in the path to the R file using the `-r/--r-env` flag.
Note that some R packages may have system dependencies that need to be installed using APT or another method. These packages will list these dependencies in their documentation. Missing dependencies will cause crashes during workflow build or when using the packages.
```R theme={null}
install.packages("RCurl")
install.packages("BiocManager")
BiocManager::install("S4Vectors")
```
```shell theme={null}
latch dockerfile -r environment.R .
```
```Dockerfile theme={null}
# Install rig the R installation manager
run \
curl \
--location \
--fail \
--remote-name \
https://github.com/r-lib/rig/releases/download/latest/rig-linux-latest.tar.gz && \
tar \
--extract \
--gunzip \
--file rig-linux-latest.tar.gz \
--directory /usr/local/ && \
rm rig-linux-latest.tar.gz
# Install R
run rig add release # Change to any R version
# Install R dependencies
copy version /opt/latch/environment.R
run Rscript /opt/latch/environment.R
```
### System: APT
A text file containing `apt` dependencies can also be installed by default. Each line of the file must contain an apt package (with format consistent with what is specified [here](https://linux.die.net/man/8/apt-get)). This can be enabled by passing the path to the file with the `-a/--apt-requirements` option.
```
autoconf
samtools
```
```shell theme={null}
latch dockerfile -a system-requirements.txt .
```
```Dockerfile theme={null}
copy system-requirements.txt /opt/latch/system-requirements.txt
run apt-get update --yes && \
xargs apt-get install --yes < /opt/latch/system-requirements.txt
```
### Environment Variables
Environment variables contained in a file can be automatically added to the workflow environment. Pass the path of the file containing the environment variables using the `-d/--direnv` option.
```
BOWTIE2_INDEXES=reference
PATH="/root/bowtie2:$PATH"
```
```shell theme={null}
latch dockerfile -d .env .
```
```Dockerfile theme={null}
env BOWTIE2_INDEXES="reference"
env PATH="/root/bowtie2:$PATH"
```
## Example of Auto-generated Dockerfile
The following Dockerfile is generated in the `subprocess` template (using `latch init --template subprocess --dockerfile example_workflow`):
```Dockerfile theme={null}
# latch base image + dependencies for latch SDK --- removing these will break the workflow
from 812206152185.dkr.ecr.us-west-2.amazonaws.com/latch-base:ace9-main
run pip install latch==2.12.1
run mkdir /opt/latch
# install system requirements
copy system-requirements.txt /opt/latch/system-requirements.txt
run apt-get update --yes && xargs apt-get install --yes
Snakemake executes remote jobs by **calling itself again**, with appropriate command-line arguments to ensure that the right storage plugin is being used, and that only the target rule is being executed. For this reason, it is vital that all containers have both `snakemake` and `snakemake-storage-plugin-latch` installed, and that `snakemake` is available on `$PATH`.
You can check that this is the case by running the container locally:
```shell theme={null}
$ docker run -it bash
root@container:/# snakemake --version
8.25.3
root@container:/# pip show snakemake-storage-plugin-latch
Name: snakemake-storage-plugin-latch
Version: 0.1.9
...
```
### Conda
It is possible to use the default container image for every rule, and use conda environment files to specify dependencies for each rule. While this practice is encouraged by snakemake, we caution against this for the sole reason of workflow performance. Simple conda environments can take multiple minutes to build, and complex ones can take even longer. Moreover, this time cost will be incurred *for every run of the workflow*, which can become expensive.
Instead, we strongly encourage you to build container images for each conda environment and use those for your rules instead. By paying the cost of building the conda environments / containers once, you save time during every workflow execution.
## Machine Specs
To configure the size and specs of the machine that the job runs on, use the `resources:` directive:
```snakemake theme={null}
rule use_pandas:
input:
storage.latch("latch://123.account/input.txt")
output:
storage.latch("latch://123.account/output.txt")
container:
"docker://812206152185.dkr.ecr.us-west-2.amazonaws.com/snakemake/pandas:2.2.5"
resources:
cpu = 2,
mem_gib = 4
script:
"scripts/use_pandas.py"
```
The following resource keys are valid:
1. `cpu` / `cpus` for CPU specification,
2. `mem_{unit}` for RAM specification - `{unit}` can be any [metric](https://en.wikipedia.org/wiki/Metric_prefix) or [binary](https://en.wikipedia.org/wiki/Binary_prefix) unit, such as `mib` or `gb`,
3. `disk_{unit}` for Ephemeral Storage / Disk space specification, with the same rules for `{unit}` as `mem`,
4. `gpu` / `gpus` for specifying the number of GPUs desired, and
5. `gpu_type` for the type of GPU to use. This field is mandatory if `gpu`/`gpus` is greater than 0. See [here](/workflows/sdk/nextflow/gpus) for valid GPU type/quantity combinations.
For `mem` and `disk`, you can also specify resources with the unit after the quantity - for example, the following is equivalent to the previous rule's resources:
```
resources:
cpu = 2,
mem = "4 GiB"
```
# Metadata
Source: https://wiki.latch.bio/workflows/sdk/snakemake-v2/metadata
In order to generate the interface for your workflow on Latch, you need to specify which parameters you want to expose - and how you want to expose them - in a `latch_metadata` package.
In your workflow directory, create a folder called `latch_metadata`, and in it, add a file called `__init__.py`. The content of the file should look like this:
```python theme={null}
from dataclasses import dataclass
from typing import List
from latch.types.directory import LatchDir, LatchOutputDir
from latch.types.file import LatchFile
from latch.types.metadata.latch import LatchAuthor
from latch.types.metadata.snakemake import SnakemakeParameter
from latch.types.metadata.snakemake_v2 import SnakemakeV2Metadata
@dataclass
class Sample:
name: str
r1: LatchFile
r2: LatchFile
metadata = SnakemakeV2Metadata(
display_name="Test Workflow",
author=LatchAuthor(),
parameters={
"samples": SnakemakeParameter(
display_name="Samples",
type=List[Sample],
samplesheet=True,
),
"results_dir": SnakemakeParameter(
display_name="Results Dir",
type=LatchOutputDir,
default=LatchDir("latch://123.account/results"),
),
},
)
```
The only hard requirements for this file is that it create a `SnakemakeV2Metadata` object and define an appropriate set of parameters using `SnakemakeParameter` objects. `SnakemakeParameter`s are identical to [`LatchParameter`s](/workflows/sdk/ui/latch-metadata#latchparameter), with an additional required `type` field.
Values passed through the interface will be marshalled into JSON and then provided to your workflow as an external config file. For example, in the above workflow, if we pass a single Sample called `test` with `r1` at `latch://123.account/test_r1.fastq` and `r2` at `latch://123.account/test_r2.fastq`, the resulting config file would look like
```json theme={null}
{
"samples": [
{
"name": "test",
"r1": "/ldata/123.account/test_r1.fastq",
"r2": "/ldata/123.account/test_r2.fastq"
}
],
"results_dir": "latch://123.account/results"
}
```
These can then be accessed from within the Snakemake workflow via the `config` object, e.g. `config["samples"][0]` would get the first sample. See [encoding](./encoding) for more info.
# Overview
Source: https://wiki.latch.bio/workflows/sdk/snakemake-v2/overview
Currently in Alpha. Install the latest alpha release at `latch==2.62.1a2`
This feature is undergoing active testing. If you encounter any bugs or issues, please contact our support team at [support@latch.bio](mailto:support@latch.bio). Your feedback is invaluable and will directly influence improvements to this feature.
Latch's Snakemake integration allows developers to build graphical interfaces to expose their Snakemake workflows to wet lab teams. It also provides managed cloud infrastructure to execute, debug, and analyze your workflows.
A primary goal for the Snakemake integration is to allow developers to register existing Snakemake projects with minimal added boilerplate and modifications to code.
## How It Works
To get started, install the latest alpha build of `latch` (Note that the version below may be out of date, please check [PyPI](https://pypi.org/project/latch/#history) for the latest release marked "PRE-RELEASE"):
```bash theme={null}
pip install latch==2.62.1a2
```
Next, navigate to your Snakemake workflow directory. Making your pipeline cloud compatible on Latch requires five main steps.
If this is your first time using Latch's Snakemake integration, we recommend starting with the [tutorial](./tutorial), which walks through the process end-to-end. Once you've completed it, return to the detailed documentation for each step to deepen your understanding.
Specify the parameters you want to expose to scientists on Latch.
[Documentation ↗](./metadata)
Declare the compute specifications and container images for each Snakemake rule.
[Documentation ↗](./executor)
Configure Snakemake to read and write files directly from Latch Data.
[Documentation ↗](./storage)
Create a Python file that Latch uses to launch your Snakemake workflow in the cloud.
[Documentation ↗](./entrypoint)
Define the environment in which your workflow will run.
[Documentation ↗](./dockerfile)
Once these steps are done, you can register this as you would any other Latch workflow:
```shell theme={null}
$ latch register -y .
```
## Start Here
To get started, follow along with an example workflow [here](./tutorial).
# Using Latch Storage
Source: https://wiki.latch.bio/workflows/sdk/snakemake-v2/storage
Snakemake exposes a storage interface that allows developers to write custom plugins to enable reading from and writing to custom data stores. The `snakemake-storage-plugin-latch` package is a plugin that allows `snakemake` to interact natively with [Latch Data](/data/overview).
# Overview
The storage plugin works by treating files on Latch as if they were files under a non-existence `/ldata` directory. For example, the file `latch://123.account/a/b/c.txt` would be represented internally as `/ldata/123.account/a/b/c.txt`.
This scheme allows common patterns such as `Path(dir) / "file"` to "just work" with Latch objects. When creating the `config` file, `LatchFile`s and `LatchDir`s are encoded as paths of this form.
# Usage
Configuring your `Snakefile` to use this storage plugin is, in most cases, fairly straightforward. There are a few exceptional cases to keep in mind, but for the most part minimal edits are required. Following are a description of common cases where edits are required.
## Using the `{input}` / `{output}` Wildcards
Firstly, ensure that *there are no hardcoded paths in any shell commands*. For example
```snakemake theme={null}
rule test_storage:
input:
"hello.txt"
output:
os.path.join(config['remote_output_dir'], "hello.txt") # assume config['remote_output_dir'] is a path on Latch
shell:
"cp {input} {output}"
```
will copy the local file `hello.txt` onto Latch under `remote_output_dir`.
Note that in the example above, the shell command never explicitly references the output path, and instead references the `{output}` wildcard. This is intentional, and all rules that can reference Latch objects must use this pattern to function correctly.
Snakemake storage plugins in general work by doing all operations on a local copy of the remote file, then uploading the remote file back at the end of rule execution. In the example above, the `{output}` wildcard is replaced with the path of the local copy. This local copy is stored opaquely and its location can change at runtime depending on the way the pipeline is configured, so the only way to reliably reference it is by using the wildcard. This also applies to inputs and the `{input}` wildcard, for the exact same reason.
## Remote Paths in the `params:` Directive
When using a remote path in `params:` directive, it is required that the path be marked with the `storage(...)` flag.
By default, Snakemake does not consider `params:` members as storage objects unless explicitly told to do so, hence file downloads / uploads will not happen. For this reason, every parm value that can be a remote storage object must be marked with `storage(...)`. For example:
```snakemake theme={null}
rule test_storage:
input:
"hello.txt"
params:
auxilliary = storage(config['auxilliary_file'])
output:
os.path.join(config['remote_output_dir'], "hello.txt") # assume config['remote_output_dir'] is a path on Latch
shell:
"cp {input} {output} && cp {input} {params.auxilliary}"
```
## Using Filesystem APIs outside of Rules
Since remote paths represent remote identifiers rather than local filesystem objects, code that performs file operations (such as reading file contents) will not work outside of a rule context. When your pipeline execution depends on accessing specific files before rule execution begins, we recommend **explicitly downloading these files in the runtime task before calling `snakemake`**. The runtime task function definition can be found in the `entrypoint.py` file generated by the `latch snakemake generate-entrypoint` command.
For example, you expand a wildcard based on which files are present in a specific `input_dir`. You can stage this `input_dir` ahead of time like below:
```python3 theme={null}
# Assume `input_dir` is a `LatchDir` parameter passed to `snakemake_runtime(...)`
print(f"Staging {input_dir.remote_path}...", flush=True)
# Need `from latch.ldata.path import LPath` at the top of file
input_dir = LPath(input_dir.remote_path).download(shared / "input_dir")
print("Done.")
config = {
...
"input_dir": get_config_val(input_dir),
...
}
```
Note that after the directory is downloaded locally, instead of passing the remote identifier to the `config` object, we pass the local path of the downloaded directory.
# Tutorial
Source: https://wiki.latch.bio/workflows/sdk/snakemake-v2/tutorial
Learn how to upload a Snakemake workflow on Latch.
## Prerequisites
* Register for an account and log into the [Latch Console](https://console.latch.bio)
* Install a compatible version of Python. The Latch SDK is currently only supported for Python `>=3.8` and `<=3.11`
* Install the Latch SDK `== 2.62.1a2`
Example on Ubuntu:
```bash theme={null}
mamba create -n env python=3.11 -n "latch-snakemake"
mamba activate latch-snakemake
pip install latch==2.62.1a2
```
## Step 1: Clone your Snakemake workflow
We will use the [snakemake-v2-tutorial](https://github.com/latchbio/snakemake-v2-tutorial) as an example; however, feel free to follow along with any Snakemake workflow.
```bash theme={null}
git clone https://github.com/latchbio/snakemake-v2-tutorial.git
cd snakemake-v2-tutorial
```
## Step 2: Configure workflow resources and containers
Before deploying to Latch, we need to specify resource requirements for each job in the workflow. Since this is a relatively low footprint pipeline, we can make each machine small and provide 1 core and 2 GiB of RAM.
You only need to do this if your Snakefile rules don't already have resources defined. This profile serves as a fallback for rules without explicit resource specifications.
Create a directory called `profiles/default` and in it create a file called `config.yaml`:
```bash theme={null}
mkdir -p profiles/default
touch profiles/default/config.yaml
```
Then, add the following YAML content to the `config.yaml`:
```yaml theme={null}
default-resources:
cpu: 1
mem_mib: 2048
```
This will set the default resources for every rule. Note that you can override these for any rule by updating the resources of that rule directly.
## Step 3: Define metadata and workflow graphical interface
The input parameters need to be explicitly defined to construct a graphical interface for a Snakemake workflow. These parameters will be exposed to scientists in a web interface once the workflow is uploaded to Latch.
First, make a directory called `latch_metadata` and in it create a file called `__init__.py`:
```bash theme={null}
mkdir latch_metadata
touch latch_metadata/__init__.py
```
In `latch_metadata/__init__.py`, create a `SnakemakeV2Metadata` object as below:
```python theme={null}
from latch.types.directory import LatchDir, LatchOutputDir
from latch.types.metadata.latch import LatchAuthor
from latch.types.metadata.snakemake import SnakemakeParameter
from latch.types.metadata.snakemake_v2 import SnakemakeV2Metadata
metadata = SnakemakeV2Metadata(
display_name="Snakemake Tutorial Workflow",
author=LatchAuthor(),
parameters={},
)
```
This object still doesn't have any parameter metadata yet, so we need to add it. Looking at the workflow configuration in the `config.yaml` file, we see that the pipeline expects 3 config parameters: `samples_dir`, `genome_dir`, and `results_dir`. The former two are inputs to the pipeline and the latter is the location where outputs will be stored.
We want all three of these to be exposed in the UI, so we will add them to the `parameters` dict in `latch_metadata/__init__.py`:
```python theme={null}
from latch.types.directory import LatchDir, LatchOutputDir
from latch.types.metadata.latch import LatchAuthor
from latch.types.metadata.snakemake import SnakemakeParameter
from latch.types.metadata.snakemake_v2 import SnakemakeV2Metadata
metadata = SnakemakeV2Metadata(
display_name="Snakemake Tutorial Workflow",
author=LatchAuthor(),
parameters={
"samples_dir": SnakemakeParameter(
display_name="Sample Directory",
type=LatchDir,
),
"genome_dir": SnakemakeParameter(
display_name="Genome Directory",
type=LatchDir,
),
"results_dir": SnakemakeParameter(
display_name="Output Directory",
type=LatchOutputDir,
),
},
)
```
In each parameter, we specified (1) a human-readable name to display in the UI, and (2) the type of parameter to accept. Since the workflow expects all of these to be directories, they are all `LatchDir`s (we made `results_dir` a `LatchOutputDir` because it is an output directory).
For now, this is all we need and we can move on, but if you like feel free to customize the metadata object further using the interface described [here](/workflows/sdk/ui/latch-metadata).
Let's inspect the most relevant fields of the `SnakemakeV2Metadata` object:
* **`display_name`**: The display name of the workflow, as it will appear on the Latch UI.
* **`author`**: Name of the person or organization that publishes the workflow
* **`parameters`**: Input parameters to the workflow, defined as `SnakemakeParameter` objects. The Latch Console will expose these parameters to scientists before they execute the workflow.
## Step 4: Generate the entrypoint
Now we need to generate the entrypoint file containing the Latch workflow wrapping our Snakemake workflow. This is a simple command:
```bash theme={null}
latch snakemake generate-entrypoint .
```
This should create a directory called `wf` containing a file called `entrypoint.py`. The file should have the following contents:
```python theme={null}
import json
import os
import shutil
import subprocess
import sys
import typing
from dataclasses import dataclass
from enum import Enum
from pathlib import Path
import requests
import typing_extensions
from latch.resources.tasks import custom_task, snakemake_runtime_task
from latch.resources.workflow import workflow
from latch.types.directory import LatchDir, LatchOutputDir
from latch.types.file import LatchFile
from latch_cli.services.register.utils import import_module_by_path
from latch_cli.snakemake.v2.utils import get_config_val
import_module_by_path(Path("latch_metadata/__init__.py"))
import latch.types.metadata.snakemake_v2 as smv2
@custom_task(cpu=0.25, memory=0.5, storage_gib=1)
def initialize() -> str:
token = os.environ.get("FLYTE_INTERNAL_EXECUTION_ID")
if token is None:
raise RuntimeError("failed to get execution token")
headers = {"Authorization": f"Latch-Execution-Token {token}"}
print("Provisioning shared storage volume... ", end="")
resp = requests.post(
"http://nf-dispatcher-service.flyte.svc.cluster.local/provision-storage-ofs",
headers=headers,
json={
"storage_expiration_hours": 0,
"version": 2,
"snakemake": True,
},
)
resp.raise_for_status()
print("Done.")
return resp.json()["name"]
@snakemake_runtime_task(cpu=1, memory=2, storage_gib=50)
def snakemake_runtime(
pvc_name: str,
samples_dir: LatchDir,
genome_dir: LatchDir,
results_dir: LatchOutputDir,
):
print(f"Using shared filesystem: {pvc_name}")
shared = Path("/snakemake-workdir")
snakefile = shared / "Snakefile"
config = {
"samples_dir": get_config_val(samples_dir),
"genome_dir": get_config_val(genome_dir),
"results_dir": get_config_val(results_dir),
}
config_path = (shared / "__latch.config.json").resolve()
config_path.write_text(json.dumps(config, indent=2))
ignore_list = [
"latch",
".latch",
".git",
"nextflow",
".nextflow",
".snakemake",
"results",
"miniconda",
"anaconda3",
"mambaforge",
]
shutil.copytree(
Path("/root"),
shared,
ignore=lambda src, names: ignore_list,
ignore_dangling_symlinks=True,
dirs_exist_ok=True,
)
cmd = [
"snakemake",
"--snakefile",
str(snakefile),
"--configfile",
str(config_path),
"--executor",
"latch",
"--default-storage-provider",
"latch",
"--jobs",
"1000",
]
print("Launching Snakemake Runtime")
print(" ".join(cmd), flush=True)
failed = False
try:
subprocess.run(cmd, cwd=shared, check=True)
except subprocess.CalledProcessError:
failed = True
finally:
if not failed:
return
sys.exit(1)
@workflow(smv2._snakemake_v2_metadata)
def snakemake_v2_snakemake_tutorial_workflow(
samples_dir: LatchDir, genome_dir: LatchDir, results_dir: LatchOutputDir
):
"""
Sample Description
"""
snakemake_runtime(
pvc_name=initialize(),
samples_dir=samples_dir,
genome_dir=genome_dir,
results_dir=results_dir,
)
```
## Step 5: Generate the Dockerfile
The last step pre-registering is to generate the `Dockerfile` that will define the environment the runtime executes in. In particular, we want that environment to contain the conda environment defined by `environment.yaml`.
Again, we can accomplish this with a simple command:
```bash theme={null}
latch dockerfile --snakemake -c environment.yaml . -f
```
This will generate a file called `Dockerfile` with the following contents:
```Dockerfile theme={null}
# Prologue
# DO NOT CHANGE
from 812206152185.dkr.ecr.us-west-2.amazonaws.com/latch-base:fe0b-main
workdir /tmp/docker-build/work/
shell [ \
"/usr/bin/env", "bash", \
"-o", "errexit", \
"-o", "pipefail", \
"-o", "nounset", \
"-o", "verbose", \
"-o", "errtrace", \
"-O", "inherit_errexit", \
"-O", "shift_verbose", \
"-c" \
]
env TZ='Etc/UTC'
env LANG='en_US.UTF-8'
arg DEBIAN_FRONTEND=noninteractive
# Install Mambaforge
run apt-get update --yes && \
apt-get install --yes curl git && \
curl \
--location \
--fail \
--remote-name \
https://github.com/conda-forge/miniforge/releases/latest/download/Miniforge3-Linux-x86_64.sh && \
`# Docs for -b and -p flags: https://docs.anaconda.com/anaconda/install/silent-mode/#linux-macos` \
bash Miniforge3-Linux-x86_64.sh -b -p /opt/conda -u && \
rm Miniforge3-Linux-x86_64.sh
# Set conda PATH
env PATH=/opt/conda/bin:$PATH
run conda config --set auto_activate_base false
# Build conda environment
copy environment.yaml /opt/latch/environment.yaml
run mamba env create \
--file /opt/latch/environment.yaml \
--name environment
env PATH=/opt/conda/envs/environment/bin:$PATH
# Copy workflow data (use .dockerignore to skip files)
copy . /root/
# Epilogue
# Latch SDK
# DO NOT REMOVE
run pip install "latch[snakemake]"==2.55.0.a6
# Latch workflow registration metadata
# DO NOT CHANGE
arg tag
# DO NOT CHANGE
env FLYTE_INTERNAL_IMAGE $tag
workdir /root
```
## Step 6: Register the workflow
To register a Snakemake workflow on Latch, type:
```bash theme={null}
latch login
latch register -y .
```
The `latch register` command searches for a Latch workflow in the current directory and registers it to Latch.
After running the above command, the Latch SDK will generate the necessary files and upload your workflow to Latch.
Once the workflow is registered, navigate to the [Workflows tab](https://console.latch.bio/workflows) in the Latch Console and select the workflow you previously registered.
## Step 7: Execute the workflow
Before executing the workflow, we need to upload test data to Latch. You can upload the data using `latch cp`:
```bash theme={null}
latch cp data latch:///snakemake-tutorial-data
```
This will upload the data to a folder called `snakemake-tutorial-data` in your account on Latch.
Now, navigate to the [Workflows tab](https://console.latch.bio/workflows) in the Latch Console and select the workflow you previously registered.
Then, select the appropriate input parameters from the test data you uploaded and click `Launch Workflow` to execute the workflow.
## Step 8: Monitoring the workflow
After launching the workflow, you can monitor progress by clicking on the appropriate execution under the `Executions` tab of your workflow.
Under the `Graph & Logs` tab, you can view the generated DAG and monitor the execution of your Snakemake workflow.
Once the workflow starts executing, you can monitor the status of each rule in the workflow through the Latch Console interface.
## Step 9 (Optional): Customizing the workflow using dynamic sample detection
You may have noticed that in the Snakefile, the sample names are hardcoded. This is obviously not desirable - we should be able to infer the sample names based on the contents of the Sample directory.
In order to accomplish this, we will need to edit both the Snakefile, and the `entrypoint` file itself. Since we need to know the contents of the Sample directory outside of a rule, we will need to stage it locally before the pipeline executes.
First, add the following import to the top of the `wf/entrypoint.py` file:
```python theme={null}
from latch.ldata.path import LPath
```
Next, edit the start of `snakemake_runtime(...)` so that it is the following:
```python theme={null}
@snakemake_runtime_task(cpu=1, memory=2, storage_gib=50)
def snakemake_runtime(
pvc_name: str,
samples_dir: LatchDir,
genome_dir: LatchDir,
results_dir: LatchOutputDir,
):
print(f"Using shared filesystem: {pvc_name}")
shared = Path("/snakemake-workdir")
snakefile = shared / "Snakefile"
# Staging samples_dir
local_samples_dir = LPath(samples_dir.remote_path).download(shared / "samples")
config = {
"samples_dir": get_config_val(local_samples_dir),
"genome_dir": get_config_val(genome_dir),
"results_dir": get_config_val(results_dir),
}
...
```
Here we explicitly download the `samples_dir` before calling `snakemake` - this way we will know the contents of the directory without needing to be in a rule.
Lastly, we will need to edit the Snakefile and remove the hardcoded samples:
```python theme={null}
# Replace SAMPLES = ["A", "B"] with the following:
SAMPLES = []
for sample in samples_dir.iterdir():
SAMPLES.append(sample.stem)
```
Now just re-register and see all 3 samples be run through the pipeline.
```bash theme={null}
latch register .
```
***
## What You've Learned
**Core Concepts:**
* **Latch's Snakemake integration** allows running Snakemake workflows with a graphical web interface.
* **Metadata definition** creates the parameter interface that scientists will use to configure and run workflows.
**Development Workflow:**
1. Clone your Snakemake workflow
2. Define metadata to create the workflow's parameter interface.
3. Generate entrypoint with `latch snakemake generate-entrypoint .` to create the Latch wrapper.
4. Generate Dockerfile with `latch dockerfile --snakemake -c environment.yaml . -f` for the execution environment.
5. Register the pipeline with `latch register -y .`.
6. Upload test data to Latch and select inputs from the Console.
7. Monitor execution through the Graph & Logs interface.
8. Customize the generated `entrypoint.py` for additional pre- or post-processing logic.
## Next Steps
* Explore [custom workflow interfaces](/workflows/sdk/python/customizing-your-interface/overview)
* Learn about [testing and debugging workflows](/workflows/sdk/testing-and-debugging-a-workflow/overview)
# Development and Debugging
Source: https://wiki.latch.bio/workflows/sdk/testing-and-debugging-a-workflow/development-and-debugging
Run and debug workflow tasks before registration
Available in `latch >= 2.65.7`
Workflows on Latch run inside a container built from your Dockerfile. This environment can differ significantly from your local machine (different OS, Python version, system packages, or installed dependencies). These differences can cause issues that don't appear during local testing.
To avoid surprises after registration, it's best to debug inside the exact environment your workflow will use.
The `latch develop` command lets you build your workflow image and drop into an interactive shell within that container. From there, you can:
* Run individual tasks or workflows directly
* Check installed packages and dependencies
* Test imports, data access, and other environment-specific behavior
This approach ensures that the code you test is running in the same conditions it will see when executed on Latch, helping you catch both environment and logic issues before running the workflow end-to-end.
## Setup
* Install `latch` version `2.65.7` or later.
* Start a development shell for your workflow by using the following commands:
```console theme={null}
$ cd test-wf # Navigate to your workflow directory
$ latch register --staging . # The `--staging` flag builds image without releasing a new version to Latch Console
$ latch develop . # Open interactive shell inside the workflow environment
```
This opens an interactive shell on a remote instance running the environment built from your Dockerfile.
## Example Usage
On your local machine, create test scripts first, then run them from within the `latch develop` interactive shell to validate your workflow.
Below is a sample test script for the `nf-core/atac-seq` workflow. This script runs nf\_nf\_core\_atacseq function with multiple input samples stored in public S3 buckets:
```python nf-core/atacseq Test Example expandable theme={null}
from wf.__init__ import *
nf_nf_core_atacseq(
input=[
SampleSheet(
sample="Sample_6",
fastq_1=LatchFile("s3://latch-public/test-data/35929/Test_Dataset_Verified/Sample_6/Sample_6.Rep_1.R1.fastq.gz"),
fastq_2=LatchFile("s3://latch-public/test-data/35929/Test_Dataset_Verified/Sample_6/Sample_6.Rep_1.R2.fastq.gz"),
replicate=1,
),
SampleSheet(
sample="Sample_6",
fastq_1=LatchFile("s3://latch-public/test-data/35929/Test_Dataset_Verified/Sample_6/Sample_6.Rep_2.R1.fastq.gz"),
fastq_2=LatchFile("s3://latch-public/test-data/35929/Test_Dataset_Verified/Sample_6/Sample_6.Rep_2.R2.fastq.gz"),
replicate=2,
),
SampleSheet(
sample="Sample_1",
fastq_1=LatchFile("s3://latch-public/test-data/35929/Test_Dataset_Verified/Sample_1/Sample_1.Rep_1.R1.fastq.gz"),
fastq_2=LatchFile("s3://latch-public/test-data/35929/Test_Dataset_Verified/Sample_1/Sample_1.Rep_1.R2.fastq.gz"),
replicate=1,
),
SampleSheet(
sample="Sample_1",
fastq_1=LatchFile("s3://latch-public/test-data/35929/Test_Dataset_Verified/Sample_1/Sample_1.Rep_2.R1.fastq.gz"),
fastq_2=LatchFile("s3://latch-public/test-data/35929/Test_Dataset_Verified/Sample_1/Sample_1.Rep_2.R2.fastq.gz"),
replicate=2,
),
],
genome_source="latch_genome_source",
run_name="Test-1",
read_length=50,
aligner=Aligner.bowtie2,
fasta=None,
gtf=None,
outdir=LatchOutputDir("latch:///ATAC_Seq_Test"),
latch_genome=Reference.hg19,
with_control=False,
skip_trimming=False,
skip_qc=False,
)
```
```bash Inside latch-develop shell theme={null}
python3 ~/atacseq/tests/main.py
```
See the full GitHub repository [here](https://github.com/latchbio-nfcore/atacseq/tree/harihara-testscases/tests).
If you are using local files while testing with latch develop, the workflow function signature still requires a LatchFile object. Pass the local file path to LatchFile, for example `LatchFile("/root/path/to/local_test_file.fastq.gz")`
## `latch develop` Sync Behavior
* `latch develop` syncs files from your local workflow directory using rsync. Files outside this directory are not synced. If you need test data, place it in a subfolder inside your workflow directory.
* Updated or new local files overwrite matching files in the container. All code changes must be made locally. Edits made inside the latch develop container are not saved back to your machine and may be overwritten during sync.
* Deleted local files are not removed from the container.
* If you change your Dockerfile, run `latch register --staging` to rebuild the image, then run `latch develop` again to enter the updated environment.
## Advanced Notes for Nextflow Users
In a normal Latch production run, the `initialize` task provisions a shared POSIX filesystem volume (OFS) and returns an identifier (usually passed as `pvc_name`) so downstream Nextflow tasks can read and write to a common mount. This works because the task is running inside Latch's execution environment, which has access to the internal dispatcher service that provisions storage and Kubernetes infrastructure to mount the volume
When you run `latch develop`, none of those services exist — you're just inside an interactive shell in the workflow container. As a result, any attempt to call initialize will fail.
The solution is to either run the `runtime_task` directly using `""` as the value of `pvc_name` or adding a conditional `if` check in the `initialize` task as below:
```python theme={null}
@custom_task(...)
def initialize(run_name: str) -> str:
if os.environ.get("LATCH_NF_DEBUG") is not None:
return ""
...
```
Full GitHub repository example [here](https://github.com/latchbio-nfcore/atacseq/blob/37c28a0c62d2463eec5f8038fc251efc4ba58e24/wf/entrypoint.py#L70).
In your `latch.config`, set the executor to `local` in debug mode so tasks can run without k8s. This ensures you can still test task logic inside `latch develop` without depending on infrastructure that only exists in production.
```latch.config theme={null}
process {
executor = 'k8s'
}
if (System.getenv("LATCH_NF_DEBUG") == "true") {
process {
executor = 'local'
}
}
```
Full GitHub repository example [here](https://github.com/latchbio-nfcore/atacseq/blob/37c28a0c62d2463eec5f8038fc251efc4ba58e24/latch.config#L5)
In the workflow's Dockerfile, ensure that you are using either `latch-base-nextflow` versions `>= v3.0.5` or `>= v2.5.6` (See [example](https://github.com/latchbio-nfcore/atacseq/blob/37c28a0c62d2463eec5f8038fc251efc4ba58e24/Dockerfile#L2))
When running tasks, the Python interpreter must have the latch SDK. If your container uses another environment (e.g., mamba/conda), it may:
* Not include `latch` package
* Override \$PATH so the wrong Python is used
**Best practice:**
* Use `/usr/local/bin/python3` (default in Latch base images)
* Install extra packages into this env instead of creating a separate one
* Check with:
```bash theme={null}
which python3
```
Make sure that your process config requests fewer resources than normal. This is to avoid running into issues where processes won't run because they request more resources than are available in the `latch develop`'s instance.
If necessary, modify the `-XX:ActiveProcessorCount` in your Nextflow command in the `entrypoint.py` file to cap Java's perceived cores.(See example [here](https://github.com/latchbio-nfcore/atacseq/blob/37c28a0c62d2463eec5f8038fc251efc4ba58e24/wf/entrypoint.py#L316))
## Choosing Instance Size
This feature is available in `latch` versions `2.59.0` and later.
Use the `--instance-size` flag to run latch develop on a specific instance type. This is useful when debugging code that depends on certain hardware specs.
Example:
```console theme={null}
$ latch develop . --instance-size small_gpu_task
```
runs on an instance with 1 NVIDIA T4 GPU.
**Supported instance sizes:**
| Instance Size | Cores | RAM | GPU |
| ----------------- | ----- | ------- | -------------- |
| `small_task` | 2 | 4 GiB | – |
| `medium_task` | 30 | 100 GiB | – |
| `large_task` | 90 | 170 GiB | – |
| `small_gpu_task` | 7 | 30 GiB | 1× NVIDIA T4 |
| `large_gpu_task` | 63 | 245 GiB | 1× NVIDIA A10G |
| `v100_x1_task` | 7 | 48 GiB | 1× NVIDIA V100 |
| `g6e_xlarge_task` | 4 | 32 GiB | 1× NVIDIA L40S |
Note: Larger instances may take 5+ minutes to start.
# Programmatic Execution
Source: https://wiki.latch.bio/workflows/sdk/testing-and-debugging-a-workflow/programmatic-execution
Execute a workflow programmatically from python.
Available in `latch >= 2.62.0`
The Latch SDK provides a Python API to programmatically launch workflows and monitor their status. This is useful for integrating workflows into automated test suites (e.g., GitHub CI/CD).
There are two ways to launch a workflow programmatically:
1. Call the workflow with Python parameter values.
2. Use a `LaunchPlan` from a previously registered workflow.
## Pre-requisites
* Please make sure you have registered your workflow to Latch using `latch register`. This creates a new workflow version, which you will reference in your script.
## Usage
```python expandable theme={null}
from latch.types.file import LatchFile
from latch_cli.services.launch.launch_v2 import launch
from wf.entrypoint import GenomeReference, Sample
# Using python parameter values
execution_id = launch(
wf_name="my_workflow",
version="0.1.0",
params={
"input": [
Sample(
patient="TestSample",
fastq_1=LatchFile(
"latch:///test_L1_1.fastq.gz"
),
...
),
...
],
"genome": GenomeReference.GATK_GRCh37,
...
}
)
```
**Parameters**:
* `wf_name:` Name of the workflow function. This is the function defined immediately after the `@workflow` decorator in your code ([Example](https://github.com/latchbio-nfcore/methylseq/blob/96d58c8532a5c2ae6204e21209f71148bc78dc1e/wf/__init__.py#L20))
* `version`: Workflow version registered on Latch
* `params`: Dictionary of parameter names and values. If the python values are not typed using the exact same types used in the workflow function signature (including the module paths), the `best_effort` parameter should be set to `True`.
* `best_effort` (default True): (available in `latch >= 2.67.8`) When set to `True`, allows for flexible conversion of params to workflow inputs. This enables launching workflows outside of the workflow environment with compatible values (e.g., strings for enums where the string matches an enum option, or dictionaries/dataclasses with all the fields of a particular dataclass).
```python expandable theme={null}
import email.utils
import time
from datetime import datetime
from latch_cli.services.launch.launch_v2 import launch_from_launch_plan
from latch_cli.tinyrequests import post
from latch_cli.utils import get_auth_header
from latch_sdk_config.latch import config
# Using a previously registered LaunchPlan
execution_id = launch_from_launch_plan(
wf_name="my_workflow",
version="0.1.0",
lp_name="Test Data",
)
# Polling execution status
while True:
list_resp = post(
url=config.api.execution.list,
headers = {"Authorization": get_auth_header()},
json={"ws_account_id": "XXXXX"},
).json()
target_execution = list_resp[str(execution_id)]
target_execution_status: str = target_execution.get('status')
if target_execution_status == 'SUCCEEDED':
break
elif target_execution_status == 'FAILED':
raise Exception("Execution failed")
elif target_execution_status == 'ABORTED':
raise Exception("Execution aborted")
elif target_execution_status == 'UNDEFINED':
time.sleep(5)
continue
start_time_str: str = target_execution.get('start_time')
start_time_tuple = email.utils.parsedate_tz(start_time_str)
if start_time_tuple is None:
raise Exception("Failed to parse start time")
start_time = datetime.fromtimestamp(email.utils.mktime_tz(start_time_tuple))
current_time = datetime.now()
if (current_time - start_time).total_seconds() > 300:
raise TimeoutError("Execution has been running for more than 5 minutes")
time.sleep(10)
```
**Parameters**:
* `wf_name:` Name of the workflow function. This is the function defined immediately after the `@workflow` decorator in your code ([Example](https://github.com/latchbio-nfcore/methylseq/blob/96d58c8532a5c2ae6204e21209f71148bc78dc1e/wf/__init__.py#L20))
* `version`: Workflow version registered on Latch
* `lp_name`: Name of the LaunchPlan ([Example](https://github.com/latchbio-nfcore/methylseq/blob/96d58c8532a5c2ae6204e21209f71148bc78dc1e/wf/__init__.py#L252))
**Important note on Python version**: If the Python version in the workflow's
Docker image does not match the Python version running the script that calls
`launch` or `launch_from_launch_plan,` the function may fail with a dill
unpickling error. In this case, it is recommended to use the same Python
version used during workflow registration.
# UI Definition
Source: https://wiki.latch.bio/workflows/sdk/ui/latch-metadata
Define and customize the Latch workflow interface.
## Overview
The Latch platform uses metadata objects to define and customize workflow interfaces. If you are using the Python SDK, you can define the metadata object in your workflow code. If you are using Nextflow or Snakemake, the metadata object is auto-generated from the `nextflow_json.schema` or `config.yaml` file using the `latch generate-metadata` command.
This document provides a comprehensive reference for all metadata types available in the Latch SDK.
## Examples
Visit a few examples that our engineers have curated below:
ATAC-seq peak-calling and QC analysis pipeline, uploaded using the Nextflow SDK.
[Workflow UI](https://console.latch.bio/workflows/110336/parameters)
[Source Code](https://github.com/latchbio-nfcore/atacseq/blob/master/latch_metadata/__init__.py)
A biomolecular foundation model that jointly predicts structure and binding affinity, uploaded using the Python SDK.
[Workflow UI](https://console.latch.bio/workflows/111064/parameters)
[Source Code](https://github.com/latchbio-workflows/wf-latchbio-boltz2/blob/main/wf/__init__.py#L155)
## Core Metadata Classes
### `LatchMetadata`
The primary metadata class for Python SDK workflows.
```python theme={null}
from latch.types.metadata import LatchMetadata, LatchParameter, LatchAuthor
metadata = LatchMetadata(
display_name="Workflow Name",
author=LatchAuthor(
name="Your Name",
email="your.email@example.com",
github="https://github.com/username"
),
documentation="https://github.com/author/my_workflow/README.md",
repository="https://github.com/author/my_workflow",
license="MIT",
parameters={
'param_name': LatchParameter(
display_name="Parameter Display Name",
description="Parameter description",
hidden=False,
section_title="Section Title"
)
},
tags=["NGS", "MAG"],
flow=[...],
no_standard_bulk_execution=False,
about_page_path=Path("about.md")
)
```
#### Parameters
* **`display_name`** (str): The human-readable name of the workflow
* **`author`** (LatchAuthor): Author information for the workflow
* **`documentation`** (str, optional): Link to workflow documentation
* **`repository`** (str, optional): Link to source code repository
* **`license`** (str): SPDX license identifier (default: "MIT")
* **`parameters`** (Dict\[str, LatchParameter]): Parameter definitions
* **`wiki_url`** (str, optional): Link to wiki documentation
* **`video_tutorial`** (str, optional): Link to video tutorial
* **`tags`** (List\[str]): Tags for workflow discovery
* **`flow`** (List\[FlowBase]): Custom parameter layouts
* **`no_standard_bulk_execution`** (bool): Disable standard CSV bulk execution
* **`about_page_path`** (Path, optional): Path to about page markdown file
### `NextflowMetadata`
Metadata class for Nextflow workflows.
```python theme={null}
from latch.types.metadata import NextflowMetadata, NextflowParameter, LatchAuthor
from latch.types.metadata import NextflowRuntimeResources
metadata = NextflowMetadata(
display_name="Nextflow Workflow",
author=LatchAuthor(name="Your Name"),
parameters={
'input_file': NextflowParameter(
type=LatchFile,
display_name="Input File",
description="Input file description"
)
},
runtime_resources=NextflowRuntimeResources(
cpus=8,
memory=16,
storage_gib=200
),
execution_profiles=["docker", "test"],
log_dir=LatchDir("latch:///log_directory"),
upload_command_logs=True
)
```
#### Parameters
* **`display_name`** (str): Workflow display name
* **`author`** (LatchAuthor): Author information
* **`parameters`** (Dict\[str, NextflowParameter]): Parameter definitions
* **`runtime_resources`** (NextflowRuntimeResources): Resource configuration
* **`execution_profiles`** (List\[str]): Available execution profiles
* **`log_dir`** (LatchDir, optional): Directory for workflow logs
* **`upload_command_logs`** (bool): Upload command logs to Latch Data
### `SnakemakeMetadata`
Metadata class for Snakemake workflows.
```python theme={null}
from latch.types.metadata import SnakemakeMetadata, SnakemakeParameter, LatchAuthor
from latch.types.metadata import DockerMetadata, EnvironmentConfig
metadata = SnakemakeMetadata(
display_name="Snakemake Workflow",
author=LatchAuthor(name="Your Name"),
parameters={
'samples': SnakemakeParameter(
type=List[Sample],
display_name="Samples",
samplesheet=True
)
},
file_metadata={
'samples': SnakemakeFileMetadata(
path=Path('data/samples/'),
config=True,
download=False
)
},
output_dir=LatchDir("latch:///output_directory"),
docker_metadata=DockerMetadata(
username="username",
secret_name="docker_secret"
),
env_config=EnvironmentConfig(
use_conda=True,
use_container=False
),
cores=8,
about_page_content=Path("about.md")
)
```
#### Parameters
* **`display_name`** (str): Workflow display name
* **`author`** (LatchAuthor): Author information
* **`parameters`** (Dict\[str, SnakemakeParameter]): Parameter definitions
* **`file_metadata`** (FileMetadata): File-specific metadata
* **`output_dir`** (LatchDir, optional): Output directory location
* **`docker_metadata`** (DockerMetadata, optional): Docker credentials
* **`env_config`** (EnvironmentConfig): Environment configuration
* **`cores`** (int): Number of cores for Snakemake tasks
* **`about_page_content`** (Path, optional): Path to about page content
## Parameter Classes
### `LatchParameter`
Base parameter class for Python SDK workflows.
```python theme={null}
LatchParameter(
display_name="Parameter Name",
description="Parameter description",
hidden=False,
section_title="Section Title",
placeholder="Enter value...",
comment="Additional comment",
output=False,
batch_table_column=False,
allow_dir=True,
allow_file=True,
appearance_type=LatchAppearanceEnum.line,
rules=[LatchRule(...)],
detail="Additional detail text",
samplesheet=False,
allowed_tables=[1, 2, 3]
)
```
#### Parameters
* **`display_name`** (str, optional): Human-readable parameter name
* **`description`** (str, optional): Parameter description/tooltip
* **`hidden`** (bool): Whether parameter is hidden by default
* **`section_title`** (str, optional): Section grouping title
* **`placeholder`** (str, optional): Placeholder text for input
* **`comment`** (str, optional): Additional comment text
* **`output`** (bool): Whether parameter is an output
* **`batch_table_column`** (bool): Show in batch mode table
* **`allow_dir`** (bool): Accept directories in UI
* **`allow_file`** (bool): Accept files in UI
* **`appearance_type`** (LatchAppearance): UI appearance type
* **`rules`** (List\[LatchRule]): Validation rules
* **`detail`** (str, optional): Secondary label text
* **`samplesheet`** (bool, optional): Enable samplesheet input
* **`allowed_tables`** (List\[int], optional): Allowed registry tables
### `NextflowParameter`
Parameter class for Nextflow workflows.
```python theme={null}
NextflowParameter(
type=typing.Any, # Required for Nextflow
display_name="Parameter Name",
description="Description",
default=None,
samplesheet=False,
samplesheet_type='csv',
samplesheet_constructor=custom_constructor,
results_paths=[Path("output1"), Path("output2")]
)
```
#### Parameters
* **`type`** (Type\[T], optional): Expected parameter type
* **`display_name`** (str, optional): Parameter display name
* **`description`** (str, optional): Parameter description
* **`default`** (T, optional): Default parameter value
* **`samplesheet`** (bool, optional): Enable samplesheet input
* **`samplesheet_type`** (Literal\["csv", "tsv", None]): Samplesheet format
* **`samplesheet_constructor`** (Callable\[\[T], Path], optional): Custom constructor
* **`results_paths`** (List\[Path], optional): Output sub-paths for UI
### `SnakemakeParameter`
Parameter class for Snakemake workflows.
```python theme={null}
SnakemakeParameter(
type=typing.Any, # Required for Snakemake
display_name="Parameter Name",
description="Description",
default=None
)
```
#### Parameters
* **`type`** (Type\[T], optional): Expected parameter type
* **`display_name`** (str, optional): Parameter display name
* **`description`** (str, optional): Parameter description
* **`default`** (T, optional): Default parameter value
## Organization of Parameters into Sections
By default, all parameters are rendered from top to bottom on the workflow UI, in the order they are defined in the metadata object. This can be overwhelming for end users if workflows have dozens or hundreds of parameters.
To make the UI more user-friendly, you can organize parameters into `Section`s and take advantage of elements like `Spoiler` or `Fork` to collapse advanced parameters.
### Custom Flows
Define custom parameter layouts using flow elements:
```python theme={null}
flow=[
Section(
"Input Section",
Text("Configure your input data"),
Params("input_file", "output_dir")
),
Section(
"Processing Options",
Text("Configure processing parameters"),
Params("threads", "memory")
),
Spoiler(
"Advanced Options",
Text("Advanced configuration options"),
Params("advanced_param1", "advanced_param2")
)
]
```
### Appearance Customization
Customize parameter appearance:
```python theme={null}
appearance_type=LatchAppearance(
type=LatchAppearanceEnum.paragraph,
placeholder="Enter detailed description...",
comment="This field supports markdown formatting",
detail="Additional context information"
)
```
## Flow Elements
### `Section`
Flow element that displays child flow in a titled card.
```python theme={null}
Section(
"Section Title",
Text("Description text"),
Params("param1", "param2"),
Fork(...)
)
```
### `Text`
Flow element that displays markdown text.
```python theme={null}
Text("This is markdown text with **bold** and *italic* formatting")
```
### `Title`
Flow element that displays a markdown title.
```python theme={null}
Title("# Main Title")
```
### `Params`
Flow element that displays parameter widgets.
```python theme={null}
Params("param1", "param2", "param3")
```
### `Spoiler`
Flow element that displays a collapsible card.
```python theme={null}
Spoiler(
"Advanced Options",
Text("These are advanced configuration options"),
Params("advanced_param1", "advanced_param2")
)
```
### `Fork`
Flow element that displays mutually exclusive alternatives.
```python theme={null}
Fork(
"sample_fork",
"Choose read type",
paired_end=ForkBranch("Paired-end", Params("paired_end")),
single_end=ForkBranch("Single-end", Params("single_end"))
)
```
## Supporting Classes
### `LatchAuthor`
Author information for workflows.
```python theme={null}
LatchAuthor(
name="Author Name",
email="author@example.com",
github="https://github.com/username"
)
```
### `LatchRule`
Validation rule for parameter inputs.
```python theme={null}
LatchRule(
regex=r"\.(fastq|fq)$",
message="Only .fastq or .fq files are allowed"
)
```
### `LatchAppearance`
Parameter appearance configuration.
```python theme={null}
# Line input
appearance_type=LatchAppearanceEnum.line
# Paragraph input
appearance_type=LatchAppearanceEnum.paragraph
# Multiselect with custom options
appearance_type=Multiselect(
options=[
MultiselectOption("Option 1", "value1"),
MultiselectOption("Option 2", "value2")
],
allow_custom=True
)
```
### `SnakemakeFileMetadata`
File-specific metadata for Snakemake workflows.
```python theme={null}
SnakemakeFileMetadata(
path=Path('local/path/'),
config=True,
download=False
)
```
### `NextflowRuntimeResources`
Resource configuration for Nextflow runtime tasks.
```python theme={null}
NextflowRuntimeResources(
cpus=8,
memory=16,
storage_gib=200,
storage_expiration_hours=168 # 7 days
)
```
### `DockerMetadata`
Credentials for private Docker repositories.
```python theme={null}
DockerMetadata(
username="docker_username",
secret_name="docker_password_secret"
)
```
### `EnvironmentConfig`
Environment configuration for Snakemake tasks.
```python theme={null}
EnvironmentConfig(
use_conda=True,
use_container=False,
container_args=["--gpus", "all"]
)
```
## Type System
### Supported Parameter Types
```python theme={null}
ParameterType = Union[
None,
int,
float,
str,
bool,
LatchFile,
LatchDir,
Enum,
_IsDataclass, # Any dataclass
Collection["ParameterType"], # Lists, Dicts, etc.
]
```
### Type Validation
The SDK automatically validates parameter types based on:
* Function signature type annotations
* Metadata parameter definitions
* Runtime value validation
* Custom validation rules via `LatchRule`
## Samplesheet Support
### Basic Samplesheet
```python theme={null}
'samples': NextflowParameter(
type=List[Sample],
samplesheet=True,
samplesheet_type='csv'
)
```
### Custom Samplesheet Constructor
```python theme={null}
def custom_constructor(samples: List[Sample]) -> Path:
# Custom logic to create samplesheet
return Path("custom_samplesheet.txt")
'samples': NextflowParameter(
type=List[Sample],
samplesheet=True,
samplesheet_constructor=custom_constructor
)
```
### `SamplesheetItem`s
Often when populating a samplesheet parameter using rows from Registry, it is useful to have access to the originating record that created the row. Wrapping a samplesheet type with the `SamplesheetItem` marker allows downstream code to easily access this underlying record.
```python theme={null}
from latch.types.samplesheet_item import SamplesheetItem
@dataclass
class Sample:
fastq_1: LatchFile
fastq_2: Optional[LatchFile]
@task
def example(input: list[SamplesheetItem[Sample]]):
for row in input:
print(row.data) # `Sample` object, contains the underlying data of the row
print(row.record) # `Record` object, None if the row wasn't imported from registry
```
## Validation and Rules
### Regex Validation
```python theme={null}
'filename': LatchParameter(
display_name="Filename",
rules=[
LatchRule(
regex=r"^[a-zA-Z0-9_-]+$",
message="Filename must contain only letters, numbers, underscores, and hyphens"
)
]
)
```
### Multiple Rules
```python theme={null}
'email': LatchParameter(
display_name="Email",
rules=[
LatchRule(
regex=r"^[^@]+@[^@]+\.[^@]+$",
message="Must be a valid email address"
),
LatchRule(
regex=r"^.{5,100}$",
message="Email must be between 5 and 100 characters"
)
]
)
```
# Launch Plans
Source: https://wiki.latch.bio/workflows/sdk/ui/launch-plans
Learn how to define test data for workflows using LaunchPlan
## Overview
The `LaunchPlan` class allows you to create named groups of default parameters for your workflows. This enables users to quickly launch workflows with predefined parameter sets, making it easier to get started with common use cases.
## Constructor
```python theme={null}
LaunchPlan(
workflow: PythonFunctionWorkflow,
name: str,
default_params: dict[str, Any],
*,
description: str | None = None,
)
```
### Parameters
* `workflow` (PythonFunctionWorkflow): The workflow function to which the default values apply. This is the function decorated with `@workflow` (See [example](https://github.com/latchbio-nfcore/methylseq/blob/96d58c8532a5c2ae6204e21209f71148bc78dc1e/wf/__init__.py#L20))
* `name` (str): A semantic identifier for the parameter values (e.g., 'Small Data', 'Production Run')
* `default_params` (dict\[str, Any]): A mapping of parameter names to their default values.
* `description` (str, optional): A description of what this launch plan represents.
## Usage
```python expandable theme={null}
LaunchPlan(
nf_nf_core_methylseq,
"Test Data",
{
"input": [
Sample(
sample="SRR389222_sub1",
fastq_1=LatchFile(
"s3://latch-public/nf-core/methylseq/test_data/SRR389222_sub1.fastq.gz"
),
fastq_2=None,
),
Sample(
sample="SRR389222_sub2",
fastq_1=LatchFile(
"s3://latch-public/nf-core/methylseq/test_data/SRR389222_sub2.fastq.gz"
),
fastq_2=None,
),
Sample(
sample="SRR389222_sub3",
fastq_1=LatchFile(
"s3://latch-public/nf-core/methylseq/test_data/SRR389222_sub3.fastq.gz"
),
fastq_2=None,
),
Sample(
sample="Ecoli_10K_methylated",
fastq_1=LatchFile(
"s3://latch-public/nf-core/methylseq/test_data/Ecoli_10K_methylated_R1.fastq.gz"
),
fastq_2=LatchFile(
"s3://latch-public/nf-core/methylseq/test_data/Ecoli_10K_methylated_R2.fastq.gz"
),
),
],
"run_name": "Test_Run",
"genome_source": "custom",
"fasta": LatchFile("s3://latch-public/nf-core/methylseq/test_data/genome.fa"),
"fasta_index": LatchFile(
"s3://latch-public/nf-core/methylseq/test_data/genome.fa.fai"
),
},
)
# Add more launch plans here...
```
See a full example of how `LaunchPlan` is used in the `nf-core/methylseq` workflow.
## How It Works
1. When you register your workflow, the launch plans are automatically created
2. The default parameters appear under the "Test Data" dropdown button in the Latch Console.
3. Users can select a launch plan to pre-populate the workflow form
4. Users can still modify any of the pre-filled parameters before execution
## Summary
The `LaunchPlan` class provides a powerful way to create predefined parameter sets for your workflows, improving the user experience by:
* Reducing setup time with pre-configured parameters
* Providing guidance on appropriate parameter values
* Supporting multiple use cases with different launch plans
* Maintaining flexibility for users to customize as needed
By creating well-named and well-described launch plans, you can make your workflows more accessible to users with different levels of expertise and different use case requirements.
# Messages
Source: https://wiki.latch.bio/workflows/sdk/ui/messages
Display styled and prominent messages to end users during and after workflow execution.
Task executions produce logs, displayed on the Latch console to provide users visibility into their workflows. However, these logs tend to be terribly verbose. It's tedious to sift through piles of logs looking for useful signals; instead, important information, warnings, and errors should be prominently displayed. This is accomplished through the Latch SDK's messaging feature.
## Usage
```python theme={null}
from latch import small_task, message
@small_task
def task():
...
try:
...
catch ValueError:
title = 'Invalid sample ID column selected'
body = 'Your file indicates that sample columns a, b are valid'
message(typ='error', data={'title': title, 'body': body})
...
```
The `typ` parameter affects how your message is styled. It currently accepts three options:
* `info`
* `warning`
* `error`
The `data` parameter contains the message to be displayed. It's represented as a Python `dict` and requires two inputs,
* `title`: The title of your message
* `body`: The contents of your message
For more information, see `latch.functions.messages` under the API docs.
## Messages Interface
During and after workflow execution, all messages are displayed under the "Messages" tab for that workflow run.
If you don't explicitly define a failure message for a task, the workflow automatically shows a default error message when the task fails. This default view also includes a button that lets the user request an LLM-generated explanation of the error.
In the case where the workflow succeeds or is aborted, the message tab will be empty and say "No messages to display".
# Results
Source: https://wiki.latch.bio/workflows/sdk/ui/results
Learn how to highlight the most relevant outputs of a workflow to users.
Latch workflows can output thousands of files, making it difficult for users to find the most relevant output files. To help users navigate these outputs, Latch provides a results page that displays the outputs of a workflow in a user-friendly interface.
## Usage
### SDK Example
To expose specific outputs to users, developers must explicitly supply a list of paths to publish. For example:
```python theme={null}
...
from latch.executions import add_execution_results
@small_task
def assembly_task(
read1: LatchFile, read2: LatchFile, output_directory: LatchOutputDir
) -> LatchFile:
...
results = []
results.append(str(output_directory.remote_path))
results.append(os.path.join(output_directory.remote_path, 'pipeline_info/execution_report.html'))
add_execution_results(results)
...
```
### Nextflow Example
Developers can explicitly define a list of subpaths for any output directory defined in `latch_metadata/parameters.py`. For example, the following
code snippet exposes shortcuts for the workflows `publishDir` and execution report:
```python theme={null}
parameters = {
'outdir': NextflowParameter(
type=LatchDir,
results_paths=[
Path("/"),
Path("/pipeline_info/execution_report.html")
]
)
}
```
## Results Interface
Both methods render a "Results" page in the Latch Console that displays the outputs of the workflow in a user-friendly interface: